Category: Cloud Education

  • How To Set Up an NGINX Reverse Proxy for Node.js, Python & Go Apps

    How To Set Up an NGINX Reverse Proxy for Node.js, Python & Go Apps

    There is a significant difference between an application that runs on localhost:3000 and one that is ready for public traffic. 

    When it is time to go live, you need SSL, a custom domain, and a secure way to route traffic to your backend. If you are like most developers, you probably grab the top NGINX reverse proxy snippet from Stack Overflow, paste it into your server, and call it a day.

    Then the weird bugs start.

    Your real-time WebSockets silently disconnect every 60 seconds. You check your application logs, only to realize every single visitor’s IP address is logged as a Cloudflare server or your own local proxy’s IP. Then a user tries to upload a basic 2MB image and gets slammed with a frustrating 413 Request Entity Too Large error.

    We have all been there.

    Instead of relying on incomplete configuration snippets, we will show you a more complete NGINX reverse proxy setup that you can adapt to your application and server environment. This will help you prevent common WebSocket timeout problems, preserve the correct client connection information, and terminate SSL cleanly before forwarding requests to your application. 

    What an NGINX Reverse Proxy Actually Does (And Why You Need One)

    If you are using NGINX for the first time, you can read our NGINX configuration basics guide first. But in short, a reverse proxy sits in front of your application server (like Node, Python, or Go) and intercepts all incoming internet traffic.
    This proxy handles several important tasks, such as:

    SSL termination, port consolidation, and HTTP/2 to the client

    When people visit a website, they expect secure https:// traffic on port 443 served via modern HTTP/2 protocols. Your application is probably served via plain HTTP/1.1 on port 3000. 

    In this setup, NGINX “terminates” the SSL connection, meaning it handles the heavy lifting of decryption and HTTP/2 multiplexing, and passes plain, unencrypted traffic to your app locally. This will allow you to centralize your certificate management.

    Why Put NGINX in Front of Your Application? 

    You can technically configure a Node.js or Go application to listen directly on port 443 and manage its own TLS certificates. In many production environments, it is simpler to place NGINX in front of the application instead.

    NGINX can handle TLS termination, connection management, request limits, compression, logging, and other web-server responsibilities while your application remains focused on handling application requests.

    Reverse proxy vs forward proxy vs load balancer

    When you are deciding between web servers and reverse proxies, you need to understand the terminology. A forward proxy sits between clients and external services and sends requests on the clients’ behalf. A reverse proxy sits in front of one or more backend servers and receives requests on their behalf. NGINX can also act as a load balancer by distributing requests across multiple backend instances. 

    Before You Configure the Reverse Proxy

    Before setting up NGINX, make sure:

    • Your application is already running.
    • You know the local port or Unix socket used by the application.
    • The application is not unnecessarily exposed on a public interface.
    • Your domain points to the server.
    • Ports 80 and 443 are reachable if you are serving the application publicly.
    • Your SSL certificate is already available if you use the HTTPS configuration shown below.

    You can test a TCP-based application locally before configuring NGINX. For example:

    curl http://127.0.0.1:3000

    If the application does not respond locally or if you see an error message saying “Failed to connect”, then you must fix the application or service first. NGINX cannot proxy successfully to an upstream service that is not running.
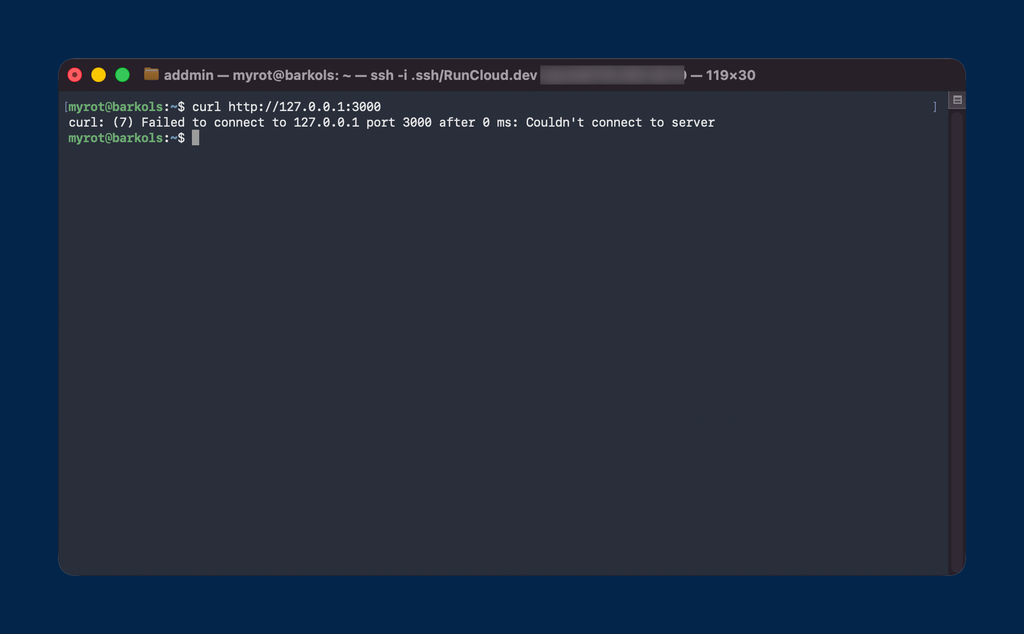
    Check application accessible via CURL

    Example NGINX Reverse Proxy Configuration 

    Most tutorials give you only the basic proxy configuration and leave you to handle features such as WebSockets, client IP forwarding, upload limits, and timeouts separately. The following example provides a more complete starting point that you can adapt to your application and server environment. 

    Example HTTPS Reverse Proxy Configuration 

    The map directive must be defined in the NGINX http context, outside the server block. The server block can then use the resulting $connection_upgrade variable when forwarding WebSocket requests. 

    map $http_upgrade $connection_upgrade { 
        default upgrade; 
        '' close; 
    } 
    server {
        listen 443 ssl;
        http2 on;
        server_name myapp.com;
        # SSL Configuration
        ssl_certificate /etc/letsencrypt/live/myapp.com/fullchain.pem;
        ssl_certificate_key /etc/letsencrypt/live/myapp.com/privkey.pem;
        # Example upload limit
        client_max_body_size 50M; 
        location / {
            # Proxy pass to your application
            proxy_pass http://127.0.0.1:3000;
    
    
            # Support HTTP/1.1 and WebSocket upgrades 
            proxy_http_version 1.1;
            proxy_set_header Upgrade $http_upgrade;
            proxy_set_header Connection $connection_upgrade;
    
    
            # Forward the original host and client connection details
            proxy_set_header Host $host;
            proxy_set_header X-Real-IP $remote_addr;
            proxy_set_header X-Forwarded-For $proxy_add_x_forwarded_for;
            proxy_set_header X-Forwarded-Proto $scheme;
    
    
            # Connection timeouts
            proxy_read_timeout 300;
            proxy_send_timeout 300; 
        }
    }

    If NGINX receives traffic directly from the client, $remote_addr contains the client’s IP address. If your site sits behind another proxy or CDN such as Cloudflare, you must also configure NGINX to trust that proxy and restore the original client IP. Otherwise, $remote_addr will contain the proxy’s IP address instead.

    If you use RunCloud, you can create and manage reverse proxy configurations from the RunCloud dashboard rather than manually editing generated NGINX configuration files.

    Configure Multiple Upstream Application Instances 

    If you run multiple instances of your application, you can define an upstream block outside the server block. NGINX can then distribute requests across those application instances.

    upstream my_nodejs_app {
        server 127.0.0.1:3000;
        server 127.0.0.1:3001;
    }

    You would then change your location block to use proxy_pass http://my_nodejs_app.

    Reverse Proxy a Node.js App (with PM2)

    When you deploy a long-running Node.js application on a VPS, you will usually run it under a process manager or service manager so that it can restart after a crash or server reboot. PM2 is a common option. 

    Run the Node.js App with PM2 on Port 3000 

    For an application that accepts a -p port argument, you could start it with PM2 on port 3000:

    pm2 start server.js --name "my-app" -- -p 3000

    The exact command depends on how your application accepts its host and port settings.

    The proxy_pass + headers config for Node

    Many Node.js frameworks use the Host and X-Forwarded-Proto headers when determining the original hostname and protocol. Forwarding these headers allows the application to identify that the original client connection used HTTPS even though NGINX communicates with the application over local HTTP.

    Depending on your framework, you may also need to configure the application to trust the reverse proxy before it uses forwarded headers.

    If you manage the application with RunCloud, you can create the reverse proxy from the RunCloud dashboard. Set the web application’s stack to Native NGINX + Custom Config, then use the predefined Proxy configuration under NGINX Config and set it to the port used by your application. 

    Zero-downtime reload pattern

    After changing a standard NGINX configuration, test the configuration before reloading the service:

    nginx -t && systemctl reload nginx

    A graceful reload applies valid configuration changes without unnecessarily interrupting active connections.
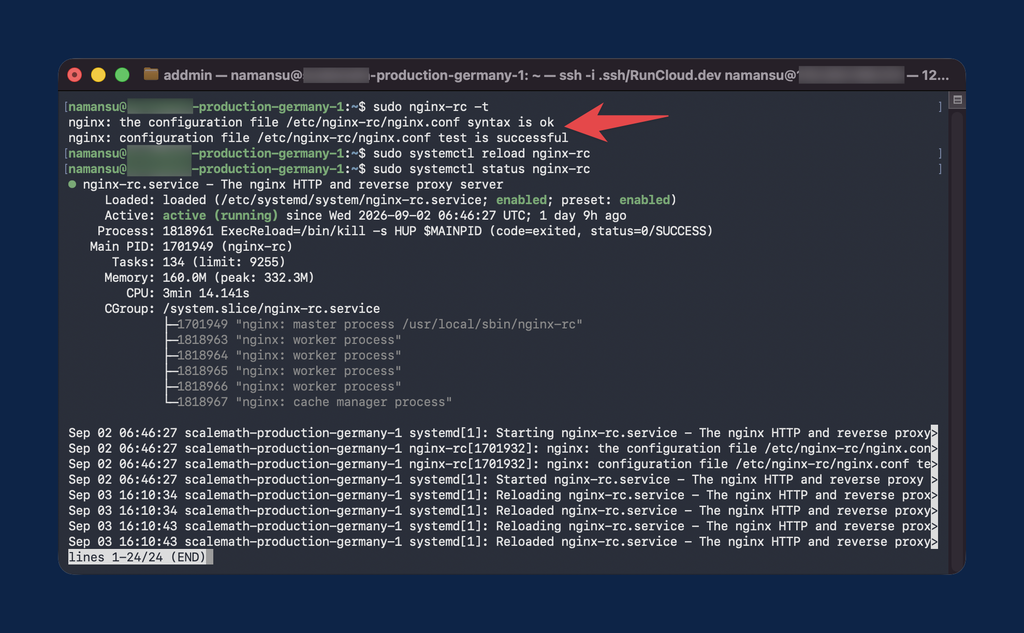
    Check NGINX config syntax

    If your server is managed by RunCloud, use the NGINX Config tools in the RunCloud dashboard to configure web applications. RunCloud uses its own NGINX package and configuration structure, so generic nginx service commands and paths may not match a RunCloud-managed server. 

    Reverse Proxy a Python App 

    Python applications handle concurrency differently than Node.js, usually relying on WSGI (Gunicorn) or ASGI (Uvicorn) servers.

    Gunicorn on a Unix socket vs TCP port

    Gunicorn can listen either on a local TCP port, such as 127.0.0.1:8000, or on a Unix socket. Unix sockets can be useful when NGINX and Gunicorn run on the same server because access can be controlled through filesystem permissions.

    For example:

    gunicorn --bind unix:/tmp/myapp.sock wsgi:app

    The NGINX upstream config for Unix sockets

    To point NGINX to a Unix socket instead of a TCP port, specify the socket path using NGINX’s Unix-domain socket syntax:

    proxy_pass http://unix:/tmp/myapp.sock:;

    Disable Proxy Buffering for Streaming Responses 

    NGINX buffers proxied responses by default. For applications that depend on incremental delivery, such as Server-Sent Events or streamed application responses, buffering can delay data reaching the client.

    You can disable proxy response buffering for the relevant location:

    proxy_buffering off;

    Reverse Proxy a Go App

    Go’s net/http package can serve HTTP traffic directly without requiring a separate web server. Placing NGINX in front of a Go application can simplify TLS termination, compression, rate limiting, logging, and other HTTP-level configuration. NGINX includes gzip support, while Brotli requires Brotli module support in the NGINX build. 

    The minimal proxy_pass for a Go binary

    If your Go application is listening on 127.0.0.1:8080, set proxy_pass to that address:

    proxy_pass http://127.0.0.1:8080;

    You can then add the required forwarding headers, timeout settings, and WebSocket configuration for your application.

    Configure WebSocket Proxying in NGINX 

    If you are running real-time applications like chat servers or automating workflows by hosting n8n behind Docker and NGINX, you need WebSockets. But WebSockets break easily behind NGINX if you miss three critical details.

    Older NGINX versions default to HTTP/1.0 when proxying HTTP requests to upstream servers. NGINX 1.29.7 and later default to HTTP/1.1.

    Explicitly setting the proxy version remains useful when you need compatibility with older NGINX installations and makes the WebSocket requirement clear:

    proxy_http_version 1.1;

    A WebSocket connection begins as an HTTP request containing an Upgrade header. NGINX needs to pass the relevant upgrade information to the upstream application.

    A reusable configuration can define the appropriate Connection value with a map:

    map $http_upgrade $connection_upgrade {

        default upgrade;

        ''      close;

    }


    Then use:

    proxy_set_header Upgrade $http_upgrade;

    proxy_set_header Connection $connection_upgrade;

    This sends Connection: upgrade only when an upgrade has been requested.

    Increase the WebSocket Read Timeout 

    The default proxy_read_timeout is 60 seconds. If the upstream server sends no data during that period, NGINX can close the connection.

    For long-lived WebSocket connections, you can increase the timeout:

    proxy_read_timeout 86400;

    This example allows up to 24 hours between successive read operations. Applications can also use WebSocket ping/pong messages or other heartbeat traffic to prevent idle connections from reaching the timeout.

    How to Set Up an NGINX Reverse Proxy in RunCloud

    If your server is managed by RunCloud, you can configure the reverse proxy from the dashboard without manually editing the generated NGINX configuration files.

    1. Log in to the RunCloud dashboard and select your server.
    2. Open Web Applications and select the application you want to configure.
    3. Open Settings and change the Web Application Stack to Native NGINX + Custom Config.
    4. Open NGINX Config and select Add a New Config.
    5. Choose Predefined Config and select the Proxy configuration.
    6. Set the proxy destination to the port used by your Node.js, Python, or Go application.
    7. Configure options such as proxy buffering or WebSocket support if your application requires them.
    8. Select Run and Debug to validate the NGINX configuration.
    9. Once the configuration passes validation, select Create Config.
    10. Test the application through its public URL or with curl.

    RunCloud recommends creating and editing custom NGINX configuration through the dashboard. Generated application configuration files should not be edited manually because RunCloud manages those files.

    Troubleshooting Common NGINX Reverse Proxy Problems

    502 Bad Gateway

    A 502 error usually means NGINX cannot connect to the upstream application.

    Check that the application is running and listening on the address or socket configured in proxy_pass.

    For a TCP-based application, test the upstream directly:

    curl http://127.0.0.1:3000

    Also, confirm that the port in proxy_pass matches the port used by the application.

    413 Request Entity Too Large

    If uploads fail with a 413 response, increase client_max_body_size to a value appropriate for your application:

    client_max_body_size 50M;

    Avoid setting a much larger limit than your application actually needs.

    WebSockets Disconnect or Fail to Connect

    Check that WebSocket upgrade headers are passed to the application and that the proxy uses HTTP/1.1 where required for compatibility.

    If connections close after periods of inactivity, review proxy_read_timeout and your application’s WebSocket heartbeat behavior.

    Redirect Loops

    If NGINX terminates HTTPS but the application believes the request arrived over HTTP, the application may repeatedly redirect the request to HTTPS.

    Make sure NGINX forwards:

    proxy_set_header X-Forwarded-Proto $scheme;

    You may also need to configure your framework to trust the reverse proxy.

    Incorrect Client IP Addresses

    If NGINX sits directly behind the client, $remote_addr represents the client address. If another proxy, such as Cloudflare, sits in front of NGINX, configure trusted proxy ranges and the appropriate real-IP header before relying on $remote_addr.

    Manage Reusable NGINX Configurations with RunCloud Templates 

    Note: Use the web application’s NGINX Config tools when configuring a reverse proxy for an individual application. NGINX Templates are useful when you want to reuse and centrally manage the same configuration across multiple applications. 

    If you manage the same NGINX rules across several web applications, repeatedly copying configuration files makes those configurations harder to maintain consistently.

    RunCloud NGINX Templates let you create reusable configuration files in your workspace and link them to multiple web applications. You can manage these templates centrally from Settings > NGINX Templates rather than manually editing each application’s configuration over SSH.

    RunCloud provides two template areas:

    • My Templates contains templates created or duplicated into your workspace.
    • Public Templates contains read-only templates provided by RunCloud and approved community members. You can duplicate a Public Template into your workspace before editing or installing it.

    This provides several benefits for server management: 

    • Centralized configuration: Link a template to multiple web applications and manage the configuration from one place.
    • Reusable templates: Create your own templates or duplicate a Public Template into your workspace as a starting point.
    • Configuration testing: Test a template against an existing web application before installing it.
    • Controlled propagation: When you update a linked template, RunCloud lets you propagate the new configuration to the selected web applications.
    • Safer deployment: RunCloud checks the NGINX configuration before applying it. If validation fails, the invalid configuration is not activated.
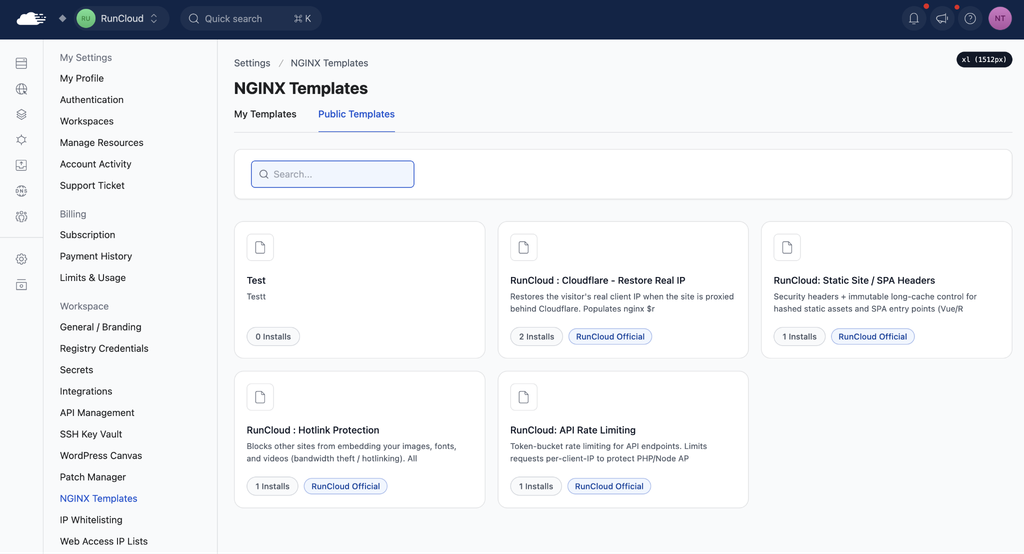
    RunCloud NGINX template dashboard for creating reverse proxy

    This makes NGINX Templates useful when the same configuration needs to be maintained across several applications without manually updating each one. 

    Wrapping Up

    An NGINX reverse proxy gives you a central place to handle HTTPS, route requests to your application, forward request information, and configure features such as WebSocket support and upload limits.

    The exact configuration depends on your application, whether another proxy or CDN sits in front of NGINX, and which NGINX version you are running. Testing each configuration change before applying it is therefore essential.

    RunCloud provides dashboard tools for managing NGINX configuration without manually editing generated application configuration files. You can create reverse proxy configurations, validate them before applying them, and manage reusable configurations through NGINX Templates.

    This gives you a safer way to manage reverse proxy configuration across your applications while retaining control over application-specific settings such as ports, WebSockets, buffering, and forwarded headers.

    If you want to manage your NGINX reverse proxy and web applications from a central dashboard, sign up for RunCloud and deploy your next application. 

    FAQs

    What is the difference between NGINX and Apache as a reverse proxy?

    Both NGINX and Apache can act as reverse proxies. NGINX uses an event-driven architecture and is commonly used as a dedicated reverse proxy in front of application servers. Apache supports reverse proxying through modules such as mod_proxy and offers several Multi-Processing Modules with different connection-handling models.
    The better choice depends on your existing server stack, configuration requirements, and operational preferences.

    Should I use Caddy or Traefik instead of NGINX?

    Caddy and Traefik are alternatives worth considering depending on your environment. Caddy focuses heavily on simple configuration and automatic HTTPS, while Traefik is commonly used with container and service-discovery workflows.
    NGINX remains a good choice when you need detailed control over proxying, routing, headers, caching, or load balancing.

    Why does my WebSocket disconnect every 60 seconds behind NGINX?

    NGINX uses a default proxy_read_timeout of 60 seconds. If the upstream sends no data during that period, NGINX can close the connection.
    You can increase proxy_read_timeout for long-lived WebSocket connections or use application-level ping/pong messages or other heartbeat traffic to keep the connection active.

    How do I pass the real client IP through NGINX and Cloudflare?

    If Cloudflare sits in front of NGINX, configure NGINX’s real-IP module to trust only Cloudflare’s published proxy IP ranges and use the appropriate client-IP header. This allows NGINX to replace the Cloudflare proxy address with the original visitor address before forwarding it to your application.
    Do not trust forwarded client-IP headers from arbitrary sources, because clients can otherwise supply forged values.

    Can NGINX do load balancing between multiple Node.js processes?

    Yes. NGINX can distribute traffic across multiple Node.js instances using an upstream block. The available load-balancing methods include the default round-robin behavior as well as methods such as least_conn and ip_hash.
    Choose the method according to how your application handles sessions, connection duration, and backend capacity.

    Does NGINX HTTP/2 work with the upstream backend?

    The protocol used between the client and NGINX is separate from the protocol NGINX uses to communicate with an upstream application. For normal HTTP reverse proxying, NGINX can proxy requests to HTTP upstream servers independently of whether the client connected using HTTP/2 or HTTP/3.
    If your application uses a protocol such as gRPC, use the corresponding NGINX proxy module and configuration rather than the standard HTTP proxy_pass configuration.

    What is the cleanest way to add SSL to a Node.js app?

    A common production approach is to terminate TLS at NGINX and proxy requests to the Node.js application over a local connection. This centralizes certificate management and allows the application to run without managing its own public TLS listener.
    You can obtain and renew certificates with a tool such as Certbot or use your server-management platform’s SSL tools.
  • How To Install And Configure Object Cache Pro for WordPress

    How To Install And Configure Object Cache Pro for WordPress

    Are you tired of slow server responses on your WordPress website? If so, you may want to consider implementing object caching.

    Object caching is a powerful technique that can greatly enhance your website’s performance by reducing database queries and speeding up page load times.

    In this article, we’ll guide you through setting up Object Cache Pro and provide the steps to configure it properly.

    Let’s get started!

    Why Should You Use Object Cache Pro?

    Object Cache Pro is a business-class Redis object cache backend for WordPress, providing reliable, highly optimized, and fully customizable caching for your website. It’s optimized for WooCommerce, Jetpack, and Yoast SEO – making it an ideal solution for businesses.

    Object Cache Pro seamlessly integrates with WordPress and offers deep insights through its Site Health and Query Monitor integrations, as well as its Debug Bar panels. Object Cache Pro offers faster binary serialization support, LZF, LZ4, and ZSTD compression, asynchronous flushing, batch key prefetching, batcache, and cache analytics.

    How to Configure Object Cache Pro for WordPress on RunCloud

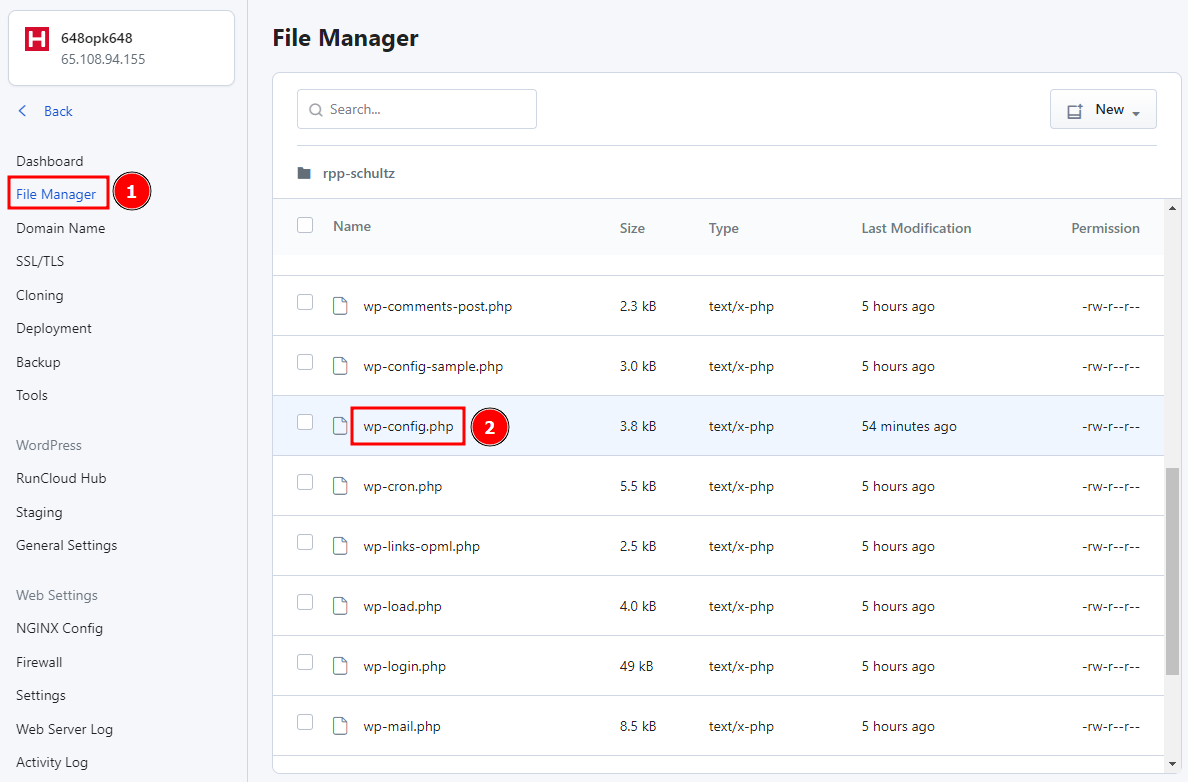
    Before installing the plugin, we recommend configuring the license key to avoid any hiccups during the installation. The easiest way to do this is by editing the wp-config.php file on the RunCloud dashboard.

    Open the wp-config.php file in the file manager and add the following code below the line that says ‘Add any custom values between this line and the “stop editing” line’. Don’t forget to replace the license key in the text snippet.

    define('WP_REDIS_CONFIG', [
    'token' => '<your-license-token>',
    'host' => '127.0.0.1',
    'port' => 6379,
    'database' => $REDIS_DATABASE,
    'prefix' => 'db${REDIS_DATABASE}:',
    'maxttl' => 86400,
    'timeout' => 1.0,
    'read_timeout' => 1.0,
    // 'prefetch' => true,
    // 'split_alloptions' => true,
    'debug' => false,
    ]);
    define('WP_REDIS_DISABLED', false);

    After you have added the file, you can browse the list of configurations to change any other settings that you like. Once you are satisfied with it, you can save and close the file.

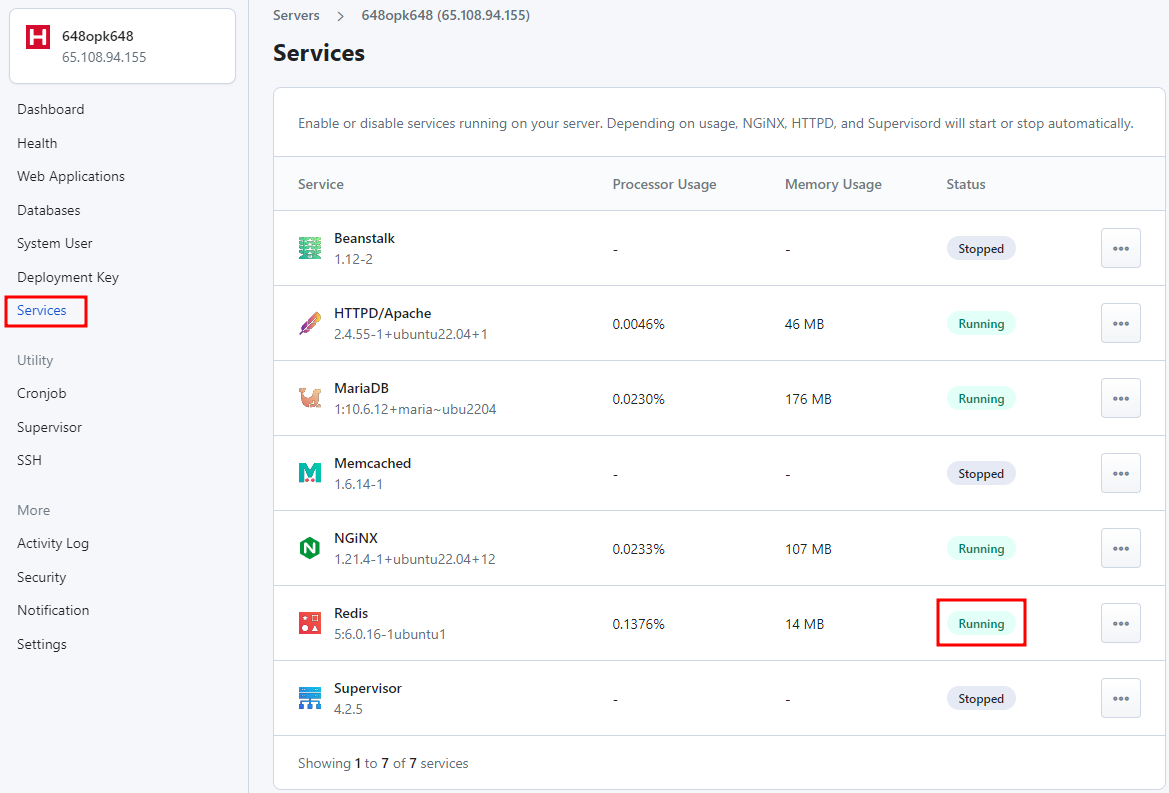
    After adding the license token, verify that Redis is running on your server. To do this, go to the Services menu and check the status, making sure it says “Running” next to Redis. If it’s stopped, you can just start it.

    How to Install Object Cache Pro for WordPress

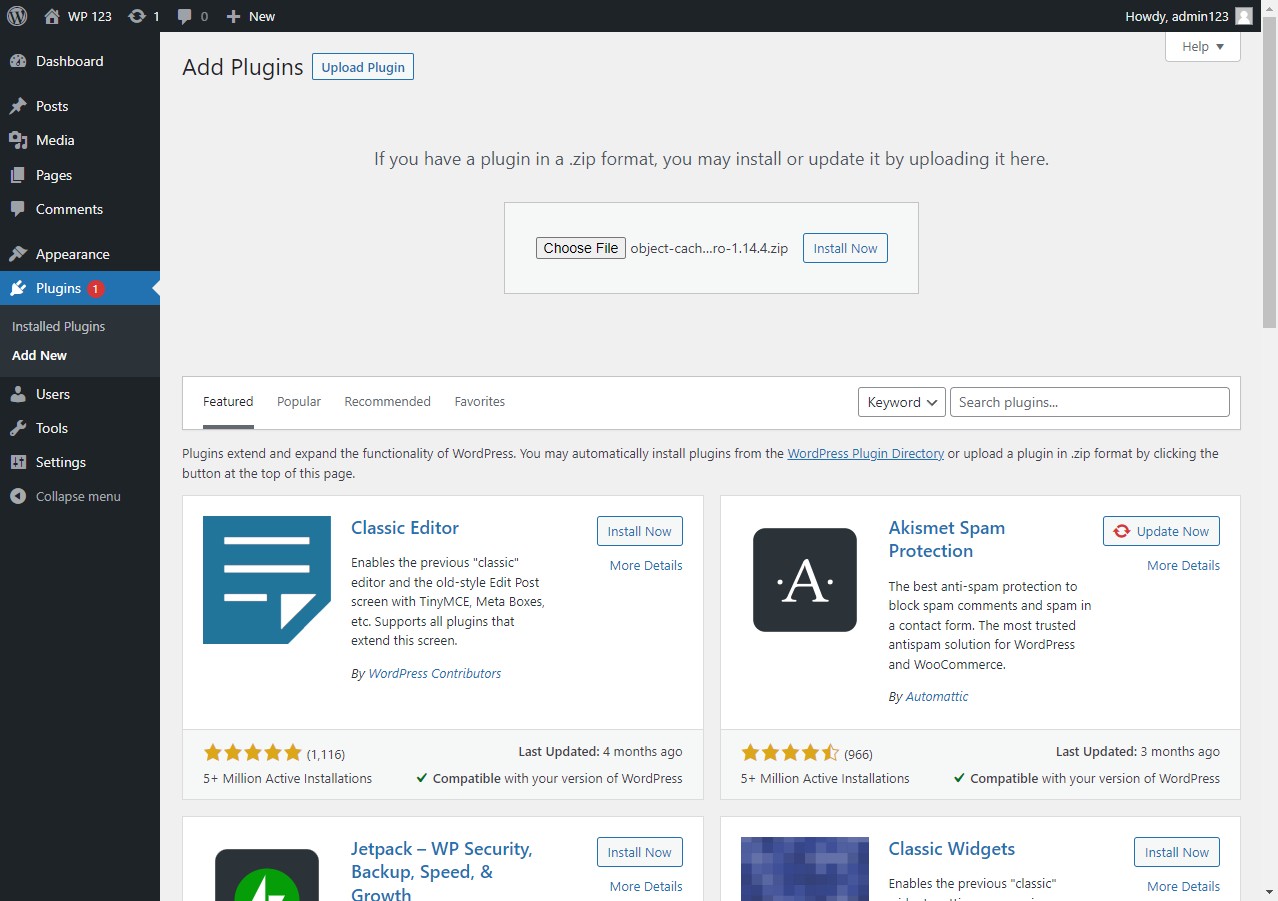
    Once you have configured the settings, you can install the plugin by uploading the zip file. Go to your WordPress dashboard and open the plugins tab. Click on “Add Plugins” and select “Upload Plugin”, then locate the zip file and install it.

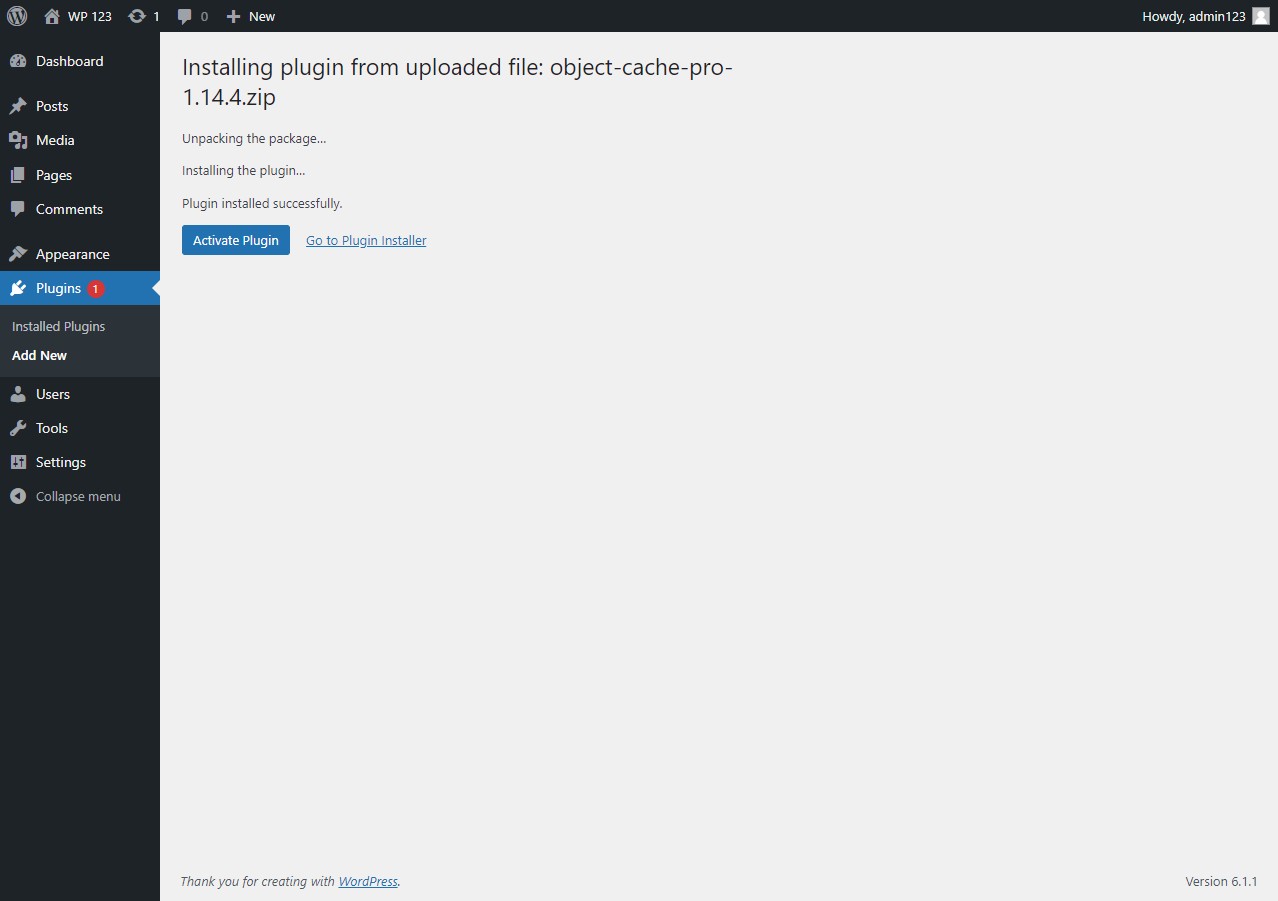
    After installation, click on the “Activate Plugin” to enable it.

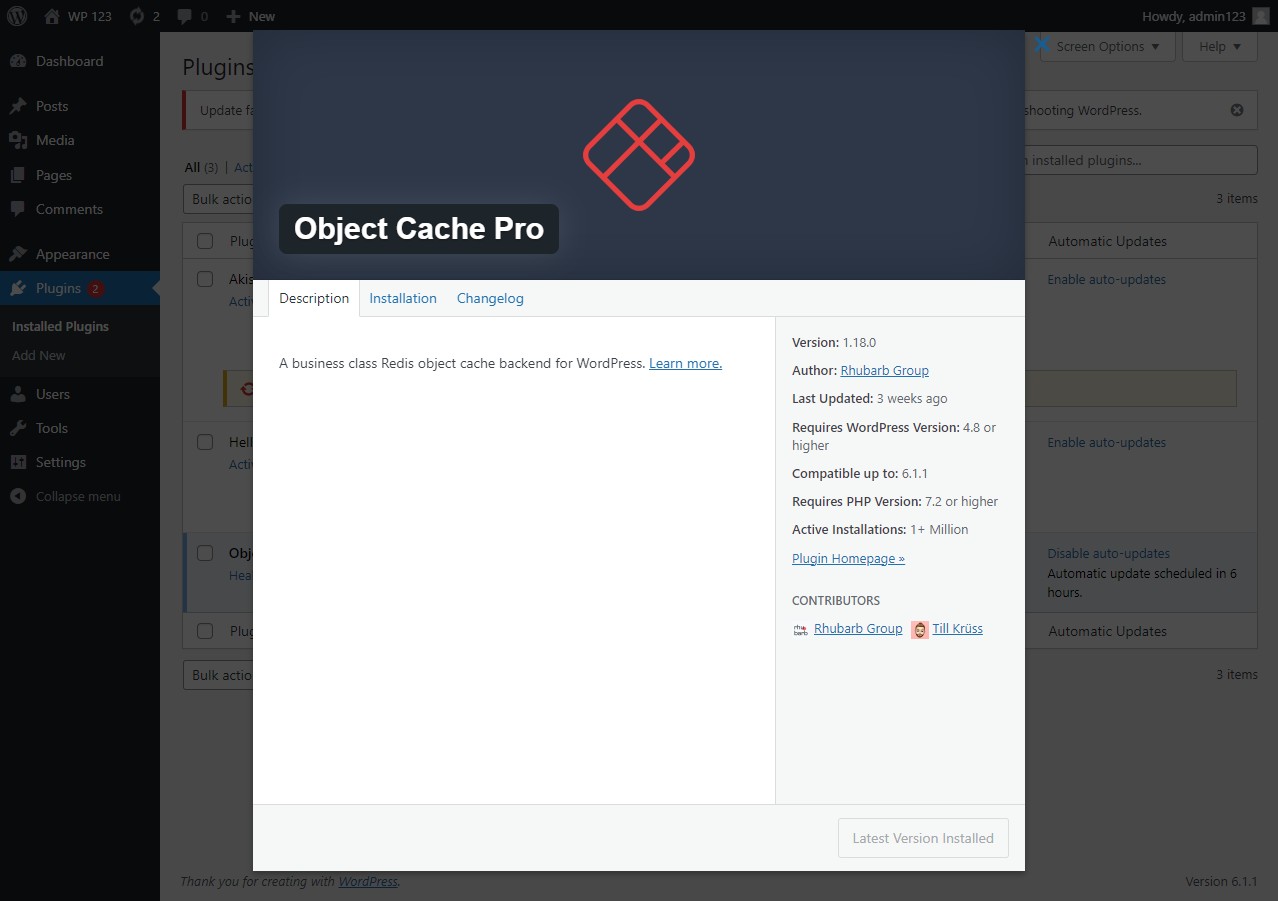
    Go to the plugins menu and click on “View Details” next to Object Cache Pro – a modal will appear with information about the plugin. Make sure it says “Latest Version Installed” on the bottom right. If you’re using an older version, simply update it.

    After this, enable auto-updates to update the plugin automatically when a new version is released.

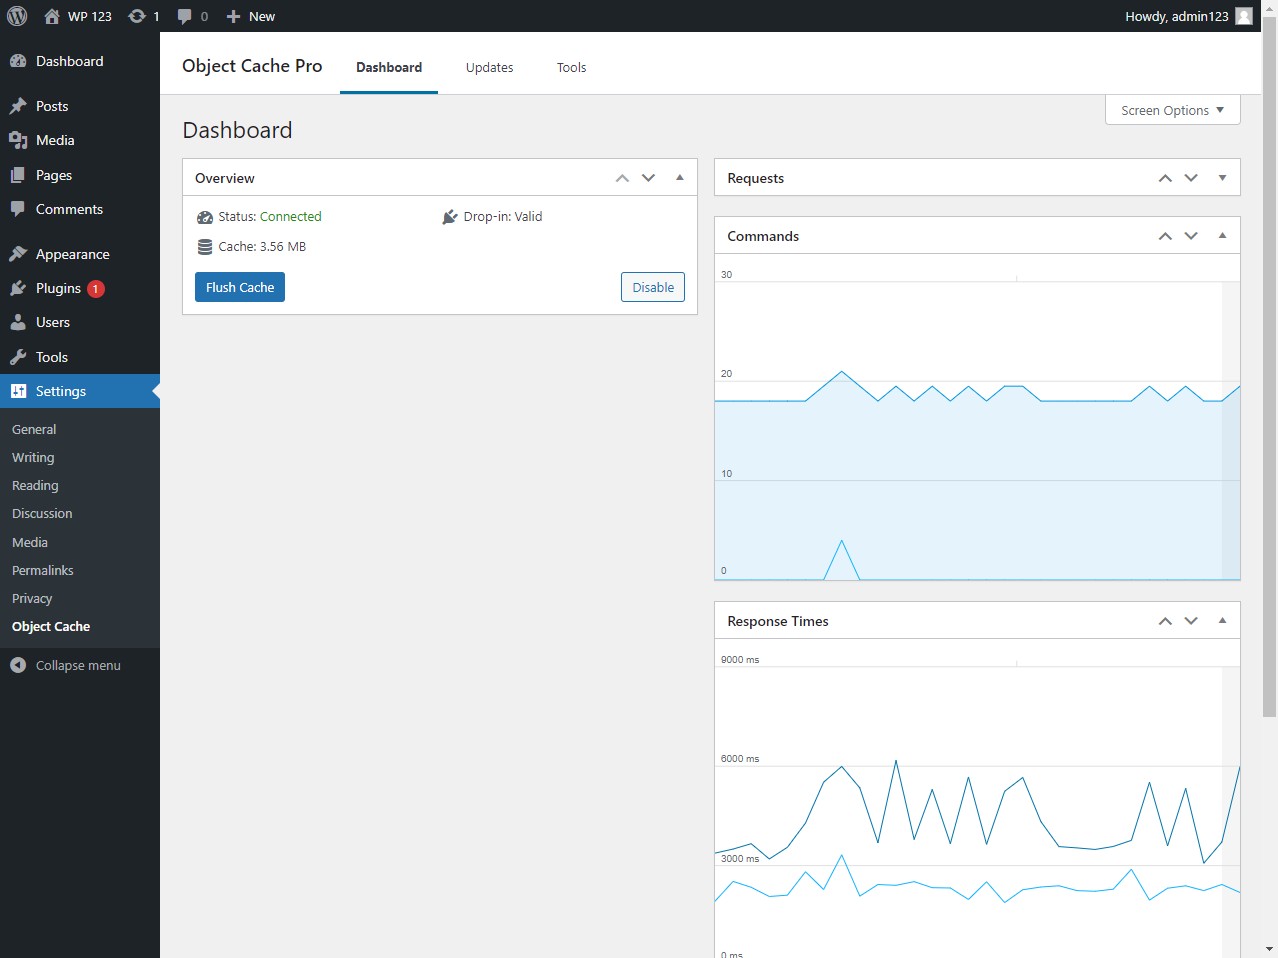
    After installing the plugin, you can open its settings to check whether everything is working correctly. You should see “Status: Connected” in the widget on your Dashboard. If not, head to Tools > Site Health for more information.

    After Action Report

    Object Cache Pro can greatly enhance the performance and speed of your WordPress website by reducing the database load and server response time. The step-by-step guide provided in this article should help you successfully set up object caching on your WordPress website.

    If you find this guide useful, you should also read:

    If you are looking for an easy-to-use platform to manage your server and save time and resources, give your website the best chance to shine by signing up for RunCloud.

    With RunCloud, you can easily deploy, manage, and monitor your server. Give RunCloud a try today and take your website’s performance to the next level.

  • How to Set Up Cloudflare Tunnel to Access Your Server Without Opening Ports (2026 Guide)

    How to Set Up Cloudflare Tunnel to Access Your Server Without Opening Ports (2026 Guide)

    Exposing public ports on your server is a bit like leaving your front door wide open. If you’re managing Linux instances or running a web server, your systems are likely being pinged thousands of times a day by automated bots and scanners.

    In the past, securing a server meant taking on the headache of complex firewall rules, juggling SSH keys, or setting up jump hosts. But there’s a better way. Cloudflare Tunnel simplifies this approach by letting you expose your web applications, SSH access, and databases to the internet or only to authorized users, without opening a single inbound port on your firewall.

    In this guide, we’ll walk through how Cloudflare Tunnel works, how it compares with traditional VPNs and proxies, and the step-by-step process for getting it running on Ubuntu or Debian.

    What is Cloudflare Tunnel?

    Before we talk about Cloudflare Tunnel, let’s first look at how we’ve traditionally handled server access. Usually, when you connect via SSH or access a web app, traffic flows from your device across the internet directly to your server’s public IP address. That requires your firewall to keep those “doors” (ports 80, 443, and 22) wide open.

    Cloudflare Tunnel flips this dynamic entirely. Instead of your server listening for incoming connections, a lightweight background process, the cloudflared daemon, reaches out to Cloudflare’s edge data centers. Because the connection is strictly outbound, your server’s firewall can safely block all incoming traffic. You don’t even need a public IP address.

    How the Daemon and Named Tunnels Work

    When you set up a “Named Tunnel,” Cloudflare assigns it a unique ID (UUID) and creates a set of cryptographic credentials. Your cloudflared daemon uses these to stay connected. When a user tries to access your domain, Cloudflare routes that request through this secure, pre-established tunnel directly to your daemon, which then proxies it locally to your app or service.

    The cloudflared daemon connects to Cloudflare using these credentials. When a user requests your domain, Cloudflare passes that request through the secure tunnel directly to cloudflared, which proxies it locally to localhost:80, localhost:22, or whichever internal port your app uses.

    CloudFlare tunnel website screenshot

    Suggested read: Enable Zero-Trust SSH with Cloudflare on Windows, Mac, Linux, and ChromeOS 

    Comparing Cloudflare Tunnel to a VPN

    You might be wondering, “Why not just use a VPN?” While they both provide access, they serve different needs:

    • Cloudflare Tunnel works at the application layer (Layer 7). It’s perfect for exposing specific services, like a website or SSH, without giving someone keys to your whole network.
    • Traditional VPNs work at the network layer (Layer 3). They directly connect your device to the remote network and grant access to every IP address and port on that subnet.

    If you need full network-level routing, a dedicated VPN, or a mesh network like Tailscale is usually the better tool. But for securing individual apps or SSH access, Cloudflare Tunnel is hard to beat.

    Cloudflare Tunnel vs. VPN vs. Reverse Proxy

    If you’re trying to figure out which tool fits your infrastructure, here’s a quick breakdown:

    FeatureCloudflare TunnelTraditional VPNReverse Proxy (NGINX/Caddy)
    Inbound Firewall PortsNone (0 ports open)Requires 1 open portRequires ports 80 & 443 open
    Public IP Required?No (works behind CGNAT)YesYes
    Traffic ScopeApplication-level (Layer 7)Network-level (Layer 3)Application-level (Layer 7)
    Access Control IntegrationBuilt-in Zero Trust / SSORequires external AAA/RADIUSRequires manual auth modules
    DDoS ProtectionIncluded via CloudflareRequires third-party mitigationExposed to direct IP attacks

    Step-by-Step Instructions for Configuring Cloudflare Tunnels

    Now that we’ve covered the fundamentals and how Cloudflare Tunnel compares to traditional networking methods, let’s dive into setting it up. In the following section, we’ll walk you through the step-by-step process of installing and configuring Cloudflare Tunnel directly on your Linux server.

    Step 1: Getting Started with cloudflared

    Cloudflare allows you to create Quick Tunnels for free without creating a Cloudflare account. This is useful for previewing and shipping ideas globally in seconds. However, in this section, we will build long-lasting, remotely managed tunnels, and the quickest way to do so is from the Cloudflare dashboard.

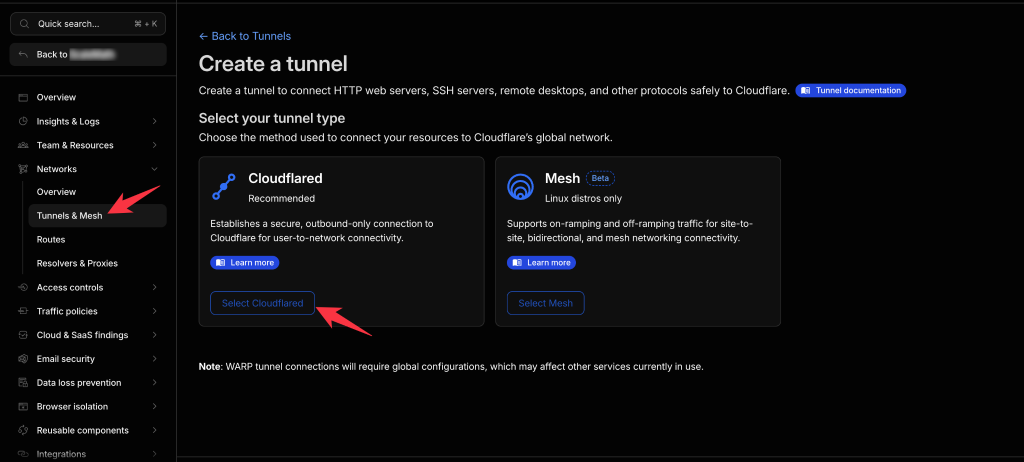
    Log in to your Cloudflare account and open the Tunnel management page. You can access this from Zero Trust > Networks > Tunnels & Mesh > Cloudflared.

    Cloudflare zero trust tunnel and mesh

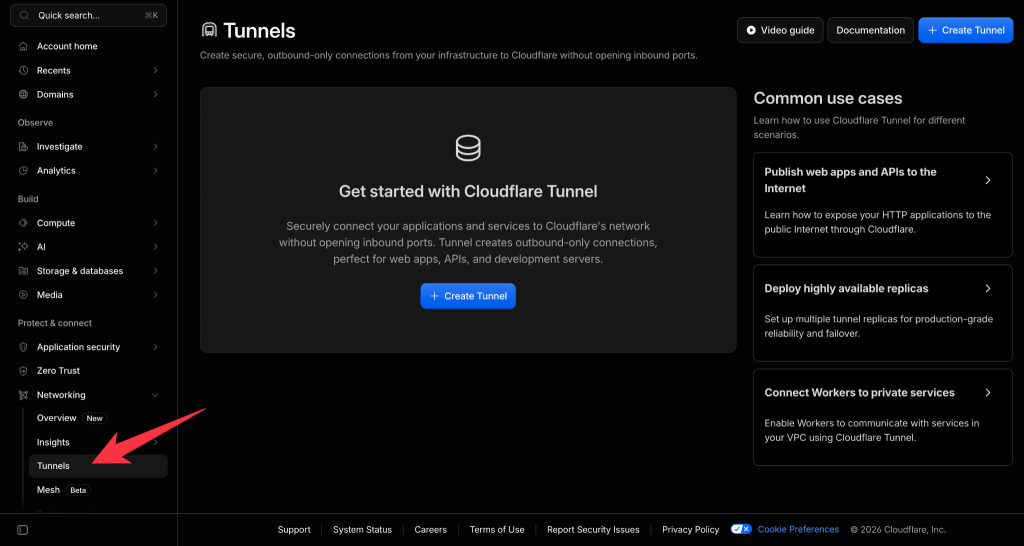
    Alternatively, you can also access the same Cloudflare Tunnel menu by navigating to Networking > Tunnels.

    Cloudflare tunnel dashboard

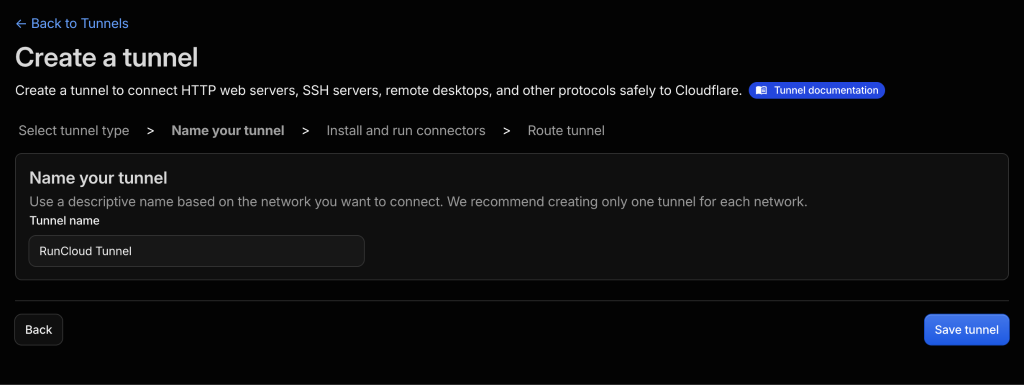
    On the next screen, you need to provide a descriptive name for your tunnel. After entering the name, click “Save tunnel” to create a new tunnel. 

    creating a cloudflare tunnel

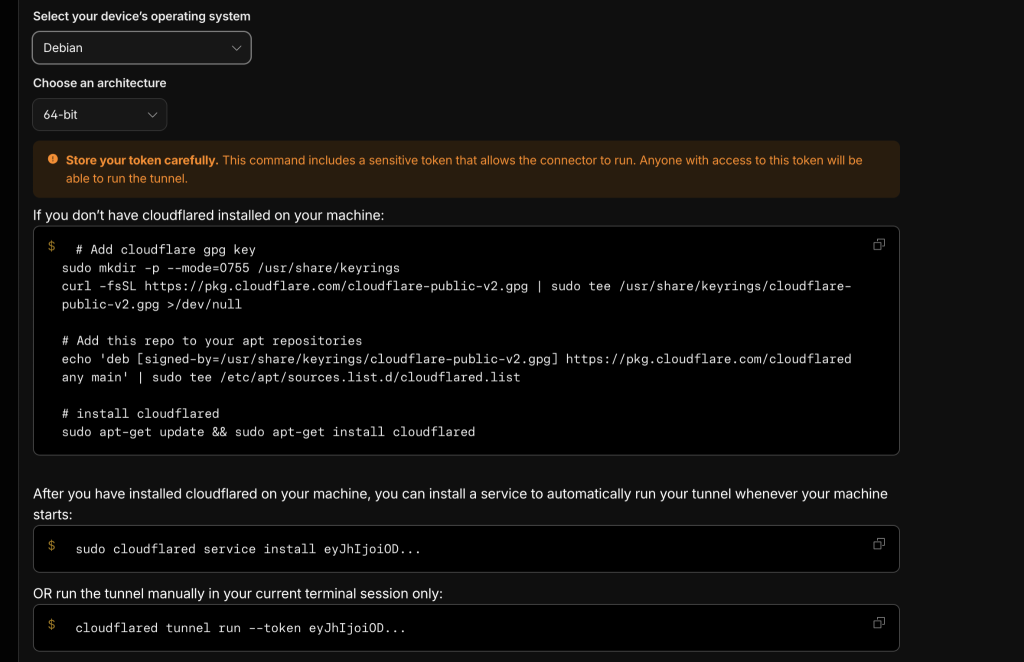
    With your tunnel configured, the next step is to install the cloudflared daemon on your server to establish the connection. The Cloudflare dashboard provides the installation commands for all operating systems. Simply copy and paste them into your terminal to get everything up and running.

    Suggested read: Cloudflare DNS for RunCloud (Security & Performance) 

    Authenticating the Daemon

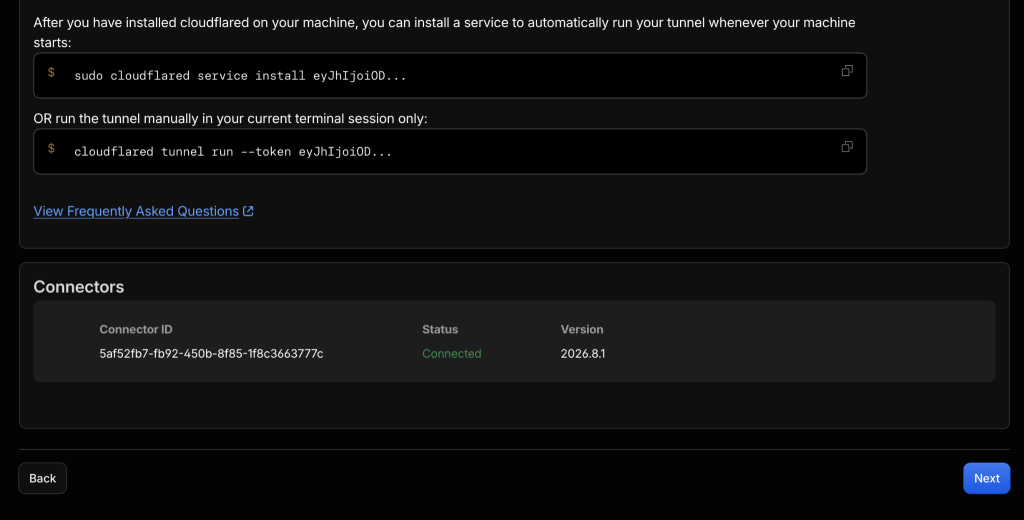
    After the installation is complete, you’ll need to link your server to your Cloudflare account. If you followed the steps, you will see two commands on your Cloudflare dashboard. After you have installed cloudflared on your machine, you can pick what you want:

    • Install a service to automatically run your tunnel whenever your machine starts.
    • Run the tunnel manually only in your current terminal session.

    Copy and paste whichever command you wish to use. For this tutorial, we will only create a one-time tunnel. 

    Cloudflare tunnel installation commands

    Once the tunnel is up and running, you will see your device listed in the Cloudflare dashboard. If you want, you can install the daemon on more devices using the same command, or scroll to the bottom and click Next to add routes.

    Cloudflare tunnel commands

    Suggested read: How to Use Cloudflare Firewall Rules to Protect Your Web Application 

    Step 2: Publish Application Route

    Now that your tunnel is running, you can securely expose your local applications to the internet directly from the Cloudflare dashboard without needing further CLI commands.

    To publish your application route:

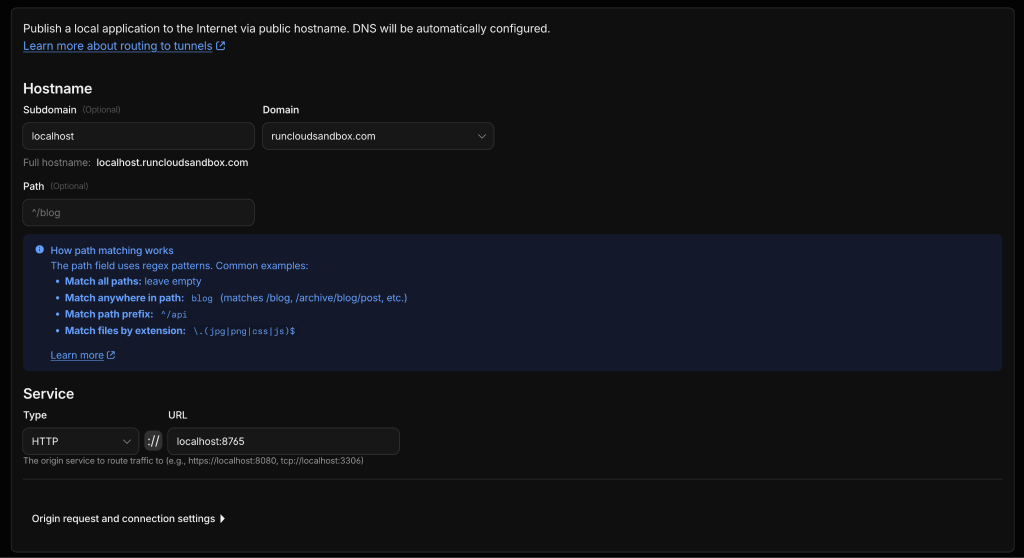
    1. Under the Hostname section, enter your desired subdomain (e.g., ‘localhost’) and select one of the domains connected to your Cloudflare account.
    2. Optionally, specify a path to route specific URL paths to this service, or just leave it blank.
    3. In the ‘Service’ section, select the protocol (e.g., HTTP) and enter the local address of your application. For example, if your app runs on ‘localhost:8765’, enter ‘localhost:8765’.
    4. After making the necessary changes, save the settings. 
    Cloudflare tunnels setup

    Once saved, your application will be accessible via the public hostname you configured (e.g., ‘localhost.runcloudsandbox.com’). Anyone on the internet can now access your application as long as your tunnel is up and running. To stop unwanted visitors from viewing your application, we will now add Access policies to restrict traffic.

    Cloudflare Tunnels are not limited to standard HTTP traffic. You can easily route HTTPS, RDP, SSH, arbitrary TCP, and virtually any other protocol through them. The platform is extremely flexible and allows you to connect almost any self-hosted service or application. 

    Suggested read: Protect Your WordPress Login Pages with Cloudflare Zero Trust 

    Step 3: Secure Your Route with Cloudflare Zero Trust

    To prevent unauthorized users from accessing your server, you can secure it with Cloudflare Zero Trust. Whether you are protecting web applications, CLI connections, or SSH access, Cloudflare Zero Trust lets you gate access with identity controls. 

    While Cloudflare supports a wide range of authentication methods, this guide focuses on setting up a simple email-based One-Time Password (OTP) for quick setup.

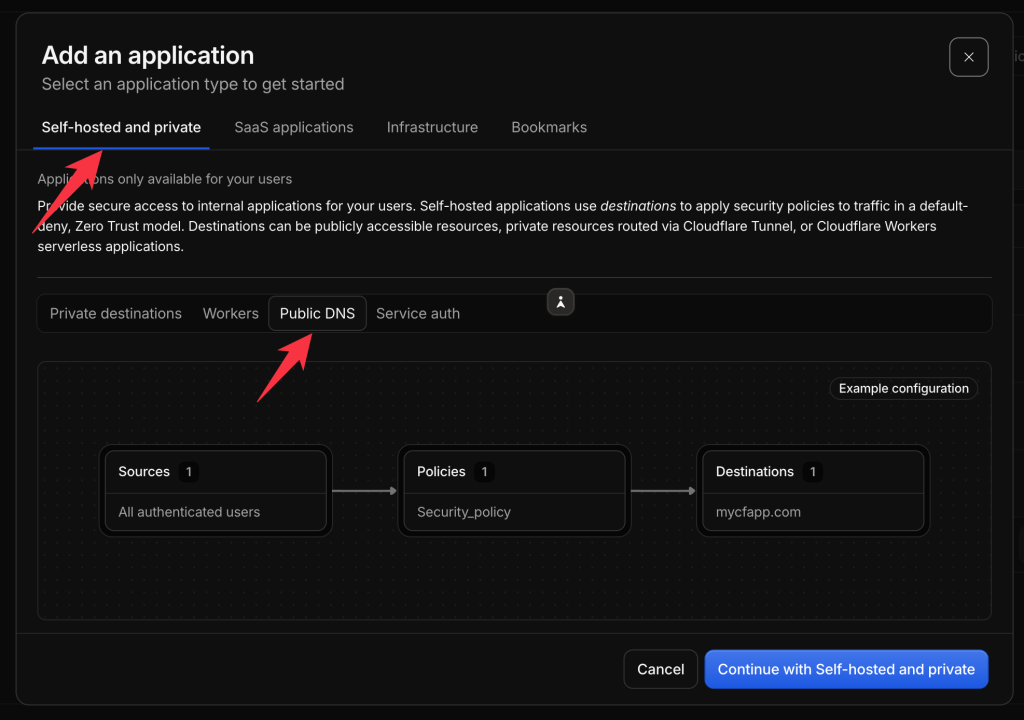
    1. Navigate to Zero Trust > Access Control > Applications.
    2. Add a new Self-hosted application using the Public DNS template, then click Continue.
    application setup in cloudflare zero trust
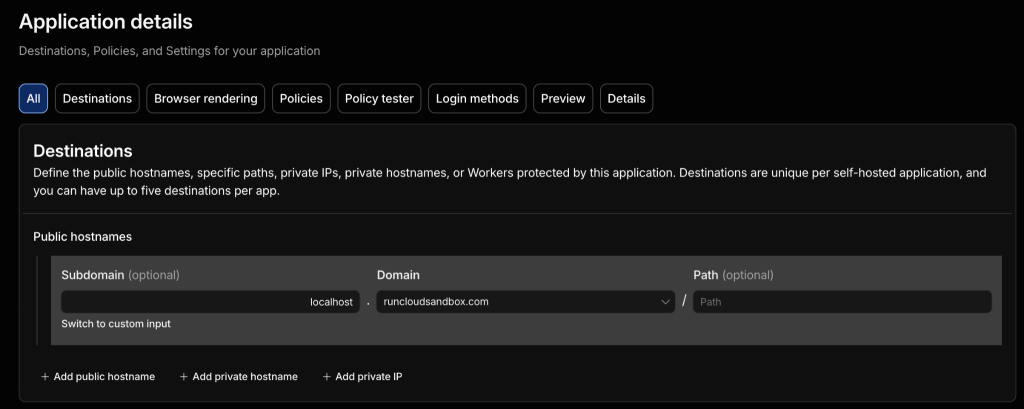
    1. On the next screen, under the Destinations section, set the subdomain, domain, and path settings to the same values that you configured in Step 2.
    domain setup in cloudflare zero trust
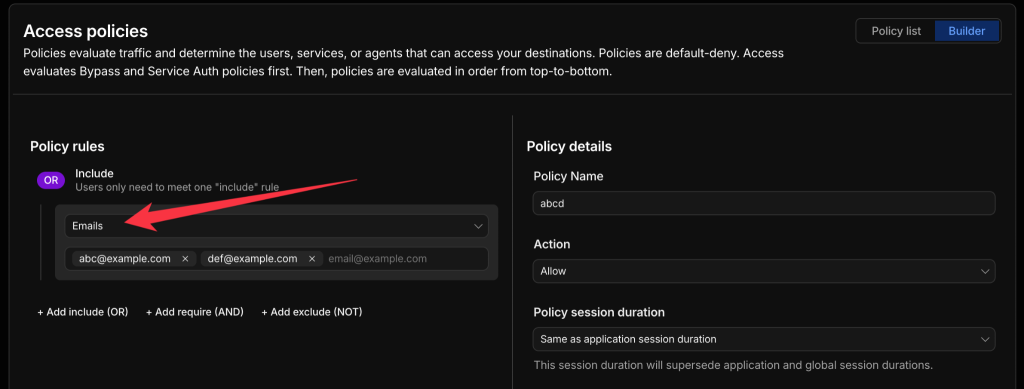
    1. Under the access policies section, create a new policy and create an access rule. You can create very complex rules as per your requirements. But to keep things simple, you can select “Email” from the dropdown and enter the list of email addresses that you want to allow access to. 
    access policies in cloudflare zero trust
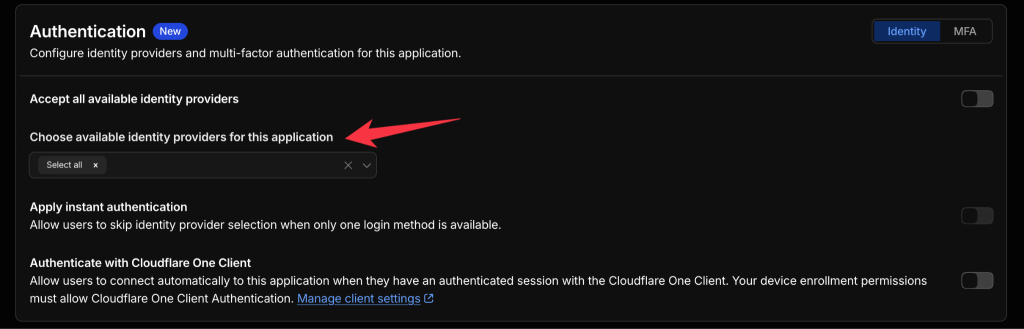
    1. After setting up your policy, you need to configure an identity provider. Scroll down to the Authentication section and under the “Choose available identity providers for this application” dropdown list, select “one-time pin”.
    2. After configuring your changes, save your settings. It usually takes a couple of minutes to take effect. 
    Authentication methods in Cloudflare zero trust
    1. After saving, anyone who tries to access your protected path will see this security prompt before they can access your application.

    Suggested read: The 8 Best Cloudflare Alternatives in 2026 

    A Simpler Alternative: RunCloud Web Terminal

    While Cloudflare Tunnel is excellent for many use cases, you might be looking for a more streamlined way to access your server’s shell without the overhead of local configurations. That’s where the RunCloud Web Terminal comes in.

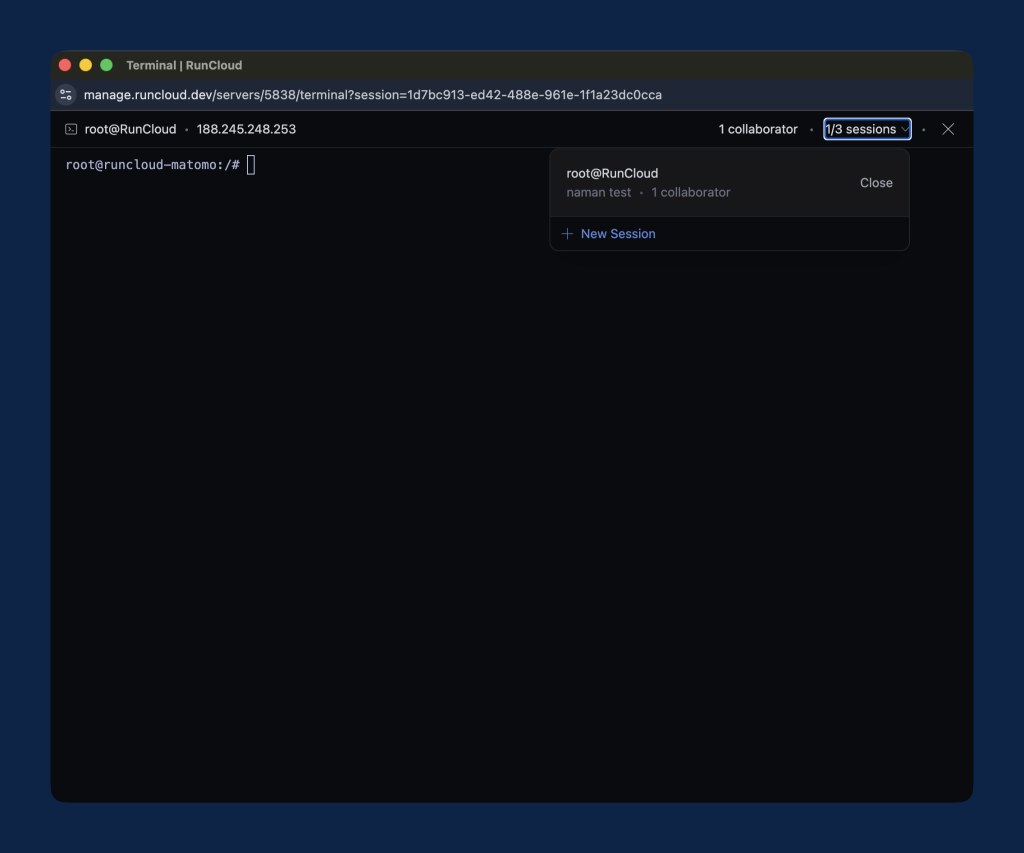
    This feature provides a collaborative, browser-based shell right in your RunCloud dashboard. It’s perfect for when you need to inspect logs, run a quick command, or collaborate with a teammate without opening ports or managing SSH keys locally.

    RunCloud web terminal dashboard

    Why you’ll love the RunCloud Web Terminal:

    • Zero Local Hassle: Access your shell from any device with a browser.
    • No Key Management: Forget about distributing and rotating SSH keys; access is handled securely through RunCloud’s permissions.
    • Enhanced Security: It’s off by default and requires 2FA, ensuring only you or those you authorize can access the shell.
    • Real-Time Collaboration: You and your team can work in the same terminal window, making debugging a collaborative effort.
    • Encrypted & Safe: Everything happens over an encrypted WebSocket connection via the RunCloud agent, keeping your secrets safe.

    It’s a fantastic way to maintain control while keeping your server’s SSH ports locked down.

    Wrapping Up

    Cloudflare Tunnel improves server security by eliminating the need to leave ports open. By routing your web apps, databases, and custom protocols through secure, outbound-only connections, you can unlock true Zero Trust protection against port scans and automated attacks.

    However, when you pair this with RunCloud, managing a secure infrastructure becomes even simpler. RunCloud takes your server management to the next level with built-in features like the RunCloud Web Terminal. This feature comes configured out of the box, and there is no need to configure additional policies or install daemons, so it is quick and easy to access your command line securely without ever exposing SSH ports to the public internet.

    Start your journey with RunCloud today.

    Frequently Asked Questions

    Is Cloudflare Tunnel free?

    Yes, Cloudflare Tunnel is completely free to use as part of the Cloudflare Zero Trust platform. You can connect your server to Cloudflare without paying for extra bandwidth or connection limits. This makes it an affordable, enterprise-grade solution for securing your web applications and managing your servers.

    Is Cloudflare Tunnel secure enough for production servers?

    Yes, Cloudflare Tunnel is built for production environments and uses outbound-only connections to prevent unauthorized access. By eliminating the need to open inbound public ports on your firewall, it protects your server from direct IP-based attacks and port scans. You also get automatic encryption and full integration with Cloudflare security and DDoS protection features.

    What is the difference between Cloudflare Tunnel and a VPN?

    A traditional VPN grants users full network access to your entire infrastructure, which creates significant security risks if a device is compromised. In contrast, Cloudflare Tunnel safely exposes only specific applications without exposing your underlying network or server IP address. 

    Can I tunnel SSH and a web app over the same cloudflared instance?

    Yes, a single cloudflared daemon instance can route multiple services simultaneously. You can configure your setup to direct web traffic to port 80 and SSH traffic to port 22 simultaneously. This setup lets you manage server access and web applications efficiently through one secure connection.

    What happens to my tunneled services if Cloudflare has an outage?

    If Cloudflare experiences an outage, your tunneled services will become temporarily unreachable from the public internet. However, your underlying server and applications remain safe and operational behind your firewall. Once Cloudflare restores its global network, the cloudflared daemon automatically reconnects your services without requiring a server reboot.

    Should I tunnel my database with Cloudflare Tunnel?

    You can tunnel database connections for internal administration or secure remote access between private servers. However, you should not expose database ports directly to the public web for general application traffic. Combining Cloudflare Tunnel with Cloudflare Access ensures that only authenticated administrators can securely access your database.

  • The 11 Best Website Uptime Monitoring Tools Compared (2026)

    The 11 Best Website Uptime Monitoring Tools Compared (2026)

    Downtime costs money and credibility. For SaaS companies and online businesses, a few minutes offline can mean lost customers, broken trust, and missed revenue. That’s why choosing the right website uptime monitoring tools is more than a technical decision – it’s a business priority.

    But with dozens of options on the market, how do you know which tool gives you the reliability, features, and pricing your team needs?

    We’ve tested and compared the best website uptime monitoring tools in 2026, breaking down their core features, pricing, and use cases so you can make a confident, informed choice.

    You’ll leave with a short list that fits your budget and growth plan – and keeps your site online.

    What is Website Uptime Monitoring?

    Website uptime monitoring means checking (from multiple locations) that your site loads and works, and alerting you the moment it doesn’t.

    A monitoring service is an automated system that continuously checks your website from multiple global locations. If this service detects that your site is down, slow, or displaying an error, it quickly alerts you via email, SMS, Slack, or similar channels.

    Why Uptime Monitoring is Essential for Websites

    Launching a website isn’t enough – what matters is keeping it online, fast, and reliable every hour of the day. For SaaS businesses, uptime isn’t just about user experience – it directly affects customer retention, revenue, and SLA commitments. Here’s why uptime monitoring matters:

    Improved Website Reliability and User Trust

    When users try to visit your site and find it unavailable, their trust in your brand diminishes. A website that is frequently down appears unprofessional and unreliable. Consistent uptime builds confidence and shows users that you are a dependable business, which is important for retaining visitors and customers.

    Faster Incident Response and Reduced Downtime

    Without monitoring, the first sign of downtime often comes from frustrated customers or public complaints. By that point, you’ve already lost revenue and credibility. Uptime data helps you prove SLA compliance, report to stakeholders, and keep customer trust.

    Better SLA Compliance and Performance Tracking

    Most SaaS businesses commit to strict uptime SLAs – often 99.9% or higher. Uptime monitoring provides the data to demonstrate compliance, generate reports for stakeholders, and build trust with customers and investors. It also provides long-term performance history, helping you spot recurring issues before they escalate.

    Data-Driven Insights for Optimization

    Modern tools track more than availability – latency, page speed, and regional performance are included. For instance, if you consistently see high latency in Asia, you can add a CDN to reduce slow-region drop-offs.

    Suggested Read: Uptime Monitoring Tools: Why You Need Them, and What to Look for

    Key Metrics Tracked by Uptime Monitoring Tools

    Uptime monitoring isn’t just a simple “yes” or “no” check. These tools track several key metrics to give you a complete picture of your website’s health.

    • Uptime Percentage: This is the percentage of time your website was online and available over a specific period (e.g., 99.95% in the last 30 days). This is the headline reliability number you’ll report to leadership and clients.
    • Response Time (Latency): This measures how quickly your server responds to a request. A sudden spike in response time can be an early warning that your server is overloaded, even before it goes down. Consistently slow response times in a specific geographic area can indicate that you need to optimize your infrastructure for that region.
    • Page Load Time is the total time it takes for a webpage to fully load in a user’s browser. This metric is one of the most important factors for user experience, as slow-loading pages lead to high bounce rates. Tracking this helps you identify if a recent code change or a large image negatively impacts performance.
    • HTTP Status Code Errors (e.g., 404, 500): This tracks the error codes your server sends back. A surge in “404 Not Found” errors could indicate broken links on your site after a redesign. A “500 Internal Server Error” means your application has a serious problem that needs immediate attention.
    • SSL Certificate Status: This check ensures your website’s SSL certificate is valid and not expired. This prevents the ‘Your connection is not private’ browser warning. However, if you are using RunCloud, then RunCloud renews SSL certificates one month before expiry.

    Suggested Read: Using Dynatrace to Monitor RunCloud Servers

    Top 11 Website Uptime Monitoring Tools Compared

    ToolFree PlanCheck FrequencyKey FeaturesBest ForStarting Price (USD)
    Better StackYes – 10 monitors, 3-min checks30 sec (paid), 3 min (free)Monitoring + incident management, status pages, integrationsTeams needing integrated monitoring + incident response$24/
    UptimeRobotYes – 50 monitors, 5-min checks5 min (free), 1 min (paid)Simple setup, generous free plan, status pagesStartups, small businesses, personal projects$7–8/mo
    PingdomNo (Paid from $10/mo)1 min+Synthetic checks, RUM, transaction monitoring, diagnosticsGrowing SaaS teams needing end-to-end visibility$10/mo
    Site24x730-day trial only1 min+All-in-one: uptime, RUM, server, API monitoringTeams needing one platform for uptime, RUM, servers, and APIs$35/mo
    Oh DearNo (10-day free trial only, no credit card required)Every 1 minuteBroken link crawler, scheduled task/cron monitoring, application status pagesWeb agencies, PHP/Laravel developers, sysadmins, and SaaS founders€15/month (up to 2 sites)
    StatusCakeYes – 10 monitors, 5-min checks30 sec–5 minUptime, page speed, domain & SSL checks, status pagesAgencies or small teams needing broad coverage$15/mo
    DatadogNo (Paid per test)1 min+Synthetic monitoring, APM/logs integration, self-healing testsMedium/large SaaS with complex systems$5 per 10k API tests
    New RelicYes – 100 checks/moVaries by usageSynthetic checks linked with APM, full-stack correlationTeams already using New Relic APMConsumption-based – free tier available
    UptrendsNo (Pay-as-you-go credits)30 sec–5 minConcurrent global monitoring, transaction flows, error snapshotsTeams needing accuracy & minimal false positives$5/mo (credits)
    SematextPay-as-you-go available1 min+Uptime + API monitoring, Core Web Vitals, public/private locationsTeams needing both public & internal monitoring$29/mo
    PulseticYes – Basic uptime + status page1–5 minUptime + branded status pages, simple incident commsTeams that prioritize clear incident comms with branded status pages, startups, and agenciesFrom $9/month (Solo)

    Better Stack

    Better Stack is more than an uptime checker – it’s a full incident management and monitoring platform. For teams running SaaS products or high-traffic websites, it helps ensure issues are caught quickly, alerts reach the right person, and communication with users stays clear. With checks running as often as every 30 seconds from multiple global locations, you avoid false positives and get accurate visibility. Its incident timelines, screenshots, and integrations with tools such as Slack, Datadog, and AWS make it suitable for teams that route alerts into Slack/PagerDuty and need on-call scheduling.

    Key Features

    • 30-second multi-location checks with screenshots and detailed logs
    • Incident management tools with on-call scheduling and smart alert merging
    • Integrations with major platforms (Datadog, Prometheus, Grafana, AWS, GCP, etc.)
    • Customizable public status pages for transparent communication
    Better Stack homepage promoting its monitoring and incident response platform.

    Pricing

    • Free plan includes basic checks, alerts, and status page functionality.
    • Paid tiers (from $29/month) add faster monitoring, richer alerting, and team workflows.

    When to Choose This Tool

    Better Stack is ideal if you need more than just basic monitoring. It’s a strong fit for SaaS companies, agencies managing multiple clients, and larger projects with dedicated support teams. Its greatest strength is combining monitoring with incident response, saving time and reducing missed alerts. If you’re solo or on a tiny project, it’s more than you need.

    Suggested Read: How UptimeRobot Can Save Your Website from Downtime Disasters

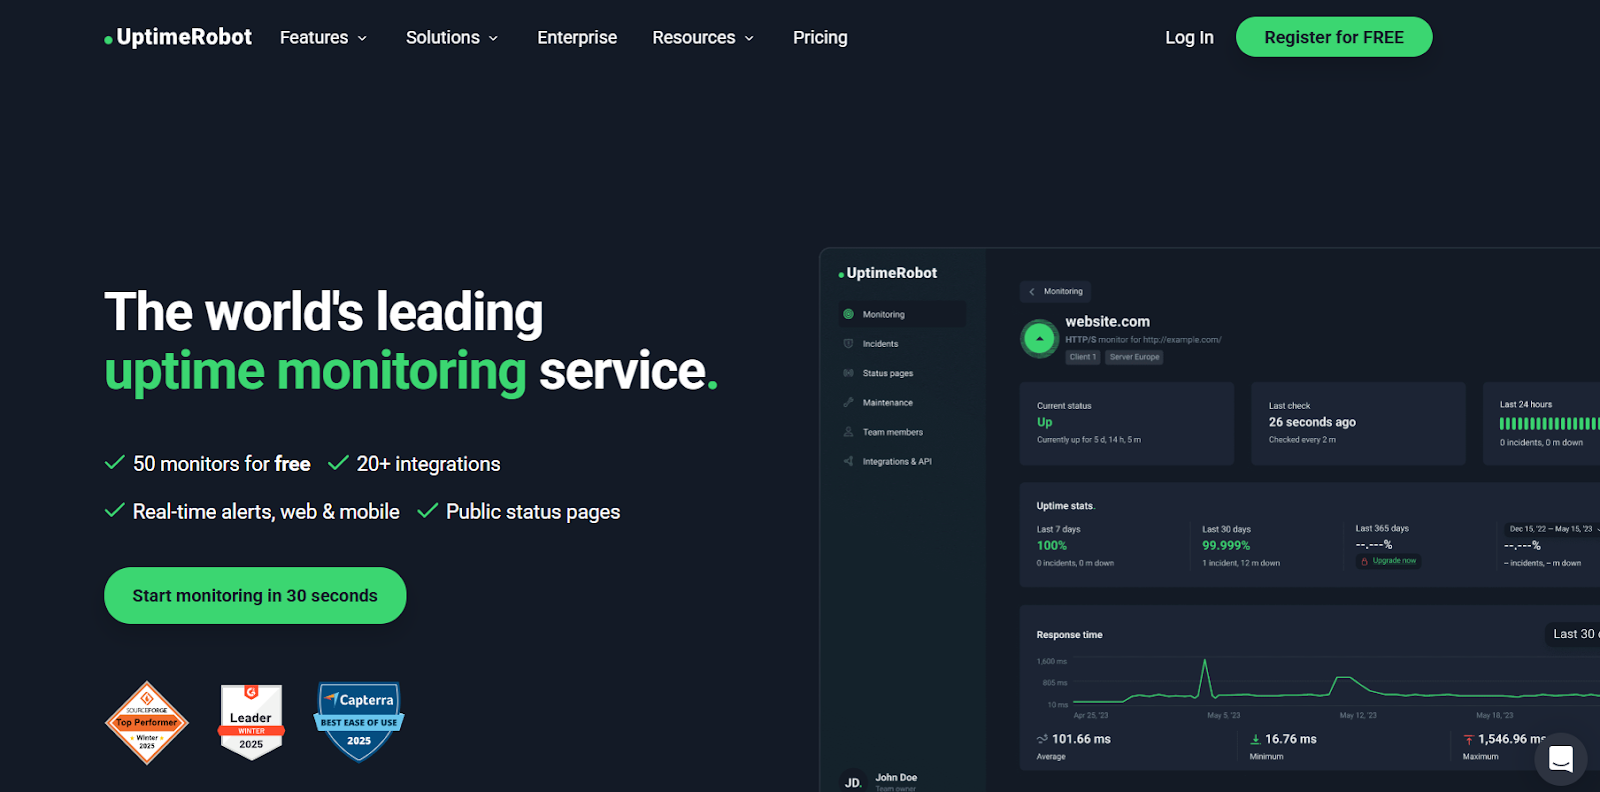
    UptimeRobot

    UptimeRobot is one of the most popular website uptime monitoring tools thanks to its simplicity and generous free plan. Setup takes minutes – add a URL, and you’re done. It covers the essentials without adding complexity, and supports HTTP(s), ping, port, keyword, SSL, and heartbeat monitoring. For small businesses, personal projects, or startups, it’s a cost-effective way to stay ahead of downtime before customers notice.

    Key Features

    • Free plan with up to 50 monitors checked every 5 minutes
    • Paid plans (from $7/month) offer 60-second checks, SSL/domain expiry alerts, and longer log retention
    • Status pages (public or private) for sharing uptime performance with customers or teams
    • Alerts delivered via email, SMS, Slack, MS Teams, Telegram, and more

    Pricing

    • Free: 50 monitors, 5-minute intervals
    • Pro plans: from $7/month for 60-second checks and advanced features
    • Higher tiers include more monitors, faster checks, and enterprise-ready features
    UptimeRobot homepage showing its uptime monitoring dashboard and website performance statistics.

    When to Choose This Tool

    UptimeRobot is best suited to small businesses, personal sites, and early-stage startups that need dependable monitoring without high costs. The free plan is among the most generous available, making it a great entry point. Free checks run every 5 minutes – fine for basics, but not for mission-critical apps, so larger SaaS companies will likely need to upgrade to faster paid plans or consider a more advanced solution.

    Suggested Read: How to Reduce Cache Misses & Avoid Them: Proven Tips [FIXED]

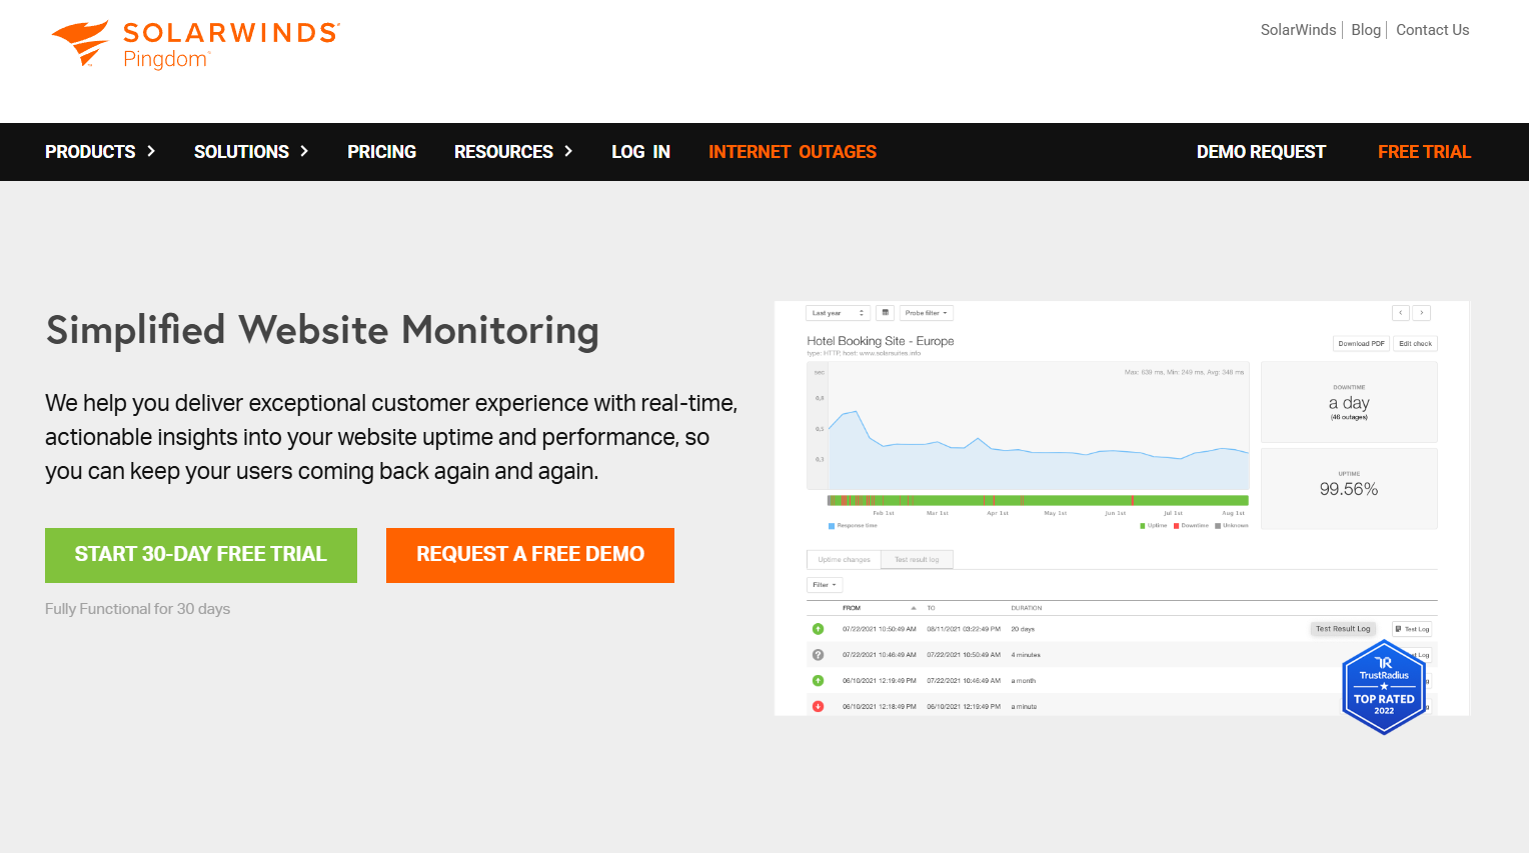
    Pingdom

    Pingdom is a robust website and digital experience monitoring platform. It covers uptime checks, synthetic user flows, real-user monitoring (RUM), and page speed analysis – all from one dashboard. Plans start at $10/month and scale to high-volume enterprise use with thousands of checks, making it a strong fit for growing digital businesses.

    Key Features

    • Synthetic monitoring from 100+ global locations; instantly detect outages.
    • Transaction and page speed monitoring; includes root-cause tools like traceroutes and server response insights.
    • Real User Monitoring provides insights into how users experience performance, segmented by browser, geography, and device.
    • Public status pages and rich alerting (SMS, email, Slack, PagerDuty, etc.).
    Pingdom website monitoring page showing uptime and performance data in a monitoring dashboard.

    Pricing

    • Synthetic Monitoring plans begin at $10/month for 10 uptime monitors, one advanced check, and 50 SMS alerts. Scale up to tens of thousands of monitors at higher tiers.
    • RUM plans also start at $10/month for 100,000 pageviews and scale up to 1 billion pageviews.

    When to Choose This Tool

    Choose Pingdom if you need deep, multi-layered insight into your website’s performance and availability. It fits well with growing SaaS companies, high-traffic sites, or agencies managing complex user journeys. You’ll get the most value when you monitor checkout, signup, and other revenue paths end-to-end, but the interface has a learning curve, and pricing can escalate quickly as you scale.

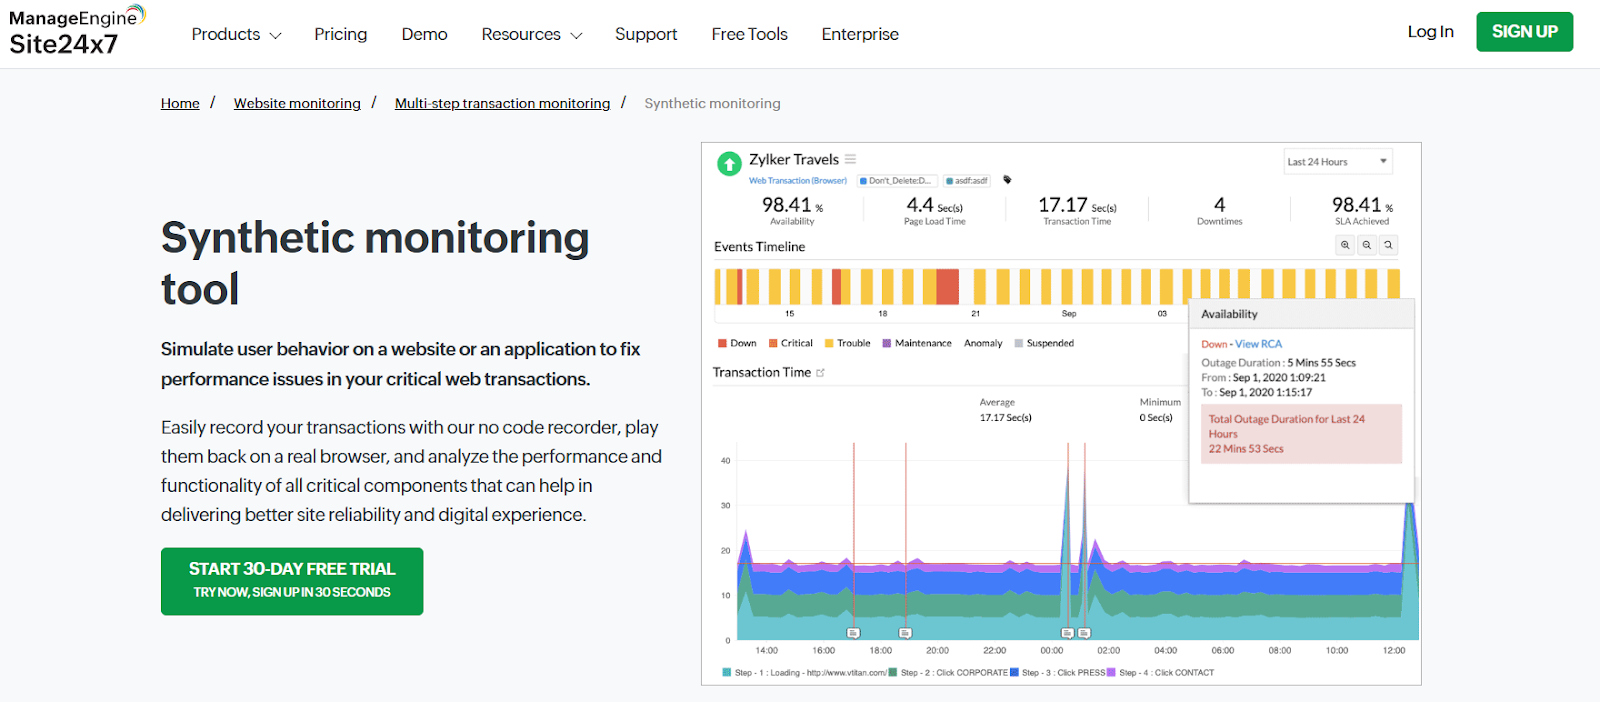
    Site24x7

    Site24x7 is an all-in-one monitoring service from Zoho that goes beyond simple uptime checks. In addition to website availability monitoring, it offers server health tracking, API monitoring, and Real User Monitoring (RUM). With over 120 global test locations, it provides a single convenient dashboard for UX metrics and backend health.

    Key Features

    • Synthetic transaction monitoring simulates user flows such as login, checkout, or search to ensure business-critical processes function correctly.
    • Real User Monitoring (RUM) captures actual visitor performance by device, browser, and region.
    • Server and application monitoring covers CPU, memory, disk, and API endpoints.
    • Global network of 120+ monitoring locations provides detailed regional insights.
    Site24x7 synthetic monitoring page showing transaction performance charts and availability data.

    Pricing

    • Pro Plan: starts around $35/month (billed annually) with website and server monitoring.
    • Classic Plan: $89/month, offering expanded resources and checks.
    • Enterprise Plan: from $225/month, supporting large-scale monitoring needs.
    • All plans include a 30-day free trial.

    When to Choose This Tool

    Site24x7 is a strong choice for mid-sized to large teams who want a unified monitoring solution covering websites, servers, APIs, and user experience. It’s particularly useful for SaaS businesses with complex infrastructure or global audiences, since synthetic and RUM monitoring together provide a full performance picture. Pricing at higher tiers can stretch small budgets – its more advanced tiers can be costly for smaller projects compared to lighter tools like UptimeRobot.

    Suggested Read: How do you check Linux CPU usage or utilization? (5 Ways)

    Oh Dear

    Oh Dear takes a broad approach to website monitoring, combining uptime, SSL certificate, broken link, performance, cron job, and other checks into a single service. All features, including team features such as SSO, are available across its plans, with pricing based primarily on the number of sites you monitor. 

    In addition to basic uptime monitoring, Oh Dear provides a comprehensive health check for your entire website ecosystem.

    It can also monitor application health, API endpoints, scheduled tasks, and other processes that basic uptime checks may miss, alerting you to issues such as SSL certificate problems, broken links, failed cron jobs, and application health failures before they affect users.

    Oh Dear website uptime monitoring page showing response time and monitoring details.

    Key Features

    • Holistic Health Monitoring: Tracks uptime, SSL certificates, broken links, mixed content, DNS records, and domain expiration dates in one place.
    • Deep Application Insights: Monitors scheduled tasks (cron jobs), API endpoints, and application health (queues, storage, cache) to ensure your backend processes are functioning correctly.
    • Performance & SEO: Tracks Lighthouse scores and monitors sitemaps to identify performance and SEO-related issues.
    • Client Reporting: Generates monthly reports and supports customizable status pages for sharing monitoring information with clients.
    • Instant Multi-Channel Alerts: Sends notifications via Slack, email, SMS, PagerDuty, and webhooks the moment an incident is detected.

    Pricing

    Oh Dear offers a transparent pricing structure where every plan includes full access to all features, so you never have to worry about missing out on essential monitoring tools. Pricing is based simply on how many sites you need to monitor:
    • Solo: €15/month for up to 2 sites.
    • Freelance: €49/month for up to 10 sites.
    • Studio: €99/month for up to 25 sites.
    • Larger plans are available for agencies and businesses monitoring more sites.

    When to Choose This Tool 

    Oh Dear is a good fit for web agencies, developers, and SaaS teams that want more than basic uptime monitoring without having to manage several separate services. Its combination of uptime, SSL, broken link, performance, DNS, cron job, API, and application health monitoring is particularly useful when you manage multiple websites or applications.

    It may also suit teams that want predictable access to features, since all plans include the same monitoring and team features. The main pricing variable is the number of sites you need to monitor.

    StatusCake

    StatusCake delivers reliable uptime monitoring, page speed, domain, server, and SSL checks. With 43 testing locations, flexible alerting, and a free tier, it covers uptime, page speed, domain/SSL, and server checks in a simple UI.

    Key Features

    • Flexible uptime checks at intervals as low as 30 seconds (depending on plan).
    • Page speed monitoring, domain expiration notifications, server resource checks, and SSL auditing.
    • Alerting via email, SMS, Slack, Discord, Telegram, and more.
    • Public status pages, sub-account management, tagging, and audit logs for team visibility and client reporting.
    StatusCake homepage showing website monitoring dashboards across desktop, tablet, and mobile devices.

    Pricing

    • Basic (Free): 10 uptime monitors at 5-minute intervals.
    • Superior: $15/month for 100 monitors, 1-minute tests, page speed, domain, server, and SSL monitoring.
    • Business: $50/month for 300 monitors, 30-second checks, team account access, and detailed logging.

    When to Choose This Tool

    StatusCake works when you need a wide feature set out of the box – especially helpful if you must track performance, domains, security, and server health together. It’s well-suited for agencies, small businesses, or teams managing multiple client sites. Benefits include deep visibility and strong alerting flexibility, but there are no RUM or scripted transactions, and some alerts/support options are available only on higher plans.

    Suggested Read: How To Install New Relic Monitoring on RunCloud

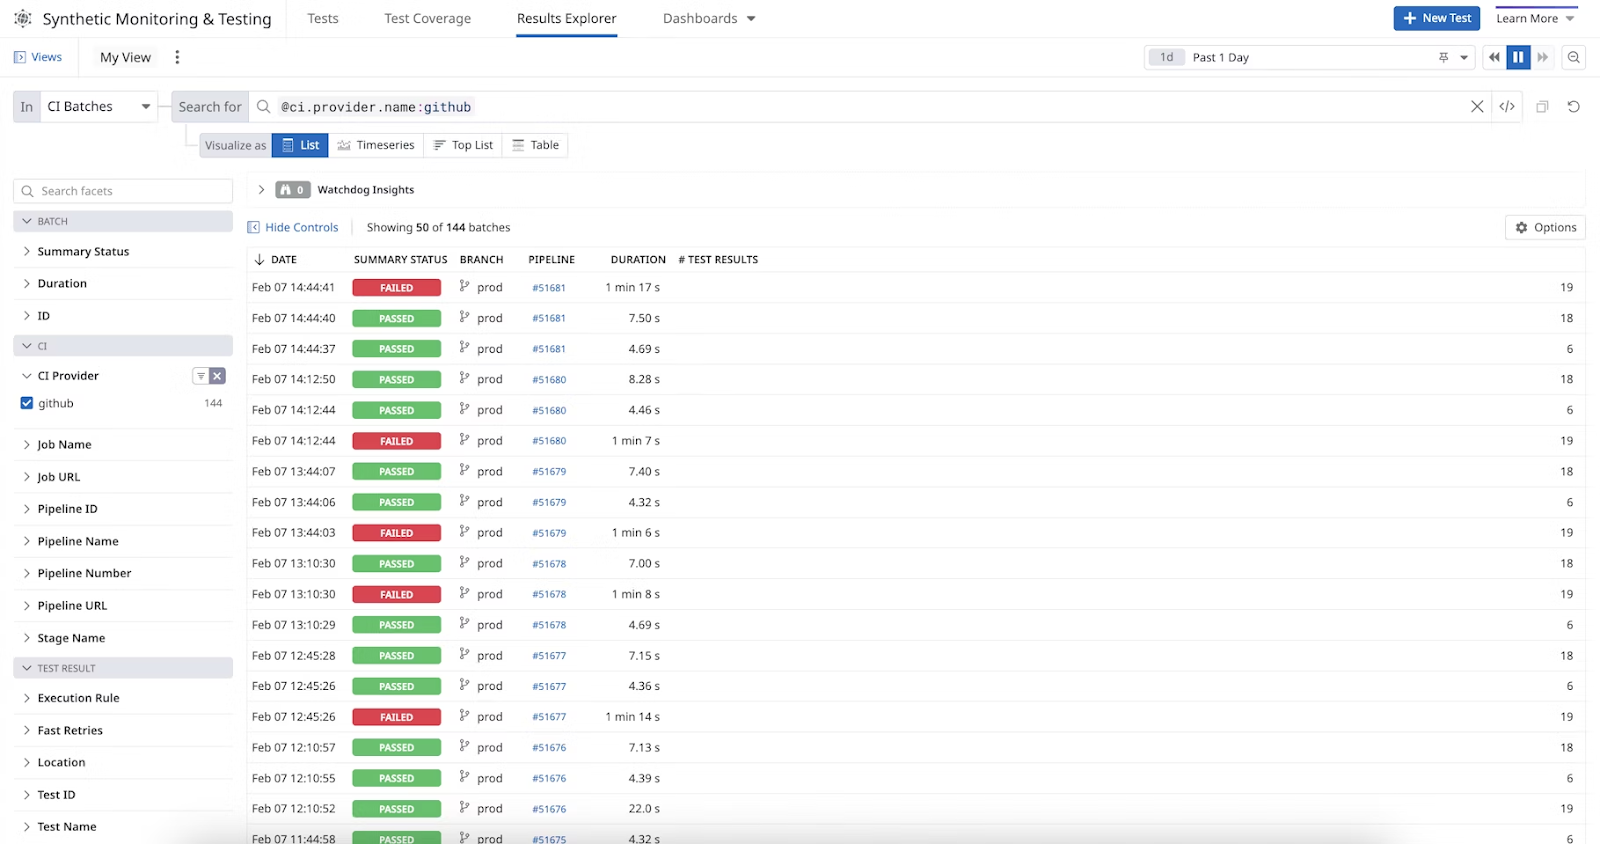
    Datadog

    Datadog is an observability platform that monitors more than just uptime. Its Synthetic Monitoring feature allows you to simulate user journeys and API calls from multiple global locations and correlate failures with backend traces, logs, and infrastructure metrics. This makes it especially valuable for teams running complex SaaS applications, where identifying the root cause of downtime is just as important as detecting it.

    Key Features

    • Codeless browser tests that simulate multi-step user interactions such as signup or checkout.
    • API monitoring with chained requests to validate data flows across services.
    • AI-powered “self-healing” tests that adapt automatically to minor UI changes.
    • Deep integration with Datadog’s wider observability suite: logs, metrics, APM, security monitoring, and incident management.
    Datadog Synthetic Monitoring results showing passed and failed CI test batches.

    Pricing

    • Synthetic API tests: start at $5 per 10,000 monthly test runs.
    • Browser tests: $12 per 1,000 test runs per month.
    • Additional pricing applies for Datadog’s broader observability products (infrastructure monitoring, APM, logs)

    When to Choose This Tool

    Datadog is best suited for medium to large SaaS companies or enterprises that already use – or want to consolidate monitoring within – a full observability platform. Its strength lies in combining uptime checks with deep diagnostics; use it when you need to quickly jump from alert to trace/logs. The main drawback is cost: Datadog can become expensive at scale, and smaller teams that only need uptime monitoring may find it more than they need.

    New Relic

    New Relic is a comprehensive observability platform with built-in synthetic monitoring. Its Synthetics feature allows you to simulate traffic and scripted user journeys from global locations, ensuring that critical workflows such as login, search, and checkout function correctly. Because it integrates tightly with New Relic’s Application Performance Monitoring (APM), logs, and infrastructure tools, it connects synthetic failures to APM traces, errors, and infrastructure data.

    Key Features

    • Browser-based monitoring to simulate multi-step user flows.
    • API monitoring to test endpoints, validate responses, and track performance.
    • Global testing from a distributed fleet of locations.
    • Full-stack correlation: connect synthetic failures directly to APM traces, error logs, and infrastructure data.
    New Relic Synthetic Monitoring page promoting simulated user journey monitoring for web applications.

    Pricing

    • Consumption-based model: you pay for the number of synthetic checks run.
    • Generous free tier includes 100 free synthetic checks per month.
    • Additional usage is billed per check; pricing scales with volume and is bundled into New Relic’s overall observability platform.

    When to Choose This Tool

    New Relic suits SaaS teams and enterprises that want monitoring embedded in a full observability ecosystem. If your developers already use New Relic APM, adding synthetic checks is a seamless way to connect uptime events to performance diagnostics. It’s especially valuable for teams managing complex applications where pinpointing the “why” behind downtime is critical. If you only need basic uptime, it’s heavy, and pricing can be harder to forecast.

    Suggested Read: How To Monitor Your Web App’s RAM & CPU Usage with Netdata

    Uptrends

    Uptrends is a dedicated website and infrastructure monitoring platform with a strong emphasis on accuracy and global coverage. With over 230 checkpoints worldwide, it verifies uptime and performance from multiple locations simultaneously, helping to eliminate false positives. Alongside uptime checks, it offers real browser, API, and transaction monitoring. Use it to script real flows – login, search, checkout – in real browsers.

    Key Features

    • Concurrent monitoring from multiple checkpoints to confirm true outages.
    • Real browser monitoring that measures full page load performance with waterfall reports.
    • Multi-step transaction monitoring for workflows such as logins, searches, and checkout processes.
    • Detailed error snapshots and traces for faster debugging.
    • Support for APIs, servers, and infrastructure components.
    Uptrends synthetic monitoring page for monitoring websites, APIs, and web applications.

    Pricing

    • Flexible, credit-based pricing model: credits are purchased and applied to different monitors (uptime, transaction, browser, API).
    • Entry-level uptime checks start from around $5 per month; more advanced monitors consume more credits.
    • The plan’s scale depends on usage, making it modular but potentially complex to budget.

    When to Choose This Tool

    Uptrends is well-suited for teams that need highly accurate monitoring with minimal false alarms, especially for global audiences. Its transaction and browser monitoring are useful for SaaS companies where user workflows must always function correctly. Agencies may also find credit-based pricing flexible when managing different types of clients. Credit pricing is flexible, but it’s easy to overspend if your checks grow.

    Suggested Read: How to Check Running Processes in Linux Using ps, top, htop, and atop Commands

    Sematext

    Sematext Synthetics is a flexible monitoring platform that combines uptime, API, and performance monitoring. It offers public test locations and private agents, so you can monitor both internal services behind your firewall and public-facing websites. Alongside uptime, it’s good for teams tracking reliability and Core Web Vitals in one place.

    Key Features

    • Uptime monitoring for websites, APIs, SSL certificates, and multi-step calls.
    • Core Web Vitals tracking, including Largest Contentful Paint (LCP) and Cumulative Layout Shift (CLS).
    • Flexible deployment: run checks from Sematext’s global network or from private locations.
    • Public and private status pages for transparent communication.
    • Detailed performance reports with waterfall charts.
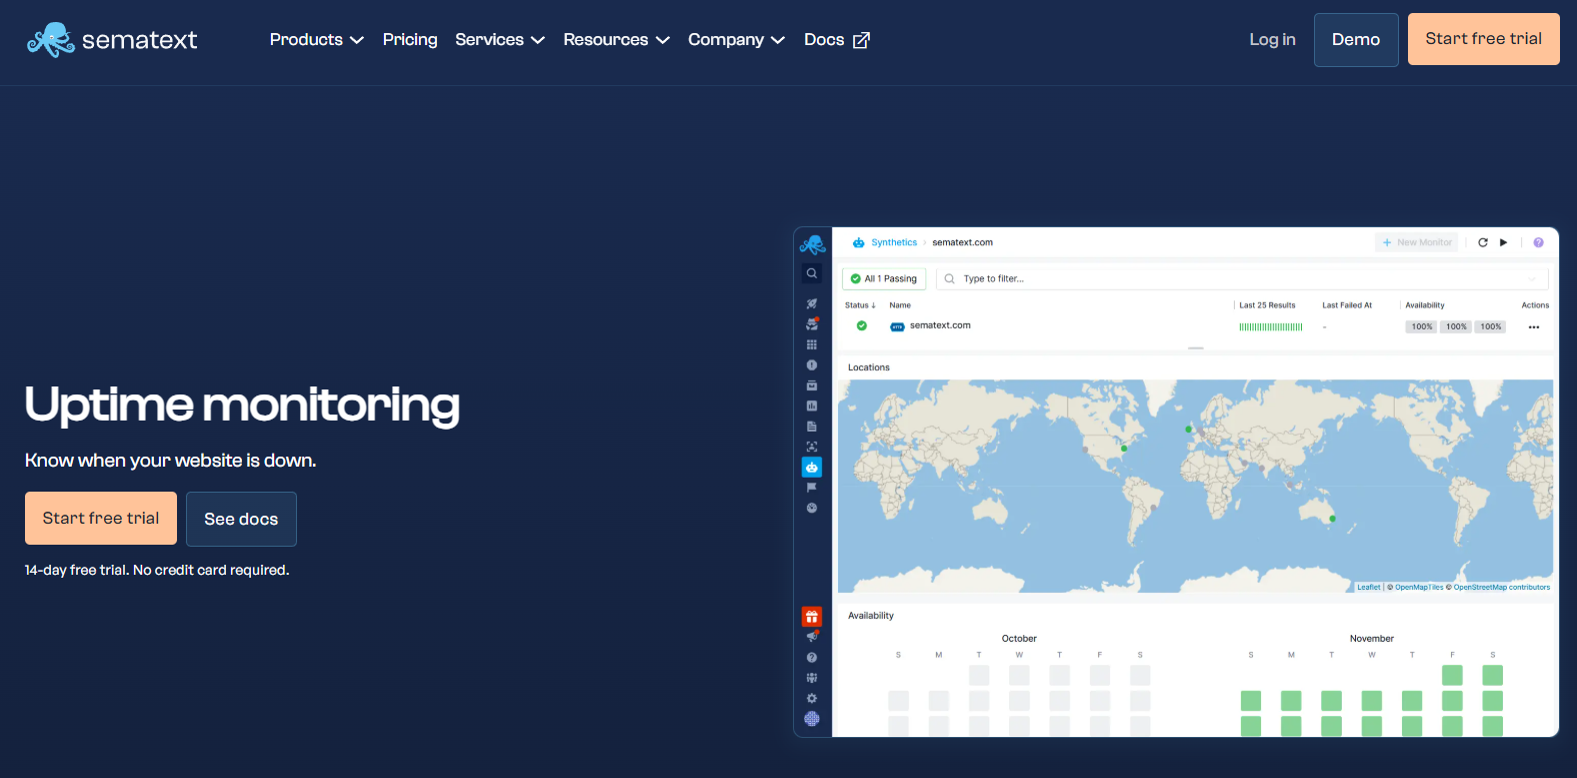
    Sematext uptime monitoring page showing global monitoring locations and website availability data.

    Pricing

    • Pay-as-you-go: charges per monitor, with granular usage control.
    • Standard plan: from $29/month for a bundle of HTTP and Browser monitors.
    • Pro plan: from $99/month, with higher limits and advanced features.

    When to Choose This Tool

    Sematext is best for teams that want flexibility, especially those needing to monitor both public and private applications. It’s useful for SaaS products where internal APIs or dashboards need to be as reliable as external websites. Core Web Vitals monitoring adds value for businesses focused on UX and SEO. It is less integrated than full observability suites, and costs rise with more monitors.

    Pulsetic

    Pulsetic is a modern uptime monitoring service that emphasizes status pages and incident communication. In addition to standard uptime and API checks, it allows teams to create visually appealing, branded status pages that keep customers informed during outages or maintenance. Alerts can be delivered via Slack, Telegram, email, or webhooks, making it a simple option for clean status pages and clear incident updates.

    Key Features

    • Uptime monitoring from multiple global regions with instant alerts.
    • Beautiful, customizable status pages hosted on your own domain.
    • Built-in incident management for posting updates and scheduling maintenance.
    • Flexible alerting via Slack, Telegram, email, and webhooks.
    Pulsetic website uptime monitoring page showing an online monitor and response time graph.

    Pricing

    • Free plan for basic uptime monitoring and simple status pages.
    • Paid tiers:
    • Solo: $9/month for individuals and freelancers.
    • Team: $19/month for collaborative use.
    • Organization: $49/month for larger businesses with more complex needs.

    When to Choose This Tool

    Pulsetic is best for teams that want uptime monitoring and professional, customer-facing status pages. It’s particularly useful for SaaS startups and agencies that need to communicate incidents clearly and maintain trust during downtime. The main limitation is that it lacks some advanced features (such as synthetic transactions or deep analytics) offered by larger platforms, so it is not designed for enterprise-scale synthetic or analytics needs.

    Final Thoughts

    Choosing the right uptime monitoring tool gives you visibility into outages, faster response times, and the data you need to keep customers confident in your service. But monitoring is only half the equation. If your hosting environment and server management aren’t reliable, even the best monitoring tool will spend more time alerting you to problems than helping you prevent them.

    That’s where RunCloud comes in.

    By pairing a powerful monitoring tool with RunCloud’s server management platform, you create a foundation that minimizes downtime from the start. With automated SSL renewals, server-level caching, and auto-healing services, RunCloud helps ensure your applications run smoothly – even during traffic spikes or unexpected errors.

    If uptime is critical to your business (and it should be), combine proactive monitoring with a hosting setup designed for resilience.

    Start building on RunCloud today and give your monitoring tools less to worry about.

    FAQs on Website Uptime Monitoring Tools

    What is the best free uptime tool?

    Many services offer excellent free plans for basic checks. UptimeRobot is a popular choice for getting started, as it provides reliable monitoring at no cost. You might consider paid services for more frequent checks and advanced features as your needs grow.

    How does uptime monitoring work?

    It works by using a global network of servers to act like virtual visitors to your website. These servers “ping” or try to load your site every few minutes, and if they receive an error or no response, the system triggers an immediate alert to notify you.

    Which tool sends instant alerts?

    Virtually all modern uptime monitoring tools, such as Better Stack and Pingdom, are built to send instant alerts. They can notify you through various channels such as email, SMS, and push notifications, ensuring you know about a problem the moment it happens.

    What is the easiest uptime checker?

    Tools like UptimeRobot are often considered the easiest for beginners because their setup is straightforward. You just enter your website’s URL and tell it where to send alerts. Services with clean user interfaces and clear instructions simplify the process.

    How often should uptime be checked?

    For most websites, checking every one to five minutes is the industry standard. This frequency provides a good balance between detecting issues quickly and avoiding unnecessary load on your server.

    Which tool is best for small sites?

    A tool with a generous free plan, like UptimeRobot or Better Stack, is often the best choice for small websites. These services provide the essential monitoring features you need without extra costs, which is perfect when you’re just starting out.

    What uptime tool works with Slack?

    Modern monitoring services, such as Better Stack, Pingdom, and StatusCake, offer excellent Slack integrations. This allows you to receive downtime alerts directly in your team’s channels.

    Is there an open-source uptime tool?

    Several excellent open-source options exist, with Uptime Kuma being one of the most popular. These tools give you full control and have no subscription fees, but they do require you to host and maintain the monitoring software on your own server.

    Which service tracks global uptime?

    Nearly all major uptime monitoring services, including Pingdom and Uptime.com, track global uptime by default. They use a network of “check locations” or “probes” spread across different continents to ensure your website is accessible to your entire audience, not just users near your server.

    What tool offers the most accurate reports?

    Accuracy comes from using multiple global check locations to confirm an outage before sending an alert, a feature found in most reputable tools like Pingdom or Better Stack. For the most complete picture, you can combine these external reports with internal server health data to quickly diagnose if the issue is with the network or the server itself.

  • Perfmatters Review and Setup Guide: Features, Pricing, Pros and Cons

    Perfmatters Review and Setup Guide: Features, Pricing, Pros and Cons

    If your WordPress site is struggling to pass Core Web Vitals, despite using a premium caching plugin, you aren’t alone. WordPress themes and page builders are getting more complex, and standard caching isn’t always enough to eliminate main-thread blocking JavaScript or prevent Cumulative Layout Shift (CLS).

    That is where Perfmatters steps in.

    Perfmatters isn’t a replacement for your caching plugin – it’s the final tuning layer, focusing on bloat removal and script management. 

    In this article, we’ll review the Perfmatters plugin, explain its features, pricing, and exactly how to use it effectively.

    By the end of this article, you’ll be able to make your WordPress site faster, more responsive, and more user-friendly with the Perfmatters plugin.

    The TL;DR Verdict: Is Perfmatters Worth It?

    Yes. If your site has sluggish Interaction to Next Paint (INP) scores or frustratingly slow Largest Contentful Paint (LCP) times, then using Perfmatters is one of the most effective ways to speed up your website.

    Who it’s for:

    • Site owners who are trying to meet Core Web Vitals requirements.
    • Users with “heavy” page builders (Elementor, Divi) who need to trim unused scripts.
    • WooCommerce store owners who need granular control over where checkout scripts load.
    • Power users looking to pair a script manager with their existing caching stack (such as WP Rocket or RunCloud’s server-level caching).

    Who should skip it:

    • Complete beginners looking for a hands-off, “set-it-and-forget-it” optimization plugin.
    • Users who only want image compression (Perfmatters does not compress images or convert to WebP).

    What is Perfmatters?

    Perfmatters is a lightweight, premium WordPress performance plugin. Unlike traditional all-in-one performance plugins that focus heavily on page caching and CDN integration, Perfmatters specializes in asset management and bloat removal.

    Its philosophy is simple: WordPress and its plugins load a massive amount of code on every single page, even when that code isn’t being used. Perfmatters allows you to selectively disable CSS and JavaScript where they aren’t needed, reducing the overall page size, lowering HTTP requests, and giving the browser less work to do.

    Because it doesn’t handle page caching, it’s designed to work alongside plugins such as WP Rocket or server-side solutions like RunCache.

    How Perfmatters Improves Core Web Vitals

    Let’s take a quick look at some of the core features of Perfmatters and how it improves Core Web Vitals. 

    1. The Script Manager

    The Script Manager is the primary reason most developers buy Perfmatters. It allows you to view every CSS and JavaScript file loading on a specific page and toggle them off with a single click.

    By disabling an unused slider script on your homepage or stopping WooCommerce cart scripts from loading on your blog posts, you significantly reduce JavaScript execution time. This is the single most effective way to improve your Interaction to Next Paint (INP) score.

    2. General Bloat Removal 

    Out of the box, WordPress includes code for emojis, dashicons, the REST API, and XML-RPC. If you aren’t using these, they’re just dead weight.

    Perfmatters offers a dashboard with simple toggle switches to disable these unnecessary WordPress core features. This reduces overall HTTP requests and slims down the page weight.

    3. Advanced Lazy Loading

    Most modern browsers have native lazy loading, but Perfmatters takes it further by letting you lazy-load images, iframes, and videos. Most impressively, it can replace YouTube iframes with a static preview image, only loading the heavy video player when the user clicks play.

    Deferring off-screen images ensures the browser focuses its resources on the content the user sees first, drastically improving Largest Contentful Paint (LCP). This feature can be quite powerful, providing a massive performance boost for media-heavy sites.

    4. Adding Missing Image Dimensions

    If you upload an image without specifying its width and height, the browser doesn’t know how much space to reserve for it. When the image finally loads, the content below it jumps down the page.

    Perfmatters automatically adds missing width and height attributes to images. This directly prevents Cumulative Layout Shift (CLS), making your pages feel stable as they load.

    5. Local Analytics and Fonts

    Loading third-party resources (like Google Analytics or Google Fonts) requires the browser to perform DNS lookups and establish new connections, which takes time.

    Perfmatters can download Google Fonts and your Google Analytics script and host them locally on your server. This reduces DNS lookups and gives you control over browser caching for these files.

    How Much Does Perfmatters Cost?

    Perfmatters has three pricing plans based on the number of sites you want to use it on. The plans are:

    • Personal: $29.95 per year for 1 site.
    • Business: $59.95 per year for 3 sites.
    • Unlimited: $124.95 per year for unlimited sites and multisite networks.

    All plans come with 1 year of updates and support, a 30-day money-back guarantee, and a 10% renewal discount.

    Pros and Cons of Perfmatters

    ProsCons
    Lightweight Footprint: Minimal code with surgical, granular script control.No Free Version: No free tier or trial available to test before buying.
    Best-in-Class Script Manager: Unmatched control over per-page/post asset management.Not All-in-One: Requires pairing with a separate page caching solution.
    Core Web Vitals Booster: Drastic improvements to INP, LCP, and CLS when properly configured.No Image Optimization: Lacks built-in image compression or WebP conversion features.
    Highly Compatible: Works flawlessly alongside caching plugins (WP Rocket, FlyingPress, RunCloud Hub).Learning Curve: Requires technical knowledge to identify which scripts to disable safely.
    Privacy & Speed: Local hosting for Google Analytics and Google Fonts built right in.Manual Configuration: Not a “set-and-forget” plugin; requires active tweaking for top results.
    Automated Maintenance: Scheduled database cleanup keeps your site lean.

    How To Install Perfmatters Plugin

    After visiting https://perfmatters.io to purchase and download the plugin, installing it is very easy and straightforward. Here are the steps to follow:

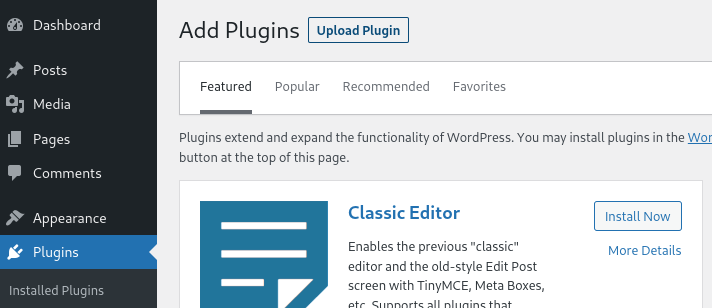
    1. To install the Perfmatters plugin, open your WordPress dashboard and navigate to the “Plugins” tab. Click on the “Upload Plugin” button and select the ZIP archive you received after completing your purchase.
    How to install perfmatters
    1. After the Installation is complete, click on “Activate Plugin” to start using it on your site.
    1. Once you have enabled the plugin, go to plugin settings and switch to the “License” tab. Enter your License key to activate all the features of the plugin.
    Perfmatters admin dashboard
    1. Once you have entered the key, you will see a message that says “License is activated” – along with the validity of your license.

    That’s it! You have successfully installed the Perfmatters plugin on your site.

    Perfmatters Basic Configuration

    Perfmatters offers many features to help you optimize your site’s performance. However, it doesn’t enable any optimization features by default. You will have to manually toggle the switch for each feature and test your site for any issues. If you notice any problem, you can simply turn off the feature and try another one.

    If you encounter a problem immediately after enabling a feature, it means your site is using that feature, so leave it alone. Here is a list of some of the important settings that you should definitely check out:

    • Script Manager: This feature lets you control which scripts load on each page or post on your site. You can turn scripts off or on that are either not needed or cause conflicts. You can also change how the scripts load, such as in the header or footer, asynchronously or deferentially, to improve your site’s speed and compatibility.
    • Lazy Loading: This feature delays the loading of images, videos, iframes, and other elements until they are visible on the screen. This reduces the initial page load time and saves bandwidth. You can also enable DOM monitoring, which detects new elements added to the page and automatically applies lazy loading to them.
    • DNS Prefetch: This feature resolves the domain names of external resources, such as images, fonts, scripts, etc., before they are requested by the browser. This reduces latency and improves your site’s loading speed. You can also manually add custom domains to prefetch.
    • Preconnect: This is an extension of the DNS Prefetch feature. In addition to resolving domain names, it establishes early connections to external domains before the browser requests them. This reduces the round-trip time and improves your site’s loading speed. You can also manually add custom domains to preconnect.
    • Heartbeat Control: This feature controls the frequency of the WordPress heartbeat API, which sends requests to the server every few seconds. These requests can consume server resources and slow down your site. You can reduce or disable the heartbeat to save resources and improve your site’s speed. You can also choose which areas of your site to apply heartbeat control to, such as the dashboard, front end, and post editor.
    • jQuery Migrate: This feature disables jQuery Migrate, which is a script that helps older plugins and themes work with newer versions of jQuery. However, this script can slow down your site and cause errors. You can disable it if you’re sure that your site doesn’t need it.
    • Disable Emojis: This feature disables emojis, which are small icons that express emotions. However, these icons can add extra requests and slow down your site. You can disable them if you don’t use them on your site.
    • Remove the wlwmanifest Link: This feature removes the wlwmanifest link, which Windows Live Writer uses to work with WordPress. However, this link can expose your site’s information and slow it down. You can remove it if you don’t use Windows Live Writer on your site.
    • Disable Comments: This feature disables comments on your site, which can reduce spam and improve your site’s performance. You can disable comments globally or on specific post types. You can also remove comment-related scripts and styles from your site.
    • Local Google Fonts: This feature hosts Google Fonts locally on your server instead of loading them from Google’s servers. This reduces external requests and improves your site’s speed and compatibility. You can also choose how to display the fonts (swap or block) and disable Google Fonts completely if you don’t use them on your site.
    • Local Analytics: This feature hosts Google Analytics locally on your server instead of loading it from Google’s servers. This reduces external requests and improves your site’s speed and privacy. You can also choose how often to update the analytics script and exclude certain roles from tracking.

    Perfmatters vs. Alternatives: Choosing the Right Performance Stack

    Deciding between Perfmatters, WP Rocket, or FlyingPress? While all three provide WordPress performance optimization, they function differently. The following comparison shows their strengths to help you pick the right tool for your specific setup.

    Feature / CategoryPerfmattersFlyingPressWP Rocket
    Primary FocusAsset optimization and granular script management.All-in-one caching with aggressive asset optimization.Page caching with reliable, automated optimization.
    Page CachingNo (Relies on your server or another caching plugin).Yes (Generates static HTML pages).Yes (Industry standard for static HTML caching).
    Manual Script ManagerBest-in-class (Unmatched control to disable scripts per page/post).No (Automates optimization but lacks manual asset toggles).No (Relies on broad automation across the whole site).
    Unused CSS HandlingYes (Loads optimized CSS efficiently in a separate external file).Yes (Highly aggressive and effective at removing unused CSS).Yes (Automated, but loads the CSS inline, which can increase HTML size).
    JavaScript OptimizationYes (Highly customizable manual control over delaying/deferring).Yes (Aggressive automated delay based on user interaction).Yes (Basic, reliable automated delay and deferral).
    Image OptimizationBasic (Handles lazy loading and preloading, but no compression).Comprehensive (Lazy loading, plus AVIF/WebP generation via add-on).Basic (Handles lazy loading, but requires a separate plugin for compression).
    Ease of UseSteep Learning Curve (Requires technical tweaking and testing to avoid breaking the site).Moderate (Requires some careful configuration for its most aggressive settings).Very Easy (“Set-and-forget” with safe, automated defaults).
    The Best Use CaseThe ultimate “scalpel” to pair with a dedicated caching plugin or server cache.A powerful standalone solution for users who want maximum automated speed.A rock-solid standalone solution for users who prioritize stability and ease of use.
    Ideal SynergyPairs perfectly with WP Rocket or RunCloud server caching.Use alone, or pair with Perfmatters to manually kill stubborn scripts.Use for caching, and pair with Perfmatters for advanced script control.

    Final Thoughts

    Perfmatters is a powerful and versatile plugin that helps you optimize your WordPress site’s performance and speed. It has many features that let you disable unnecessary features and scripts, tweak settings and options, clean up your database, use a CDN, host analytics locally, and more.

    If you’re looking for a plugin that can make your site faster, more responsive, and more user-friendly, then Perfmatters is a great choice for you.

    If you’re tired of managing your own servers, you might want to check out RunCloud (yep, that’s us!).

    RunCloud is built for developers who want to focus on shipping great work, not on managing their infrastructure. Experience painless server configuration, with no need to spend hours figuring it out.

    Get started with RunCloud today & get up and running in minutes. 

    Frequently Asked Questions

    Is Perfmatters a caching plugin?

    No, Perfmatters is not a caching plugin. It’s a performance optimization and script management plugin. It is designed to work alongside your existing caching solution (like WP Rocket or server-level caching) to remove bloat and reduce page weight.

    Perfmatters vs WP Rocket: which is better?

    They serve different purposes. WP Rocket is an all-in-one caching plugin, while Perfmatters specializes in asset management and removing unused code. For the best results, they should be used together.

    Does Perfmatters work with WooCommerce?

    Yes, Perfmatters is highly recommended for WooCommerce. WooCommerce loads cart and checkout scripts on every page by default. Perfmatters allows you to disable these scripts on your blog posts and homepage, significantly speeding up your site.

    Is Perfmatters worth it?

    Yes. If you’re struggling with Core Web Vitals, specifically INP or LCP, Perfmatters offers the granular control needed to fix those issues. For $29.95/year, it provides incredible value.

    What is the Perfmatters Script Manager?

    The Script Manager is a tool within Perfmatters that shows you every CSS and JavaScript file loading on a specific page. It allows you to toggle those files off individually, preventing unused code from slowing down your site.

    Does Perfmatters have a free version?

    No, Perfmatters does not have a free version or a trial. It is a premium-only plugin, but it does offer a 30-day money-back guarantee.

  • HTTP/2 vs HTTP/3: What Every Web Server Owner Needs to Know 2026

    HTTP/2 vs HTTP/3: What Every Web Server Owner Needs to Know 2026

    Most modern websites use the HTTP/2 protocol, which uses multiplexing to send multiple files over a single connection.

    This works quite well for people who surf the internet using high-speed fiber or broadband. However, if you’re using an unreliable network, such as a mobile connection, then the story is quite different.

    Why HTTP/2 Has a TCP Problem

    HTTP/2 uses TCP, which was designed in the 1970s with strict requirements that needed reliability and ordered delivery. If a single data packet is lost in transit, TCP halts the entire connection, asks the server to resend the missing packet, and waits for it to arrive before processing anything else.

    Because HTTP/2 pushes every asset (HTML, CSS, JS, Images) over a single TCP connection, a single dropped packet stalls the delivery of all other assets. 

    This strict sequential ordering creates “Head-of-Line (HoL) Blocking.” If you’re serving a page to a desktop user on a gigabit connection, then their packet loss is near zero, and HoL blocking is irrelevant.

    However, if your traffic skews heavily toward mobile, HoL blocking has a measurable negative impact on your Core Web Vitals.

    In environments with just a 2% packet loss (typical for a user on a crowded 4G network or a commuter train), HTTP/2’s HoL blocking can delay rendering by hundreds of milliseconds.

    Your CSS payload might be received correctly, but the browser can’t parse it because TCP is waiting for a dropped packet from an unrelated background image.

    HTTP/3 was engineered specifically to address the structural limitations of TCP that degrade performance on mobile devices, in high-latency connections, and in lossy networks.

    HTTP/2 vs HTTP/3 Side by Side

    HTTP/3 abandons TCP entirely. Instead, it runs on QUIC (Quick UDP Internet Connections), a protocol built on top of UDP. Let’s see what the differences are between the two protocols:

    Transport Protocol: TCP vs QUIC over UDP

    UDP is fundamentally different from TCP as it sends data packets without waiting for acknowledgments. It’s fast but inherently unreliable. QUIC solves this by building reliability on top of UDP.

    QUIC handles packet loss recovery natively. It retains the speed and lightweight nature of UDP while intelligently managing congestion.

    This shift from UDP to QUIC offers massive performance gains for mobile networks with fluctuating signal strength, but adds negligible differences for users hardwired to a corporate LAN.

    Suggested read: How To Fix ERR_SSL_VERSION_OR_CIPHER_MISMATCH 

    Handshakes and 0-RTT

    TCP and TLS 1.2/1.3 require separate handshakes to establish a connection. An HTTP/2 connection requires 2 to 3 round-trip times (RTT), i.e., several messages are sent back and forth between your browser and the server before you can start seeing the actual data for your website.

    HTTP/3 bakes the cryptographic handshake directly into the transport layer. This works differently in different cases:

    • First visits: When a user visits the website, the server establishes a connection in a single round-trip.
    • Returning visitors: For all the subsequent requests to the same server, QUIC enables 0-RTT (Zero Round Trip Time). The browser remembers the server and sends HTTP requests in the very first packet.
    • The Data: On a high-latency 3G/4G connection (e.g., 100ms ping), moving from 3-RTT to 0-RTT shaves up to 300ms off your Time to First Byte (TTFB).

    Independent Streams vs Shared Connection

    While HTTP/2 uses logical multiplexing within a single TCP tunnel, HTTP/3 uses cryptographic multiplexing via QUIC.

    This means that in HTTP/3, streams are truly independent. If packet #44 (containing a chunk of an image) is lost on a spotty Wi-Fi network, only the stream for that specific image is paused for retransmission. The streams carrying your CSS, JavaScript, and HTML continue rendering without interruption. 

    This significantly improves Largest Contentful Paint (LCP) and First Contentful Paint (FCP), especially under poor network conditions.

    Mandatory TLS 1.3 in HTTP/3

    With HTTP/2, encryption was technically optional (though practically enforced by browsers). In a standard TCP connection, the payload (your website data) is encrypted, but the transport headers (packet numbers, sequence details, flags) are sent in clear text.

    In contrast, QUIC uses TLS 1.3 directly during its own connection establishment. When a client connects to a server via HTTP/3, the transport handshake (saying “hello, let’s connect”) and the cryptographic handshake (exchanging TLS 1.3 keys) occur simultaneously in the very first packet. If the client doesn’t support or provide TLS 1.3 key negotiation, the QUIC connection can’t be established. There is no mechanism in the protocol to complete a connection first and secure it later.

    This prevents middleboxes (such as ISP routers or corporate firewalls) from inspecting or manipulating transport-layer data, reducing the likelihood of network-level interference that often causes TCP connections to drop.

    Suggested read: How to Set Up a Hetzner Server with RunCloud 

    Connection Migration on Mobile Networks

    A frequent issue for mobile users is switching networks, as may happen when walking out of a building and dropping from Wi-Fi to a 5G cellular network, for example.

    • HTTP/2 (TCP): Connections are tied to the user’s IP address. When the IP changes from Wi-Fi to 5G, the TCP connection breaks. The server and browser must negotiate a completely new connection from scratch, stalling the page load.
    • HTTP/3 (QUIC): Connections use a unique “Connection ID” rather than an IP address. When the user’s IP address changes, QUIC seamlessly migrates the existing connection to the new IP address.

    This delivers a flawless, uninterrupted user experience for mobile users on the go. It has no impact on stationary desktop users.

    Is HTTP/3 Supported on Your Stack?

    Before you begin modifying configuration files or adjusting firewall rules, verify that the layers of your hosting are fully prepared to handle QUIC traffic over UDP. The transition to the HTTP3 protocol has picked up pace in 2026, and it’s highly likely that your audience’s devices are already using it.

    According to recent data from Cloudflare Radar, HTTP/3 now accounts for an impressive 31.2% of all human web traffic worldwide, while HTTP/2 maintains the majority share at 59.1%, and legacy HTTP/1.x traffic has steadily declined to just 9.6%.

    When analyzing the distribution of secure network connections, Cloudflare Radar reports that QUIC directly handles 31.7% of all encrypted traffic, operating efficiently alongside traditional TLS 1.3, which handles 65.7%, while outdated TLS 1.2 connections have dwindled to a mere 2.6%.

    This rapid, widespread adoption proves that the global infrastructure is ready, but your individual server stack still dictates how seamlessly you can implement it.

    Browser Support: Chrome, Firefox, Safari, Edge

    From the client-side perspective, compatibility is essentially solved because the development teams behind Chrome, Firefox, Safari, and Edge have deeply integrated native HTTP/3 support into their modern browser releases.

    When a modern browser receives the Alt-Svc header from your server advertising that HTTP/3 is available, it will attempt to negotiate a QUIC connection in the background. However, if the browser discovers that UDP port 443 is blocked or heavily throttled on the user’s local network, it will silently and instantaneously revert the connection to standard HTTP/2 over TCP without ever surfacing a timeout error or disrupting the end user’s browsing experience.

    Suggested read: How to Set Up a Google Cloud Server to Host Your Websites 

    Web Server Support: NGINX, Caddy, LiteSpeed, Apache

    While client-side support is essentially universal, the server-side support is somewhat fragmented, meaning your specific web server software will entirely dictate your architectural approach and implementation strategy.

    • NGINX: If you are running NGINX, native HTTP/3 support is now fully available and highly stable, but using it requires updating your environment to version 1.25.0 and ensuring that your binary was explicitly compiled with the official ngx_http_v3_module enabled.
    • Caddy & LiteSpeed: If your backend infrastructure relies on modern, aggressively performance-focused web servers like Caddy or LiteSpeed, you will benefit from a much smoother deployment process, as both platforms feature highly mature, out-of-the-box HTTP/3 integration that requires practically zero manual configuration to activate.
    • Apache & Apache APISIX: The traditional Apache HTTP Server (httpd) still significantly lags behind its modern competitors. However, if your infrastructure uses Apache APISIX, you can enable HTTP/3 for downstream client connections by modifying the config.yaml file.

    While this configuration allows you to use QUIC’s 0-RTT, the official Apache documentation strictly warns that this functionality is currently considered experimental and explicitly advises administrators against deploying it in live production environments.

    Until these native experimental features are released as stable versions, placing your classic Apache server behind an HTTP/3-capable CDN (as discussed below) is the only feasible solution.

    Suggested read: How to Fix a 502 Bad Gateway Error 

    How to Enable HTTP3 on Your Website

    The web is constantly evolving, and at RunCloud, we want to help you stay on the leading edge with the latest protocols.
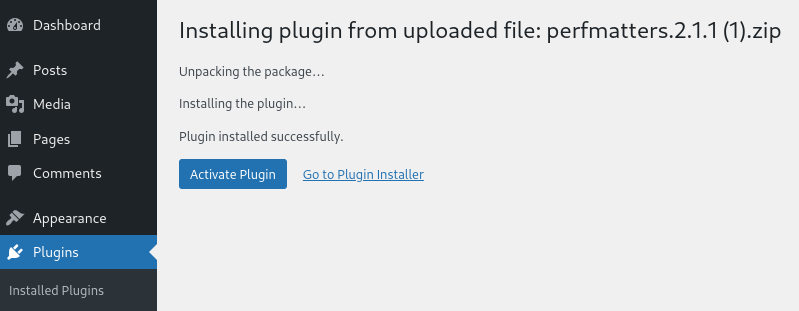
    You might be apprehensive about upgrading your production server to a brand-new protocol, and you’d be right to be cautious.

    However, unlike previous major protocol shifts, adopting HTTP/3 is a zero-risk move. It is explicitly designed to work in parallel with HTTP/2 and HTTP/1.1, rather than replacing them. Modern browsers will simply use HTTP/3 (h3) if the server offers it and the network allows it. If not, they instantly fall back to HTTP/2 (h2) without interrupting the user experience.

    Let’s see how we can enable HTTP/3 without adding unnecessary architectural complexity.

    Method 1: Use CDN (Recommended for Immediate Deployment)

    By using a modern CDN, server administrators can bypass the complexities of modifying origin server configurations, compiling experimental web server modules, or reconfiguring restrictive cloud firewalls to accept UDP traffic.

    The CDN handles the computationally heavy QUIC connection termination at the edge nodes located closest to the end user, and then seamlessly proxies that traffic back to your origin server over a standard, thoroughly tested HTTP/2 TCP connection.

    Because dashboard interfaces and underlying infrastructure architectures vary significantly across edge providers, the exact procedural steps to enable this protocol will differ by vendor, but the fundamental deployment logic remains the same.

    How to Enable HTTP/3 Using Cloudflare

    Cloudflare makes upgrading to HTTP/3 incredibly easy for beginners. You don’t need to configure complex UDP ports on your server or manually install TLS 1.3 security certificates. Cloudflare automatically handles all the heavy technical lifting on its global edge network. When you turn this feature on, Cloudflare instantly starts offering the faster QUIC protocol to your mobile and desktop visitors.

    Follow these steps to enable the protocol from your dashboard:

    1. Log in to your Cloudflare dashboard and click the domain you want to speed up.
    2. In the left-hand sidebar menu, click on Speed and go to the Settings tab.
    3. Scroll down the page until you find the section labeled Protocol. Here, you will see a list of network-layer optimization options.
    4. Find the HTTP/3 option and toggle the switch to ON. 
    5. Right below the HTTP/3 toggle, find the 0-RTT Connection Resumption option and turn it ON. This feature works perfectly with HTTP/3 to make your website load almost instantly for returning visitors by skipping the initial security handshake.

    Once you save your settings, Cloudflare will automatically serve all web requests using the best-supported protocol for your visitors.

    How to Enable HTTP/3 Using AWS CloudFront

    If you’re using AWS CloudFront (Amazon’s Content Delivery Network) to intercept and speed up the traffic at the edge of the network. This approach completely protects your underlying EC2 instances and load balancers from any risky configuration mistakes.

    Follow these steps to update your AWS distribution to use the newest web protocols:

    1. Log in to the AWS Management Console and open the CloudFront dashboard.
    2. Look at your list of delivery networks, then click your target Distribution to open its details.
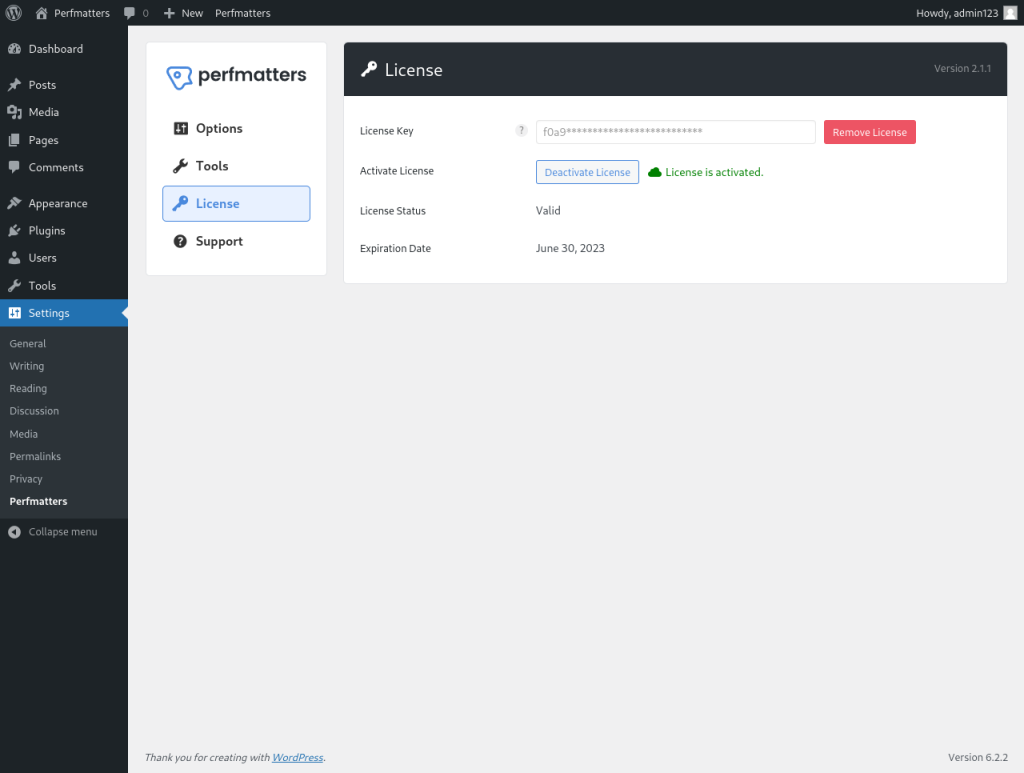
    1. On the main General settings panel, click the Edit button to begin making changes.
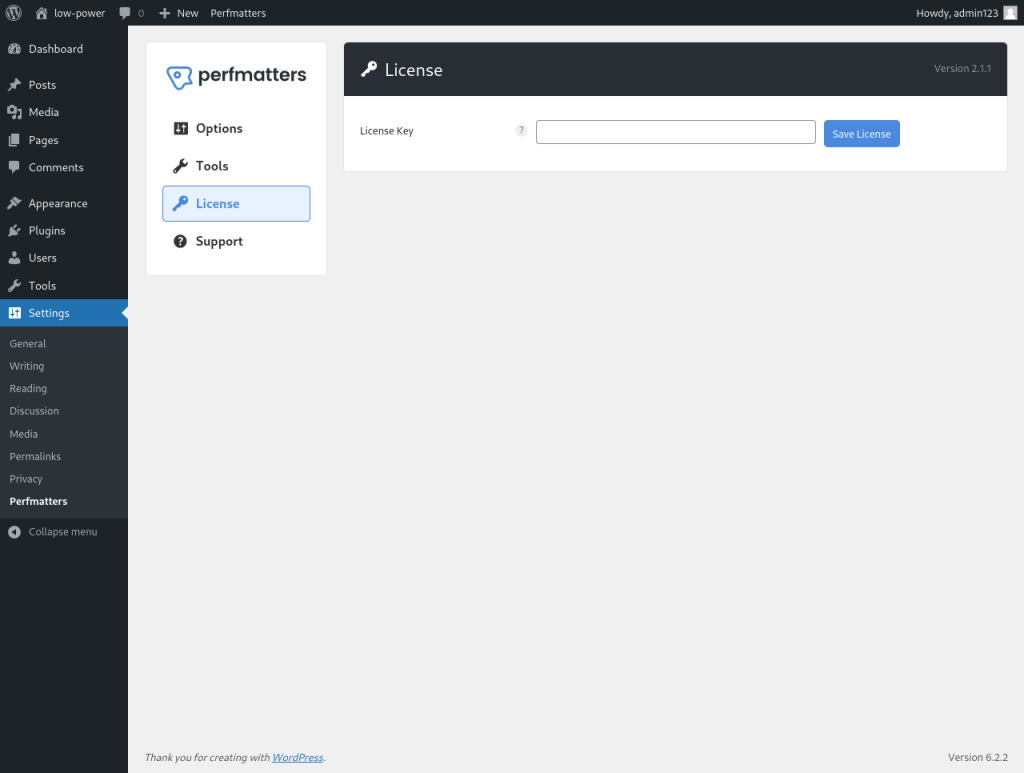
    2. Scroll down the edit page until you reach the section titled “Supported HTTP versions.”
    3. You will notice that AWS selects HTTP/1.0 and HTTP/1.1 by default, so older web browsers can still access your site. To modernize your setup, explicitly check the boxes next to both HTTP/2 and HTTP/3.
    4. Click the Save changes button at the bottom of the screen. 
    Enable HTTP/3

    AWS will take a few minutes to update its global network. Once the deployment finishes, CloudFront will automatically start terminating QUIC connections at the edge to give your visitors a faster browsing experience.

    Method 2: The Origin Server Method (NGINX)

    If you manage your own bare-metal or VPS and want HTTP/3 at the origin, you need NGINX version 1.25.0 or the mainline branch (which includes the official QUIC module).

    Step 1: Open UDP Port 443.

    HTTP/3 requires UDP traffic. Your firewall (ufw, iptables, or AWS Security Groups) must allow UDP on port 443.

    sudo ufw allow 443/udp

    Step 2: Update NGINX Configuration

    Edit your server block to listen for both TCP (HTTP/2) and UDP (HTTP/3), and add the Alt-Svc header so browsers know HTTP/3 is available.

    server {
        # Listen on TCP for HTTP/1.1 and HTTP/2
        listen 443 ssl;
        http2 on;
    
    
        # Listen on UDP for HTTP/3 (QUIC)
        listen 443 quic reuseport;
    
    
        server_name yourdomain.com;
    
    
        # TLS 1.3 is strictly required
        ssl_protocols TLSv1.3;
        ssl_certificate /path/to/cert.pem;
        ssl_certificate_key /path/to/key.pem;
    
    
        # Broadcast to browsers that HTTP/3 is available
        add_header Alt-Svc 'h3=":443"; ma=86400';
    
    
        location / {
            # Your standard proxy or root directives
        }
    }

    Step 3: Test and Validate

    Restart NGINX (systemctl restart nginx). Open Chrome DevTools, navigate to the Network tab, right-click the column headers, and check Protocol. Reload the page a few times. You should see h3 appear instead of h2 for your primary document and assets.

    Method 3: Enabling HTTP/3 with RunCloud 

    If you manage your own servers, manually compiling experimental modules or editing NGINX configuration files via SSH introduces unnecessary risk and leaves significant room for human error. A single typo in your server block can instantly break your production site. 

    RunCloud offers a vastly superior, fully automated alternative, with an intuitive dashboard to manage everything.

    RunCloud deploys a custom NGINX stack that is already optimized for modern protocols, allowing you to modernize your infrastructure with zero technical friction.

    With RunCloud, you never have to touch a configuration file to get QUIC running. The platform handles the complex port binding and header injections for you.

    1. Open your Web Application: Log in to your RunCloud dashboard and navigate to the specific Web Application you want to optimize.
    2. Navigate to SSL/TLS Settings: Open the settings panel where you manage your domains and security certificates.
    3. Enable the Protocol: Simply click the checkbox next to Use HTTP/3.

    That’s the entire process! Because HTTP/3 requires TLS 1.3, RunCloud automatically generates, installs, and manages the lifecycle of your SSL certificates behind the scenes. You get all the performance benefits of an enterprise-grade setup without the administrative headache of rotating certificates or debugging connection failures.

    Important Firewall Note: Before you check the HTTP/3 box in RunCloud, ensure your infrastructure allows the traffic. If you’re hosting on providers such as Hetzner or Google Cloud Platform (GCP), their external network firewalls block UDP traffic by default. You will need to open UDP port 443 at the cloud provider level first. If you’re spinning up a new server, our server setup guides for Hetzner and Google Cloud Platform cover this firewall step. Once the port is open, RunCloud handles the rest of the web server configuration automatically.

    HTTP/2 or HTTP/3: Which One is Better?

    If your site traffic is predominantly desktop users on reliable broadband connections, HTTP/3 won’t significantly alter your performance metrics. In environments with near-zero packet loss, the data shows HTTP/2 and HTTP/3 perform almost identically. 

    However, if your audience includes a large percentage of mobile users, spans across multiple continents, or frequently accesses your application from lossy network environments, HTTP/3 is a low-risk, high-reward upgrade. 

    Real-world telemetry shows that switching to QUIC under a 2% packet-loss scenario can reduce Largest Contentful Paint (LCP) delays by hundreds of milliseconds. Because modern clients gracefully fall back to HTTP/2 when UDP fails, there is zero downside to enabling it.

    Ready to Upgrade to HTTP/3? 

    Sign up for RunCloud and deploy a high-speed, HTTP/3-ready server in minutes.

    Frequently Asked Questions: Upgrading to HTTP/3

    Is HTTP/3 faster than HTTP/2?

    Yes, HTTP/3 is significantly faster than HTTP/2 because it uses the QUIC protocol instead of TCP, effectively eliminating head-of-line blocking. This architectural upgrade allows web pages to load much more quickly and maintain highly stable connections, especially on unreliable mobile networks.

    Do I need to disable HTTP/2 to use HTTP/3?

    No, you do not need to disable HTTP/2 because modern web browsers and servers automatically negotiate the highest supported protocol. Keeping both protocols enabled ensures backward compatibility with older devices while delivering the maximum HTTP/3 speeds to updated browsers.

    Does HTTP/3 affect SEO or Core Web Vitals?

    Implementing HTTP/3 positively impacts SEO by directly improving crucial Core Web Vitals metrics, such as Largest Contentful Paint (LCP) and Interaction to Next Paint (INP). Because Google uses page load speeds as a ranking factor, this enhanced technical performance signals a superior user experience and can boost your organic search visibility.

    Does HTTP/3 require TLS?

    Yes, HTTP/3 strictly requires TLS 1.3 encryption, which is built into the QUIC transport protocol. This mandatory cryptographic standard ensures that all data connections are established much faster while remaining inherently secure against modern cyber threats.

    Is HTTP/3 safe to enable in production?

    HTTP/3 is widely considered safe, highly stable, and strongly recommended for live production environments by web performance experts. Because top-tier tech platforms and global CDNs already use it by default, you can confidently enable it to enhance your website’s speed and security reliably.

  • Redis vs Memcached: Which In-Memory Data Store Should You Use?

    Redis vs Memcached: Which In-Memory Data Store Should You Use?

    If your WordPress site feels sluggish despite having a great theme and high-quality hosting, the bottleneck is likely your database.

    Every time a visitor loads a page, WordPress performs dozens of queries to fetch settings, menu structures, and widget content from your MySQL database.

    Object caching changes this by storing repetitive results in RAM and serving them instantly to your visitors.

    But which caching backend should you choose: Redis or Memcached?

    In this guide, we will discuss the differences between these two high-performance solutions. We’ll explore why Redis has become the industry standard for complex, data-heavy sites, when Memcached might still be the smarter choice for a resource-constrained VPS. By the end of this post, you will understand which of these services is right for you.

    What are Memcached and Redis?

    Memcached and Redis are both high-performance, open-source, in-memory data stores, but they were designed with different architectural philosophies.

    Memcached is a distributed memory object caching system designed specifically for simplicity, serving as a “pure” cache to speed up dynamic web applications by alleviating database load.

    Redis, by contrast, is an advanced in-memory data structure store that functions as a cache, a primary database, and a message broker, offering a much richer feature set than a traditional key-value cache.

    Suggested read: How to Set Up WooCommerce Caching: The Ultimate Guide in 2026

    Performance: Speed, Throughput, and Multi-Threading

    In raw read/write operations for simple key-value pairs, both systems deliver sub-millisecond latency and incredibly high throughput. Memcached uses a multi-threaded, non-blocking architecture, which makes it exceptionally efficient at handling thousands of concurrent connections on multi-core servers without significant locking contention.

    While early versions of Redis were single-threaded, modern Redis supports multi-threaded I/O to improve performance on high-end hardware, while maintaining a single-threaded execution model for command processing to avoid the complexities of data locking.

    For the vast majority of WordPress use cases, both systems are more than capable of handling high traffic; however, Memcached’s architectural simplicity often provides a slight edge in pure throughput for static, high-frequency key-value lookups.

    Suggested read: How To Use Redis Object Cache To Speed Up Dynamic WordPress Site

    Data Types and Persistence

    Memcached and Redis differ in how they handle data and the level of persistence they offer. Let’s see how

    Memcached: strings only, no persistence

    Memcached is strictly a key-value store where the values are treated as unstructured blobs of data (strings). It doesn’t understand the content of the data it stores, meaning if you need to update a single element within a large object, your application must retrieve the entire object, modify it in application memory, and write the whole blob back to the cache.

    Memcached is designed to be volatile; it offers no mechanism to save data to disk, meaning all cached items are lost instantly if the service restarts.

    Suggested read: Everything You Need To Know About WordPress Object Caching

    Redis data structures (hashes, sets, lists, sorted sets)

    Redis provides a powerful set of native data structures that enable developers to perform operations directly on the server. With Hashes (ideal for storing objects like user profiles), Lists, Sets, and Sorted Sets (perfect for leaderboards or queueing), you can perform granular tasks, such as pushing a new item to a list or incrementing a counter, without fetching and replacing the entire dataset.

    This reduces network bandwidth and CPU overhead, making Redis significantly more flexible for complex applications that require more than just simple caching.

    Suggested read: How To Install And Configure Object Cache Pro for WordPress

    RDB snapshots and AOF logging explained

    A key differentiator for Redis is its ability to persist data, which is achieved through two primary mechanisms: RDB (Redis Database Backup) and AOF (Append Only File).

    • RDB Snapshots: This performs point-in-time snapshots of your dataset at specified intervals (e.g., every 60 minutes if 1,000 keys changed). It is highly efficient for backups and recovery, though it carries a small risk of losing data created between the last snapshot and a crash.
    • AOF Logging: This logs every write operation received by the server into a file, which is then replayed upon startup to reconstruct the original dataset. AOF provides much higher data durability than RDB, as it can be configured to sync to disk after every write operation, effectively turning Redis into a reliable, persistent database rather than just a transient cache.

    Suggested read: How to Reduce Cache Misses & Avoid Them: Proven Tips [FIXED]

    How WordPress object caching works (WP_CACHE, drop-in)

    WordPress has a built-in object caching system that prevents redundant database queries. By default, this cache is non-persistent, meaning it exists only for a single page load. To make this persistent, meaning the cache stays alive across different page visits, you must enable the WP_CACHE constant in your wp-config.php file.

    In WordPress, a drop-in is a special type of file that WordPress core checks during its initialization. If WordPress finds a file named object-cache.php inside your /wp-content/ directory, it automatically loads it instead of using its default (non-persistent) caching mechanism.

    Here is the breakdown of how this process works, the standard implementation steps, and the conceptual bridge it creates:

    1. Default Behavior: Without a drop-in, WordPress uses its internal WP_Object_Cache class. This class stores data in PHP memory, but that memory is wiped clean at the exact moment a page finishes loading. The next time a user visits, WordPress must query the database again.
    2. The Interception: When the object-cache.php file exists, WordPress skips the default WP_Object_Cache class and use the code defined inside that drop-in file instead.
    3. The Persistent Connection: The drop-in file contains the logic to connect to an external, memory-based storage server (like Redis or Memcached). Because this storage server exists outside the scope of a single PHP request, the data persists between page loads. Now, when WordPress needs a database result, it asks the drop-in file, which fetches it from RAM (the cache server) instead of triggering a slow MySQL query.
    Memcached service in RunCloud

    Suggested read: WP Rocket vs LiteSpeed Cache: Which One is Best in 2026

    Redis vs Memcached for WordPress Object Cache

    Choosing between Redis and Memcached for WordPress object caching can be confusing, but understanding how they interact with your database is key to unlocking faster page load times. 

    Memcached with W3 Total Cache or Object Cache Pro

    Memcached is the “classic” choice for WordPress performance. It’s extremely lightweight and focuses on a single task: storing simple key-value pairs in memory. When using plugins like W3 Total Cache, Memcached is often the default choice because of its simplicity and low resource requirements.

    If you’re using a managed WordPress host or a performance-heavy plugin such as Object Cache Pro, you may find that Memcached performs exceptionally well for basic site speed. Because it’s multi-threaded and doesn’t handle disk writes, it can handle massive bursts of read requests with very little CPU overhead, making it ideal for standard, content-heavy websites.

    Redis with WP Redis / Object Cache Pro

    Redis has become the industry standard and the modern “default” for most high-performance WordPress hosts. Plugins such as WP Redis or the enterprise-grade Object Cache Pro allow WordPress to use Redis’s advanced data structures.

    Unlike Memcached, Redis can handle complex data structures, allowing WordPress to store related data together in “hashes” or “sets”. This means that when WordPress needs to update a piece of information, it can talk to Redis more intelligently, reducing the need to constantly delete and rewrite large chunks of data. 

    Suggested read: LiteSpeed Cache WordPress Plugin Configuration Tutorial

    Which performs better for WP transients and session data?

    When comparing performance for transients (temporary database entries including plugin data, API responses, or WooCommerce cart items) and session data, Redis is the clear winner.

    • Why for Transients: WordPress transients often need to be expired or searched based on specific criteria. Because Redis supports sorted sets and hashes, it can manage these transient expirations more efficiently than Memcached.
    • Why for Sessions: Because Redis supports persistence, your user session data remains intact even if you restart your server or clear the cache. Memcached would wipe all active user sessions if the server restarts, forcing your visitors to log in again.

    Wrapping Up: Which Object Caching Tool Should You Use – Memcached Or Redis?

    Deciding between Memcached and Redis ultimately comes down to your server resources and the complexity of your WordPress site.

    If you’re running a lightweight site on a resource-constrained VPS, Memcached’s minimal memory footprint makes it an excellent choice for basic query acceleration.

    However, for most modern WordPress environments, especially those using WooCommerce, complex page builders, or high-volume transient data, Redis is the superior option.

    Runcache with Redis caching

    Manually managing caching services via SSH can be tricky, especially when configuring PHP-FPM worker pools or adjusting php.ini settings.

    RunCache has simplified this process by providing native, one-click toggles to enable caching for your WordPress web application.

    This approach ensures you don’t need to manually touch configuration files, reducing the risk of downtime while optimizing cache performance.

    Whether you choose the lean profile of Memcached or the feature-rich capabilities of Redis, RunCloud ensures your site remains lightning-fast, secure, and easy to maintain.

    Sign up for your RunCloud account and experience painless server management today.

    FAQs

    Is Redis faster than Memcached for WordPress?

    While both provide excellent performance, Redis is often considered superior for complex WordPress environments because it supports advanced data structures and atomic operations. However, for simple key-value caching, the speed difference is usually negligible, meaning the “faster” choice often depends more on your specific server configuration and plugin implementation than the software itself.

    Can Memcached persist data across server restarts?

    No, Memcached is a purely volatile, in-memory key-value store, and it doesn’t have native support for persisting data to disk. If your server restarts or the Memcached service is stopped, all cached data is permanently cleared and must be rebuilt by your application.

    Does WordPress support Memcached as an object cache backend?

    Yes, WordPress has native support for Memcached as an object cache backend through the use of a persistent object cache plugin. By dropping an object-cache.php file into your wp-content directory, WordPress can efficiently store and retrieve database query results in RAM rather than querying your MySQL database repeatedly.

    What is the difference between Redis and Memcached for PHP sessions?

    The primary difference is that Redis provides persistence, allowing PHP sessions to survive server reboots, whereas Memcached loses all session data upon restart. Additionally, Redis offers better reliability for high-traffic sites due to its ability to handle more complex data types and provide snapshots of session states.

    Should I use Redis or Memcached on a VPS with limited RAM?

    Memcached is generally the better choice for a VPS with extremely limited RAM because it has a smaller memory footprint and lower overhead than Redis. Redis includes more features, such as data persistence and complex data structures, which consume more memory resources even when idle.

    What is Valkey and does it replace Redis for WordPress caching?

    Valkey is an open-source, community-driven fork of Redis created to ensure the project remains under a permissive license following changes to Redis’s licensing model. It’s fully compatible with existing Redis implementations, making it an excellent drop-in replacement that works seamlessly with WordPress caching plugins that support Redis.

  • How to Easily Find Your DNS Server IP Address in Linux

    How to Easily Find Your DNS Server IP Address in Linux

    DNS translates domain names into IP addresses so your system knows where to connect. In this guide, you will learn exactly how to check DNS server settings in Linux across all major distributions, including Ubuntu, Debian, CentOS, and RHEL.

    You’ll learn the difference between static configuration files and dynamic network managers so you can accurately list DNS servers for troubleshooting or security audits.

    Whether you’re a system administrator working via SSH or a desktop user navigating the GNOME interface, this comprehensive walkthrough ensures you never have to wonder “which DNS am I using” again.

    How to Find the Current DNS Server in Linux

    There are four common ways to view the DNS server settings in Linux:

    Method 1: Check Your DNS Server with the Terminal

    The Linux terminal is an incredibly powerful tool, and for tasks like this, it’s often the fastest way to get the information you need. You can get this information quickly with a single command. Follow the steps below to get started:

    Step 1: Open the Terminal

    First, open the terminal application. You can find it in your applications menu, or use the common keyboard shortcut: Ctrl + Alt + T.

    This will open up a new window, where you can enter your commands. If you are connected to the server via SSH, then you don’t need to take any additional steps. You can type your commands in this shell, as it’s the terminal itself.

    Step 2: Check the resolv.conf File

    For this step, you will use the cat command, which simply reads a file and displays its contents on the screen.

    In your terminal, type the following command and press Enter:

    cat /etc/resolv.conf

     You will see an output similar to the image below:

    Look for the line that starts with nameserver. The IP address immediately following it is the DNS server your system is configured to use. In the example above, the DNS server is 192.168.0.1.

    If you see an address like 192.168.0.1, your system is using your router for DNS, which then forwards the request to your ISP. This is a very common and default setup.

    If you have explicitly defined the DNS servers in your network configuration, then you might get an output similar to the following image:

    In the above example, the computer is using three different DNS servers with the following IP addresses: 1.1.1.1, 8.8.8.8, and 9.9.9.9, which belong to Cloudflare, Google, and Quad9, respectively. 

    systemd-resolved vs /etc/resolv.conf

    If you run cat /etc/resolv.conf on modern Linux distributions (like Ubuntu 18.04 and later), you will see a nameserver entry for 127.0.0.53. This doesn’t mean your actual DNS server is on your own machine.

    On these systems, /etc/resolv.conf is often a symbolic link to a “stub” file managed by systemd-resolved. The 127.0.0.53 address is a local DNS stub listener that forwards your requests to the actual upstream DNS servers.

    While this file is technically “accurate” for the OS, it doesn’t list the external DNS providers (like Google or Cloudflare) you’re actually using. To see the true upstream nameservers on these systems, you must use Method 3 (resolvectl) or Method 4 (nmcli).

    Method 2: Find The DNS Server in Linux Using The GNOME Graphical Interface

    If you prefer clicking over typing, Linux desktop environments such as GNOME provide a user-friendly way to see your network settings.

    Step 1: Open Your System Settings

    Click on the system tray area in the top-right corner of your screen, where you see the icons for Wi-Fi, volume, and power. In the menu that appears, click the gear icon (⚙️) to open the Settings window.

    Step 2: Go to Network Settings

    In the Settings window, look at the menu on the left-hand side. Click on either Wi-Fi or Wired, depending on your connection method.

    Step 3: Open Your Active Connection’s Details

    You will now see a list of available networks. Find the network you are currently connected to (it will be the one that’s toggled on). To the right of its name, click the gear icon (⚙️) to open its specific settings.

    Step 4: Find Your DNS Entry

    A new window will pop up with several tabs. It will open on the Details tab by default. Here, you can immediately see a summary of your connection. Look for the DNS entry to find your server’s IP address.

    As you can see, the DNS is listed as 192.168.0.1, which matches what we found in the terminal.

    Step 5: Understanding the “Automatic” Setting

    To see why you have this DNS server, click on the IPv4 tab at the top of this same window.

    Notice that the DNS setting has a switch toggled to Automatic. This setting, along with the Automatic (DHCP) option for IPv4 Method, instructs your computer to automatically accept the network settings provided by your router.

    Most systems use DNS settings provided automatically by the router (via DHCP). Switching to Manual lets you specify your own DNS server. If you want to manually set a different DNS server (such as Google’s 8.8.8.8), toggle this switch off, then enter the new IP address in the field.

    Method 3: Use resolvectl 

    On Linux distributions that use systemd-resolved, the resolvectl command is the recommended way to check your DNS status. This tool provides a detailed breakdown of which DNS servers are assigned to specific network interfaces.

    To use this method, you first need to connect to your remote server via SSH as described in Method 1. Once you are logged in to the terminal, run the following command:

    resolvectl status
    resolvectl status

    Look for the “DNS Servers” and “Current DNS Server” lines under your active network interface. This will show the actual IP addresses of the DNS providers your system is querying, bypassing the local stub address.

    Method 4: Use nmcli (NetworkManager Systems)

    If your server uses NetworkManager to handle connections (common in RHEL, CentOS, and most Desktop environments), the nmcli tool is the most efficient way to query DNS settings directly from the networking stack.

    Use the following command to display your network details:

    nmcli device show | grep IP4.DNS

    This command filters the output to show only the IPv4 DNS servers assigned to your active devices. It displays the DNS servers exactly as they were received from DHCP or manually configured in the NetworkManager profile.

    Bonus: Query a Site Using Any DNS Server

    After identifying your DNS server, you may not be completely satisfied with it. If you are facing network issues, you can bypass your local settings entirely and request a website’s IP address from any public DNS server worldwide.

    Why would you do this?

    If a site loads for others but not for you, your DNS server might be outdated, overloaded, or applying filters. Querying a public DNS server gives you a clean comparison.

    dig @<DNS-SERVER-IP> <WEBSITE-TO-LOOKUP>

    Let’s break that down:

    • dig: The command to run the tool.
    • @<DNS-SERVER-IP>: The @ symbol tells dig, “direct your question to this specific server.” Replace <DNS-SERVER-IP> with the IP address of the server you want to query, such as @8.8.8.8 for Google.
    • <WEBSITE-TO-LOOKUP>: The domain name you want the IP address for, such as runcloud.io.

    Let’s ask Google’s public DNS server (8.8.8.8) for the IP address of runcloud.io. Open your terminal and run this command:

    dig @8.8.8.8 runcloud.io

    The terminal will print a block of text that might look a little intimidating at first, but don’t worry! You only need to concern yourself with one specific part.

    Scroll down until you find the ;; ANSWER SECTION:. This is the response from the DNS server

    runcloud.io.                300        IN        A        104.26.10.235
    runcloud.io. 300 IN A 104.26.11.235
    runcloud.io. 300 IN A 172.67.68.114

    This tells us that, according to Google’s DNS, runcloud.io has three IP addresses: 104.26.10.235, 104.26.11.235, and 172.67.68.114. It’s that simple!

    If you prefer a graphical interface, Google offers a simple web tool that performs the same function. You can visit https://dns.google/ to see the same query we just ran, but in your browser.

    This will display the raw DNS information in a format that computers prefer (called JSON), making it easy to spot the IP address in the “data” field. It’s a great alternative if you’re not in front of a terminal.

    When Applications Bypass Your System DNS

    The IP address you found using the methods above is the default DNS server for your system. However, it’s essential to note that some applications may opt to disregard it and use their own. Before you spend hours troubleshooting, be aware of these common overrides:

    • DNS-over-HTTPS (DoH): Modern browsers can use DNS-over-HTTPS, which bypasses your system DNS for privacy. VPNs also override DNS to keep traffic secure.
    • Virtual Private Networks (VPNs): When you connect to a VPN, it almost always forces your computer to use its own private DNS servers. This is a critical security feature. If your computer uses your regular DNS while connected to a VPN, your internet service provider may still be able to see which websites you’re trying to visit, defeating a key purpose of the VPN.

    Next Steps for DNS Management

    You now know how to check your DNS server from both the terminal and GNOME, as well as how to test any DNS provider using the dig command.

    DNS checks are only one part of managing a server. RunCloud provides an easy and reliable way to deploy and manage Linux servers without manual configuration. It handles security, updates, monitoring, and performance tuning, so you can focus on your applications.

    If you want a simpler way to manage Linux servers and avoid repetitive configuration work, RunCloud gives you a clean dashboard for deployments, updates, backups, and security.

    Create your FREE RunCloud account and streamline your server workflow today.

    FAQs

    How do I check which DNS server my Linux system is using?

    You can check your active DNS servers by running the resolvectl status command. 

    Why does /etc/resolv.conf show 127.0.0.53 instead of my real DNS?

    The IP address 127.0.0.53 indicates that your system is using a local DNS stub listener managed by systemd-resolved. This local service acts as an intermediary, receiving your queries and forwarding them to the actual upstream DNS servers, which you can identify using the resolvectl status command.

    How do I set DNS to 8.8.8.8 in Linux?

    You can set your DNS to Google’s public DNS by running nmcli connection modify [connection-name] ipv4.dns “8.8.8.8”. For persistent changes on Ubuntu servers, you must add 8.8.8.8 to the nameservers section of your configuration file in /etc/netplan/ and run sudo netplan apply.

  • How & Why You Should Remove Unused WordPress Plugins

    How & Why You Should Remove Unused WordPress Plugins

    Unused WordPress plugins can slow your site down and weaken your security, even when they’re deactivated.

    This guide explains why they cause problems and shows you how to safely remove them.

    Why You Should Remove Unused Plugins

    Leaving inactive or unused plugins on your WordPress installation is a significant liability. Here’s why you should clean them up:

    Enhanced Security

    Inactive plugins still leave their files on your server. If a vulnerability is found, attackers can target those files directly. Removing unused plugins closes those entry points.

    Improved Performance

    Many plugins add files and database entries that remain after deactivation. They increase backup sizes and sometimes still load assets. Removing them reduces bloat and can help your site load faster.

    Simplified Maintenance

    A shorter list of plugins makes your life easier. It simplifies troubleshooting when issues arise and reduces the time you spend on updates. With fewer plugins to manage, you can focus on the ones that are essential for your site’s functionality.

    Reduced Bloat

    Over time, unused plugins can contribute to database bloat. Even after deactivation, some plugins leave behind tables and rows in your database. This unnecessary data can slow down your database queries and negatively impact your overall site performance.

    Why Deactivation Isn’t Enough

    Many WordPress site owners believe that if a plugin is deactivated, it’s harmless. While it’s true that deactivating a plugin prevents it from actively running on your site, this is only a half-measure that creates a false sense of security. The reality is that the plugin’s files are still sitting on your server.

    Think of it this way: even if the plugin isn’t “on,” its code is still present and accessible. Hackers and malicious bots are constantly scanning the web, not just for active vulnerabilities, but for the mere presence of specific plugin files known to have security flaws. If a known vulnerability exists in a deactivated plugin, its files can still be scanned and exploited. Removing the plugin avoids this risk entirely.

    remove wordpress plugins

    How to Identify and Remove Unused Plugins

    Follow these simple steps to clean up your WordPress installation.

    Step 1: Identify Unused Plugins

    Go to Plugins in the WordPress dashboard and review each installed plugin. For each one, check whether you still use it and whether the functionality is truly needed.

    • What function does this plugin perform?
    • Is this functionality still necessary for my website?
    • Is there a better way to achieve this without a plugin?
    • When was the last time I used this plugin’s features?

    If you’re unsure about a plugin, try deactivating it and checking your website to see if any issues arise. This can help you determine if it’s safe to remove.

    Suggested read: How to Block WordPress Spam Comment Bots With Fail2ban Rate Limiting

    Step 2: Deactivate the Plugin

    Once you’ve identified a plugin that is no longer needed, click “Deactivate” under its name. This will disable the plugin, but its files will still be on your server.

    Step 3: Delete the Plugin

    After deactivating the plugin, a “Delete” option will appear. Click on it. WordPress will ask for confirmation before permanently removing the plugin’s files. Confirm the deletion.

    delete wordpress plugins

    By following these steps, you are actively enhancing your website’s security and performance. A clean WordPress installation is a crucial component of a well-maintained website, enabling you to use your hosting resources to their fullest potential.

    Suggested Read: How to Easily Change Your WordPress Site URL

    Test Plugin Changes Safely with RunCloud

    As we’ve seen, keeping your WordPress site free of unused plugins is a powerful step towards a faster, more secure, and easier-to-manage website. By removing unnecessary plugins, you can eliminate security vulnerabilities and reduce performance-draining code.

    Cleaning up unused plugins is easier when you can test changes safely and securely.

    RunCloud provides a simple and reliable way to manage WordPress sites, featuring one-click staging, automated backups, and performance-focused server setups.

    You can test plugin removals in staging, confirm everything works, and deploy changes with confidence.

    Take the risk out of managing WordPress. Use RunCloud to create a staging site, test plugin changes safely, and run your site on a fast, secure server setup.

    Create your free RunCloud account and start managing WordPress the easy way.

    Frequently Asked Questions About Removing Unused Plugins

    How does removing unused plugins help my website’s SEO?

    Search engines like Google favor websites that are fast and secure. By removing unused plugins, you reduce code bloat and potential security vulnerabilities, which improves your site’s loading speed and overall health. This sends positive signals to search engines that can boost your rankings.

    Is deactivating a plugin the same as deleting it?

    No, they are not the same. Deactivating a plugin simply turns it off, but its files remain on your server, posing a potential security risk. Deleting the plugin completely removes its files, which is the recommended practice for better security and performance.

    How often should I perform a plugin cleanup?

    It’s a good practice to review your installed plugins every three to six months. This regular audit helps ensure that you are only keeping the plugins that are necessary, up to date, and beneficial for your site’s functionality.

    Could I break my site by deleting a plugin?

    Yes, if the plugin provides essential functionality. To avoid this, always deactivate the plugin first and thoroughly test your website’s key features to ensure everything still works as expected before proceeding with deletion.

    What if I need a deleted plugin in the future?

    If you think you might need a plugin again, you can simply reinstall it from the WordPress plugin repository. However, for plugins you are certain you won’t use, complete removal is the best way to keep your site lean and secure.

  • How to Install Docker on Windows Server 2016, 2019 & 2022

    How to Install Docker on Windows Server 2016, 2019 & 2022

    Although Linux remains the easier and more efficient platform for most containers, Windows Server still plays a major role in many production environments. If your applications, tooling, or infrastructure tie you to Windows, mastering Docker on Windows Server becomes a practical requirement.

    You might be working with Windows containers because:

    • Legacy .NET Framework apps: Older ASP.NET MVC sites, WCF services, or Windows Services that can’t run in Linux containers.
    • Your Application Has Windows-Specific Dependencies: Some applications are deeply woven into the Windows operating system. If your code calls on technologies like Microsoft Message Queue (MSMQ), COM+, relies on assemblies in the Global Assembly Cache (GAC), or interacts directly with the Windows Registry in complex ways, then you will need a Windows environment to function.
    • Your Company Runs on Windows: Corporate policy and existing infrastructure are powerful forces. If all your servers are Windows-based, then your monitoring tools would be optimized for it, your security policies would be built around Active Directory, and your entire team’s expertise would lie in managing a Windows environment. In this scenario, introducing a few Linux servers adds significant operational overhead.
    • You need a Windows CI/CD Build Agent: A Windows environment is required to build and package Windows applications. You cannot compile a WPF desktop application, run MSBuild for a full .NET solution, or create a Windows Installer (.msi) package on a Linux build agent. A containerized Windows build agent gives you a clean, repeatable, and isolated environment for every single build.

    In this guide, we’ll explain how to install Docker on Windows Server. By the end of this article, you will be able to install it and run containers without any help.

    If you’re using Windows Server only because Linux feels unfamiliar, you don’t need to avoid it. RunCloud provides an intuitive dashboard for managing fast and secure Linux servers without requiring complex command-line knowledge.

    Explore How RunCloud Simplifies Linux Hosting →

    Prerequisites and Requirements For Docker on Windows

    A good DevOps engineer knows that a successful deployment is 90% preparation. Before you type a single installation command, verify that your environment is properly set up.

    Section 1: System Requirements & Hypervisor Check

    Check that you’re running a supported 64-bit Windows Server version (2016, 2019, or 2022). Then confirm CPU virtualization is enabled. How you check this depends on whether you are on bare metal or a virtual machine.

    If Your Server is a Physical Machine:

    You need to verify that virtualization support (often referred to as Intel VT-x or AMD-V) is enabled in the server’s BIOS or UEFI. The easiest way to check this from within Windows is to run a simple PowerShell command.

    Open an elevated PowerShell prompt and run the following command:

    systeminfo | findstr "Virtualization"

    Look at the output. You need to see Hyper-V – Virtualization Enabled in Firmware: Yes. If it says “No,” you must reboot the server, enter the BIOS/UEFI settings, and enable the feature.

    If Your Server is a Virtual Machine (VM):

    If your server runs inside a VM, you must enable nested virtualization on the host. Docker cannot run inside a VM without it.

    This setting is not configured inside your Windows Server VM. You must configure it from the management interface of the host hypervisor that is running your VM.

    • For VMware ESXi/vSphere: Shut down the VM. Edit the VM’s settings, expand the CPU section, and check the box for “Expose hardware-assisted virtualization to the guest OS.”
    • For Microsoft Hyper-V: Shut down the VM. Open a PowerShell prompt on the Hyper-V host (not the guest VM) and run the command: Set-VMProcessor -VMName “Your-VM-Name” -ExposeVirtualizationExtensions $true.

    Section 2: Install Latest Windows Updates

    Unlike a simple application, the Docker Engine integrates deeply with the Windows kernel. Microsoft regularly releases critical bug fixes, performance improvements, and even new container features directly through Windows Updates. By skipping updates, you are likely to encounter strange bugs, networking issues, or outright installation failures that the Windows engineering teams have already resolved.

    Prepare your server for a successful installation by getting it completely up to date.

    1. Open the Start Menu, type “Check for updates,” and open the System Settings panel.
    2. Click the “Check for updates” button and let Windows scan for all necessary updates.
    1. After the updates are installed, you will be prompted to restart your device. Do it. Rebooting your computer ensures that all changes are fully applied to the operating system before you proceed.

    Section 3: Understanding Windows vs. Linux Containers

    Windows Server can run both Windows and Linux containers, but you must choose the right one for your app. Pick Windows containers for .NET Framework or Windows-specific APIs. Use Linux containers for standard web stacks like NGINX, Node.js, Python, and databases.

    When Should You Use Windows Containers?

    These are native Windows containers. They run directly on your server, sharing the host’s Windows kernel, which makes them highly efficient and start quickly. Think of them as highly isolated Windows processes that have their own filesystem and registry, but fundamentally speak “Windows.”

    • Common Base Images: When you build a Windows container, you’ll start from a base image provided by Microsoft, such as:
      • Windows Server Core: This is the most common choice. It offers the best compatibility for older applications, as it includes a large subset of Windows APIs and services, such as IIS.
      • Nano Server: This is an incredibly lightweight, stripped-down version of Windows. You use it for modern, self-contained .NET Core/5/6+ applications to create the smallest possible image size.
    • When to use them: You must use a Windows container if your application is:
      • Built on the .NET Framework (e.g., version 4.8 or earlier).
      • An IIS-hosted website (ASP.NET, classic ASP).
      • A Windows Service.
      • Dependent on Windows-specific technologies like MSMQ, COM+, or the GAC.

    When Should You Use Linux Containers?

    When you want to run a standard Linux container (like one for NGINX, Python, or Node.js), Docker on Windows cleverly uses virtualization to run a tiny, purpose-built Linux virtual machine in the background. Your Linux containers run inside this hidden VM, not directly on the Windows kernel.

    You should use a Linux container when your application is a standard Linux workload. This is perfect for:

    • Web servers like NGINX or Apache.
    • Applications written in Python, Node.js, Ruby, or Go.
    • Databases like PostgreSQL, MySQL, or Redis.
    • Essentially, any application you would normally find on Docker Hub that is not explicitly for Windows.

    3. Installation Guide: Using PowerShell

    To manage a Windows Server effectively, you need to embrace automation and scripting. For the entire installation, we will use PowerShell for all tasks. It’s repeatable, less prone to human error, and the professional way to configure your servers.

    First, open PowerShell as an Administrator. You can do this by right-clicking the Start button and selecting “Windows PowerShell (Admin)” or “Windows Terminal (Admin)”.

    Step 1: Enable Required Windows Features

    Before you can install the Docker Engine, you must first enable the underlying features in the Windows operating system that support containerization and virtualization.

    In your elevated PowerShell window, run the following commands one by one:

    # Installs the core Windows Containers feature
    Install-WindowsFeature -Name Containers
    # Installs the Hyper-V role. This is best practice for security and compatibility.
    Install-WindowsFeature -Name Hyper-V 

    Even if you only plan to run Windows containers, installing the Hyper-V role enables “Hyper-V isolation.” This is a more secure way to run containers, as each one gets its own lightweight, dedicated kernel, preventing anything inside the container from affecting the host server.

    Step 2: Install the Docker Engine on Windows

    After your server has restarted, open another elevated PowerShell window. You will now use Microsoft’s DockerMsftProvider module to find and install the Docker Engine directly from a trusted repository.

    Run these two commands:

    # Installs the PowerShell module that knows how to find and install Docker
    Install-Module -Name DockerMsftProvider -Repository PSGallery -Force
    # Uses the module to install the latest validated version of Docker Engine
    Install-Package -Name docker -ProviderName DockerMsftProvider

    You will be asked to trust the repository; type A (for “Yes to All”) and press Enter to proceed.

    Step 3: Post-Install Verification

    Once your server is back online, it’s time to confirm that everything is working as expected. Open a new elevated PowerShell window and run these checks.

    1. Check the Docker Service: The Docker Engine runs as a Windows service. Run the following command to verify it. You should see the Status listed as Running.
    Get-Service docker
    1. Check the Docker CLI: Run the following command to verify that the docker command is available in your system’s PATH.
    docker --version

    This should return the Docker version you just installed, for example: Docker version 20.10.9, build 79ea9d3.

    1. Get Detailed Information: The ‘docker info’ command provides a comprehensive overview of your installation.
    docker info

    Post-Installation Configuration

    After installation, make Docker production-ready by adjusting these settings:

    • Create the Config File: Create a file named daemon.json inside the C:\ProgramData\docker\config\ directory. You will need to create the config folder yourself if it does not exist.
    • Move the Docker Data Directory: To prevent filling your C: drive, add the following to your daemon.json: "data-root": "D:\\Docker". This moves all images, volumes, and container data to the specified path on your D: drive.
    • Set up a Registry Mirror: To speed up image pulls for docker pull, configure a local mirror. Add "registry-mirrors": ["https://your.registry-mirror.url"] to prioritize pulling from your faster, local cache.
    • Grant Access to Non-Admins: To allow standard users to run Docker commands, add the following to the configuration: "group": "docker". This gives members of the local Docker security group access to the Docker engine.
    • Set a Network Proxy: To use Docker behind a corporate proxy, you must set an environment variable. Use PowerShell to run [Environment]::SetEnvironmentVariable("HTTP_PROXY", "http://user:pass@proxy:port/", [EnvironmentVariableTarget]::Machine).
    installing docker on windows
    • Run a Test Container: After configuring and restarting the Docker service, always confirm it’s working correctly. Run docker run mcr.microsoft.com/windows/nanoserver:ltsc2022 powershell -Command "echo Hello from your configured container!" to verify it works correctly.

    Suggested read: Self-Hosting Docker vs Cloud-Based Docker

    After Action Report

    Docker on Windows solves specific use cases, but most modern stacks run faster and more reliably on Linux. If you want that performance without managing Linux manually, RunCloud gives you a clean dashboard for deploying and managing Linux servers with ease.

    With RunCloud, you get:

    • Rock-Solid Security: RunCloud automates complex security configurations, so your server is hardened and protected from the start.
    • Total Flexibility: It works with any cloud provider (e.g., AWS, DigitalOcean, Vultr) or even a server in your own home. You never get locked into a single provider.
    • Complete Control: You always retain full root access and complete control of your server; RunCloud is your co-pilot, not a black box.

    If you’re ready to run Docker with fewer constraints and better performance, try hosting your containers on a fast Linux server managed through RunCloud’s easy dashboard.

    Create your free RunCloud account and deploy your next container the simple way.