Category: Tips & Tricks

  • Laravel Hosting: Best Platforms for Deploying Laravel Apps

    Laravel Hosting: Best Platforms for Deploying Laravel Apps

    Laravel currently powers over 1.5 million websites globally, and the ecosystem is growing faster than ever. Because of this massive growth, finding the best Laravel hosting has become a top priority for development teams, agencies, and enterprise architects. 

    This article compares several leading Laravel hosting solutions, including their strengths, pricing models, and suitability for different development workflows. 

    Common Challenges with Hosting Laravel Apps

    When choosing how to host a Laravel application, developers may need to consider the following challenges:

    1. The DevOps Burden of Unmanaged Servers: It takes a frustrating amount of time and effort to manage servers manually. Configuring NGINX, securing firewalls with iptables, manually renewing Let’s Encrypt certificates, and troubleshooting PHP-FPM bottlenecks require significant effort.
    2. Vendor Lock-in: Some managed and serverless platforms encourage the use of provider-specific databases, caching services, storage systems, or deployment configurations. The more closely an application depends on these services, the more work may be required to migrate it elsewhere. 
    3. Cost Predictability at Scale: Usage-based pricing can make monthly costs harder to predict, particularly during sustained traffic increases or unexpected spikes. In some cases, this can cost more than a flat-rate compute instance. 
    4. Architectural Isolation: Some server configurations make it difficult to run applications that require conflicting PHP versions or supporting services. Without suitable isolation, these differences can cause dependency conflicts. 
    Top Laravel Hosting Platforms

    The platforms below take different approaches to server management, application isolation, pricing, and scalability. The best Laravel hosting option will depend on your technical requirements and preferred level of infrastructure control.

    Laravel Forge

    Laravel Forge is a developer-focused server management tool and has been the go-to choice in the PHP community since 2014. It is created by the team behind the Laravel framework itself and is designed to provision and manage VPS instances across popular cloud providers such as DigitalOcean, AWS, and Hetzner. 

    The greatest strength of Forge is its deep, native understanding of the modern PHP ecosystem. It provides first-class support for managing background queue workers via Supervisor, handling scheduled cron tasks, and deploying database clusters straight from a clean, minimalist dashboard. If you work primarily within the Laravel ecosystem, Forge provides a closely integrated way to provision servers and deploy applications. 
    Laravel Forge website homepage

    Suggested read: What is Laravel? A Comprehensive Guide for 2026

    While Forge is incredibly powerful, it traditionally installs your software stack natively onto the server’s operating system. This approach is highly efficient but may occasionally require extra care when running multiple applications on the same server that require conflicting versions of secondary services. For teams that prefer a deployment service created by the Laravel team, Forge remains a strong option. 

    Cost: Forge uses a SaaS model. The Hobby plan starts at $12 per month for managing a single server. As your needs grow, you can upgrade to the Growth plan at $19 per month for unlimited servers, or the Business plan at $39 per month to unlock advanced deployment workflows and priority support. You simply pay this flat management fee alongside your separate raw cloud server costs.

    Laravel Cloud & Laravel Vapor

    If you want to eliminate server management, you can use one of two first-party cloud solutions: Laravel Vapor and the newly launched Laravel Cloud. Laravel Vapor is a serverless deployment platform powered by AWS, while Laravel Cloud is a managed application platform built specifically for Laravel. Both reduce the amount of infrastructure that developers must manage directly. 

    Laravel Vapor deploys applications to AWS Lambda and can automatically scale application capacity in response to changing traffic. This makes it suitable for applications with variable or unpredictable workloads. Laravel Cloud supports hibernation for compatible compute resources. These resources can scale to zero while idle and resume in under 500 milliseconds when traffic returns, reducing compute charges during inactive periods. 
    Laravel Cloud website homepage

    Suggested read: How to Install and Deploy Bagisto (Laravel eCommerce)

    These platforms suit developers who want to reduce the amount of infrastructure they manage directly. Laravel Cloud automatically injects your environment variables, handles dedicated worker clusters for queue processing, and offers native support for managed databases. You can connect your repository and deploy your code while the platform manages much of the underlying routing and infrastructure. Scaling behavior and resource allocation can then be configured for the application. 

    Cost: These platforms rely on usage-based billing. Vapor offers a free Sandbox tier, while its paid plans and any underlying AWS resources incur separate charges. Laravel Cloud’s Starter plan costs $5 per month and includes $5 in monthly usage credits. Further charges depend on the resources used. This pricing can suit small or variable workloads, although costs may be harder to forecast than those of a fixed-price server. 

    Cloudways

    Cloudways provides a good balance between traditional shared hosting and complex cloud infrastructure by offering a fully managed experience. Instead of buying a server from DigitalOcean and connecting it to a separate control panel, Cloudways bundles the server and the management interface into a single, unified monthly bill.

    Cloudways includes caching, SSL management, backups, and several server security features. Other services, including CDN and malware-protection products, may be available as paid add-ons. Their platform is incredibly user-friendly, allowing you to launch applications, configure SSL certificates, and manage automated backups with just a few clicks.
    Cloudways website homepage

    Suggested read: How to Deploy Laravel with Docker on VPS in 2025 (Comprehensive Guide)

    The primary trade-off with Cloudways is its pricing structure at scale. Because they bundle the service, you pay a markup on the underlying server cost. While this is fantastic for one or two small servers, if you are running a digital agency that manages dozens of large servers, you may find that these markup fees become quite expensive compared to purchasing unmanaged servers directly. 

    Cost: Cloudways is highly attractive for single-server setups. Cloudways currently advertises DigitalOcean-based managed hosting plans starting at $11 per month, which include server resources and Cloudways’ management platform. Cloudways also provides 24/7 support, which may appeal to business owners who do not want to manage servers without assistance.

    Ploi

    Ploi is a SaaS server management panel designed for developers and agencies. Ploi connects to your VPS and offers an easy-to-navigate, functional interface. It also provides several unique features that anticipate the needs of modern web agencies.

    For example, it includes out-of-the-box support for load balancing, status pages, and staging-to-production deployment workflows. Furthermore, its seamless one-click installations across platforms such as WordPress, Statamic, and Nextcloud make it incredibly versatile for agencies managing mixed technology stacks.

    Ploi also offers a Team Management feature to help you collaborate with team members. You can create a team and maintain full control over who has access to what. It provides granular, role-based permissions that you can configure per user, per server, and per site. This makes it possible to grant a team member specific access, such as database-only rights, without compromising other areas. 
    Ploi website homepage

    Suggested read: Laravel With Git Deployment The Right Way

    It successfully takes complex infrastructure tasks, such as setting up load balancers or configuring database backups with external providers, and simplifies them into intuitive processes. 

    Cost: Ploi offers a free plan for one server. Its paid Basic plan costs €8 or $10 per month for up to 5 servers, while higher plans increase the server allowance and add more features. 

    Upsun

    Upsun is a modern, multi-cloud Platform-as-a-Service (PaaS) that offers deep, native integrations specifically tailored for Laravel development. Unlike traditional VPS management tools, Upsun manages the underlying infrastructure entirely across AWS, Azure, and GCP, while allowing you to define managed services (such as PostgreSQL, Redis, or RabbitMQ) directly in your configuration files.

    A notable Upsun feature is its support for preview environments. When you create a new Git branch, Upsun can automatically spin up an isolated preview environment that inherits live data, services, and routing from your production setup. This allows your team to test bug fixes and new features in a highly realistic, production-like setting before ever pushing to the live app.
    Upsun website homepage

    Upsun also includes built-in integrations for Blackfire.io to profile your database queries and queue jobs, along with environment-specific toggles for Laravel Telescope. It even supports dedicated worker containers for Laravel Horizon, ensuring your background queues never compete with your web traffic for resources.

    Cost: Because Upsun uses resource-based, per-second pricing, the final cost depends on the resources and services used. Its pricing calculator can provide an estimate, though the monthly total may vary based on the precise CPU, RAM, and storage your application consumes, alongside variable and fixed components such as user licenses (€10.00/user/month), project fees (€9.00/project/month), storage (€0.49/GB/month), backups (€0.10/GB/month), and request volume (€1.00/100,000 requests). 

    RunCloud

    RunCloud (that’s us!) is a server management platform for teams who want to use their own cloud servers and manage them through a graphical interface. It can connect to compatible Ubuntu servers from a wide range of cloud providers.

    What sets RunCloud apart is its innovative use of Docker-containerized servers. If you use the Dockerized server stack on RunCloud, you can isolate different web applications on your server. 
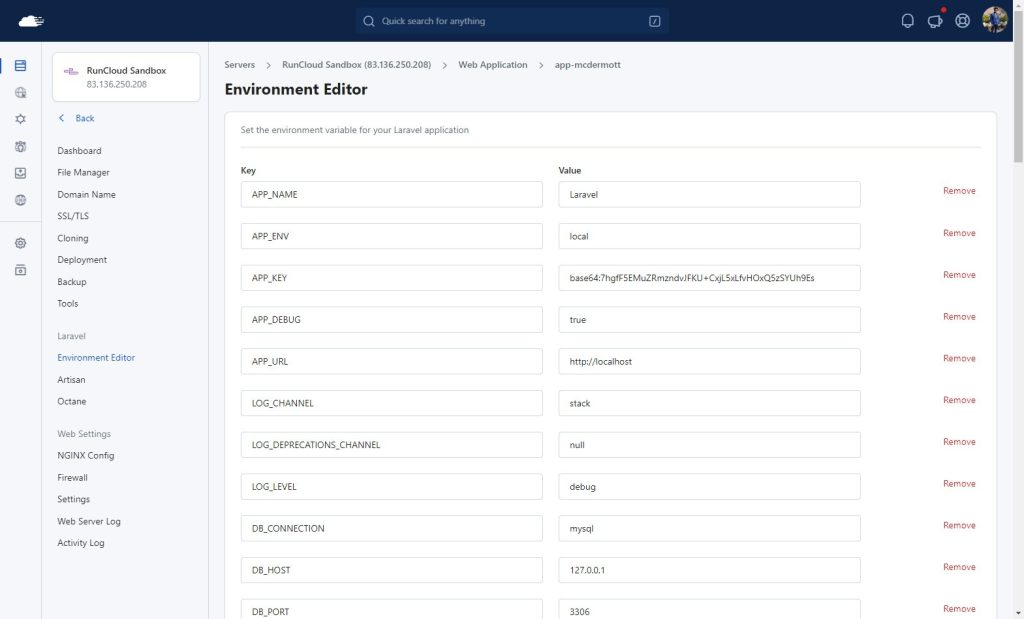
    RunCloud Laravel Environment editor

    This isolation can prevent dependency conflicts between applications and reduce the impact of an application-level problem on other containers. It also allows different applications to use different supported PHP versions on the same server. Container isolation does not remove the need to secure and update the host server and each application.

    RunCloud also offers Git with atomic deployment functionality. This minimizes application downtime during updates by preparing your new release in an isolated directory before updating the active web root symlink. To coordinate this process across your organization, you can use RunCloud’s teams and workspaces features to partition your projects and manage access permissions for your team members.
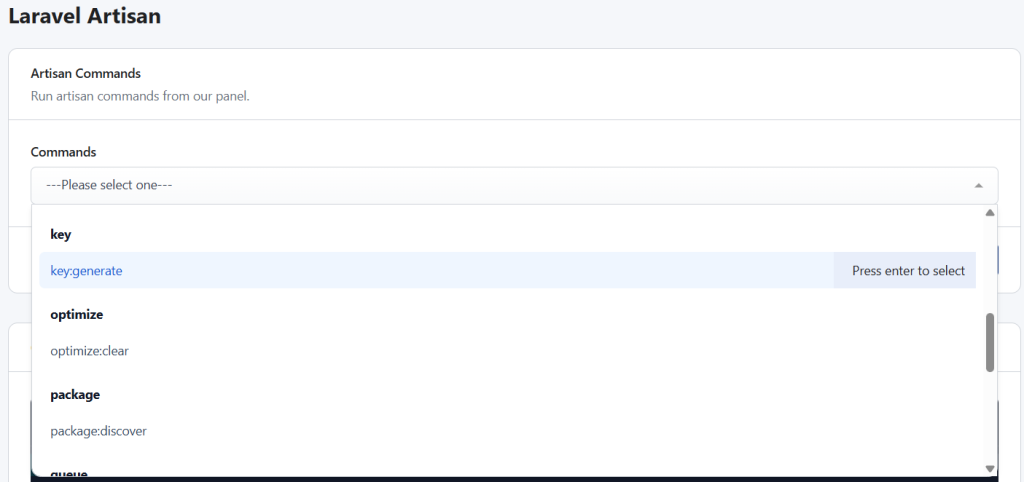
    Laravel Artisan

    You can also use the RunCloud API to configure applications, trigger deployments, and automate recurring server-management tasks. For high-performance setups, follow our guide to set up Laravel Octane on RunCloud servers.

    Cost: RunCloud uses flat-rate subscription plans, with cloud-server charges paid separately. The Essentials plan costs $9 per month for one server. The Professional plan costs $19 per month and supports up to 50 servers, while the Business plan costs $49 per month and supports up to 100 servers. Business also includes features such as atomic deployment, team management, a Web Application Firewall, and API access. 

    Total Cost of Ownership for Hosting Laravel Apps

    The relative cost of a PaaS, serverless platform, or server management panel depends on the application’s traffic, resource requirements, staffing needs, and operational model. A control panel may offer predictable management fees, while a PaaS can reduce the time spent on infrastructure maintenance.

    Direct cost comparisons between these platforms are difficult because they include different services and use different billing models. RunCloud and Forge charge a management subscription in addition to the cost of your servers. Cloudways combines managed hosting and server resources into a single price. Laravel Cloud and Upsun charge according to the resources and services used. 

    Infrastructure ModelManagement Fee TierCompute Cost ModelTCO: 1 Server / MoTCO: 10 Servers / Mo
    RunCloud (Essentials/Pro)$9 to $19 / moRaw compute ($6/svr)$15.00$79.00
    Laravel Forge (Hobby/Pro)$12 to $39 / moRaw compute ($6/svr)$18.00$99.00
    Cloudways (Managed)Bundled markupApprox. $14/svr base$14.00$140.00
    Laravel Cloud (PaaS)$5 to $200+ / moUsage-based / Scale$5.00+ usageVariable (High)
    Upsun (PaaS)Resource-basedUsage / Per SecondVariableVariable (High)

    Final Thoughts

    In this post, we have discussed several tools for managing and hosting your Laravel applications. Forge offers close ties to the Laravel ecosystem; Laravel Cloud and Vapor reduce the need for direct infrastructure management; Cloudways bundles hosting and management; Ploi provides agency-focused server tools; and Upsun offers a managed multi-cloud platform. RunCloud suits teams that want to retain control of their cloud servers while managing them through a central panel. 

    RunCloud offers a 7-day free trial for developers and teams who want to test its server management, deployment, and application isolation features.
    Start using RunCloud Today.

  • How to Block AI Crawlers (GPTBot, ClaudeBot, PerplexityBot, Bytespider) on Your Server in 2026

    How to Block AI Crawlers (GPTBot, ClaudeBot, PerplexityBot, Bytespider) on Your Server in 2026

    AI crawlers can consume bandwidth, increase server load, and collect your content without sending visitors back to your website. Blocking them isn’t as simple as adding a few lines to robots.txt, since not every crawler respects those instructions.

    You also need to distinguish between different types of AI bots.

    • Training crawlers such as GPTBot, ClaudeBot, and Bytespider collect content for AI development.
    • User-triggered agents, such as ChatGPT-User and Perplexity-User, may help your pages appear as cited sources in AI-generated answers.

    Blocking every AI-related user agent could reduce your visibility as well as your server traffic.

    This guide explains how to control AI crawler access without accidentally blocking legitimate search engines or useful AI referral traffic. You will learn how to:

    • Identify the AI crawlers you may want to block
    • Set rules in robots.txt
    • block requests at the NGINX server level
    • Configure Cloudflare’s AI crawler controls
    • Test your rules and confirm they work

    By the end, you will have a layered approach that gives you greater control over who can access your content and how much server capacity automated crawlers consume.

    Why robots.txt Alone Won’t Stop AI Crawlers

    AI-related crawlers serve several different purposes. Some collect content for model training, while others build search indexes or retrieve pages in response to a user request. High-volume crawling can consume bandwidth and server resources, but the impact depends on the crawler, its request rate, your caching configuration, and your application stack.

    This is exactly why you should identify the crawler and its purpose before deciding whether to block it.

    While adding a disallow directive to your robots.txt file is the traditional method for managing bots, it is ineffective against these bots because it runs on an honor system. Aggressive scrapers, poorly configured rogue bots, and many proprietary data brokers routinely ignore robots.txt entirely.

    If you want to protect your infrastructure and intellectual property, you need to implement server-level blocking using NGINX or implement other firewall measures. This allows you to intercept these unauthorized requests at the server level, where you can drop the connection by returning a 403 Forbidden response before the request ever reaches your web application or consumes your server’s computing resources.

    Suggested read: How To Use ModSecurity and OWASP CRS For Web App Firewall (WAF) To Secure Your Website

    Which AI Bots Should You Block in 2026?

    If you want to protect your server resources and intellectual property, you should prioritize blocking the following primary training crawlers.

    Targeting High-Volume AI Training Crawlers

    The following control tokens and user agents are associated primarily with AI training, model development, or large-scale dataset collection:

    • GPTBot
    • ClaudeBot
    • Bytespider
    • Amazonbot
    • Applebot-Extended
    • Google-Extended
    • Meta-ExternalAgent
    • CCBot

    Claude-SearchBot should be considered separately, as Anthropic uses it to support search results rather than for general model training. 

    PerplexityBot is also separate from bulk training crawlers. Perplexity states that it uses PerplexityBot to build its search index and surface links in Perplexity results, not to train foundation models. Blocking it may prevent your pages from appearing in Perplexity search results. 

    block AI crawlers

    Evaluating Real-Time AI Search Agents

    Real-time fetchers operate under a different set of rules than bulk scrapers. Instead of indiscriminately harvesting data, these digital assistants visit your server only when a human query explicitly triggers them to fetch your content. This makes them an important component for maintaining visibility in modern, AI-driven search results.

    Integrating with these tools can be a good marketing move, but it requires balancing visibility against your specific privacy concerns.

    • ChatGPT-User
    • Perplexity-User
    • OAI-SearchBot
    • Claude-User

    Allowing these agents enables AI services to retrieve and cite your current content in response to user requests. It doesn’t guarantee that your page will be selected, cited, ranked prominently, or visited by the user. However, if your domain contains sensitive data or strictly paywalled content, you should weigh your goals carefully. If you prefer total privacy over AI search exposure, block these alongside the bulk training bots.

    Anthropic uses separate user agents for different purposes. ClaudeBot crawls content for model development, Claude-SearchBot supports Claude’s search results, and Claude-User may retrieve a page in response to an individual user’s request. 

    Suggested read: How to Use Cloudflare Firewall Rules to Protect Your Web Application

    Will Blocking AI Crawlers Hurt Your Google Rankings?

    Blocking AI crawlers won’t harm your traditional Google Search rankings if you implement your security blocks correctly and target the right bots. Google designed its ecosystem to allow web admins to opt out of generative AI training without sacrificing their organic SEO visibility.

    Google uses the Googlebot user agents to crawl, index, and rank your pages in standard search engine results. For AI training and generative model grounding (such as feeding live search context to Gemini), Google uses a separate control token known as Google-Extended. Disallowing Google-Extended tells Google not to use your content for training and grounding in certain Gemini systems. Google states that Google-Extended doesn’t affect inclusion or ranking in Google Search.

    Google-Extended doesn’t control AI features that form part of Google Search itself. Access to those features is governed through Googlebot and standard Search controls such as nosnippet, data-nosnippet, max-snippet, and noindex.

    However, there is a massive technical caveat for web admins: unlike most web scrapers, Google-Extended doesn’t have its own separate HTTP request user-agent string. The physical crawling is still executed using standard Google crawler user agents, meaning the Google-Extended token functions purely in a control capacity within your robots.txt file.

    Because the phrase “Google-Extended” will never appear in your server’s incoming HTTP requests, you can’t block it at the NGINX or Cloudflare WAF level using a simple User-Agent string match. You must use the traditional robots.txt opt-out method for Google’s AI training and rely on server-level blocks for other companies’ bots.

    Because of this shared infrastructure, you must be extremely cautious when writing your NGINX rules or WAF policies. Using broad wildcards like *Google* or *bot* to stop scrapers will result in a catastrophic SEO failure, as you will accidentally block the legitimate Googlebot, Googlebot-Image, and Googlebot-Video indexers that your business relies on.

    Suggested read: Linux Server Hardening: 11 Steps to Secure a Production VPS 

    Implementing a Multi-Layered Strategy for AI Bot Management

    Relying on a single method for blocking unwanted AI traffic can leave your infrastructure exposed. If you want to build a truly resilient defense, it is best to implement a layered strategy that covers public directives, server-level interception, and network-edge filtering. This ensures that if one mechanism fails or is ignored, your subsequent layers act as a fail-safe to protect your server resources.

    Layer 1 – Block AI Bots with robots.txt

    To set up your first layer of defense, create or edit a simple text file named robots.txt and place it in the root directory of your website (usually the public_html or htdocs folder). 

    To edit your robots.txt, you can simply open your web host’s file manager, create this file, and copy-paste the code below to ask all major 2026 AI training bots to stay away from your entire site:

    User-agent: GPTBot
    User-agent: ClaudeBot
    User-agent: Bytespider
    User-agent: Amazonbot
    User-agent: Applebot-Extended
    User-agent: Google-Extended
    User-agent: Meta-ExternalAgent
    User-agent: CCBot
    Disallow: /

    Why robots.txt alone is not enough (RFC 9309 is advisory)

    While adding a robots.txt file is the industry standard first step, it is important to understand that it operates entirely on an honor system. RFC 9309 standardizes how crawlers should interpret robots.txt, but it doesn’t provide authentication or access control. Compliant crawlers follow its directives voluntarily, while another client can still request the same URL directly. 

    Reputable companies like Google and OpenAI currently program their bots to respect these rules, but aggressive scrapers, rogue data brokers, and malicious AI crawlers will completely ignore your robots.txt file and scrape your content anyway. Therefore, relying on this file alone leaves your server vulnerable to heavy automated traffic, so you must implement server-level blocking as well.

    Layer 2 – Block AI Bots at the NGINX Layer

    If you search for tutorials on how to block bots using NGINX, almost every old guide will tell you to place an if statement directly inside your server block (for example, if ($http_user_agent ~* "GPTBot") { return 403; }).

    Complex rewrite logic inside an NGINX if block can produce unexpected results, particularly when it is placed inside a location block. A simple condition that performs only a return is much less problematic.

    If you want to block traffic, you should use the map directive, which is a better and highly optimized alternative to if statements. When a visitor sends a request, NGINX checks their User-Agent exactly once against this map and assigns a variable (like a simple true/false flag). Because it is evaluated outside the complex location rules, it is incredibly fast and can automatically apply to every single website hosted on your entire server without repeating code.

    To implement this on your server, you will need to access your global NGINX configuration (often located in /etc/nginx/conf.d/) and create a new file named ai_bot_map.conf. Paste the following map directive into that file, which flags the 2026 AI bots with a 1 (true) if they match, and a 0 (false) for normal human visitors:

    map $http_user_agent $is_ai_bot {
        default 0;
        "~*GPTBot" 1;
        "~*ClaudeBot" 1;
        "~*Bytespider" 1;
        "~*Amazonbot" 1;
        "~*Meta-ExternalAgent" 1;
        "~*CCBot" 1;
    }

    Don’t add Google-Extended or Applebot-Extended to this map. They are robots.txt control tokens rather than independent crawler User-Agent strings. Instead, use robots.txt to control them. 

    Choosing the response code

    After identifying the crawlers, you need to decide how your server should handle them when they arrive. Here is a list of appropriate HTTP status codes you can return when rejecting a web request.

    403 Forbidden 

    Returning a 403 Forbidden status is the most common and standard choice because it clearly communicates to the bot that the server understood the request but is actively refusing to fulfill it. 

    444 (Nginx-specific, drops the connection with no response)

    If you are dealing with an incredibly aggressive bot that is hitting your server thousands of times a minute and draining your bandwidth, you should use NGINX’s special 444 response code. Unlike standard HTTP codes, 444 doesn’t send any headers or error pages to the bot; it simply closes the connection immediately. This can reduce the response work and outbound data associated with rejected requests, although NGINX must still accept and process the connection far enough to match the rule. 

    410 Gone (signals permanent removal, deters re-crawls)

    Another good option is to return a 410 Gone status code, which signals to the AI crawler that the resource it is looking for has been permanently deleted and won’t be returned. Use 410 Gone only when the requested resource has been permanently removed. Don’t return 410 solely as a bot-blocking technique for pages that remain available to other visitors. Use 403 or 444 when you are refusing access based on the requester rather than the state of the resource. 

    Logging Blocked Requests for Audit

    You shouldn’t blindly block traffic without keeping a record of what your server is doing. You can instruct NGINX to log blocked bot attempts to a separate file so they don’t clutter your main website analytics.

    By adding a simple directive like access_log /var/log/nginx/blocked_ai_bots.log; inside the block that returns your 403 or 444 code, you create an isolated, easily readable audit trail where you can safely monitor which AI companies are trying to harvest your data.

    Suggested read: How to Block IP Address Using WordPress .htaccess File to Stop Bad Visitors

    Layer 3 – Block AI Bots at the Edge with Cloudflare WAF

    If you manage your DNS through Cloudflare, you can easily intercept AI bots at the network edge before they ever reach your web server by configuring their built-in bot policies. Cloudflare has updated its approach to AI traffic by introducing new features that categorize bots into three distinct behaviors:

    • “Search” (crawlers indexing content to answer queries later and drive referrals)
    • “Agent” (real-time automated bots acting on a human’s behalf, like chat fetch bots) 
    • “Training” (scrapers permanently absorbing your data to train large language models).

    Configure AI Bot Policies

    Cloudflare provides two related ways to manage AI traffic:

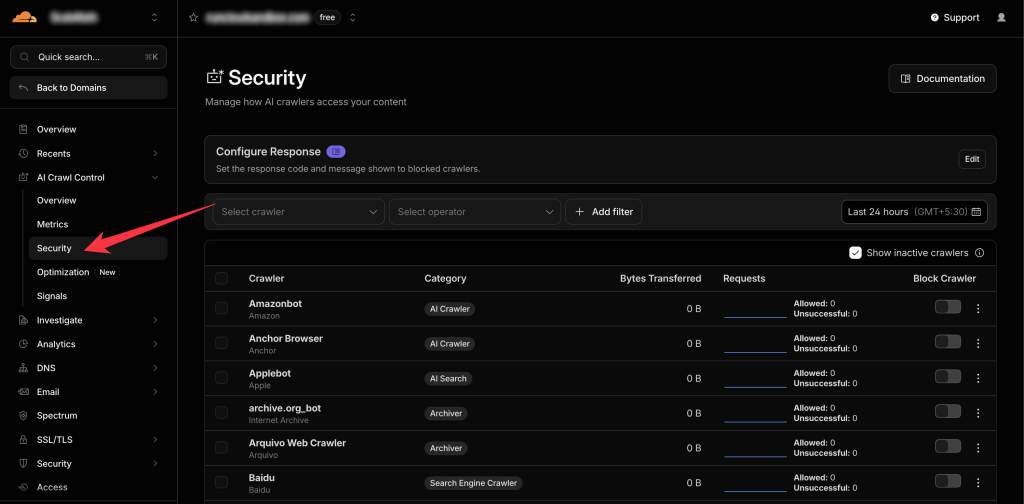
    In AI Crawl Control, open the Crawlers tab to review individual crawlers and set each one to Allow or Block.

    For broader behavior-based controls, open the Security settings and configure how Cloudflare handles Search, Agent, and Training traffic. Each category can be allowed, blocked across the domain, or blocked only on pages where Cloudflare detects advertising.

    For each type of bot, you can choose to “Block (on all pages),” “Allow (do not block),” or select “Block on pages with ads,” which uses Cloudflare’s automated detection to block bots strictly on monetized pages while leaving the rest of your site accessible.

    Additionally, from September 15, 2026, Cloudflare will automatically block ‘Training’ and ‘Agent’ bots on pages with ads for all new domains, while keeping Search bots allowed. Cloudflare’s updated system will apply the most restrictive rule to multi-purpose crawlers, such as Googlebot or Applebot, that crawl for both search indexing and AI training.

    From 15 September 2026, Cloudflare plans to evaluate multi-purpose crawlers against all their declared behaviors. A crawler that combines Search and Training may therefore be affected by your Training rule even when Search traffic is allowed.

    Review Cloudflare’s displayed outcome before applying category-wide rules, particularly where a crawler also supports conventional search discovery.

    cloudflare AI crawlers block

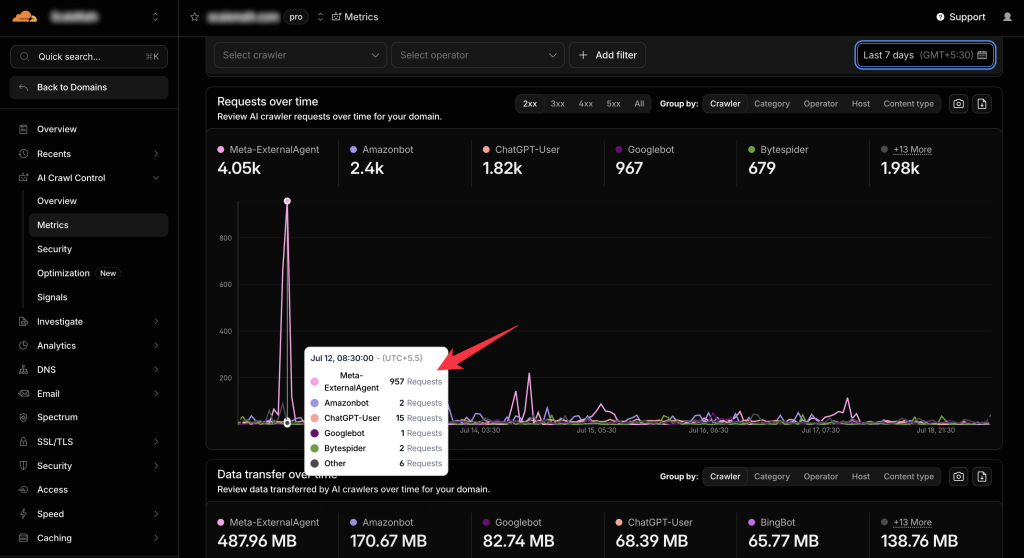
    Before enforcing broad blocks across your entire domain, you can also establish governance rules using Cloudflare’s AI Audit tools. The AI Audit dashboard provides visibility into which AI services are scanning your website, allowing you to clearly see the volume of requests from specific bots and understand how they interact with your content.

    By analyzing this traffic, novice users can make data-driven security decisions, such as explicitly allowing search-focused tools that drive referral traffic, while firmly rejecting exploitative scrapers.

    AI traffic in cloudflare

    Future of AI Content Monetization

    Cloudflare is also testing Pay Per Crawl, which is currently in closed beta. Participating site owners can set a price and choose whether to allow, block, or charge supported crawlers.

    A crawler that doesn’t provide the required payment information receives an HTTP 402 Payment Required response. Availability and crawler participation remain limited, so this shouldn’t yet be treated as a general replacement for blocking.

    Suggested read: What is Fail2Ban with Setup & Configuration? (Detailed Guide)

    Verify that NGINX Blocking is Working

    After deploying your NGINX mapping rules, you shouldn’t simply assume they are functioning perfectly. Server-level configurations are powerful but unforgiving; a minor syntax error could potentially block legitimate traffic or fail to stop the unwanted bots you are targeting.

    You need to validate your setup to ensure your defenses are correct and not causing collateral damage to your site’s availability. Follow the steps below to verify that your block list is successfully intercepting requests.

    Curl with a faked GPTBot User-Agent and expect 403

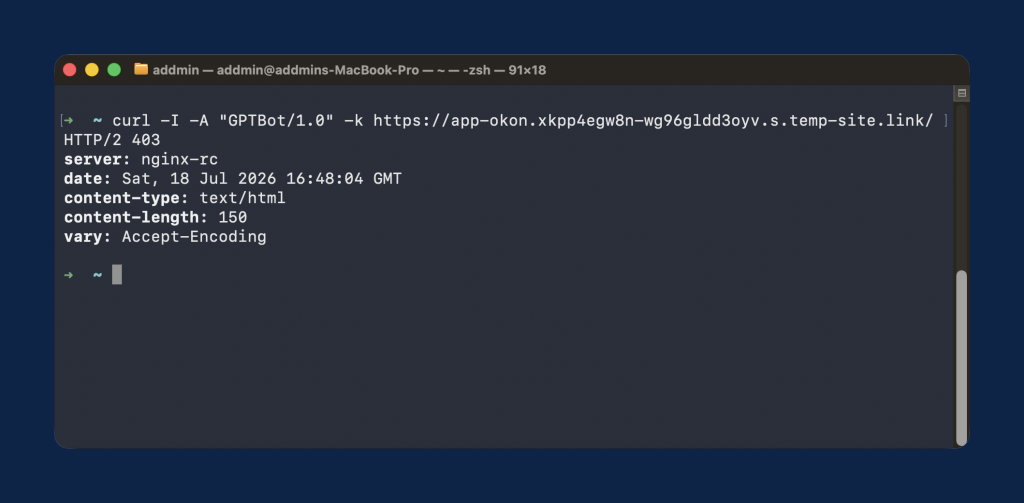
    The easiest way for a novice to test if their server block is working is to pretend to be an AI bot using the command line. Open your computer’s terminal (or Command Prompt) and type the following command exactly:

    curl -I -A "GPTBot/1.0" https://example.com

    This command sends a fake request to your site claiming to be GPTBot; if your NGINX rules are working correctly, your terminal will print out an HTTP/2 403 Forbidden error (or return an empty reply if you used the 444 code), proving the block is active.

    Tail NGINX access logs and grep for the bot user-agents

    To watch your server actively defend itself in real-time, you can filter your live server logs for specific bot names. Log in to your server via SSH and run the command:

    tail -f /var/log/nginx/access.log | grep -i "gptbot"

    The tail -f command streams the log file live, while grep filters out everything except requests containing the word “gptbot”, allowing you to sit back and watch the exact moment the AI crawler hits your server and gets rejected.

    Cross-check with Cloudflare bot analytics

    Finally, you can verify your edge-level blocks by reviewing your visual data within the Cloudflare dashboard. Navigate to Security and then click on Events to see a complete log of all web traffic that triggered your WAF rules.

    By filtering this list by “User Agent” or specifically looking at the “Block AI bots” rule metrics, you can visually confirm how many thousands of requests from scrapers like ClaudeBot and Bytespider were successfully dropped by Cloudflare’s network before they ever touched your origin server.

    Final Thoughts: Take Control of Your Server Traffic

    In this article, we have discussed how to manage custom NGINX configurations and protect your websites. It might sound overwhelming, but RunCloud makes the entire process effortless.

    With RunCloud, you can easily manage and deploy sites on your own cloud infrastructure without needing to be a command-line expert. Its highly intuitive dashboard allows you to make quick NGINX updates and instantly reload your server to deploy those security rules across all your hosted applications in just a few clicks.

    Whether you’re hosting a single high-traffic web application or managing dozens of client sites, having complete, frictionless control over your hosting environment is important. 

    Start using RunCloud today.

    Should You Block AI Crawlers? Common Questions Answered

    Will blocking GPTBot or ClaudeBot affect my Google search rankings?

    No, blocking AI crawlers like GPTBot or ClaudeBot won’t negatively impact your Google search rankings. These bots are completely separate from Googlebot, which is the scraper responsible for indexing your site for search engine results. Blocking AI scrapers only prevents your content from being scraped to train their large language models.

    What is the difference between ClaudeBot, Claude-SearchBot, and Claude-User? 

    ClaudeBot crawls web content for Anthropic’s model development. Claude-SearchBot supports Claude’s search results, while Claude-User may retrieve a page in response to an individual user’s request.
    You may choose to block ClaudeBot while allowing Claude-SearchBot and Claude-User if you want to limit training access without removing your content from Claude’s search and user-directed retrieval features.

    Can AI crawlers bypass robots.txt and NGINX blocks?

    Reputable AI crawlers will respect robots.txt directives, but rogue scrapers or malicious bots can easily ignore them. NGINX blocks are significantly more powerful because they intercept and drop the connection at the server level based on the User-Agent or IP address before the site even loads. Custom NGINX rules provide stronger enforcement than robots.txt because they can reject matching requests before they reach the application. User-Agent matching is not foolproof, since another client can spoof a crawler’s name.
    For stronger protection, combine NGINX rules with rate limiting, request logs, verified crawler IP ranges where available, and edge-level bot controls such as Cloudflare.

    Should I block ChatGPT-User and Perplexity-User the same way as I do for GPTBot?

    It depends on your goals, as GPTBot crawls your site globally for AI training, whereas ChatGPT-User and Perplexity-User act as real-time search agents triggered by active user prompts. Blocking these “User” bots will prevent those AI tools from summarizing or linking to your live pages in their chat interfaces. If you want your site to be cited as a live source in AI-generated answers, you should leave user bots alone and block only training bots.

    Does blocking Google-Extended affect Googlebot or Google Ads?

    No, blocking Google-Extended only prevents your site’s content from being used to train Google’s generative AI models, such as Gemini. It operates entirely independently from traditional search indexing and advertising systems. Disallowing Google-Extended doesn’t affect your inclusion or ranking in Google Search. It is separate from the Googlebot controls used for conventional Search crawling.
    Avoid blocking broader Google user agents or IP ranges at the server or firewall level, since an overly broad rule could interfere with Google services that rely on those crawlers.

  • Perfmatters Review and Setup Guide: Features, Pricing, Pros and Cons

    Perfmatters Review and Setup Guide: Features, Pricing, Pros and Cons

    If your WordPress site is struggling to pass Core Web Vitals, despite using a premium caching plugin, you aren’t alone. WordPress themes and page builders are getting more complex, and standard caching isn’t always enough to eliminate main-thread blocking JavaScript or prevent Cumulative Layout Shift (CLS).

    That is where Perfmatters steps in.

    Perfmatters isn’t a replacement for your caching plugin – it’s the final tuning layer, focusing on bloat removal and script management. 

    In this article, we’ll review the Perfmatters plugin, explain its features, pricing, and exactly how to use it effectively.

    By the end of this article, you’ll be able to make your WordPress site faster, more responsive, and more user-friendly with the Perfmatters plugin.

    The TL;DR Verdict: Is Perfmatters Worth It?

    Yes. If your site has sluggish Interaction to Next Paint (INP) scores or frustratingly slow Largest Contentful Paint (LCP) times, then using Perfmatters is one of the most effective ways to speed up your website.

    Who it’s for:

    • Site owners who are trying to meet Core Web Vitals requirements.
    • Users with “heavy” page builders (Elementor, Divi) who need to trim unused scripts.
    • WooCommerce store owners who need granular control over where checkout scripts load.
    • Power users looking to pair a script manager with their existing caching stack (such as WP Rocket or RunCloud’s server-level caching).

    Who should skip it:

    • Complete beginners looking for a hands-off, “set-it-and-forget-it” optimization plugin.
    • Users who only want image compression (Perfmatters does not compress images or convert to WebP).

    What is Perfmatters?

    Perfmatters is a lightweight, premium WordPress performance plugin. Unlike traditional all-in-one performance plugins that focus heavily on page caching and CDN integration, Perfmatters specializes in asset management and bloat removal.

    Its philosophy is simple: WordPress and its plugins load a massive amount of code on every single page, even when that code isn’t being used. Perfmatters allows you to selectively disable CSS and JavaScript where they aren’t needed, reducing the overall page size, lowering HTTP requests, and giving the browser less work to do.

    Because it doesn’t handle page caching, it’s designed to work alongside plugins such as WP Rocket or server-side solutions like RunCache.

    How Perfmatters Improves Core Web Vitals

    Let’s take a quick look at some of the core features of Perfmatters and how it improves Core Web Vitals. 

    1. The Script Manager

    The Script Manager is the primary reason most developers buy Perfmatters. It allows you to view every CSS and JavaScript file loading on a specific page and toggle them off with a single click.

    By disabling an unused slider script on your homepage or stopping WooCommerce cart scripts from loading on your blog posts, you significantly reduce JavaScript execution time. This is the single most effective way to improve your Interaction to Next Paint (INP) score.

    2. General Bloat Removal 

    Out of the box, WordPress includes code for emojis, dashicons, the REST API, and XML-RPC. If you aren’t using these, they’re just dead weight.

    Perfmatters offers a dashboard with simple toggle switches to disable these unnecessary WordPress core features. This reduces overall HTTP requests and slims down the page weight.

    3. Advanced Lazy Loading

    Most modern browsers have native lazy loading, but Perfmatters takes it further by letting you lazy-load images, iframes, and videos. Most impressively, it can replace YouTube iframes with a static preview image, only loading the heavy video player when the user clicks play.

    Deferring off-screen images ensures the browser focuses its resources on the content the user sees first, drastically improving Largest Contentful Paint (LCP). This feature can be quite powerful, providing a massive performance boost for media-heavy sites.

    4. Adding Missing Image Dimensions

    If you upload an image without specifying its width and height, the browser doesn’t know how much space to reserve for it. When the image finally loads, the content below it jumps down the page.

    Perfmatters automatically adds missing width and height attributes to images. This directly prevents Cumulative Layout Shift (CLS), making your pages feel stable as they load.

    5. Local Analytics and Fonts

    Loading third-party resources (like Google Analytics or Google Fonts) requires the browser to perform DNS lookups and establish new connections, which takes time.

    Perfmatters can download Google Fonts and your Google Analytics script and host them locally on your server. This reduces DNS lookups and gives you control over browser caching for these files.

    How Much Does Perfmatters Cost?

    Perfmatters has three pricing plans based on the number of sites you want to use it on. The plans are:

    • Personal: $29.95 per year for 1 site.
    • Business: $59.95 per year for 3 sites.
    • Unlimited: $124.95 per year for unlimited sites and multisite networks.

    All plans come with 1 year of updates and support, a 30-day money-back guarantee, and a 10% renewal discount.

    Pros and Cons of Perfmatters

    ProsCons
    Lightweight Footprint: Minimal code with surgical, granular script control.No Free Version: No free tier or trial available to test before buying.
    Best-in-Class Script Manager: Unmatched control over per-page/post asset management.Not All-in-One: Requires pairing with a separate page caching solution.
    Core Web Vitals Booster: Drastic improvements to INP, LCP, and CLS when properly configured.No Image Optimization: Lacks built-in image compression or WebP conversion features.
    Highly Compatible: Works flawlessly alongside caching plugins (WP Rocket, FlyingPress, RunCloud Hub).Learning Curve: Requires technical knowledge to identify which scripts to disable safely.
    Privacy & Speed: Local hosting for Google Analytics and Google Fonts built right in.Manual Configuration: Not a “set-and-forget” plugin; requires active tweaking for top results.
    Automated Maintenance: Scheduled database cleanup keeps your site lean.

    How To Install Perfmatters Plugin

    After visiting https://perfmatters.io to purchase and download the plugin, installing it is very easy and straightforward. Here are the steps to follow:

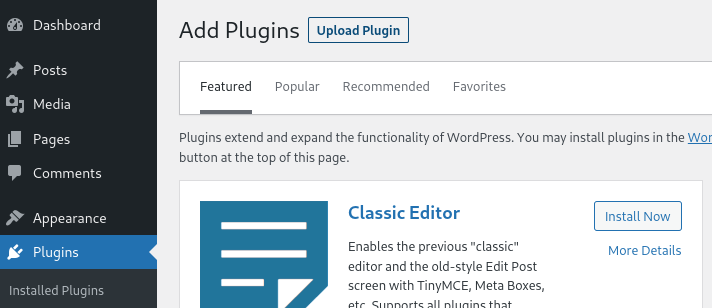
    1. To install the Perfmatters plugin, open your WordPress dashboard and navigate to the “Plugins” tab. Click on the “Upload Plugin” button and select the ZIP archive you received after completing your purchase.
    How to install perfmatters
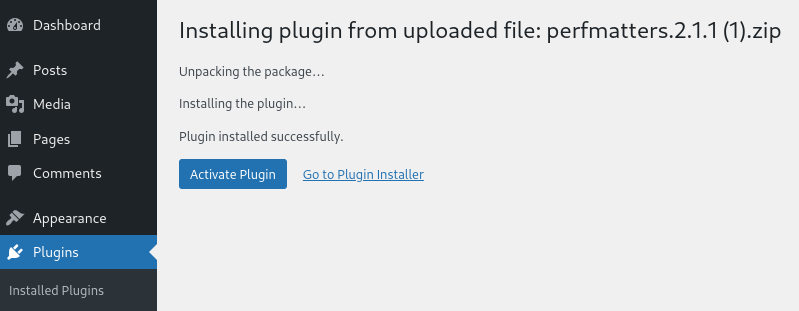
    1. After the Installation is complete, click on “Activate Plugin” to start using it on your site.
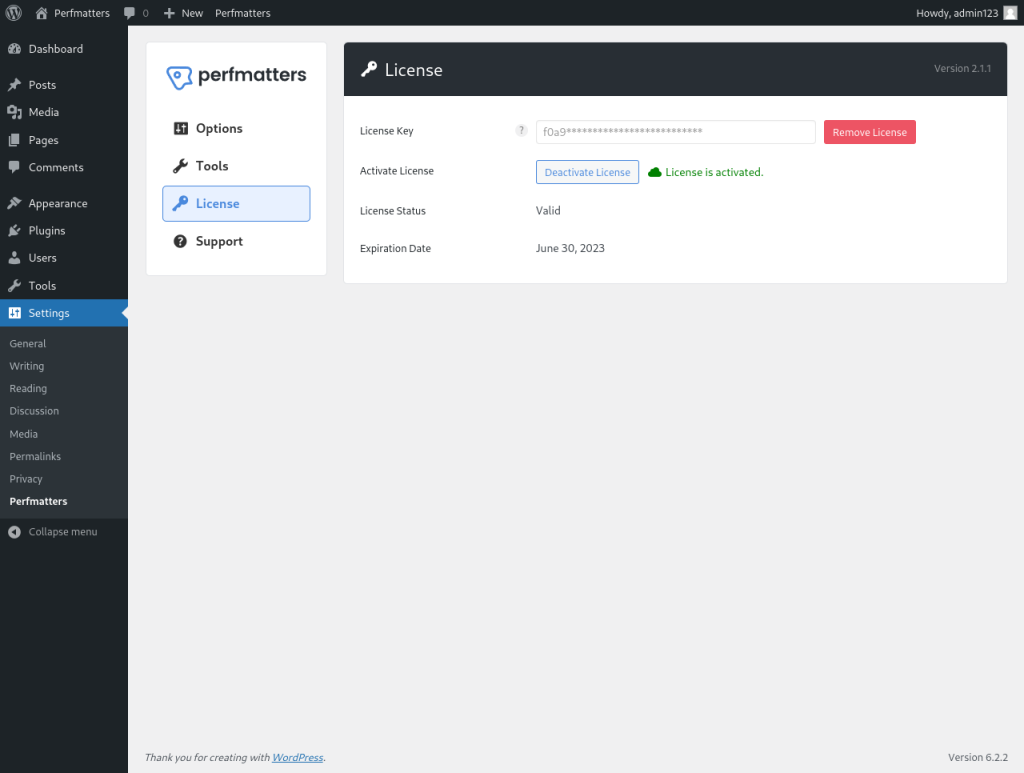
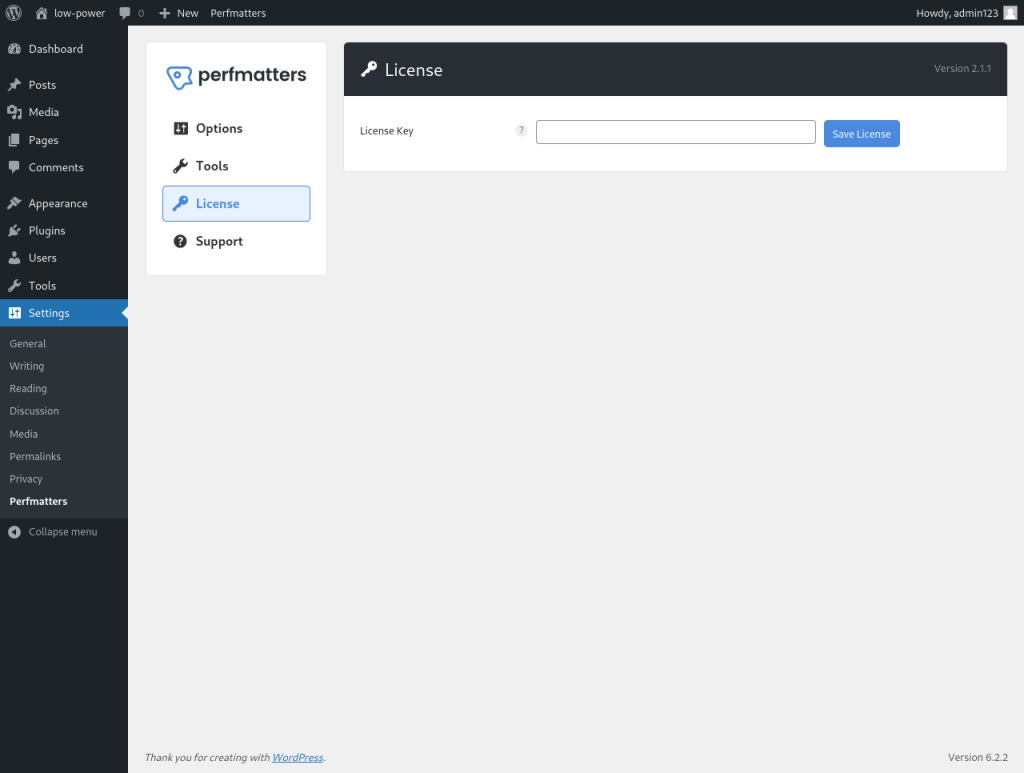
    1. Once you have enabled the plugin, go to plugin settings and switch to the “License” tab. Enter your License key to activate all the features of the plugin.
    Perfmatters admin dashboard
    1. Once you have entered the key, you will see a message that says “License is activated” – along with the validity of your license.

    That’s it! You have successfully installed the Perfmatters plugin on your site.

    Perfmatters Basic Configuration

    Perfmatters offers many features to help you optimize your site’s performance. However, it doesn’t enable any optimization features by default. You will have to manually toggle the switch for each feature and test your site for any issues. If you notice any problem, you can simply turn off the feature and try another one.

    If you encounter a problem immediately after enabling a feature, it means your site is using that feature, so leave it alone. Here is a list of some of the important settings that you should definitely check out:

    • Script Manager: This feature lets you control which scripts load on each page or post on your site. You can turn scripts off or on that are either not needed or cause conflicts. You can also change how the scripts load, such as in the header or footer, asynchronously or deferentially, to improve your site’s speed and compatibility.
    • Lazy Loading: This feature delays the loading of images, videos, iframes, and other elements until they are visible on the screen. This reduces the initial page load time and saves bandwidth. You can also enable DOM monitoring, which detects new elements added to the page and automatically applies lazy loading to them.
    • DNS Prefetch: This feature resolves the domain names of external resources, such as images, fonts, scripts, etc., before they are requested by the browser. This reduces latency and improves your site’s loading speed. You can also manually add custom domains to prefetch.
    • Preconnect: This is an extension of the DNS Prefetch feature. In addition to resolving domain names, it establishes early connections to external domains before the browser requests them. This reduces the round-trip time and improves your site’s loading speed. You can also manually add custom domains to preconnect.
    • Heartbeat Control: This feature controls the frequency of the WordPress heartbeat API, which sends requests to the server every few seconds. These requests can consume server resources and slow down your site. You can reduce or disable the heartbeat to save resources and improve your site’s speed. You can also choose which areas of your site to apply heartbeat control to, such as the dashboard, front end, and post editor.
    • jQuery Migrate: This feature disables jQuery Migrate, which is a script that helps older plugins and themes work with newer versions of jQuery. However, this script can slow down your site and cause errors. You can disable it if you’re sure that your site doesn’t need it.
    • Disable Emojis: This feature disables emojis, which are small icons that express emotions. However, these icons can add extra requests and slow down your site. You can disable them if you don’t use them on your site.
    • Remove the wlwmanifest Link: This feature removes the wlwmanifest link, which Windows Live Writer uses to work with WordPress. However, this link can expose your site’s information and slow it down. You can remove it if you don’t use Windows Live Writer on your site.
    • Disable Comments: This feature disables comments on your site, which can reduce spam and improve your site’s performance. You can disable comments globally or on specific post types. You can also remove comment-related scripts and styles from your site.
    • Local Google Fonts: This feature hosts Google Fonts locally on your server instead of loading them from Google’s servers. This reduces external requests and improves your site’s speed and compatibility. You can also choose how to display the fonts (swap or block) and disable Google Fonts completely if you don’t use them on your site.
    • Local Analytics: This feature hosts Google Analytics locally on your server instead of loading it from Google’s servers. This reduces external requests and improves your site’s speed and privacy. You can also choose how often to update the analytics script and exclude certain roles from tracking.

    Perfmatters vs. Alternatives: Choosing the Right Performance Stack

    Deciding between Perfmatters, WP Rocket, or FlyingPress? While all three provide WordPress performance optimization, they function differently. The following comparison shows their strengths to help you pick the right tool for your specific setup.

    Feature / CategoryPerfmattersFlyingPressWP Rocket
    Primary FocusAsset optimization and granular script management.All-in-one caching with aggressive asset optimization.Page caching with reliable, automated optimization.
    Page CachingNo (Relies on your server or another caching plugin).Yes (Generates static HTML pages).Yes (Industry standard for static HTML caching).
    Manual Script ManagerBest-in-class (Unmatched control to disable scripts per page/post).No (Automates optimization but lacks manual asset toggles).No (Relies on broad automation across the whole site).
    Unused CSS HandlingYes (Loads optimized CSS efficiently in a separate external file).Yes (Highly aggressive and effective at removing unused CSS).Yes (Automated, but loads the CSS inline, which can increase HTML size).
    JavaScript OptimizationYes (Highly customizable manual control over delaying/deferring).Yes (Aggressive automated delay based on user interaction).Yes (Basic, reliable automated delay and deferral).
    Image OptimizationBasic (Handles lazy loading and preloading, but no compression).Comprehensive (Lazy loading, plus AVIF/WebP generation via add-on).Basic (Handles lazy loading, but requires a separate plugin for compression).
    Ease of UseSteep Learning Curve (Requires technical tweaking and testing to avoid breaking the site).Moderate (Requires some careful configuration for its most aggressive settings).Very Easy (“Set-and-forget” with safe, automated defaults).
    The Best Use CaseThe ultimate “scalpel” to pair with a dedicated caching plugin or server cache.A powerful standalone solution for users who want maximum automated speed.A rock-solid standalone solution for users who prioritize stability and ease of use.
    Ideal SynergyPairs perfectly with WP Rocket or RunCloud server caching.Use alone, or pair with Perfmatters to manually kill stubborn scripts.Use for caching, and pair with Perfmatters for advanced script control.

    Final Thoughts

    Perfmatters is a powerful and versatile plugin that helps you optimize your WordPress site’s performance and speed. It has many features that let you disable unnecessary features and scripts, tweak settings and options, clean up your database, use a CDN, host analytics locally, and more.

    If you’re looking for a plugin that can make your site faster, more responsive, and more user-friendly, then Perfmatters is a great choice for you.

    If you’re tired of managing your own servers, you might want to check out RunCloud (yep, that’s us!).

    RunCloud is built for developers who want to focus on shipping great work, not on managing their infrastructure. Experience painless server configuration, with no need to spend hours figuring it out.

    Get started with RunCloud today & get up and running in minutes. 

    Frequently Asked Questions

    Is Perfmatters a caching plugin?

    No, Perfmatters is not a caching plugin. It’s a performance optimization and script management plugin. It is designed to work alongside your existing caching solution (like WP Rocket or server-level caching) to remove bloat and reduce page weight.

    Perfmatters vs WP Rocket: which is better?

    They serve different purposes. WP Rocket is an all-in-one caching plugin, while Perfmatters specializes in asset management and removing unused code. For the best results, they should be used together.

    Does Perfmatters work with WooCommerce?

    Yes, Perfmatters is highly recommended for WooCommerce. WooCommerce loads cart and checkout scripts on every page by default. Perfmatters allows you to disable these scripts on your blog posts and homepage, significantly speeding up your site.

    Is Perfmatters worth it?

    Yes. If you’re struggling with Core Web Vitals, specifically INP or LCP, Perfmatters offers the granular control needed to fix those issues. For $29.95/year, it provides incredible value.

    What is the Perfmatters Script Manager?

    The Script Manager is a tool within Perfmatters that shows you every CSS and JavaScript file loading on a specific page. It allows you to toggle those files off individually, preventing unused code from slowing down your site.

    Does Perfmatters have a free version?

    No, Perfmatters does not have a free version or a trial. It is a premium-only plugin, but it does offer a 30-day money-back guarantee.

  • n8n vs Zapier vs Make: Which Automation Tool Is Right for You?

    n8n vs Zapier vs Make: Which Automation Tool Is Right for You?

    Automation platforms often look inexpensive until your workflows start running at scale.

    A process that captures a lead, checks a CRM, cleans the data, sends a notification, and updates another system may consume several billable tasks or credits every time it runs. Multiply that by thousands of executions, and a modest monthly subscription can quickly become a major operating cost.

    That makes the choice between n8n vs. Zapier and n8n vs. Make more than a question of which workflow builder has the easiest interface. You also need to compare how each platform charges for usage, how much control it gives your developers, and where your business data is processed.

    This guide breaks down n8n pricing alongside the task-based pricing used by Zapier and the credit-based model used by Make. It also examines n8n self-hosted pricing, including the server, storage, maintenance, and management costs that are often missed when calculating the full n8n self-hosting cost.

    You will learn:

    • How n8n, Zapier, and Make calculate workflow usage
    • What each platform may cost as your automation volume grows
    • When self-hosted automation offers better control and more predictable costs
    • What running n8n on your own server requires
    • How RunCloud can reduce the server administration involved in hosting n8n

    By the end, you should have a clearer view of whether Zapier, Make, n8n Cloud, or a self-hosted n8n deployment is the right fit for your workload, technical resources, and budget.

    Comparing n8n vs. Zapier vs. Make

    Choosing between n8n, Zapier, and Make requires analyzing three things: long-term pricing structures, processing flexibility, and data security. In this section, we will compare how these three platforms handle real-world operational demands.

    Comparing Costs at Scale

    Each platform uses a completely different mechanism to calculate your monthly usage invoice.

    • Zapier bills by Tasks (every successful action step in a workflow consumes a task).
    • Make bills by Credits (every module action, such as fetching data, routing, or updating a record, consumes one credit). For Make’s “Make Code App”, there is a resource cost of 2 credits per second of code execution.
    • n8n bills by Executions (one complete workflow run from trigger to final step equals one execution, regardless of complexity).

    To illustrate how these billing philosophies affect your budget, consider a common business scenario: processing 10,000 leads per month using a standard 7-step automation process.

    The Scenario: 7-Step Lead Enrichment Workflow

    1. Trigger: Webhook captures a new lead.
    2. Action 1: Searches a CRM database to check for an existing record.
    3. Action 2: Filters and routes the lead based on geographic location.
    4. Action 3: Formats and cleans the name and email address.
    5. Action 4: Updates the CRM contact record.
    6. Action 5: Sends an internal Slack notification to the sales team.
    7. Action 6: Sends an automated introductory email to the prospect.

    The Monthly Cost Breakdown

    • Zapier: Because Webhook triggers don’t consume tasks, the remaining 6 actions count as tasks. Running this 10,000 times a month consumes 60,000 tasks. To accommodate this volume on Zapier’s Professional plan, you must scale your task tier, which will result in an estimated subscription cost of $300-$400 per month.
    • Make: Most actions consume 1 credit, while some advanced features use more credits. Running this 10,000 times will consume at least 70,000 credits, but it can vary widely and could easily reach 200,000. This could cost you $110 to $315 per month.
    • n8n Cloud: Because n8n bills purely per workflow execution, running this 7-step pipeline 10,000 times consumes exactly 10,000 executions. This is included in the n8n Pro plan, which costs 50€ per month (billed annually).
    • n8n Self-Hosted: Running this workflow incurs no software licensing fees and only the cost of your underlying server infrastructure (typically $10-$20 per month for a standard cloud VPS).

    Note: Pricing checked in June 2026. Actual costs depend on the selected plan, billing cycle, workflow configuration, feature usage, overage charges, and applicable taxes. Check each provider’s current pricing before making a purchasing decision.

    n8n vs zapier comparison

    Comparing Flexibility & Custom Code

    When workflows require custom business logic, the platforms differ in how they handle developer integrations.

    • n8n: Was built with a developer-first mindset. n8n natively integrates JavaScript and Python code blocks across all deployment tiers. These code blocks run directly within the execution path, allowing complex array transformations, data parsing, and custom cryptography without incurring additional billing penalties.
    • Zapier: Scripting is limited to basic “Code by Zapier” blocks. These steps are subject to strict run-time limits and memory allocations, and they consume standard task quotas, making heavy data manipulation costly.
    • Make: Make’s greatest strength is its highly visual drag-and-drop routing and filtering interface, which allows non-technical users to easily build logical branches. For advanced logic, Make provides a “Make Code App” functionality; however, this incurs a 2-credit cost per 1 second of code execution, so complex scripts can rapidly drain your monthly credit pool.

    Comparing Data Sovereignty & Security

    If your organization operates in highly regulated fields such as healthcare (HIPAA), finance (PCI-DSS), or legal services, where customer data is highly sensitive, how data is handled is just as important as the cost.

    • Zapier and Make: Both are primarily managed cloud platforms. Workflow data is processed through infrastructure controlled by the provider, although the available security, data residency, and enterprise controls vary by platform and plan. Organizations handling regulated or sensitive data should assess those controls against their own legal, contractual, and compliance requirements.
    • n8n Self-Hosted: With n8n Community Edition, you can run the platform on infrastructure you control. This gives you greater control over workflow data, credentials, execution logs, storage locations, and retention policies. You remain responsible for securing the server and configuring the deployment to meet your compliance requirements.

    The True Cost of Self-Hosting n8n

    The appeal of self-hosted automation is undeniable, particularly given n8n’s self-hosted pricing. By choosing to host n8n on your own infrastructure, you can bypass the execution limits associated with SaaS cloud plans and maintain complete control over your data.

    However, understanding the total n8n pricing self-hosting cost is essential, as running your own automation stack is rarely a “zero-cost” endeavor. While the n8n Community Edition has no software license fee, your overall n8n pricing will still need to account for hardware, database management, and maintenance.

    Infrastructure and Server Costs

    To run n8n reliably in production, you need to provision a VPS from a cloud infrastructure provider. While n8n can technically run on very minimal resources, a production environment, especially one running a separate PostgreSQL database for execution logs, requires adequate RAM and CPU to prevent bottlenecks during concurrent executions.

    Here is a breakdown of typical VPS options suitable for hosting n8n in 2026:

    ProviderEntry-Level Tier (Light Testing)Production-Ready Tier (Recommended)Estimated Monthly Cost
    Hetzner Cloud1 vCPU, 2 GB RAM, 20 GB SSD2 vCPUs, 4 GB RAM, 40 GB SSD€4.00 – €8.00 / month
    DigitalOcean1 vCPU, 1 GB RAM, 25 GB SSD2 vCPUs, 2 GB RAM, 50 GB SSD$6.00 – $12.00 / month
    Vultr1 vCPU, 1 GB RAM, 25 GB SSD2 vCPUs, 2 GB RAM, 55 GB SSD$5.00 – $12.00 / month
    AWS Lightsail1 vCPU, 1 GB RAM, 40 GB SSD2 vCPUs, 2 GB RAM, 60 GB SSD$7.00 – $15.00 / month

    When calculating your hardware budget, keep in mind that n8n stores execution data by default. Every step of every workflow run writes data to your database. If you process thousands of executions daily, a standard 25 GB SSD can fill up within weeks, potentially freezing the server.

    To maintain system stability, self-hosted administrators must budget for either:

    • Sufficient SSD block storage (an extra $5 to $10/month).
    • Correctly configured execution pruning rules (e.g., setting n8n environment variables to delete execution data older than 7 days).

    In addition to the above costs, you should also budget for hardware and storage to back up your data to a separate location or a storage device.

    RunCloud server creation

    Additional Operational Overhead for Hosting n8n

    When evaluating your overall n8n pricing self-hosting cost, the time spent on server administration is often the most significant expense to include in your n8n pricing calculations. 

    1. Server Provisioning and Security Setup

    Setting up a VPS is only the first step. To make n8n usable, you must secure the server. This might require configuring a firewall (such as UFW), setting up a reverse proxy (such as NGINX, Traefik, or Caddy) to direct traffic, and closing unnecessary open ports to prevent unauthorized access to your workflow canvas.

    2. Configuring SSL Certificates

    To trigger webhooks and connect securely to external APIs, your n8n instance must run over HTTPS. This requires installing SSL certificates. While Let’s Encrypt certificates are free, configuring them to renew automatically without disrupting your reverse proxy configuration requires ongoing maintenance.

    3. Managing Updates and Preventing Downtime

    n8n is being actively developed, which is both a blessing and a curse. You will get access to new features, but you will also need to upgrade frequently to receive the latest security patches, bug fixes, and new integration nodes.

    If an update fails due to a database conflict or an incompatible custom code block, your entire automation pipeline goes offline. Without deep Linux command-line expertise, troubleshooting these failures and restoring backups can result in hours of costly business downtime.

    Managing Self-Hosted n8n Without the System Admin Headache

    For many organizations, the long-term financial math of self-hosted automation is highly compelling. However, the primary barrier to entry is what is often called the “sysadmin tax.” If your team lacks dedicated DevOps resources or deep Linux command-line expertise, the prospect of managing SSH keys, writing reverse proxy rules, and manually maintaining database performance can feel like a steep price to pay.

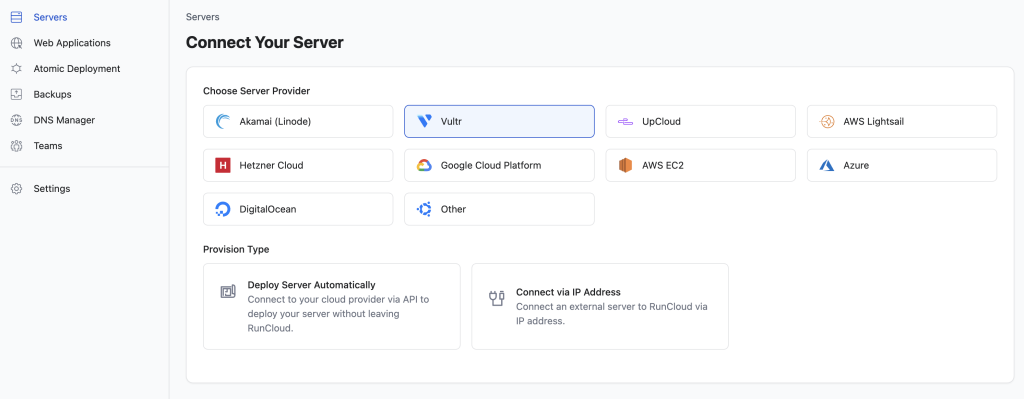
    Fortunately, there is a balanced approach that separates raw cloud infrastructure from complex server administration. By pairing a standard, cost-effective cloud server (such as Vultr, DigitalOcean, AWS, or Linode) with a centralized server management panel like RunCloud, you can establish a self-hosting environment without the technical friction of manual server setup.

    How RunCloud Simplifies Self-Hosted Server Management

    Rather than forcing you to interact with a terminal or build complex server stacks from scratch, RunCloud provides a visual control panel for your cloud servers. This helps manage the operational realities of running self-hosted applications:

    • Less Routine Command-Line Management: RunCloud provides a visual dashboard for many recurring server management tasks, including monitoring, database administration, SSL management, backups, and application configuration. Deploying and troubleshooting a self-hosted n8n instance may still require familiarity with Docker, NGINX, configuration files, or the command line. 
    • Automated SSL and Core Security: Secure communication is mandatory for any automation workflow that relies on external webhooks. RunCloud automates the deployment and renewal of Let’s Encrypt SSL certificates with a single click. It also handles server-level firewall configuration and automatically applies security patches, keeping your environment protected against vulnerabilities.
    • Centralized Multi-Server Control: If your team uses other self-hosted utilities alongside n8n, such as an independent PostgreSQL database server, a staging instance, or auxiliary microservices, you can manage and monitor them all from a single dashboard. This consolidated view gives you full visibility into your server’s resource usage (CPU, RAM, and disk storage) so you can scale your hardware as your workload grows.
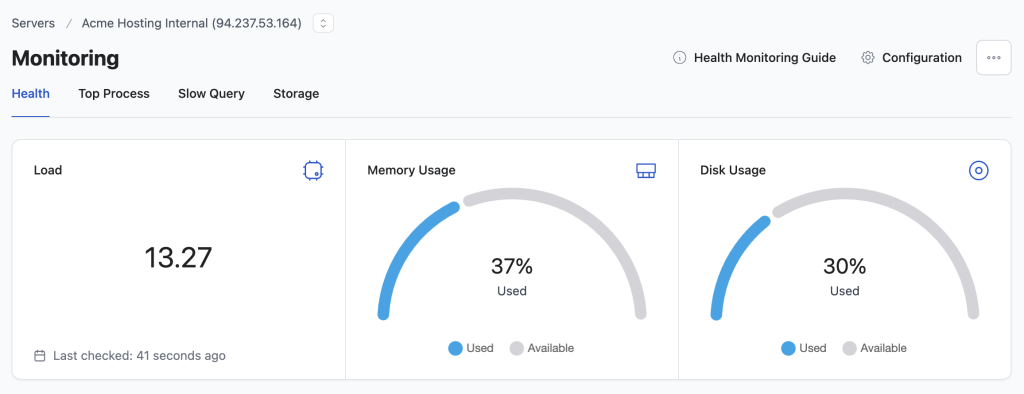
    RunCloud monitoring panel

    This hybrid approach gives you the ultimate benefit of self-hosting: you can avoid cloud plan execution allowances and scale the deployment by adding appropriate server, database, and worker capacity. Your practical limits depend on the infrastructure, workflow design, external services, and n8n edition you use. 

    Final Thoughts

    Selecting the right platform for your workload is more than just picking the cheapest option. You also need to factor in your team’s technical, application, and data security capabilities, as well as your data security requirements. 

    Use the following framework to determine which option fits your business needs.

    When to Choose Zapier

    Best for: Teams with limited developer resources that require specialized, niche integrations and have the budget to support usage fees for scaling.

    • No Developer Overhead: You can build and deploy workflows without understanding APIs, JSON, or code.
    • Massive Integration Library: Access to over 9,000 apps means even highly obscure third-party tools are likely supported natively.
    • The Trade-off: As your workflow volume grows, the “per-task” billing model can quickly lead to high monthly expenses.

    When to Choose Make

    Best for: visual builders who need advanced multi-branch logic and medium-scale automation without managing any software infrastructure.

    • Visual Logic Mapping: The circular “bubble” interface makes it easy to visualize complex, multi-route databases and workflows.
    • Cost-Efficient SaaS: It is generally more affordable than Zapier for moderate volumes, though it is still subject to monthly “operation” quotas.
    • The Trade-off: Like Zapier, you are entirely dependent on their cloud infrastructure, and you cannot keep sensitive operational data entirely inside your own network.

    When to Choose n8n

    Best for: Technical teams, SaaS startups, agencies processing high volumes of data, and privacy-conscious enterprises.

    • Execution-Based & Self-Hosted Pricing: Paying per complete execution (on n8n Cloud) or self-hosting for $0 in licensing fees makes it the most scalable financial choice.
    • Developer-First Flexibility: Native JavaScript/Python nodes, AI agent features, and custom HTTP request capabilities give developers granular control over data.
    • Data Sovereignty: Running n8n on your own servers ensures sensitive customer data never leaves your infrastructure.

    Run n8n on Your Own Server Without Managing Everything Manually 

    Zapier and Make may suit teams that want a fully hosted platform and do not expect workflow costs to rise sharply with usage.

    For technical teams running larger workloads, self-hosting n8n can provide more control over data, infrastructure, and long-term costs. The trade-off is that someone still needs to configure, secure, monitor, and maintain the server.

    RunCloud helps remove much of that server management work.

    You can connect a cloud server from providers such as DigitalOcean, Vultr, AWS, or Linode, then manage key server tasks through the RunCloud dashboard. This includes SSL certificates, firewall settings, backups, server monitoring, database management, and security updates.

    You retain the cost and control benefits of self-hosted automation without having to manage every part of the server through the command line.

    Start managing your self-hosted n8n server with RunCloud.

    Frequently Asked Questions

    Is n8n really free to self-host?

    Yes. The standard self-hosted version of n8n is source-available under a “fair-code” license (the n8n Community Edition) and can be downloaded from GitHub at no cost. The Community Edition does not charge per workflow execution. The number of workflows and executions your instance can handle depends on its infrastructure, configuration, workload, and external service limits. While the software license is free, you will still need to pay for the underlying virtual private server (VPS) on which the software runs.

    What is the true n8n pricing for self-hosting?

    For a reliable production environment, your self-hosting cost generally consists of two parts:
    The Cloud VPS: A virtual server from providers like Vultr, DigitalOcean, or Hetzner typically costs $5 to $20 per month, depending on your memory and CPU requirements.
    The Server Management Panel: Using a management platform like RunCloud to handle your server administration costs a predictable flat monthly fee.
    Even when combining these two costs, the total monthly expense is usually a fraction of the price of mid-tier SaaS plans from Zapier or Make, especially if you are processing tens of thousands of executions.

    How do I secure my self-hosted n8n instance and configure SSL?

    Since n8n relies on webhooks to trigger workflows, your instance must run over a secure HTTPS connection. With RunCloud, security configuration is automated, and you can deploy and renew free Let’s Encrypt SSL certificates with a single click inside the dashboard.

    When does it make sense to transition from n8n Cloud to a self-hosted instance?

    If your workflow volume is low (under 2,500 executions per month), n8n’s Cloud Starter plan (20€/month) is highly convenient. However, if your business operations scale to tens of thousands of monthly executions, or if you need to run resource-heavy custom Python/JavaScript scripts, transitioning to a self-hosted server managed by RunCloud allows you to scale your execution volume without hitting subscription caps or facing unexpected price jumps.

  • How to Use Edge Caching to Speed Up WordPress Worldwide

    How to Use Edge Caching to Speed Up WordPress Worldwide

    Is your WordPress website loading quickly for local users, but frustratingly slow for visitors on the other side of the world?

    In modern SEO, website speed is a key ranking factor. If your site takes too long to load, frustrated visitors will simply leave, costing you both traffic and sales. 

    In this beginner-friendly guide, we will break down exactly what edge caching means and why it drastically lowers your Time to First Byte (and what that is!).

    You’ll learn how modern Content Delivery Networks cache full HTML pages and how to do it safely without breaking dynamic pages like WooCommerce.

    Why Edge Caching Speeds Up WordPress 

    If your main WordPress hosting server is located in New York, a visitor from London will naturally experience a slower loading time than a visitor from Brooklyn. This happens because data has to physically travel across the ocean.

    Edge caching solves this distance problem by ensuring your website loads instantly for everyone, no matter where they live.

    What Edge Caching Means for WordPress

    To understand edge caching, think of a massive central warehouse (your web host) and dozens of small, local retail stores (the “edge” servers).

    Normally, whenever a user visits your website, their browser must request the website files directly from your main web host. Edge caching changes this by saving a copy of your WordPress site on a global network of servers (a Content Delivery Network, or CDN). 

    When someone visits your website, the server closest to them (the “edge”) serves it. Because the data travels a much shorter distance, your website appears on their screen in the blink of an eye.

    Suggested read: NGINX Caching for WordPress – Complete Guide & Tutorial

    How Caching HTML at the Edge Cuts TTFB for Global Visitors

    TTFB stands for Time to First Byte. It’s a metric that measures exactly how long it takes a user’s browser to receive the very first data from your website. A lower TTFB means a faster website.

    In the past, CDNs only saved “static” files like images or fonts. Your main server still had to do the heavy lifting of building the actual web page (the HTML) for every single visitor. Today, modern edge caching stores the entire, fully built HTML page directly on edge servers.

    Here is why caching HTML is a game-changer for your SEO and speed:

    • Zero Database Queries: WordPress doesn’t have to waste time searching its database to build the page.
    • No PHP Processing: The server doesn’t have to run complex code. It just hands the pre-built page to the visitor.
    • Instant Delivery: Because the fully built page is waiting right next door to the user, your TTFB drops from over a second to just milliseconds.

    Suggested read: How To Use Redis Object Cache To Speed Up A Dynamic WordPress Site

    When Edge Caching Will Not Help

    While edge caching is incredibly powerful, it’s not a magic fix for everything. Because edge caching is designed to serve static copies of pages to the public, it automatically turns off in a few specific situations.

    Edge caching will not speed up your site in these scenarios:

    • Logged-In Traffic: If a user is logged in to your site (e.g., a member or WordPress administrator), they need to see personalized, live content. The edge cache is bypassed, so they don’t see an old, cached version of the dashboard.
    • Uncached Dynamic Pages: E-commerce pages, such as WooCommerce Shopping Cart or Checkout pages, cannot be cached. If they were, shoppers might see other people’s items! 
    • A Slow Backend Server: Edge caching hides a slow server from your public readers. However, anytime a visitor needs to do something dynamic (like submit a contact form, use a search bar, or process a payment), the request must go back to your original WordPress host. If your hosting provider is slow or your database is bloated, these actions will still feel slow.

    Suggested read: How To Use Redis Full-Page Caching To Speed Up WordPress

    How to Implement Edge Caching for WordPress

    Configuring edge caching for WordPress might sound highly technical, but the steps are quite simple. Here is the exact step-by-step process for implementing edge caching in WordPress.

    Step 1: Pick your edge caching approach 

    Before changing any settings, you must decide how you want your CDN to interact with your WordPress host. There are two primary approaches:

    • Origin Page Cache + CDN (Traditional Method): Your WordPress server (the origin) generates and caches the HTML page locally. The CDN is used only to deliver static assets such as images, CSS, and JavaScript. While this is easy to set up, global visitors still have to wait for the HTML document to travel from your main server, keeping your Time to First Byte (TTFB) higher than ideal.
    • CDN HTML Cache (Full Page Edge Caching): The CDN stores a complete copy of the HTML document on its global edge servers. This is the preferred method for maximum speed worldwide. When a user requests a page, the edge server delivers the HTML instantly without ever contacting your WordPress host.
    • RunCache (All-in-one): For most users, Cloudflare Automatic Platform Optimization is the gold standard for CDN HTML caching. Cloudflare’s data shows that APO can improve TTFB by up to 72% globally. To get the absolute best results, we highly recommend using the RunCache Cloudflare Integration.

    This integration seamlessly bridges your local WordPress cache with Cloudflare’s global edge network. It also ensures that whenever you update a post or change a product, the edge cache is purged and rebuilt instantly, giving you blazing-fast global speeds without the headache of showing outdated content.

    Step 2: Enable Edge Caching on WordPress

    For this tutorial, we will be using RunCache with Cloudflare’s global CDN to serve your entire website from edge locations closer to your visitors. Follow these steps to generate a secure API token and connect your site.

    Step 2.1: Generate a Custom Cloudflare API Token

    To maintain high security, we recommend creating a “Custom Token” with limited permissions rather than using your Global API Key.

    1. Log in to your Cloudflare Dashboard.
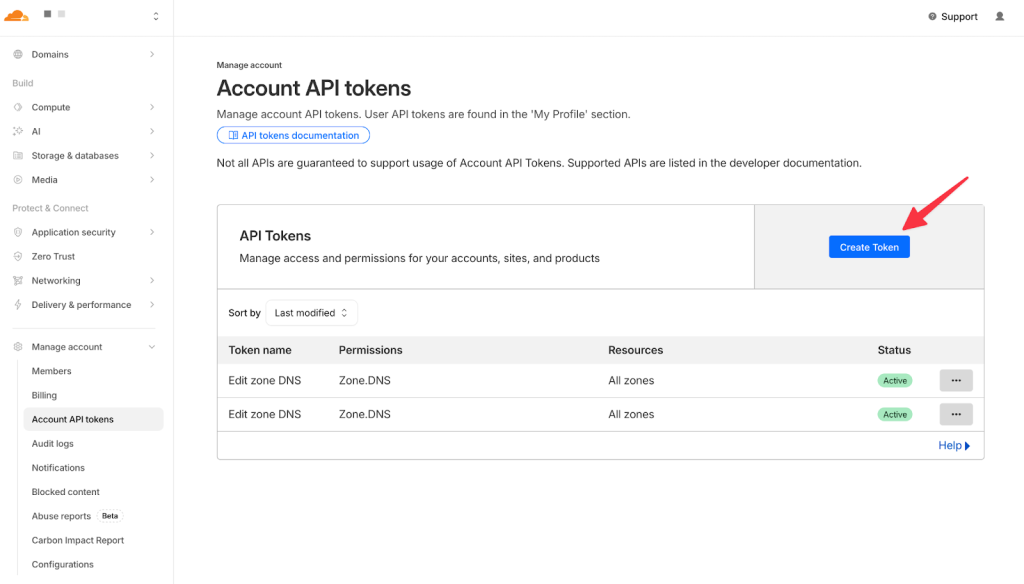
    2. In the left menu, click on Manage Account and select Account API tokens.
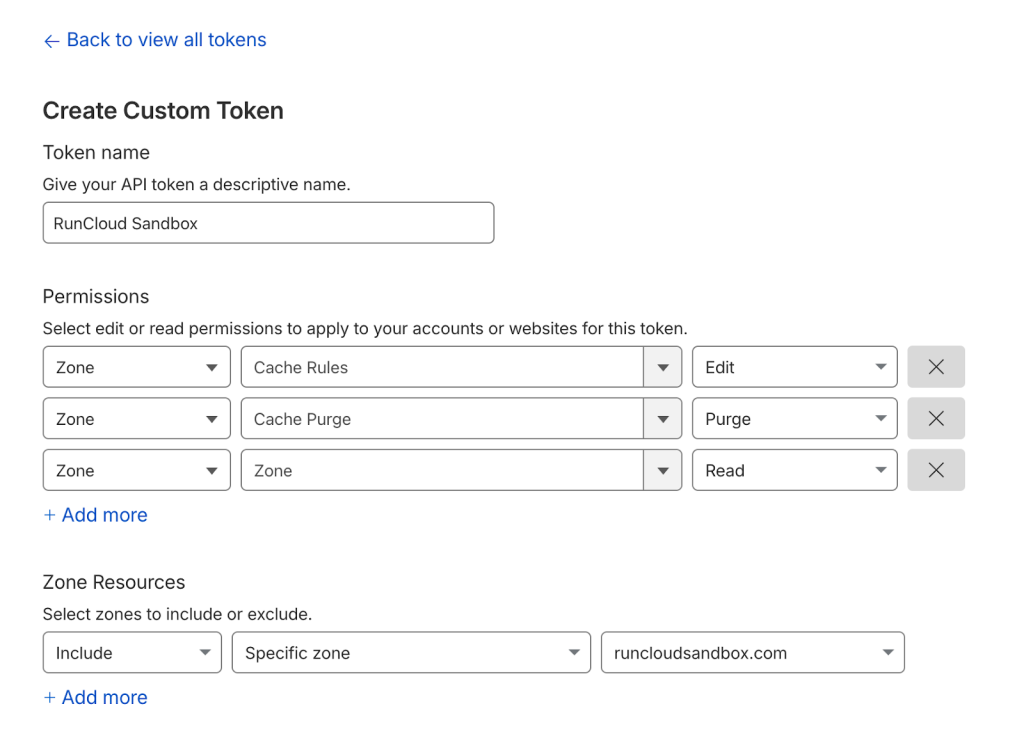
    1. Click Create Token, then locate Create Custom Token at the bottom and click Get Started.
    2. Token Name: Enter a name like RunCache – [Your Site Name].
    3. Permissions: Add the following three permissions:
      • Zone: Cache Rules: Edit
      • Zone: Cache Purge: Purge
      • Zone: Zone: Read
    1. Zone Resources: Under “Include,” select Specific zone and choose the domain you are currently configuring.
    2. Click Continue to Summary, then Create Token.
    3. After creating the token, copy it immediately and store it in a safe place – Cloudflare will not show it to you again.

    Step 2.2: Ensure Your Domain is Proxied

    Cloudflare caching only works if your traffic is flowing through their network.

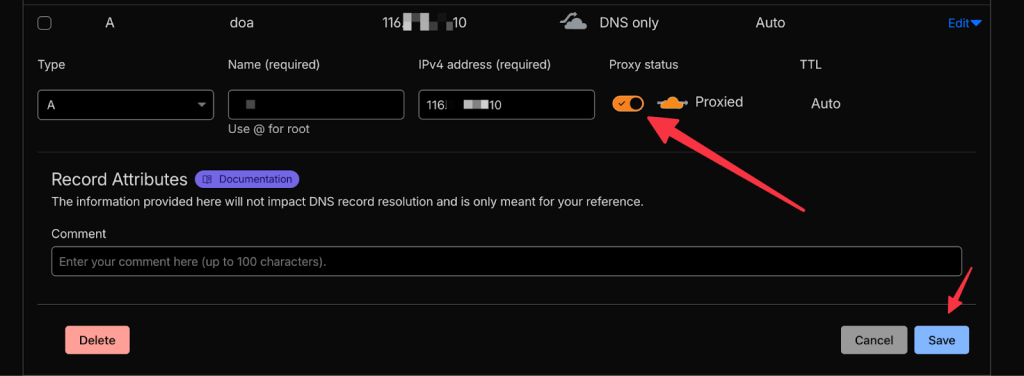
    1. In your Cloudflare Dashboard, go to the DNS tab for your domain.
    2. Locate your A or CNAME records (usually for your root domain and the www subdomain).
    3. Ensure the Proxy status toggle is set to Proxied (the cloud icon should be Orange). If it is “DNS Only” (Grey), Cloudflare’s cache will not be active.

    Step 2.3: Enable Cloudflare in the RunCache Plugin

    Now that you have your token and your DNS is ready, connect the plugin to Cloudflare.

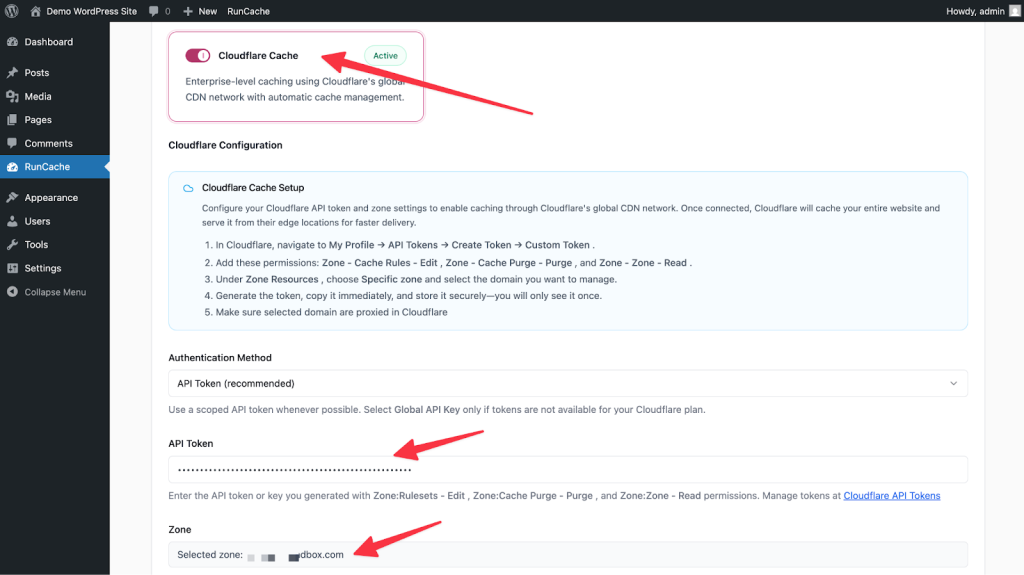
    1. Log in to your WordPress Admin Dashboard.
    2. Navigate to RunCache in the sidebar and click on the Full Page Cache tab.
    3. Enable Cloudflare from the list of cache providers.
    4. Paste your newly created token into the API Token field.
    5. Click Save Settings.
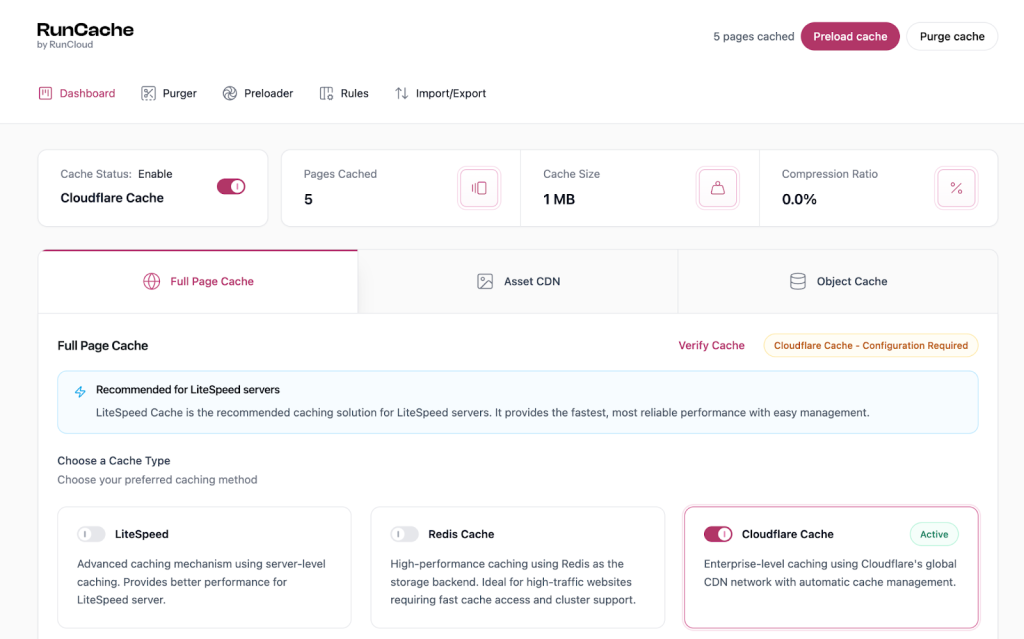
    enable cloudflare edge caching wordpress

    Once connected, RunCache will automatically communicate with Cloudflare to manage your cache, purge outdated content when you update posts, and ensure your visitors receive the fastest possible delivery via the Cloudflare edge network.

    Suggested read: Scaling RAM & CPU Cores – How They Affect WordPress Performance

    Step 2: Set the right cache headers for HTML and assets 

    Note: if you are using RunCache, all HTTP headers are handled intelligently by RunCache, and you don’t need to configure them manually.

    CDNs don’t just guess what to cache – they follow strict instructions sent by your server, called HTTP Headers. To make edge caching work perfectly, you need to configure the following directives in Cache-Control headers correctly:

    • max-age: This tells the visitor’s local web browser how long to store the file. For edge-cached HTML, you usually want this set to a low value (e.g., max-age=3600) so browsers always request the latest version from the CDN.
    • s-maxage (Shared Max-Age): The “s” stands for shared cache (your CDN). This tells the edge server how long to hold onto the HTML file. A good rule for WordPress posts is s-maxage=604800 (7 days).
    • stale-while-revalidate: If an edge-cached page expires after 7 days, this directive tells the CDN to immediately serve the “stale” (expired) page to subsequent visitors so they don’t have to wait. In the background, the CDN quietly fetches the latest version from your WordPress server for future visitors. Setting stale-while-revalidate=86400 (24 hours) keeps your site feeling instantly fast 100% of the time.

    Suggested read: How to Easily Optimize Your WordPress Website With RunCloud Hub

    Step 3: Add bypass rules for logged-in users, WooCommerce, and dynamic cookies

    Note: if you are using RunCache, this step is handled automatically.

    The biggest risk of edge caching is caching private or dynamic information by accident. If an edge server caches a page while you are logged in, it might show your WordPress admin bar to regular visitors. To prevent this, you must set up Bypass Rules (also known as Cache Exclusions) in your CDN dashboard or via your caching plugin.

    If you’re using RunCache, you can manage these settings under the Rules tab.

    Important Bypass Rules for WordPress:

    1. Logged-in Users: Tell the CDN to completely bypass the cache if the browser contains the wordpress_logged_in_* cookie.
    2. WooCommerce Cookies: Exclude caching for any user carrying the woocommerce_items_in_cart or wp_woocommerce_session_* cookies. 
    3. Dynamic URLs: Force the CDN to bypass the cache for specific URL paths, including:
      • /wp-admin/*
      • /cart/
      • /checkout/
      • /my-account/

    By setting these rules, your public blog posts and landing pages will load from the edge instantly, while your secure, dynamic pages will safely load directly from your origin server.

    Suggested read: Understanding RunCache Purging Options in RunCloud Hub

    Step 4: Verify edge caching is working using response headers and DevTools

    Once you’ve configured your setup, you should test it to ensure the HTML is actually being served from the edge. You don’t need any fancy software to do this – just your web browser.

    1. Open your website in an Incognito/Private window (to ensure you aren’t logged in).
    2. Right-click on the page and select “Inspect” to open Developer Tools.
    3. Click the “Network” tab, then refresh the page (press F5).
    4. Then click the network request that you want to inspect.
    5. Look at the “Response Headers” section on the right side.
    6. In the response section, you need to look for the following response headers x-cache: HIT or x-runcache-status: HIT. If it says “MISS”, refresh the page one more time to prime the cache. Once it says “HIT”, your HTML is successfully loading from the edge.

    Suggested read: How To Host Multiple Websites On One Server | Ultimate Guide

    Wrapping Up 

    Edge caching is the best strategy for delivering a lightning-fast WordPress experience to visitors worldwide. However, maximizing these speed benefits requires careful management to avoid common pitfalls.

    Edge caching significantly reduces the daily workload on your origin server, but you still need a clean, conflict-free setup to keep your backend fast under heavy load. Running multiple overlapping caching layers often leads to messy system conflicts, which is why RunCloud built Runcache.

    Runcache is a modern WordPress caching plugin that consolidates all caches (local page cache, Redis object cache, and edge network) into one streamlined layer.

    And the best part is that RunCache works with any WordPress site on any host, not just those hosted on RunCloud.

    Start using RunCache to deliver faster global WordPress performance.

    FAQs

    What is edge caching in WordPress?

    Edge caching in WordPress stores a copy of your website on servers located very close to your visitors. These servers are part of a global Content Delivery Network (CDN) with hundreds of worldwide locations. When a user visits your site, the closest edge server delivers the content instead of your primary web host.

    Does edge caching cache HTML or only static files?

    Traditional CDNs only cache static files, such as images, CSS, and JavaScript. However, modern edge caching also caches your fully generated WordPress HTML pages. This advanced process is known as full-page edge caching.
    By caching HTML at the edge, your site can handle thousands of concurrent visitors without crashing. Only dynamic requests, such as form submissions, bypass the cache and reach your origin server.

    What WooCommerce pages should never be cached?

    You must never cache dynamic WooCommerce pages that contain personal user data. The three main pages to absolutely exclude from caching are the Cart, Checkout, and My Account pages. If you cache these pages, a customer might accidentally see another shopper’s private billing information. 

    Why do I still see old content after a purge?

    You usually see old content because of local browser caching. You can easily fix this by performing a hard refresh using Ctrl+F5 on Windows or Cmd+Shift+R on a Mac. Another common reason is multiple active caching layers. You might have cleared your CDN edge cache, but your WordPress caching plugin or server object cache still holds the old data. 

    Should I use edge caching with a WordPress caching plugin?

    Yes, you should absolutely use edge caching alongside a high-quality WordPress caching plugin. Edge caching excels at delivering your website files globally at lightning speeds. Meanwhile, a local caching plugin handles critical on-site performance optimizations.

  • Linux Server Hardening: 11 Steps to Secure a Production VPS

    Linux Server Hardening: 11 Steps to Secure a Production VPS

    Almost as soon as you deploy a server on the internet, it is under attack.

    Within seconds, automated bots begin scanning your ports and hammering your SSH login. If you’re using the default settings on your server, then you are more likely to get compromised.

    While most cloud providers offer a clean slate, those default configurations are built for convenience, not combat. To truly protect your data, you need to follow industry-standard Linux server security best practices.

    Through this guide, you will have a detailed roadmap to secure your VPS with enterprise-grade security. 

    Why a Fresh Linux VPS Is a Target for Hackers

    As soon as your cloud provider assigns a public IPv4 address to your server, the clock starts. Security researchers and malicious botnets continuously scan the entire IPv4 address space using tools such as Shodan, Censys, and Zmap.

    Honeypot data consistently shows that a new, exposed Linux server will experience its first automated SSH login attempt within 3 to 5 minutes of going live.

    If you leave default settings intact, it isn’t a matter of if you get breached, but when. If you don’t protect your server, an automated script will root your server, deploy a crypto-mining payload, and potentially leave you with a thousand-dollar cloud compute bill overnight.

    What Does the “Attack Surface” Mean?

    The “attack surface” is the exact combination of open ports, default configurations, and predictable patterns your server exposes to the internet. A fresh VPS usually has:

    • Port 22 open to the world: The universal beacon for SSH brute-force scripts.
    • Root login enabled: Giving attackers the ultimate username; they only need to guess the password.
    • Password authentication is enabled, allowing unlimited dictionary attacks against your login prompt.

    If you provision your servers through a control panel like RunCloud, much of this attack surface is already minimized for you. But if you are managing a bare-metal VPS yourself, run the commands below to manually lock it down.

    However, any one single measure won’t be enough to protect your server; that’s why we recommend following the “Swiss Cheese Model of Security”.

    Suggested read: 10 Security Tips to Secure VPS Server in 2025 [Ultimate Guide] 

    The Swiss Cheese Model of Security

    This model is built on the principle that security should never rely on a single control, as even the best defense has holes, or “slices” of weakness. 

    In this model, each layer of security (like disabling root login, configuring UFW, enabling Fail2Ban, etc.) is represented by a slice of Swiss cheese. Each slice has holes representing vulnerabilities, misconfigurations, or human error.

    • A single slice (one defense) is easily penetrated if an attacker’s exploit aligns with the hole in that single layer.
    • Multiple slices stacked together provide defense-in-depth. While the holes in the first slice (e.g., a custom SSH port) might align with the threat, the second slice (e.g., SSH key authentication) or the third slice (e.g., Fail2Ban) is highly unlikely to have a hole in the exact same spot.
    The Swiss Cheese Model of Security for Linux Server Hardening

    By stacking all 11 steps in this guide, we can ensure that even if one defense fails, the next layer (or the layer after that) will stop the threat, preventing it from reaching your core application.

    Suggested read: 5 Ways to Fix the SSH Connection Refused Error [SOLVED] 

    How to Harden a Linux Server

    Follow the steps below to protect your Linux server on the internet:

    Step 1: Disable Root Login and Create a Sudo User

    Performing regular maintenance activities on your server as the root user is dangerous – a single typo can destroy your system.

    To protect your system, we recommend creating an unprivileged user and granting it administrative rights via sudo.

    Connect to your VPS as root, then run:

    # Replace 'sysadmin' with your preferred username
    adduser sysadmin

    You will be prompted to set a password. Make it strong, even though we will disable password logins shortly. Skip the contact information prompts by hitting Enter.

    Next, add your new user to the sudo group so you can execute administrative commands:

    usermod -aG sudo sysadmin

    Verify it works before logging out. Switch to your new user and test sudo:

    su - sysadmin
    sudo ls -la /root

    If you are prompted for your password and can successfully see the contents of the root directory, your sudo user is ready.

    With RunCloud, you can manage users and permissions for your Linux server directly from the web dashboard, without SSHing into the server. 

    Step 2: Switch to SSH Key Authentication and Disable Password Login

    A secure password is hard to remember, and a weak password can be cracked immediately. That’s why all cybersecurity experts agree that cryptographic keys are a better replacement for your username/password based logins.

    In this step, we are going to replace password authentication with an ed25519 SSH key pair (which is faster and more secure than older RSA keys).

    Generate your key pair locally

    Do not run this on your VPS. Open a new terminal on your local computer (your Mac, Windows, or local Linux machine):

    ssh-keygen -t ed25519 -C "your_email@example.com"

    Hit Enter to save the key to the default location (~/.ssh/id_ed25519). When prompted, you can set a strong passphrase to encrypt the key on your local disk or leave it blank if you don’t want to encrypt it.

    Copy the public key and lock down the sshd_config

    Still on your local computer, copy the public key to your VPS, targeting your new sudo user:

    ssh-copy-id sysadmin@YOUR_VPS_IP

    Now, go back to the terminal window connected to your VPS. It’s time to edit the SSH daemon configuration to disable password logins and root access permanently.

    sudo nano /etc/ssh/sshd_config

    Find the following lines, uncomment them (remove the #), and change their values to match these exactly:

    PermitRootLogin no
    PasswordAuthentication no
    PubkeyAuthentication yes

    Save and exit (CTRL+O, Enter, CTRL+X). Do not restart the SSH service just yet; we are going to change the port in the next step.

    Note: RunCloud users can add SSH keys to their servers simply by pasting their public key into the RunCloud dashboard, no nano or config editing required.

    Step 3: Change the Default SSH Port

    Most automated scripts scan for and try to exploit port 22. Moving SSH to a non-standard high port (between 1024 and 65535) won’t stop a targeted attack, but it drops botnet noise by 99%, keeping your auth logs clean and saving CPU cycles.

    Open the SSH config file again:

    sudo nano /etc/ssh/sshd_config

    Find the line that says #Port 22. Uncomment it and change it to your desired port. For this example, we will use 52222:

    Port 52222

    Save and exit.

    Warning: DO NOT restart SSH until we configure the firewall in Step 4, or you will permanently lock yourself out.

    Step 4: Configure UFW to Allow Only What You Need

    Ubuntu and Debian servers use UFW (Uncomplicated Firewall) to manage network connections. To protect your server, we recommend setting a default-deny policy for incoming traffic, allowing outgoing traffic, and explicitly opening only the ports we need.

    Run the following commands on your VPS:

    # Deny all incoming traffic by default
    sudo ufw default deny incoming
    
    
    # Allow all outgoing traffic by default
    sudo ufw default allow outgoing
    
    
    # Allow your NEW custom SSH port (crucial!)
    sudo ufw allow 52222/tcp
    
    
    # Allow HTTP and HTTPS if you are hosting web apps
    sudo ufw allow 80/tcp
    sudo ufw allow 443/tcp

    Review your staged rules:

    sudo ufw show added

    If everything looks correct, you can enable the firewall by running the following command:

    sudo ufw enable

    Once the firewall is enabled, any new traffic entering or leaving your server will be inspected and filtered according to the rules we configured above. If any application has already established a connection, it won’t be terminated, but if the application attempts to establish a new connection, it will be blocked by the firewall. 

    Now that the firewall allows traffic on your custom port, we can safely apply the SSH changes by running the following command:

    sudo systemctl restart ssh

    Testing phase: DO NOT CLOSE your current terminal session. Open a new terminal on your local machine and test your new setup:

    ssh -p 52222 sysadmin@YOUR_VPS_IP

    If you successfully connect using your SSH key, you can close the original root session.

    Note: If configuring firewalls over CLI makes you nervous, RunCloud’s Firewall Manager lets you set, preview, and deploy port rules and IP whitelists directly from the dashboard without touching the terminal.

    Suggested read: Enable Zero-Trust SSH with Cloudflare on Windows, Mac, Linux, and ChromeOS 

    Step 5: Install Fail2Ban to Block Brute-Force Attacks

    Now that we have changed the SSH port and disabled password authentication, the server is relatively secure, but automated bots will still try to break in by sending random login attempts with incorrect credentials.

    Fail2Ban monitors your log files and dynamically updates your firewall to block IP addresses that show malicious behavior.

    To configure this on your Linux server, you can install the Fail2Ban package using the following command:

    sudo apt update && sudo apt install fail2ban -y

    After installing it, you need to create a set of rules (called “jails”) for your server. We strongly recommend that you don’t edit the default jail.conf file, as package updates will overwrite it. Instead, you should copy it to create a new file called jail.local. You can do this on a Linux server using the following command:

    sudo cp /etc/fail2ban/jail.conf /etc/fail2ban/jail.local

    After creating the file, you can edit your local configuration:

    sudo nano /etc/fail2ban/jail.local

    Scroll down to the [sshd] block. You need to tell Fail2Ban that you are using a custom port, and explicitly enable the jail. Modify the block to look like this:

    [sshd]
    enabled = true
    port    = 52222
    logpath = %(sshd_log)s
    backend = %(sshd_backend)s
    maxretry = 3
    bantime = 1h

    Run the following commands to save and exit, then start and enable the service:

    sudo systemctl enable fail2ban
    sudo systemctl restart fail2ban

    After creating the service, you can verify that your SSH jail is active using the following command:

    sudo fail2ban-client status sshd

    In the screenshot above, we can see the list of IP addresses that Fail2Ban has banned from accessing our server.

    By completing these 5 steps, you have eliminated the low-hanging fruit that compromises 95% of fresh Linux setups. 

    Note: Getting Fail2Ban thresholds wrong in jail.local often results in banning yourself or failing to trigger on real attacks. That’s why RunCloud ships with Fail2Ban pre-configured for web and SSH traffic. 

    Suggested read: How to Use Cloudflare Firewall Rules to Protect Your Web Application 

    Step 6: Enable Automatic Security Updates

    A hardened server is only secure until the next CVE is published. If you are managing more than one server, you should not want to manually run apt upgrade whenever a vulnerability is discovered in OpenSSL or your kernel. Enable unattended-upgrades to automatically install critical security patches in the background.

    To do this, first you need to install the necessary packages using the following command:

    sudo apt update && sudo apt install unattended-upgrades apt-listchanges -y

    After installing the services, you can enable the service via the interactive prompt:

    sudo dpkg-reconfigure -plow unattended-upgrades

    Select Yes when prompted to automatically download and install stable updates.

    After configuring it, check the configuration file to verify that it has been activated successfully using the following command:

    cat /etc/apt/apt.conf.d/20auto-upgrades

    When you run the above command, you should see APT::Periodic::Unattended-Upgrade "1"; in the output.

    Step 7: Remove Unused Packages and Disable Unnecessary Services

    Every service running on your server is a potential entry point for hackers. If you aren’t using a service or application, you can turn it off to protect your server and conserve resources.

    To do this, first, we will audit what is actively listening on your server’s network interfaces by using the following command:

    sudo ss -tulpn

    If you see any services that you don’t want, then you can stop and disable them so they don’t start on reboot:

    sudo systemctl stop <name>
    sudo systemctl disable <name>

    In the above commands, replace the <name> with the actual name of the service that you want to disable. 

    Next, purge any orphaned packages and dependencies that came pre-installed on your provider’s OS image but which aren’t needed anymore:

    sudo apt autoremove --purge -y

    Step 8: Harden Kernel Parameters with sysctl

    By default, the Linux kernel uses networking parameters optimized for broad compatibility rather than strict security. When you deploy your server on the internet, it will be constantly bombarded with hundreds of attacks that try to exploit these compatibility features. 
    But you can mitigate several types of network attacks (like SYN floods and IP spoofing) by tweaking sysctl.conf. To do this, you can open the configuration file using the following command:

    sudo nano /etc/sysctl.conf

    In this file, we will disable certain features by appending the following lines to the bottom of the file:

    # Protect against SYN flood attacks
    net.ipv4.tcp_syncookies = 1
    
    
    # Ignore ICMP broadcast requests (prevent smurf attacks)
    net.ipv4.icmp_echo_ignore_broadcasts = 1
    
    
    # Disable ICMP redirects (prevent man-in-the-middle routing attacks)
    net.ipv4.conf.all.accept_redirects = 0
    net.ipv6.conf.all.accept_redirects = 0
    
    
    # Log spoofed packets, source routed packets, and redirect packets
    net.ipv4.conf.all.log_martians = 1

    After editing the file, you can save and exit the file editor (CTRL+O, Enter, CTRL+X). After that, you can apply the changes immediately without rebooting by running the following command:

    sudo sysctl -p

    Suggested read: 16 Best Linux Distros in 2025 

    Step 9: Set Strict File Permissions and Audit User Accounts

    If an attacker compromises a system, they will try to either create hidden backdoor users, or leave files with wide-open permissions. There are several steps you can take to ensure this isn’t the case on your server. First, you can audit your user accounts to ensure only root has a User ID (UID) of 0. Run this command to print any user with root-level privileges:

    awk -F: '($3 == "0") {print}' /etc/passwd

    This should output exactly one line: root:x:0:0:root:/root:/bin/bash. If you see any other user here, then it is possible that your server is compromised.

    Next, verify that no users have empty passwords:

    sudo awk -F: '($2 == "") {print}' /etc/shadow

    This should return no output.

    Finally, find and review any world-writable directories (directories anyone can write to) that don’t have the “sticky bit” set (which prevents users from deleting each other’s files):

    sudo find / -type d -perm -0002 -a ! -perm -1000 -print 2>/dev/null

    If your server is serving multiple websites, then the above command will probably return a long list of directories. You need to review this list and, if you find any rogue directories, investigate them immediately and restrict their permissions using chmod 755.

    Step 10: Review Mandatory Access Control (AppArmor and SELinux)

    AppArmor (on Ubuntu/Debian) and SELinux (on RHEL/AlmaLinux) are Mandatory Access Control (MAC) systems. They act as a high-level security guard built directly into the Linux kernel. While standard file permissions (chmod) control who can see a file, MAC systems control which specific programs are allowed to do what.

    In a standard setup, if a hacker exploits a vulnerability in a web server such as NGINX and gains “root” access, they can theoretically access every file on your server.

    With AppArmor or SELinux active, the program is confined to a “sandbox.” Even if NGINX is compromised, the MAC system detects that NGINX is attempting to access sensitive system files (such as/etc/shadow) or execute unauthorized commands. Because that behavior isn’t in the program’s predefined “security profile,” the kernel blocks the action instantly, even if the attacker has root privileges. It effectively limits the “blast radius” of any potential hack.

    You can run the following commands to check the configuration of these systems on your server:

    • On Ubuntu/Debian (AppArmor):
    sudo aa-status
    • On RHEL/Alma/Rocky:
    sestatus

    Manually configuring MAC systems is tricky, and beyond the scope of this article. It requires writing deep-level security profiles that define every single file, port, and network socket a program is allowed to touch. One small mistake in a profile can cause your database to crash or prevent your website from loading, leading to hours of frustrating troubleshooting.

    The good news is that if you are using RunCloud, you don’t need to lift a finger.

    RunCloud servers are engineered to be secure out of the box. The platform automatically configures and optimizes these security layers during server provisioning. Your server is hardened the moment it connects to the RunCloud panel, allowing you to focus on your applications while RunCloud handles the complex kernel security in the background.

    Step 11: Configure Off-Server Backups

    Hardening your server reduces the risk of a hack, but it cannot protect you against hardware failure, a data center fire, or an accidental rm -rf / command. Off-server backups ensure that even if your entire VPS is deleted, your business can be restored in minutes.

    There are several ways to handle backups, each with its own pros and cons:

    1. Disk-Level Snapshots: Taking a full image of your server via your provider (like DigitalOcean or AWS). These are easy but often expensive, and they’re hard to move between providers.
    2. Application Plugins: Using WordPress plugins like UpdraftPlus. These are user-friendly, but they can slow down your site because they use your server’s PHP resources to compress files.
    3. Manual Scripting: Using Linux tools to manually move data. If you choose to do this manually, you must manage three distinct parts: the database, the files, and the transport. 
      • Security: Manual rclone or script configs often store your Cloud API keys or Database passwords in plaintext on the server. If a hacker gets in, they now have your backup keys too.
      • Resource-Heavy: Compressing large folders (tar) and dumping databases every night causes high CPU and Disk I/O spikes, which can make your website sluggish during the backup window.
      • Reliability: If the script fails, you won’t know until you try to restore and find out that the files are empty.

    If you are using RunCloud, you don’t need to deal with any of this.

    RunCloud uses Incremental Backups, which is a far superior technology. Instead of zipping your entire site every night (which is slow and uses a lot of disk space), RunCloud only identifies the specific data that changed – and syncs just that.

    • Fast & Efficient: Because it only moves “changes,” backups finish in seconds rather than minutes.
    • Zero Resource Lag: It doesn’t put a heavy load on your server, keeping your website fast even during a backup.
    • Encrypted & Secure: Your S3 or Backblaze credentials are stored in RunCloud’s encrypted vault.
    • Backup Notifications: You can configure the Backup script to notify you via Slack/Email/Discord if the backup fails for any reason.
    • One-Click Restore: If something goes wrong, you don’t have to remember complex Linux commands. You just click “Restore” in the dashboard, and RunCloud puts everything back exactly where it belongs.
    Runcloud automated backups

    After Action Report

    If you have followed all the steps in this article, your server is now locked down and can withstand a variety of internet attacks. But a hardened server isn’t very useful if it doesn’t host anything. The next step is installing your web stack (NGINX/Apache, PHP, MySQL) and provisioning SSL certificates.

    Doing this manually means diving right back into the terminal. After hardening, managing NGINX, PHP-FPM, and SSL still requires SSH for every single configuration change, virtual host creation, and certificate renewal.

    RunCloud manages your NGINX configuration, PHP-FPM tuning, and Let’s Encrypt SSL deployments entirely from a UI, while fully respecting the hardened SSH and firewall configurations you just put in place. 

    While RunCloud simplifies complex server management tasks, it is designed for developers, agencies, and power users who need more than just a basic cPanel replacement. Once your servers are hardened, RunCloud enables you to scale your operations by offering tools for advanced management:

    • Multi-Server Management: Easily oversee, update, and manage dozens or hundreds of hardened Linux servers from a single dashboard.
    • Team & Role-Based Permissions: Delegate server access to team members or clients without sharing SSH keys or root passwords, thanks to granular control over who can manage applications, databases, or backups.
    • API-Driven Control: Integrate server and application management into your custom workflows using the RunCloud API, allowing for automated server provisioning and deployment.

    Start using RunCloud today.

    Frequently Asked Questions

    What is Linux server hardening?

    Linux server hardening is the process of reducing a system’s attack surface by patching vulnerabilities, disabling unused services, and implementing strict access controls. Common hardening steps include disabling root SSH access, configuring firewalls like UFW, and enforcing cryptographic key-based authentication.

    How long does it take to harden a Linux server?

    Manually executing a basic Linux hardening checklist on a fresh VPS typically takes an experienced sysadmin about 30 minutes. However, advanced hardening procedures like configuring SELinux, setting up intrusion detection systems, and passing compliance audits can take several hours to properly tune. 

    Should I run hardening on an existing server or only on fresh ones?

    You should ideally harden a fresh Linux server before it is ever exposed to public internet traffic or connected to your production application stack. Applying strict firewall rules, altering permissions, and modifying SSH configurations on an existing server carries a high risk of breaking active application dependencies or accidentally locking yourself out. If you must harden an existing production server, thoroughly test the new security policies in a staging environment and ensure you have recent, verified off-site backups first.

    Does changing the SSH port actually improve security?

    Changing the default SSH port from 22 to a non-standard high port is a security-through-obscurity tactic that will not stop a determined, targeted attacker running a full port scan. However, it is still highly recommended because it drops automated botnet brute-force attempts by over 99 percent. This drastically cleans up your system authentication logs, reduces wasted CPU cycles, and prevents tools like Fail2Ban from being overwhelmed by background internet noise.

  • How to Clear Browser Cache & Cookies (Chrome, Firefox, Edge, Safari)

    How to Clear Browser Cache & Cookies (Chrome, Firefox, Edge, Safari)

    “Browser cache” and “cookies” can be confusing terms. If you have ever built a website, updated a page, and still seen the old data, you know the frustration. 

    If you search the internet, you will hear about hard refreshes, incognito mode, and temporary files. But all of this is overwhelming, especially when you just want to run your business and ensure your customers see your latest content, not a broken layout.

    In this post, we will help you identify why changes are not showing and fix the right problem.

    In some cases, clearing browser data is enough. In others, it will never work. Before jumping into step-by-step fixes, you need to know which situation you are dealing with.

    Bonus: If you are a site owner, sticking with manual fixes isn’t efficient. At the end of this post, we will share the best solution for speeding up WordPress sites without any additional hassle, including a one-click purge feature that ensures your visitors always see the freshest version of your site.

    Let’s get started!

    What are Browser Cache & Cookies?

    If you spend any time on the internet, you’ve likely heard the advice to “clear your cache and cookies” whenever something goes wrong. But what exactly are these things, and why is your browser storing them in the first place?

    To understand them, think of your web browser (like Chrome, Safari, or Edge) as a very organized backpack that helps make your trip across the internet easier.

    This guide covers two very different situations.

    • You are a visitor, and the website looks broken or outdated
    • You own or manage a website, and changes are not showing for users

    If you are fixing a one-off display issue, clearing browser data can help.

    If this keeps happening on your site, the problem is not the browser. It is server-side caching.

    This guide explains both situations and how to identify the real cause.

    Before you clear anything, answer these questions:

    1. Does the issue affect only you, or multiple users?
    2. Does the issue disappear in Incognito or Private mode?
    3. Did you recently update content, CSS, or a plugin?

    If the problem affects only you, browser cache is likely the cause. If multiple users see old content, browser cache is not the issue, and clearing it will not fix the problem.

    What is Browser Cache?

    Cache is your browser’s short-term memory. When you visit a website, your computer has to download many assets to display it properly. For example, a modern website usually needs logos, background images, fonts, and large code files.

    If you had to re-download every single logo and image every time you clicked a new page on the same site, browsing would be painfully slow. Instead, your browser saves (caches) these files on your hard drive. The next time you visit that site, the browser says, “I already have these images!” and loads them instantly from your computer rather than downloading them again. This significantly reduces load times and saves data.

    Suggested read: How to Easily Fix Leverage Browser Caching Warning in WordPress 

    What are Browser Cookies?

    Cookies are small text files that websites save to your browser to remember you. Without cookies, the internet would have no memory. If you logged into Facebook and then refreshed the page, you’d be logged out immediately because the site wouldn’t recognize you. While cache only saves the data to speed up the site, cookies provide several useful functionalities, such as:

    • Authentication: Keeping you logged in as you move from page to page.
    • Preferences: Remembering that you prefer “Dark Mode” or English language settings.
    • Shopping Carts: Remembering what you put in your basket while you continue shopping.

    Suggested read: Server Cache vs. Browser Cache vs. Site Cache: What’s the Difference? 

    Why Clearing Cache & Cookies Is Useful

    Since cache speeds things up and cookies make things more convenient, it might seem counterintuitive to delete them. Over time, these files can become outdated or corrupted, or simply accumulate, until they interfere with your browsing experience.

    Here are some of the common problems an individual user can fix by clearing browser cache and cookies:

    1. Fix “Glitchy” Websites

    Developers are constantly updating websites. If a website owner changes a photo or a piece of code, but your browser loads an outdated local copy, the site might look broken for you even though it is correct for everyone else. Buttons might be missing, or formatting might look weird. Clearing the cache forces your browser to download the newest, correct version of the site.

    1. Protect Your Privacy

    Cookies are often used for tracking. Have you ever looked at a pair of shoes online, and then seen ads for those exact shoes on every other website you visit for a week? That is the work of third-party tracking cookies. Clearing your cookies removes these trackers, preventing advertisers from tracking your digital footprint across the web.

    1. It Resolves Login Conflicts

    If you recently changed your password but your browser is still holding an old cookie with your old credentials, you might get stuck in a “login loop” where the site refuses to let you in. Clearing cookies removes that outdated “ID badge,” forcing the site to issue you a new, working session.

    1. It Speeds Up Your Computer

    While cache is designed to speed up browsing, having gigabytes of old files stored on your hard drive can eventually slow down your browser itself. It’s like a filing cabinet that is too full; it takes longer to find what you need. 

    Suggested read: How To Use Redis Full-Page Caching To Speed Up WordPress 

    How to Clear Cache & Cookies in Major Browsers

    Clearing your browser data is one of the most effective ways to troubleshoot website errors, but the process varies slightly depending on the browser and device you use. Here are the steps for the three most popular web browsers.

    How to Clear Cache & Cookies in Google Chrome (Desktop + Mobile)

    On Desktop (Windows/Mac):

    1. Open the Menu: Click the three vertical dots in the top-right corner of the browser window and select Delete browsing data. You can also press Ctrl + Shift + Delete (Windows) or Cmd + Shift + Delete (Mac) on your keyboard.

    Suggested read: How to Reduce Cache Misses & Avoid Them: Proven Tips [FIXED] 

    1. Choose Your Settings: A pop-up window will appear.
      • Time range: Select “All time” to ensure a complete cleanup.
      • Checkboxes: Ensure “Cookies and other site data” and “Cached images and files” are selected.
    1. Finish: Click Delete from this device.

    On Mobile (Android/iOS):

    1. Open the Chrome app and tap the Menu (three dots).
    2. Tap History, then select Delete browsing data.
    3. Choose your time range (usually “All time”) and make sure “Cookies” and “Cached images” are checked.
    4. Tap Delete data.

    Suggested read: The Best WordPress Caching Plugins To Speed Up Your Site 

    How to Clear Cache & Cookies in Mozilla Firefox (Desktop + Mobile)

    On Desktop:

    1. Open Settings: Click the hamburger menu (three horizontal lines) in the top-right corner, then select Settings.
    1. Privacy & Security: On the left sidebar, click Privacy & Security. Find the section labeled Cookies and Site Data and click the Clear Browsing Data button.
    1. Select & Clear: Check both boxes (“Cookies and Site Data” and “Temporary cached files and pages”) and click Clear.

    On Mobile:

    1. Tap the Menu button (three lines or dots, depending on your device placement).
    2. Tap Settings and scroll down to Privacy.
    3. Tap Delete browsing data (on Android) or Data Management (on iOS).
    4. Toggle the switches for Cache and Cookies, then tap the delete button.

    How to Clear Cache & Cookies in Safari (Mac + iOS)

    On Mac:

    1. Top Menu: In the menu bar at the very top of your screen, click the word Safari.
    2. Clear History: Select Clear History… from the dropdown menu.
    3. Confirm: A pop-up will ask for a timeframe. Select “all history” and click Clear History.
    clear browser cache and cookies

    On iOS (iPhone/iPad):
    Note: You do not do this inside the Safari app itself.

    1. Open your device’s main Settings app (the gear icon).
    2. Scroll down and tap on Safari.
    3. Scroll down again and tap the blue text that says Clear History and Website Data.
    4. Confirm your choice. This will refresh Safari and log you out of websites.

    Suggested read: How to Flush DNS Cache on Windows, Mac, and Linux 

    Hard Refresh vs Full Cache Clear – What’s the Difference?

    When a support agent or a developer asks you to “refresh” a page, it can be confusing to know exactly what they mean. There is a big difference between a standard reload, a hard refresh, and a full cache clear.

    FeatureHard Refresh Full Cache Clear 
    What it isIt is a command that tells the browser to ignore the cache for the current page only.It is a browser setting that permanently wipes temporary files and data from all websites.
    ScopeAffects only the single URL you are currently viewing.Affects your entire browsing history and every site you have visited.
    Impact on LoginSafe: You stay logged in. It does not delete cookies.Destructive: You will be signed out of most accounts (Gmail, Facebook, etc.) if you clear your cookies.
    When to useWhen a page looks “broken,” formatting is weird, or new content isn’t showing up.When a hard refresh fails, you have privacy concerns (tracking), or multiple sites are acting up.
    How to do it (Win)Ctrl + F5Ctrl + Shift + Delete (opens settings)
    How to do it (Mac)Cmd + Shift + RCmd + Shift + Delete (opens settings)

    Why CDN Cache Often Causes Confusion

    At this point, many people assume the browser is still responsible. In reality, the browser is often the last place the problem exists.

    Content Delivery Networks sit between your server and the browser. They cache full pages and assets at edge locations around the world.

    This means:

    • Clearing the browser cache may do nothing
    • Hard refresh may still show old content
    • Only purging the CDN cache fixes the issue

    If your site uses a CDN, outdated content is rarely a browser problem. It is almost always a cache purge issue upstream.

    💡 Pro Tip for Site Owners:
    Do your visitors constantly have to perform a Hard Refresh to see your latest content? That is a sign of server-side cache configuration issues, not user error.

    RunCloud solves this by managing server-side caching (like NGINX and Redis) for you. With RunCache, you can ensure updates appear instantly for everyone, saving your users the hassle of troubleshooting your site.

    Suggested read: Everything You Need To Know About WordPress Object Caching 

    The Correct Cache Clearing Order

    When changes are not showing, clear the cache in this order:

    1. Server cache
    2. CDN or edge cache
    3. Application or plugin cache
    4. Browser cache

    Clearing the browser cache first treats the symptom, not the cause. If the issue is server-side, it will persist no matter how many times users refresh.

    Wrapping Up

    Understanding the mechanics of browser cache and cookies is important for anyone using the web. For the average internet user, these troubleshooting steps are helpful tricks to keep in their back pocket. But if you are a website owner or developer, relying on your visitors to clear their cache is a bad strategy.

    If your users regularly need hard refreshes or cache clears, something is wrong. Well-configured server caching removes that burden entirely.

    Visitors should never need to troubleshoot your site for you.

    Instead of expecting visitors to troubleshoot your site, you can eliminate the problem at the source with RunCache by RunCloud.

    RunCache eliminates the need for disjointed plugins and manual configuration by offering a unified approach to Page, Object, and Edge caching. It ensures that when you update your content, your server intelligently purges the old versions instantly.

    Create a test site with RunCache in less than 3 seconds (no credit card required).

    FAQs on Cache & Cookies

    Does clearing the cache delete passwords or saved logins?

    No, clearing your browser cache removes temporary files like images and scripts, but it does not delete saved passwords or login credentials unless you specifically select the “Passwords” checkbox. 

    Will I lose browsing history if I clear the cache?

    You will not lose your list of visited websites when you clear the cache, as browsing history is stored separately from temporary cached files. 

    How often should I clear cache & cookies?

    It is generally recommended to clear cache and cookies only when you encounter page formatting errors or login issues, rather than as part of a set routine. 

    Does clearing cookies affect site preferences or saved settings?

    Yes, clearing cookies will sign you out of most websites and reset user-specific preferences, such as language settings or shopping cart items. 

    Is there a shortcut to clear the cache?

    Most major browsers let you quickly access the Clear Data menu by pressing Ctrl + Shift + Delete (Windows) or Cmd + Shift + Delete (Mac). Just as these shortcuts save users time for local troubleshooting, RunCloud offers the RunCloud Hub to clear server-side cache instantly with a single click from the WordPress dashboard.

    What’s the difference between cache and cookies?

    Cache consists of temporary files (such as images and HTML) stored to speed up page loading, whereas cookies are small text files that store user data, such as login status and tracking preferences. 

    Does using private/incognito mode avoid caching issues?

    Yes, using Incognito or Private mode prevents the browser from saving local cache or cookies, allowing you to view a website as if you were a new visitor. This is a great way to debug issues, but for a permanent fix, RunCloud allows you to manage and purge server-level cache to ensure all users see the correct version of your site without needing private windows.

  • How to Fix Cloudflare Captcha Failure in 2026 [SOLVED]

    How to Fix Cloudflare Captcha Failure in 2026 [SOLVED]

    Cloudflare CAPTCHA errors are a common frustration for both users and developers.

    These verification failures waste time, interrupt logins, and can even block legitimate visitors from accessing your site.

    In this guide, you’ll learn what causes Cloudflare CAPTCHA to fail – including network, browser, and configuration issues – and how to fix them effectively, whether you’re troubleshooting as a user or optimizing your setup as a site administrator.

    What Cloudflare CAPTCHA Does

    Cloudflare CAPTCHA, now evolving into Cloudflare Turnstile, verifies that site visitors are human before allowing sensitive actions like logins, registrations, or form submissions.

    Cloudflare Turnstile captcha

    Captcha challenges serve several key security purposes:

    • Protects against brute-force attacks by blocking automated login attempts.
    • Prevents spam and abuse in forms, comments, or mass account creation.
    • Verifies human interaction to maintain service integrity.
    • Reduces fraudulent activity by preventing bot-driven actions.

    Common Reasons Cloudflare CAPTCHA Fails

    Cloudflare uses machine-learning models to classify traffic as safe or suspicious. These models aren’t perfect, meaning legitimate users can sometimes be challenged or blocked.

    The most common triggers include:

    • Suspicious IP addresses: Shared or blacklisted IPs from VPNs, proxies, or hotel Wi-Fi can be misclassified.
    • High challenge frequency: When multiple users share an IP previously linked to abuse, Cloudflare increases CAPTCHA prompts.
    • Aggressive security rules: Overly strict firewall or bot protection settings can block genuine visitors.

    To reduce false positives:

    • Use reputable VPNs.
    • Avoid public or shared networks for login attempts.
    • Review Cloudflare’s Firewall Rules and Bot Fight Mode for overly restrictive settings.

    How to Fix CAPTCHA Failures (for Users)

    Captcha failures can indeed be a source of frustration, but there are several steps you can take to resolve common issues.

    Here is our three-point checklist of how to troubleshoot Cloudflare Captcha failures:

    #1 – Clear Your Browser’s Cache and Cookies

    Cached data and cookies are essential components of your browsing experience, designed to improve website performance and remember your preferences. However, if the cached version of a webpage becomes outdated or corrupt, it may not interact properly with current versions of web applications – this can lead to Captcha either not loading or not validating your inputs correctly.

    Additionally, cookies can sometimes store incorrect or outdated session data, which may conflict with the Captcha validation process. For example, if a cookie retains an old session state, it might prevent the Captcha from recognizing that you’ve entered the correct response.

    How to Clear Cached Data and Cookies:

    1. Access Browser Settings: Open your browser settings or preferences. This is usually found in the menu in the upper right corner of your browser.
    2. Locate Clearing Options: Look for an option that says something like “Clear browsing data,” “Clear cache,” or “Clear cookies and site data”.
    3. Select Data to Clear: Choose to clear cached images and files (cache) and cookies. You may also have the option to clear browsing history, but this is not typically necessary for resolving Captcha issues.
    4. Clear the Data: Confirm the action to clear the selected data from your browser.
    Cookies clear to fix captcha

    By clearing your cache and cookies, you remove any potentially corrupted or outdated files that could be causing issues with Captcha. This can often resolve problems where Captcha won’t load or won’t accept your input, even when you’re sure you’ve got it right.

    #2 – Update Your Browser

    Modern web applications, including Captcha systems, are built using the latest web standards; an outdated browser may not be compatible with these standards, leading to functionality issues.

    Update your browser regularly as new updates introduce new features or improve existing ones, including those related to accessibility and user interaction, which can affect how Captchas are displayed and function.

    #3 – Disable Browser Extensions

    Browser extensions can significantly enhance your browsing experience by adding functionality or improving privacy. However, they can also interfere with how web pages load and function, and this can include the operation of Captcha systems.

    Many extensions use JavaScript to modify web pages, which can lead to altering or blocking scripts that are essential for Captcha to work. Some privacy-focused extensions might actually block or restrict web requests that Captcha systems use to verify responses. To fix this, consider temporarily disabling extensions:

    1. Open Extension Settings: Launch your browser and enter chrome://extensions/ (for Chrome) or the equivalent in your browser’s address bar.
    2. Disable Extensions: You’ll see a list of installed extensions with toggle switches. Turn off all extensions by clicking these switches.
    3. Test Captcha: With all extensions disabled, try accessing the Captcha again. If it works, extensions are likely the cause of the problem.
    4. Consider Alternatives: If you identify an extension that’s causing issues, look for alternative extensions that don’t interfere with Captcha, or adjust the extension’s settings if possible.

    Managing CAPTCHA Behavior (for Site Admins)

    If you are a website owner, administrator, or developer, then you need to understand why your legitimate users are being challenged and how to fine-tune your settings for a better experience without compromising security.

    In this section, we will teach you how to diagnose issues with Cloudflare analytics, configure Turnstile for modern applications, and test your implementation correctly.

    Use Turnstile Analytics to Diagnose Issues

    Cloudflare’s Turnstile Analytics dashboard is your best diagnostic tool for understanding how security challenges affect real users.

    Key metrics to review include:

    • Challenge volume: Identify sudden increases that may indicate new bot activity or overly strict firewall rules.
    • Challenge solve rate (CSR): A low CSR suggests legitimate users are being challenged or abandoning the process.
    • Challenge type metrics: Track whether certain challenge types (e.g., managed vs. interactive) correlate with failures.

    Regularly reviewing these metrics helps ensure your configuration maintains security without compromising user experience.

    Enable Pre-Clearance for Single-Page Apps

    Single-page applications (SPAs) don’t reload full pages, which can lead to repeated Turnstile challenges as users navigate between views.

    Cloudflare’s Pre-Clearance feature solves this by issuing a temporary verification cookie after a user completes one challenge. This cookie confirms the user’s authenticity for the rest of their session, preventing unnecessary prompts and improving usability.

    Exclude Turnstile from Automated Testing

    If you are running automated tests on your application, then you will need a way to bypass Turnstile verification. Continuously solving real challenges in a test environment is impractical and unreliable. Cloudflare provides dedicated testing keys for this purpose.

    You should use the official test credentials provided in Cloudflare documentation for your testing environments. Cloudflare’s servers will always accept these keys without presenting a real challenge.

    Warning: Never use these test credentials in a production environment. Your deployment process must have safeguards to ensure that only your production keys are used on your live website.

    Troubleshooting Repeating CAPTCHA Loops

    A “challenge loop” happens when users solve one CAPTCHA only to face another immediately after.

    Common causes:

    • Unstable or low-quality network connections (e.g., public Wi-Fi or VPNs).
    • Browser extensions blocking Turnstile’s JavaScript.
    • Outdated browsers (Internet Explorer is unsupported).
    • Disabled JavaScript – Turnstile cannot function without it.

    Fix: Ensure JavaScript is enabled, test on a modern browser, and avoid VPNs or shared connections when possible. For persistent cases, check your Cloudflare logs for repeated bot classifications from the same IP range.

    Final Thoughts and Next Steps

    Cloudflare’s Captcha serves as a critical line of defense against bots and automated threats, although it’s not without its quirks. While Captcha challenges can sometimes be a source of frustration, they play a vital role in maintaining the integrity and security of online services. If you find yourself battling Captcha failures, remember to:

    • Lower Security Settings: High security settings are great, but they can sometimes be overzealous. If you’re facing persistent Captcha challenges, consider temporarily dialing back your security settings.
    • Incognito Mode: This mode isn’t just for private browsing – it can also help bypass troublesome browser settings that might be interfering with Captcha.
    • Check for IP Ban: Too many failed attempts can lead to a temporary IP ban. If you suspect this is the case, then consider restarting your router and trying again after a few hours.
    • Use a Different Device: Device-specific issues can cause unexpected Captcha failures. Switching devices can be a quick fix.

    Managing server security, SSL, and configuration doesn’t need to be time-consuming.

    RunCloud simplifies everything, from automatic configuration and PHP management to real-time monitoring and SSL setup, all from one intuitive dashboard.

    Start your free RunCloud trial today and manage your Cloudflare-protected sites with confidence.

    FAQs About Cloudflare Captcha Failure

    Is Cloudflare Turnstile better than CAPTCHA?

    Cloudflare Turnstile is a user-friendly, privacy-preserving alternative to traditional Captchas. It automatically blocks bot traffic using a suite of non-intrusive browser challenges based on telemetry and client behavior. As a result, many find it to be a better option due to its less intrusive nature and privacy considerations.

    Does Cloudflare use Google CAPTCHA?

    Cloudflare previously used Google’s reCAPTCHA service, but now it has developed its own CAPTCHA alternative, Turnstile, to address privacy concerns and provide more flexibility.

    Are CAPTCHA systems outdated for spam protection?

    While CAPTCHAs are still commonly used, their effectiveness against spam and automated threats has been questioned. Advanced bots have found ways to bypass CAPTCHAs, and alternatives such as Cloudflare’s Turnstile are emerging as more effective solutions.

    Is Cloudflare Turnstile CAPTCHA Free?

    Yes, Cloudflare Turnstile is a free service that aims to deliver frustration-free web experiences and confirms visitors are real without the data privacy concerns or the need for users to solve puzzles.

    How can I prevent my own team from being challenged by Cloudflare during development and testing?

    The best practice is to use IP Access Rules in the Cloudflare dashboard under Security > WAF > Tools. By adding your office’s or team members’ static IP addresses to the “Allow” list, you can ensure they bypass Cloudflare’s security checks entirely. This is the most reliable way to prevent trusted traffic from being challenged.

    My Turnstile widget appears correctly on the frontend, but my server-side verification keeps failing. What should I check?

    This issue almost always points to one of two problems. First, double-check that you are using your secret key for the server-side API call, as mistakenly using the public sitekey here is a common error. Second, ensure that your server’s firewall allows outgoing HTTPS requests to Cloudflare’s API endpoint.

    Will adding Cloudflare Turnstile negatively impact my site’s Core Web Vitals?

    No, Turnstile is specifically designed to be lightweight and performance-friendly. Unlike traditional CAPTCHA, which can be render-blocking, Turnstile runs non-intrusive JavaScript challenges that have a minimal impact on metrics like Largest Contentful Paint (LCP) and First Input Delay (FID). It is a much better choice for performance-conscious developers than older, more disruptive challenge systems.

  • How to Delete all Text in a File Using Vi/Vim Editor

    How to Delete all Text in a File Using Vi/Vim Editor

    One common task in Linux is to delete all text in a file using the Vi/Vim editor. Whether you’re clearing a log, resetting a config file, or preparing a test dataset, knowing the right commands saves time and prevents mistakes.

    In this guide, you’ll learn:

    • Several methods for wiping a file clean in Vi/Vim
    • Why this approach is safer than deleting and recreating the file
    • Step-by-step instructions for saving or exiting afterward.

    When Do You Need to Delete All Text in a File with Vi/Vim?

    Before looking at the commands, it helps to know when clearing a file is better than deleting it entirely. You will often find that emptying a file is a more appropriate solution than deleting it entirely. Here are some common examples:

    • Managing Large Log Files: Applications and services constantly write to log files, which can quickly grow large. Clearing them is safer than deleting the file, since active processes may still rely on it. For long-term management, see our Logrotate Troubleshooting Guide.
    • Resetting Temporary or Cache Files: When working with programs that use temporary or cache files, you may need to clear them out before running a process. This ensures that you start with a clean slate and that old data does not interfere with the new operation.
    • Resetting Configuration Files: Sometimes, you may need to reset a configuration file by clearing its contents before pasting in a new configuration. If you’re working with web server configs, see our guide on configuring NGINX log rotation for related best practices.
    • Preparing for Development and Testing: In a development environment, it is common to run tests that read from or write to specific data files. Clearing these files between each test run allows us to ensure that the results of one test do not influence the outcome of the next.

    Why Not Just Delete and Recreate the File in Linux?

    Deleting and recreating a file might seem simpler, but it often causes problems. First, deleting a file resets its ownership and permission settings, which you would then need to reconfigure manually.

    Additionally, this action will break any symbolic or hard links pointing to the original file. Most importantly, if another application is actively using the file, deleting it can cause that application to crash or behave unexpectedly. For these reasons, editing the file in place to clear its contents is a much safer and more reliable practice.

    Suggested read: How to edit files using Nano

    How to Create a Sample File to Practice in Vi/Vim

    To help you follow along with the examples in this guide, you can create a temporary practice file filled with random data. Please open your terminal and execute the following command. This will create a file named tmp.abc in the /tmp/ directory, which you can use to test the commands safely.

    tr -dc '[:alnum:] \n' < /dev/urandom | head -c 1024 > /tmp/tmp.abc

    How to Delete All Text in a File Using Vi/Vim Commands

    Vi/Vim is a powerful text editor, and deleting all text in a file is a straightforward process once you know the right commands. Here are a few of the most effective methods:

    Method 1: Delete All Text in Vi/Vim with ggdG

    This method combines three Vim commands into one sequence that’s easy to remember. Let’s break it down into its individual components.

    • The first part of the sequence, gg, is a command that instantly moves your cursor to the very first character on the first line of the file.
    • Next, the d key acts as the delete operator. By itself, d does not delete anything; instead, it signals to Vim that you intend to perform a deletion and waits for a subsequent motion command to define the range of text that should be removed.
    • The final part of the sequence, G, provides the motion command that the d operator was waiting for. When used alone, the G command moves the cursor to the very last line of the file.

    When you type these commands together as ggdG, the editor is directed to “delete from the first line to the last line,” removing every line in the current buffer.

    Step-by-Step: Using ggdG to Clear a File

    Here is a detailed, step-by-step guide on how to use this command to clear a file’s content.

    1. Open Your File in Vi/Vim: First, launch your terminal and open the desired file by typing vim your_file.txt. Make sure to replace your_file.txt with the actual path and name of your file.
    2. Ensure You Are in Normal Mode: Once the file is open, you must be in Normal mode to execute commands. This is the default mode when you first open a file. If you have been typing or are otherwise unsure of your current mode, simply press the Esc key to return to Normal mode.
    3. Execute the Deletion Command: With Normal mode active, carefully type the command sequence ggdG in succession. You do not need to press the Enter key. As soon as you type the final G, Vim will immediately execute the full command, and all text within the file will be deleted, leaving you with a blank screen.
    4. Enter Insert Mode to Add New Content: Now that the file is empty, you can begin adding new content. To do this, press the i key to switch from Normal mode to Insert mode. You will notice that your cursor may change shape, and you can now start typing text as you would in any standard editor.
    5. Save and Close the File: Once you are satisfied with your changes, you will need to save the file. The section below provides detailed instructions on the various commands used to save your work and exit the Vim editor.

    Method 2: Delete All Text in Vi/Vim with :%d

    You can also use Vim’s Command-line mode, also known as Ex mode. To delete everything, you can simply type :%d.

    To see how it works, let’s look at each part of the command.

    • Typing the colon (:) immediately shifts Vim from Normal mode into Command-line mode. This action moves the cursor to the bottom of the screen, which indicates that Vim is now ready to accept a typed command.
    • The percentage symbol (%) is a special character that represents the entire file.
    • Finally, the d character is the command to be executed across the specified range. In Command-line mode, d is the direct command for “delete”.

    Step-by-Step: Using :%d to Clear a File

    Here is a detailed, step-by-step guide on how to use the :%d command to clear all text from a file.

    1. Open Your File in Vi/Vim: To begin, you will need to open the file you wish to modify by executing the following command in your terminal: vim your_file.txt.
    2. Ensure You Are in Normal Mode: Before you can enter a command-line instruction, make sure you are in Normal mode. If you have just opened the file, you are already in this mode. However, if you have been editing or are uncertain, simply press the Esc key to ensure you return to Normal mode.
    3. Enter Command-line Mode and Execute the Command: Now, type a colon (:). You will see the cursor jump to the bottom-left corner of your screen, which indicates that Vim is now in Command-line mode. Next, you need to type %d after the colon and then press the Enter key to confirm and execute the full command. The entire content of the file will be deleted instantly.
    4. Enter Insert Mode to Add New Content: With the file now empty, you can switch into Insert mode to begin adding your new text. Press the i key to enable insert mode. This will allow you to type freely within the file.
    5. Save and Close the File: After you have finished typing your new content, you will need to save your changes and exit the editor. Please refer to the section below to learn how to save and close the file with Vim.

    How to Save and Exit After Deleting Text in Vi/Vim

    After clearing a file, the changes exist only in Vim’s memory. To make them permanent, you need to save (or “write”) the buffer to disk.

    Save Without Exiting in Vi/Vim (:w)

    There may be situations where you want to save your progress but continue working within the file. The :w command allows you to do just this.

    1. First, press the Esc key to ensure you are in Normal mode.
    2. Type :w and then press the Enter key.
    3. Vim will save the file, and you will see a confirmation message at the bottom of the screen with the file name and the number of lines and characters written. After you execute this command, you will remain inside the editor and this allows you to continue your work.

    Save and Quit in Vi/Vim (:wq or ZZ)

    This is the most frequently used command when you have finished your work and wish to save it and close the editor in a single step.

    • The :wq command is a combination of the “write” command (w) and the “quit” command (q). It first saves the file and then exits the Vim editor.
    • An even faster alternative is the ZZ command (note the capital letters). This is a Normal mode shortcut that performs the exact same action as :wq. It saves the file if it has been modified and then quits the editor.

    How to use :wq in Vim:

    1. Press the Esc key to enter Normal mode.
    2. Type :wq and press the Enter key to save your changes and exit.

    How to use ZZ in Vim:

    1. Ensure you are in Normal mode by pressing the Esc key.
    2. Without typing a colon, simply type the capital letters ZZ in succession. The editor will immediately save the file and close it.

    Quit Without Saving in Vi/Vim (:q!)

    If you accidentally delete the file’s content and want to revert, then you can close the file without saving. The q stands for “quit,” while the exclamation mark (!) is a “force” modifier. By adding !, you are telling Vim to quit immediately and to discard all changes made since the last time the file was saved.

    How to use it:

    1. Return to Normal mode by pressing the Esc key.
    2. Type :q! and press the Enter key.
    3. Vim will close instantly without saving.

    Final Thoughts: Easier File Management with RunCloud

    You’ve seen how easy it is to delete all text in a file using Vi/Vim with commands like ggdG or:%d. Once you know them, these commands are quick and give you full control from the terminal. If your goal is freeing up storage, our guide on checking disk space in Linux shows how to spot problems before they cause downtime.

    Still, managing files directly from the terminal takes time and leaves room for error. That’s where modern server management tools can make a difference.

    With RunCloud, you get both SSH access and a browser-based file manager. That means you can edit, clear, and manage files in seconds — without needing to remember Vim shortcuts.

    Our platform gives you a secure, browser-based file manager alongside full SSH access, so you can edit, clear, and manage files in seconds — without memorising Vim shortcuts.

    Try RunCloud today and simplify the way you manage files on your servers.

    At a Glance: Commands to Delete Text in Vi/Vim

    If you just need the key commands in one place, here’s a quick reference you can scan before diving into the FAQs.

    CommandWhat it doesExample usage
    ggdGDeletes all text in the file using normal modeOpen file → type ggdG
    :%dDeletes all text in the file using command mode:%d then press Enter
    ddDeletes the current lineMove to a line → type dd

    u

    Undoes the last changePress u after a deletion
    :q!Quits without saving changes:q! then press Enter
    :wqSaves and quits after deleting:wq then press Enter

    FAQs on Deleting All Text in a File Using Vi/Vim

    How do I delete a single line in Vi/Vim instead of all text?

    Use the dd command. Move the cursor to the line you want to delete and press dd. That removes just that one line.

    Can I undo deleting all text in Vi/Vim?

    Yes. Press u to undo the last change. If you deleted everything with ggdG or :%d, pressing u will bring the text back.

    What’s the difference between ggdG and :%d in Vi/Vim?

    Both commands delete all text in the file. The difference is how you use them. ggdG is a normal-mode command sequence, while :%d is an Ex command typed on the command line inside Vim.

    How do I delete text in Vi/Vim without saving the changes?

    After clearing the file, exit with :q!. That quits Vim without saving, so the file stays unchanged on disk.

    What’s the fastest way to clear a very large file in Vi/Vim?

    Both ggdG and :%d work quickly, even on large files. If the file is extremely big, :%d is usually a little faster because it runs as a single command.

  • How to fix the ERR_SSL_PROTOCOL_ERROR

    How to fix the ERR_SSL_PROTOCOL_ERROR

    Seeing “This site can’t provide a secure connection” with the ERR_SSL_PROTOCOL_ERROR message can stop you in your tracks. For developers, agencies, or site owners, it’s more than an inconvenience – it can mean downtime, lost visitors, and support tickets piling up.

    This guide explains what the error means, why it happens, and how to fix it quickly, whether you’re troubleshooting from your own device or diagnosing an issue on your server.

    Let’s get started!

    What is the ERR_SSL_PROTOCOL_ERROR?

    When you connect to a website, your computer encrypts all the traffic between your browser and the remote server using a common SSL certificate. When your browser and the website’s server fail to establish a secure connection, the browser displays an ERR_SSL_PROTOCOL_ERROR.

    This error can pop up for various reasons, ranging from simple local issues on your computer to more complex problems with the website’s configuration.

    Common Causes of the ERR_SSL_PROTOCOL_ERROR

    Several factors can trigger this error, and they can originate from either the user’s end or the server’s end. Here are some of the most frequent culprits:

    • Incorrect System Time and Date: One of the simplest and most common causes is an incorrect date and time on your computer. SSL certificates have a specific validity period, and if your system’s clock is off, your browser may incorrectly perceive the certificate as expired or not yet valid.
    • Corrupted Browser Cache or SSL State: Your browser stores data from websites to load them faster on subsequent visits. However, this cached data can sometimes become outdated or corrupted, leading to SSL errors. Similarly, your operating system maintains an SSL cache, which can cause issues.
    • Interference from Antivirus or Firewall Software: Security software is designed to protect you, but can sometimes cause unexpected errors. For example, your antivirus or firewall might misinterpret a website’s SSL/TLS protocol as a threat and block the connection.
    • Outdated Browser or Operating System: An outdated browser may not support the latest SSL/TLS protocols used by modern websites, leading to a connection failure.
    • Browser Extension Conflicts: A browser extension can occasionally interfere with the SSL/TLS handshake process.
    • Server-Side SSL/TLS Configuration Issues: Sometimes, the problem might be on the server’s side. This could be due to a few things: maybe their security certificate has expired or wasn’t set up correctly, or the website uses an old and less secure protocol to connect.

    How to Fix the ERR_SSL_PROTOCOL_ERROR

    If you’re encountering this error on a website, try the following troubleshooting steps in the provided order:

    1. Check Your System’s Date and Time: This is the quickest and often most effective fix. Ensure your computer’s date, time, and timezone are all set correctly.
    2. Clear Your Browser’s Cache and Cookies: Clearing your browsing data forces your browser to fetch a fresh version of the website. To do this in Chrome, press Ctrl + Shift + Delete (or Cmd + Shift + Delete on a Mac) and select to clear your browsing data for 1 hour.
    3. Clear Your SSL State: Your operating system also stores a cache of SSL certificates. Clearing this can resolve the issue. In Windows, you can find this option in “Internet Properties” > “Content” tab > “Clear SSL state”.
    1. Disable the QUIC Protocol in Your Browser: QUIC (Quick UDP Internet Connections) is a protocol developed by Google that is enabled by default in Chrome. Although generally beneficial, it can sometimes be the source of SSL errors. To disable it, type chrome://flags/#enable-quic into your Chrome address bar, and change the setting from “Default” to “Disabled”.
    Disabling experimental settings in Chrome to fix the ERR_SSL_PROTOCOL_ERROR
    1. Review Your Antivirus and Firewall Settings: Temporarily disable your antivirus or firewall to see if it’s causing the issue. If the error disappears, you must adjust your security software’s settings to allow the website. Be cautious with this step and remember to re-enable your security software afterward.
    2. Disable Browser Extensions: Try disabling your browser extensions individually to see if a specific extension is causing the conflict.
    3. Update Your Browser and Operating System: Ensure that you are using the latest browser version and that your operating system has all the latest security updates installed.
    4. Disable Experimental TLS features: In newer versions of Chrome, Google sometimes releases experimental features that can interfere with the TLS handshake mechanism. Search for “TLS” in the Chrome flags and disable new features.
    For Website Owners: Ensuring a Secure Connection

    If you own a website and your users are reporting the ERR_SSL_PROTOCOL_ERROR, you need to investigate your server’s configuration.

    • Verify Your SSL Certificate Installation: Ensure you have a valid SSL certificate installed on your server. You can use online tools like SSL Shopper or SSL Labs to check the status of your certificate.
    • Check for Expired SSL Certificates: SSL certificates have an expiration date. Make sure your certificate is valid.
    • Correct Your SSL Configuration: Your server should be configured to use modern, secure encryption protocols such as TLS 1.2 or TLS 1.3. Configure your web server to use these modern protocols and disable older, vulnerable protocols like SSLv2 and SSLv3.
    • Ensure Correct DNS A Record: Your domain’s DNS A record should point to the correct IP address of your hosting server. If you have already configured your DNS server, then you need to wait for a few hours for the DNS changes to propagate across the globe.

    Final Thoughts

    The ERR_SSL_PROTOCOL_ERROR might look technical, but it often comes down to simple fixes, from adjusting your system clock to updating your browser. If you follow the steps in this guide, you can usually get your site or browsing session back on track in minutes.
    If you’d rather avoid SSL errors altogether, RunCloud can help.

    Every site you host with RunCloud gets a free, automatically renewing SSL certificate – no manual renewals, expired certificates, or downtime. Setup takes just a few clicks, even for advanced setups like WordPress Multisite.

    Spend less time troubleshooting and more time running your sites.
    Get started with RunCloud and secure your websites automatically.
    Frequently Asked Questions (FAQs)

    Why do I only see this error on some websites and not others?

    This usually means the problem is with that specific website’s security setup, not your computer. Your browser is successfully making secure connections to other sites, but it’s hitting a snag with that one in particular.

    Is the ERR_SSL_PROTOCOL_ERROR dangerous to my computer?

    No, the error message itself is not dangerous; it is actually a safety feature from your browser. It’s stopping you from connecting to a site that it can’t verify as secure, which helps protect your personal information.

    If I clear my browser cache, will I lose all my saved passwords?

    Most browsers allow you to choose what data you want to clear. When you go to clear the cache, simply uncheck the boxes for “Passwords” and “autofill form data” to keep them saved.

    Can my Wi-Fi network cause this SSL error?

    Yes, some public or office Wi-Fi networks have strict rules that can block certain connections and cause this error. Visiting the site using a different network, like your mobile data, is a good way to check if this is the cause.

    I’ve tried all the steps, and the error won’t disappear. What should I do?

    If you have tried all the user-side fixes, the issue is almost certainly on the website’s end. You can try contacting the website’s administrator to let them know, or simply wait a day or two for them to fix it.