Whether you’re running Ubuntu, Arch, Debian, or any other Linux distribution, knowing how to quickly and accurately identify your OS version can be the difference between smooth operations and compatibility nightmares.
And knowing your Linux OS version precisely is essential when troubleshooting a software installation, planning a system upgrade, or ensuring security patch compatibility.
This straightforward guide will demystify the process of checking your Linux operating system version and provide multiple command-line techniques that work across various distributions, such as Ubuntu, CentOS, Fedora, and more.
Understanding Linux Versions and Distributions
Before checking your system’s version, remember that Linux comes as a “distribution” – a complete operating system built around the Linux kernel. While hundreds of different distributions are available, most systems you will encounter belong to one of two major families: Debian or Red Hat.
For example, many servers run on distributions from the Red Hat family, such as Red Hat Enterprise Linux (RHEL) itself or others built to be compatible with it, like Rocky Linux, AlmaLinux, and CentOS Stream. On the other hand, an enormous community of developers and desktop users prefers distributions from the Debian family; the most famous is Ubuntu, which is based directly on Debian.
This family relationship is important because software packaged for one distribution, like RHEL, will often work on its close relatives. Similarly, an application designed for Debian will usually run perfectly on Ubuntu.
Although most Linux systems are based on these two lineages, a handful of users rely on other excellent independent distributions like Arch Linux or SUSE. Therefore, identifying your OS version is about finding the specific distribution name (e.g., Ubuntu) and its release number (e.g., 22.04), which tells you about its features and software family.
How to Check OS Version in Linux Command Line
There are six ways to check your Linux version via the command line. Here’s our guide to all six methods.
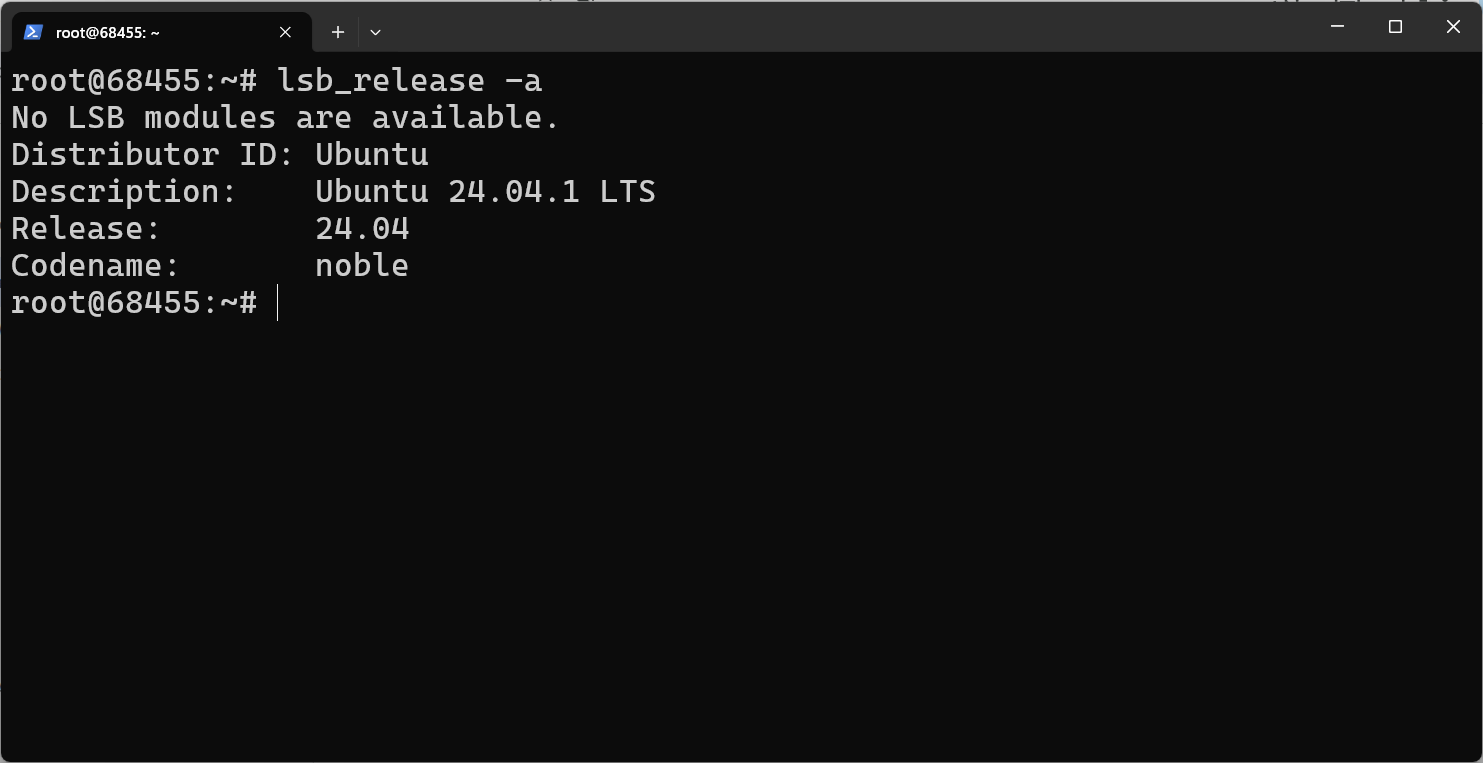
1. How to Check OS Version in Linux with lsb_release
The lsb_release -a command provides comprehensive information about your Linux distribution, including version details and codename. This command works across most Linux distributions and offers a quick, standardized way to retrieve system information.
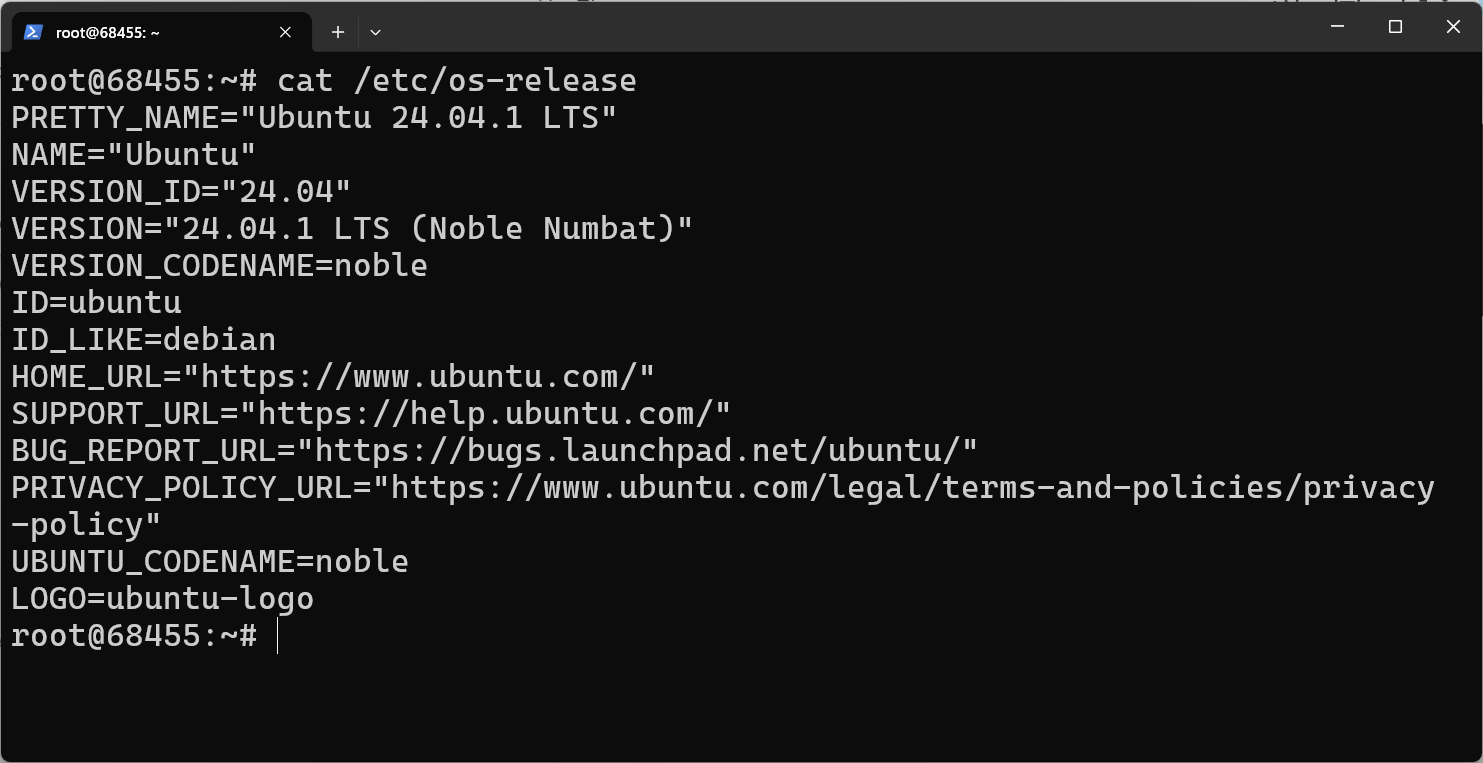
2. How to Check OS Version in Linux with /etc/os-release
The /etc/os-release file contains detailed distribution-specific information that can be viewed using the cat command. It provides the operating system name, version, and other identification details. This method offers a reliable and consistent approach to checking the OS version across different Linux distributions.
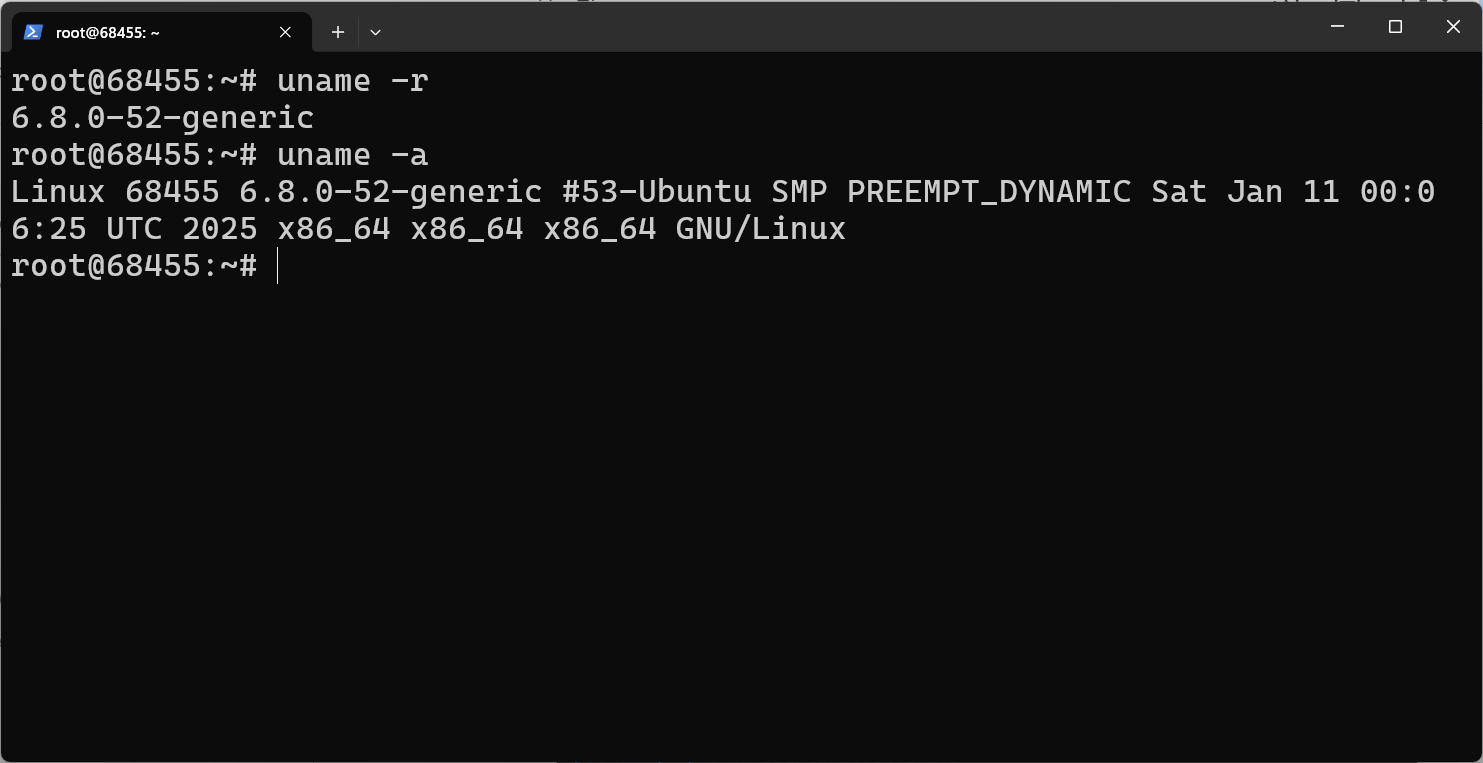
3. How to Check OS Version and Kernel in Linux with uname
The uname -a command displays system information, including kernel version and system architecture, which helps identify the core operating system details. If you want to check the kernel version, you can use uname -r to view the kernel release information.
Let’s break down this example piece by piece so you can understand what it is telling you:
Field
Example value
Meaning
Kernel name
Linux
The kernel in use
Hostname
server01
The system’s network name
Kernel rel.
6.8.0-52-generic
Kernel version number
Build info
#53-Ubuntu SMP Fri Jul…
Who built it and when
Arch
x86_64
CPU architecture (64-bit here)
OS type
GNU/Linux
Confirms the operating system
Knowing this information is extremely useful when downloading software, as you must choose a package that matches your system’s architecture (x86_64 or arm64).
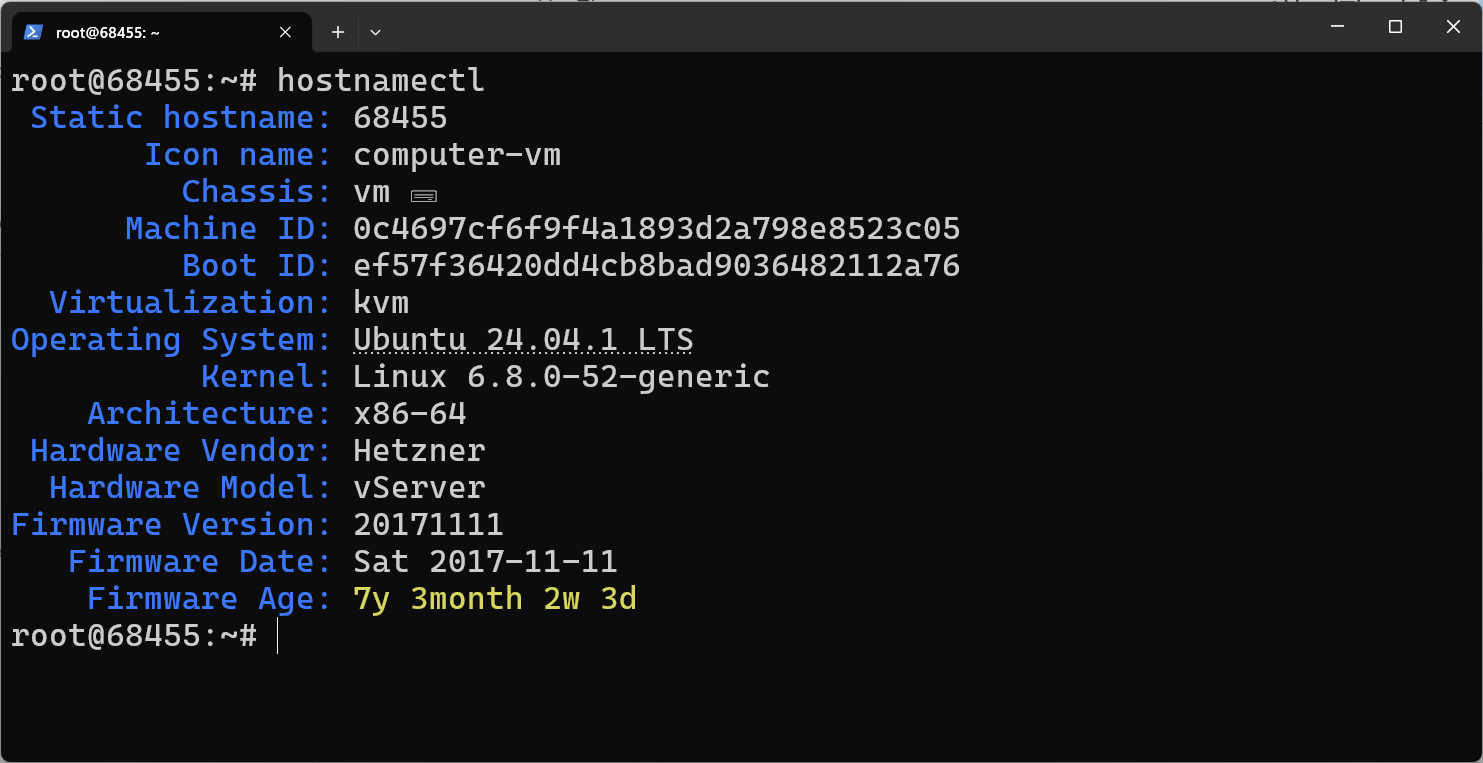
The hostnamectl command offers a modern, systemd based approach to retrieving system information. It displays detailed operating system and hardware details in a clean, readable format. This command is particularly useful for systems using systemd as their init system.
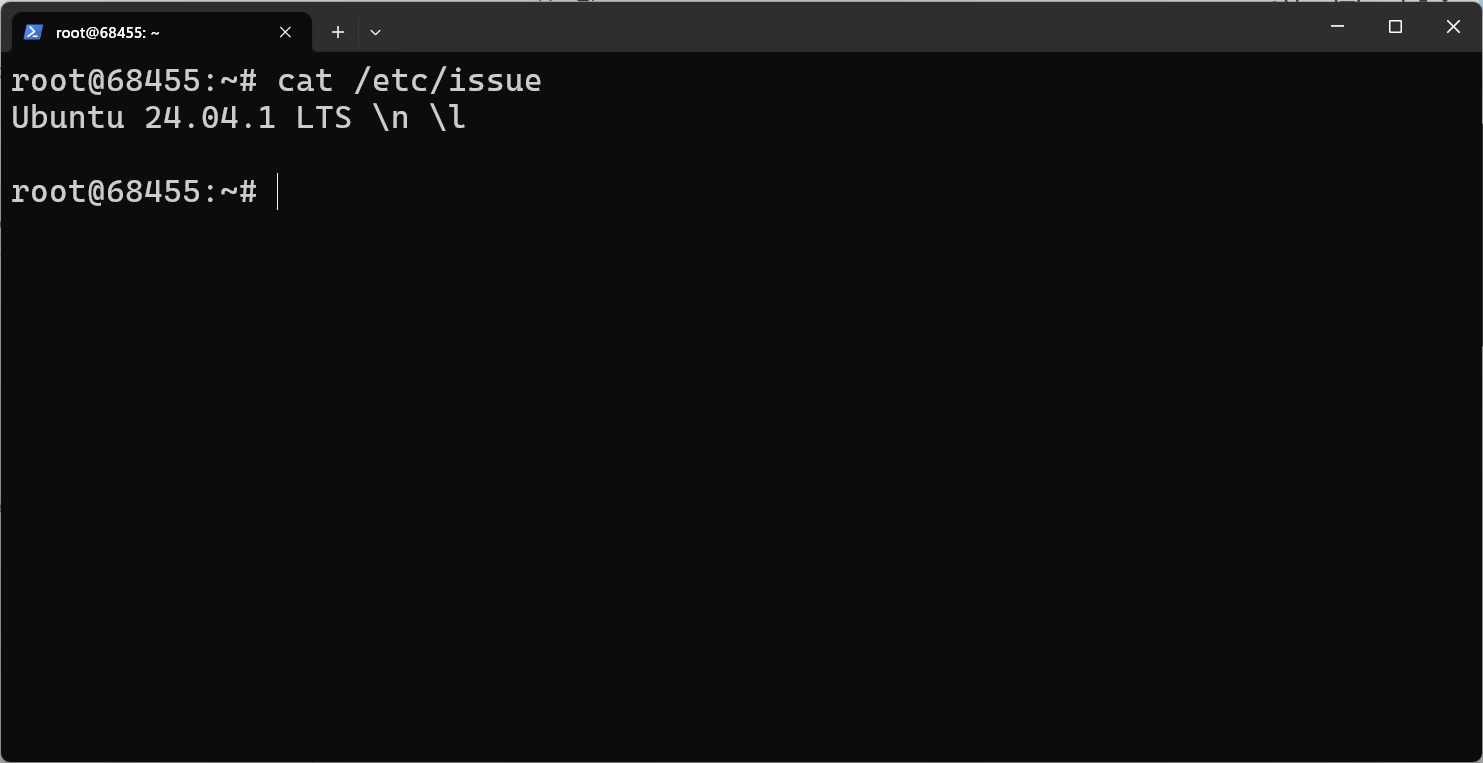
The /etc/issue file briefly describes the operating system and can be viewed using the cat command. It provides a quick glimpse of the system’s distribution and version. This method offers a simple, straightforward way to check basic system identification information.
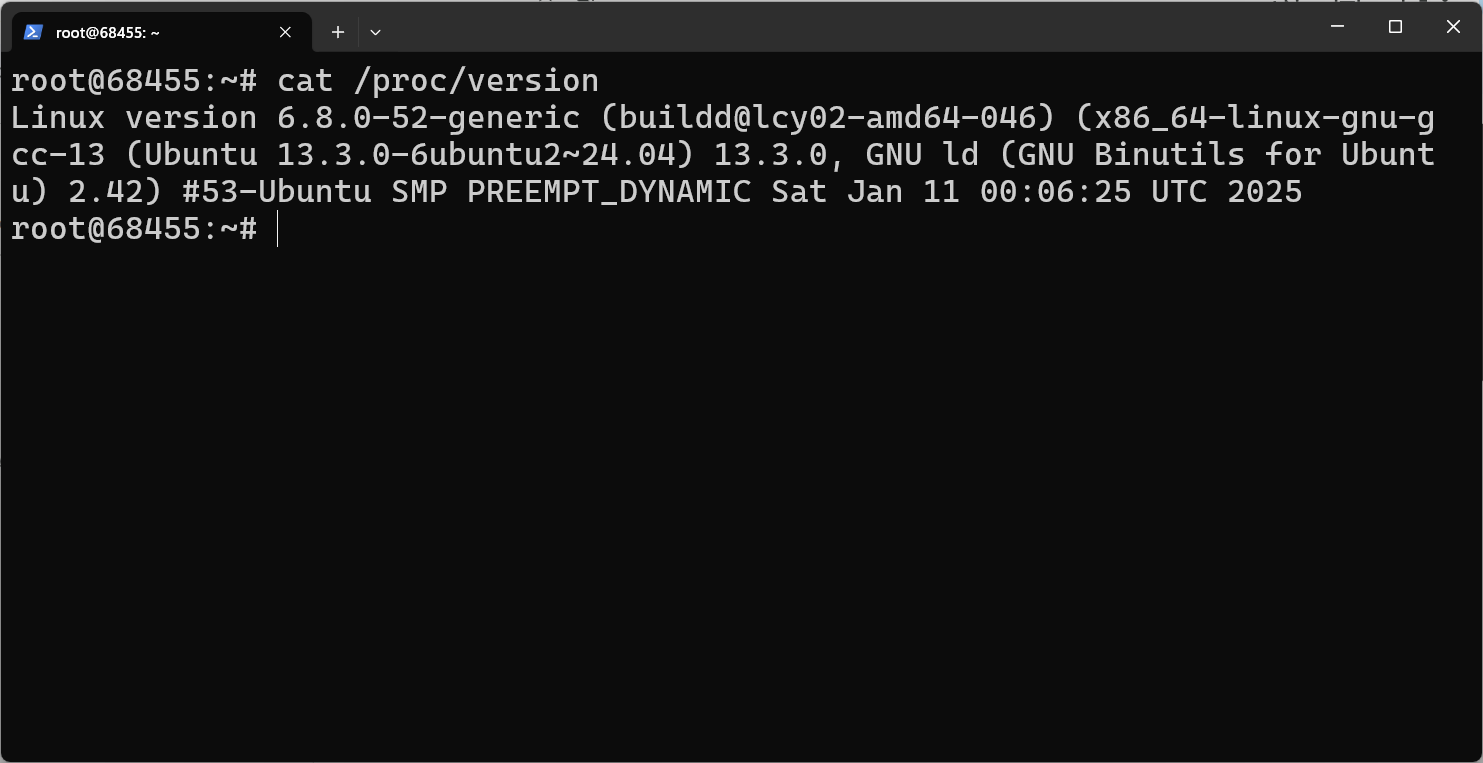
The cat /proc/version command reads the Linux kernel version directly from the virtual /proc filesystem, offering a quick and direct method to view kernel information. This command provides raw kernel details and is particularly useful for technical users seeking precise system information.
Checking the Linux Kernel Version via CLI
The Linux kernel is software responsible for managing your computer’s hardware and resources. While you will more frequently need to know your distribution’s version, sometimes a specific piece of software or a troubleshooting guide will require you to know the version of the Linux kernel itself.
The kernel has its own version number, separate from the distribution’s version number. Fortunately, there is a simple and universal command to find this information on any Linux system.
To see which kernel version your system is running, type the following command into the terminal and press Enter:
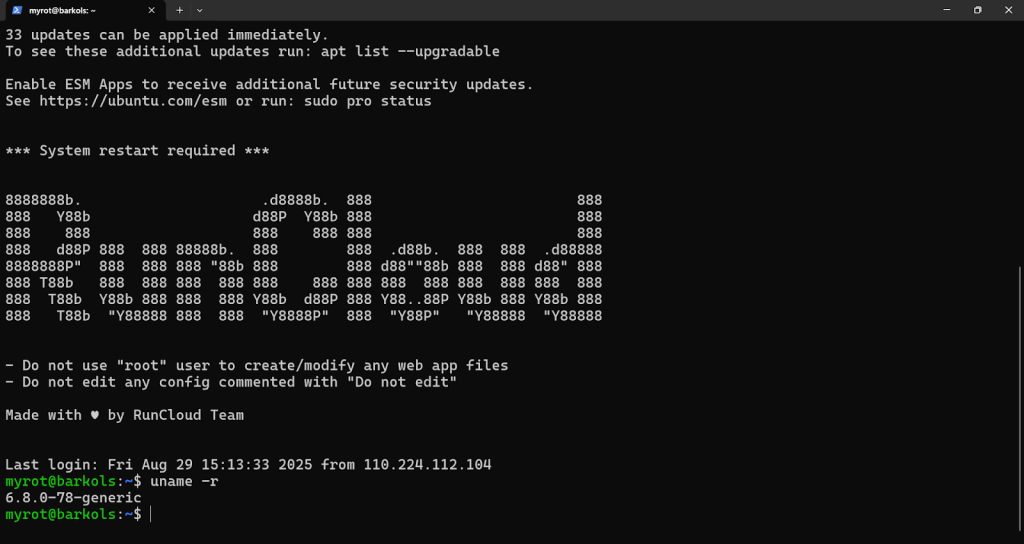
uname -r
After you run the command, your terminal will display your kernel version. In the above screenshot, the kernel version is 6.8.0-78-generic. This tells you the kernel’s major and minor release numbers that your system is currently using.
Quick Guide: Checking Your Linux OS Version
If you just want the commands without explanations, here’s a quick reference:
Command to Type
What It Shows You
When to Use It
hostnamectl
A clean, easy-to-read summary including the distribution name, version, and kernel.
Best for a quick overview.
lsb_release -a
The full distribution name, version number, and official codename (e.g., “Jammy Jellyfish”).
Use this when you need the official distribution details.
cat /etc/os-release
Detailed information about the distribution is formatted as simple text variables.
This file is on almost all modern Linux systems and is a great alternative if other commands fail.
cat /etc/issue
A single line of text usually identifies the distribution and its version.
This file contains the message shown before you log in, so it’s a simple way to see the OS name.
uname -a
The Linux kernel version and system architecture (e.g., 64-bit), not the distribution version.
Use this specifically when you need to know the kernel version for a driver or advanced software, not the OS name like “Ubuntu.”
cat /proc/version
Extremely detailed information about the Linux kernel, including how and when it was compiled.
This advanced command is useful for deep troubleshooting or when you need technical details about the kernel itself.
Wrapping Up: When and Why to Check Your Linux OS Version
Understanding your Linux OS version becomes particularly important when deploying web applications, and this is where platforms such as RunCloud shine for developers and website owners.
RunCloud simplifies the complex process of Linux server management, enabling users without deep technical expertise to deploy, manage, and scale web applications effortlessly.
Whether you’re a seasoned developer or a beginner looking to launch your first web application, RunCloud eliminates the traditional barriers associated with Linux server management.
RunCloud provides an intuitive interface that abstracts the technical complexities, allowing you to focus on your application rather than server configuration intricacies.
To find the Linux kernel version, use the command uname -r in the terminal. This command will display the current kernel release number, providing a quick and straightforward way to identify the specific kernel version running on your system.
Which command shows the full OS version?
The command cat /etc/os-release provides comprehensive information about your Linux distribution, including the full OS version and name. Alternatively, lsb_release -a offers detailed distribution-specific information in a user-friendly format.
Is there a graphical way to check the OS version?
Most Linux desktop environments, such as GNOME and KDE, offer system information tools accessible through the settings menu. This menu displays OS version details in a graphical interface. These built-in utilities provide an easy, user-friendly method for checking system information without using terminal commands.
Can I check the OS version remotely?
You can check the OS version remotely using SSH by executing version commands such as uname -a or cat /etc/os-release on the remote Linux system. Ensure you have proper authentication and access permissions before attempting remote system information retrieval.
Are there differences in commands across Linux distributions?
While core commands like uname are consistent across distributions, specific version-checking methods can vary between Linux systems including Ubuntu, CentOS, or Fedora.
What is the significance of the OS version number?
The OS version number indicates the current release, including kernel updates, security patches, and feature improvements. Understanding your version helps manage system compatibility and security and determines eligibility for software and hardware support.
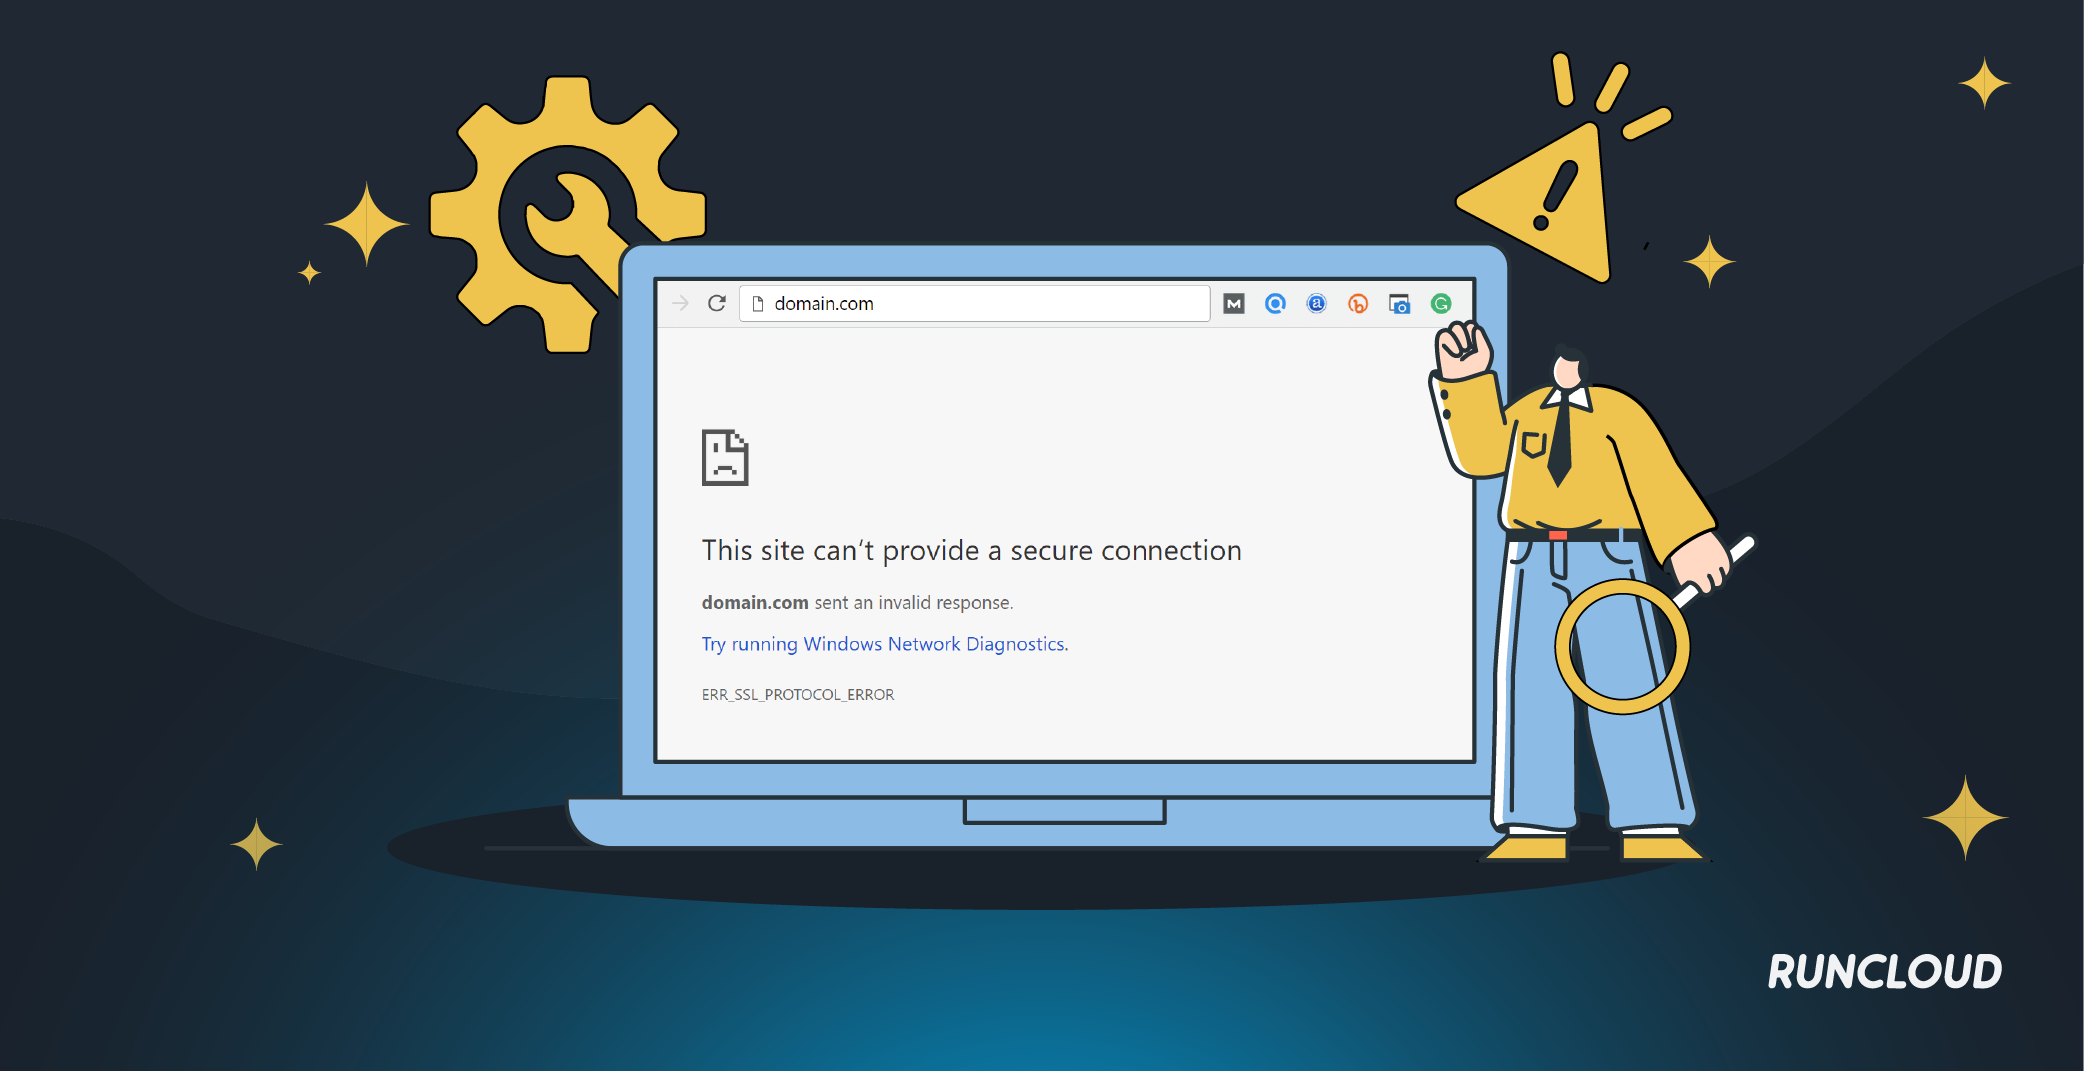
Seeing “This site can’t provide a secure connection” with the ERR_SSL_PROTOCOL_ERROR message can stop you in your tracks. For developers, agencies, or site owners, it’s more than an inconvenience – it can mean downtime, lost visitors, and support tickets piling up.
This guide explains what the error means, why it happens, and how to fix it quickly, whether you’re troubleshooting from your own device or diagnosing an issue on your server.
Let’s get started!
What is the ERR_SSL_PROTOCOL_ERROR?
When you connect to a website, your computer encrypts all the traffic between your browser and the remote server using a common SSL certificate. When your browser and the website’s server fail to establish a secure connection, the browser displays an ERR_SSL_PROTOCOL_ERROR.
This error can pop up for various reasons, ranging from simple local issues on your computer to more complex problems with the website’s configuration.
Common Causes of the ERR_SSL_PROTOCOL_ERROR
Several factors can trigger this error, and they can originate from either the user’s end or the server’s end. Here are some of the most frequent culprits:
Incorrect System Time and Date: One of the simplest and most common causes is an incorrect date and time on your computer. SSL certificates have a specific validity period, and if your system’s clock is off, your browser may incorrectly perceive the certificate as expired or not yet valid.
Corrupted Browser Cache or SSL State: Your browser stores data from websites to load them faster on subsequent visits. However, this cached data can sometimes become outdated or corrupted, leading to SSL errors. Similarly, your operating system maintains an SSL cache, which can cause issues.
Interference from Antivirus or Firewall Software: Security software is designed to protect you, but can sometimes cause unexpected errors. For example, your antivirus or firewall might misinterpret a website’s SSL/TLS protocol as a threat and block the connection.
Outdated Browser or Operating System: An outdated browser may not support the latest SSL/TLS protocols used by modern websites, leading to a connection failure.
Browser Extension Conflicts: A browser extension can occasionally interfere with the SSL/TLS handshake process.
Server-Side SSL/TLS Configuration Issues: Sometimes, the problem might be on the server’s side. This could be due to a few things: maybe their security certificate has expired or wasn’t set up correctly, or the website uses an old and less secure protocol to connect.
How to Fix the ERR_SSL_PROTOCOL_ERROR
If you’re encountering this error on a website, try the following troubleshooting steps in the provided order:
Check Your System’s Date and Time: This is the quickest and often most effective fix. Ensure your computer’s date, time, and timezone are all set correctly.
Clear Your Browser’s Cache and Cookies: Clearing your browsing data forces your browser to fetch a fresh version of the website. To do this in Chrome, press Ctrl + Shift + Delete (or Cmd + Shift + Delete on a Mac) and select to clear your browsing data for 1 hour.
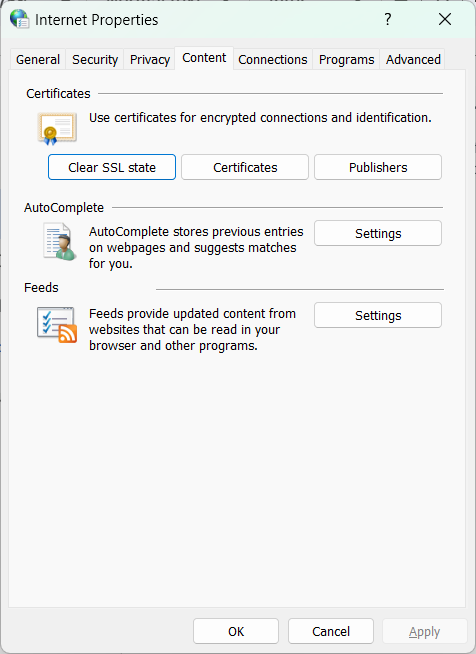
Clear Your SSL State: Your operating system also stores a cache of SSL certificates. Clearing this can resolve the issue. In Windows, you can find this option in “Internet Properties” > “Content” tab > “Clear SSL state”.
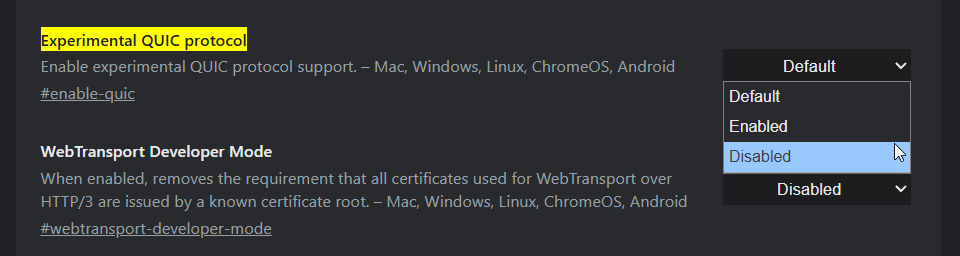
Disable the QUIC Protocol in Your Browser: QUIC (Quick UDP Internet Connections) is a protocol developed by Google that is enabled by default in Chrome. Although generally beneficial, it can sometimes be the source of SSL errors. To disable it, type chrome://flags/#enable-quic into your Chrome address bar, and change the setting from “Default” to “Disabled”.
Review Your Antivirus and Firewall Settings: Temporarily disable your antivirus or firewall to see if it’s causing the issue. If the error disappears, you must adjust your security software’s settings to allow the website. Be cautious with this step and remember to re-enable your security software afterward.
Disable Browser Extensions: Try disabling your browser extensions individually to see if a specific extension is causing the conflict.
Update Your Browser and Operating System: Ensure that you are using the latest browser version and that your operating system has all the latest security updates installed.
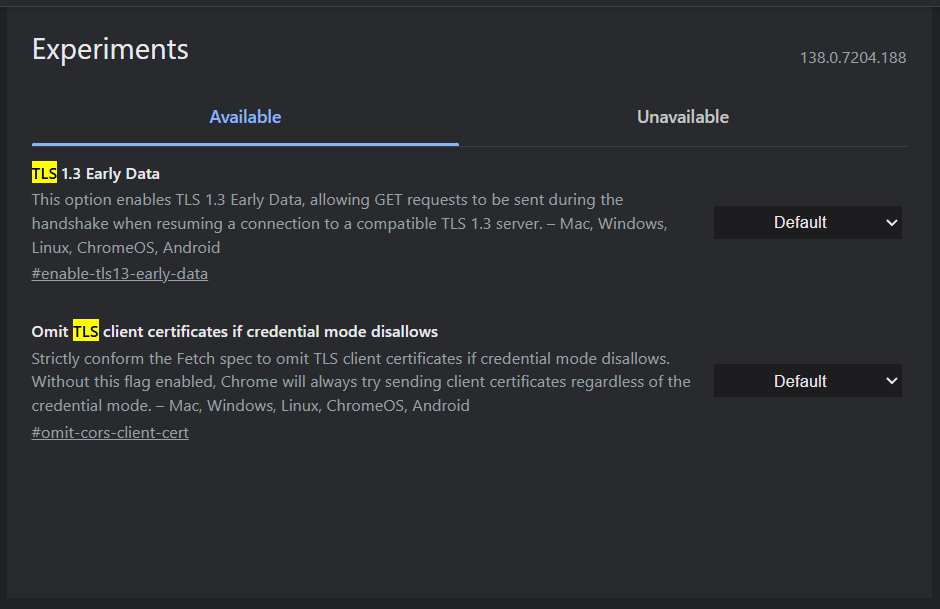
Disable Experimental TLS features: In newer versions of Chrome, Google sometimes releases experimental features that can interfere with the TLS handshake mechanism. Search for “TLS” in the Chrome flags and disable new features.
For Website Owners: Ensuring a Secure Connection
If you own a website and your users are reporting the ERR_SSL_PROTOCOL_ERROR, you need to investigate your server’s configuration.
Verify Your SSL Certificate Installation: Ensure you have a valid SSL certificate installed on your server. You can use online tools like SSL Shopper or SSL Labs to check the status of your certificate.
Check for Expired SSL Certificates: SSL certificates have an expiration date. Make sure your certificate is valid.
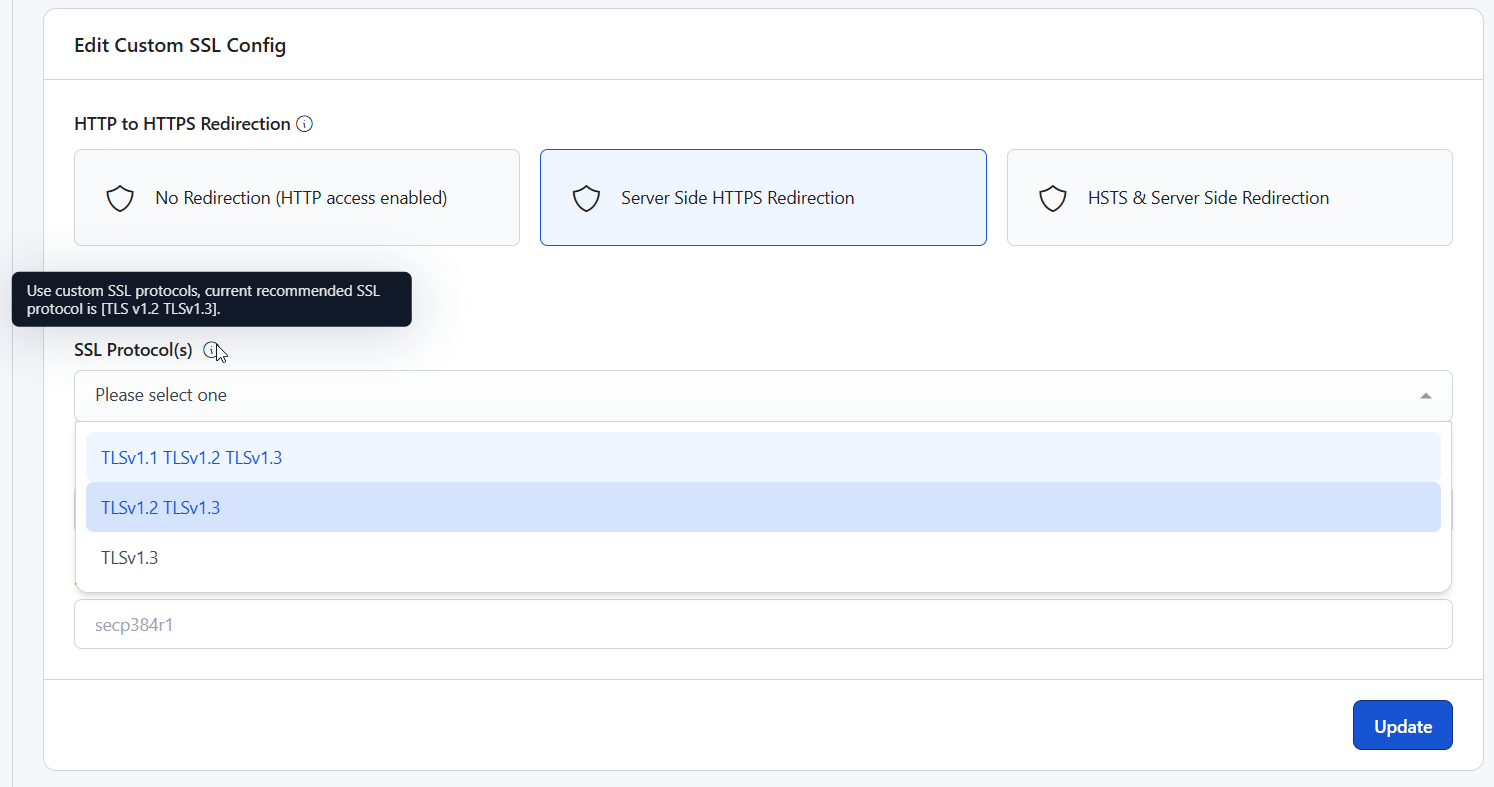
Correct Your SSL Configuration: Your server should be configured to use modern, secure encryption protocols such as TLS 1.2 or TLS 1.3. Configure your web server to use these modern protocols and disable older, vulnerable protocols like SSLv2 and SSLv3.
Ensure Correct DNS A Record: Your domain’s DNS A record should point to the correct IP address of your hosting server. If you have already configured your DNS server, then you need to wait for a few hours for the DNS changes to propagate across the globe.
Final Thoughts
The ERR_SSL_PROTOCOL_ERROR might look technical, but it often comes down to simple fixes, from adjusting your system clock to updating your browser. If you follow the steps in this guide, you can usually get your site or browsing session back on track in minutes.
If you’d rather avoid SSL errors altogether, RunCloud can help.
Every site you host with RunCloud gets a free, automatically renewing SSL certificate – no manual renewals, expired certificates, or downtime. Setup takes just a few clicks, even for advanced setups like WordPress Multisite.
Spend less time troubleshooting and more time running your sites.
Why do I only see this error on some websites and not others?
This usually means the problem is with that specific website’s security setup, not your computer. Your browser is successfully making secure connections to other sites, but it’s hitting a snag with that one in particular.
Is the ERR_SSL_PROTOCOL_ERROR dangerous to my computer?
No, the error message itself is not dangerous; it is actually a safety feature from your browser. It’s stopping you from connecting to a site that it can’t verify as secure, which helps protect your personal information.
If I clear my browser cache, will I lose all my saved passwords?
Most browsers allow you to choose what data you want to clear. When you go to clear the cache, simply uncheck the boxes for “Passwords” and “autofill form data” to keep them saved.
Can my Wi-Fi network cause this SSL error?
Yes, some public or office Wi-Fi networks have strict rules that can block certain connections and cause this error. Visiting the site using a different network, like your mobile data, is a good way to check if this is the cause.
I’ve tried all the steps, and the error won’t disappear. What should I do?
If you have tried all the user-side fixes, the issue is almost certainly on the website’s end. You can try contacting the website’s administrator to let them know, or simply wait a day or two for them to fix it.
Are you tired of unresponsive programs, resource-hogging applications, or rogue processes slowing your Linux system down? While knowing how to kill a process on Linux from the command line is a fundamental skill for any Linux user, the story doesn’t end with a simple kill command.
What if you can’t find the process ID (PID)?
What’s the difference between a “job” and a “process” – and how do you manage them?
If you’ve ever found yourself searching for answers to these follow-up questions, you’re in the right place. This article will move past the basic ps aux | grep command and discuss more efficient tools like pgrep and pidof to find exactly what you’re looking for.
We will learn how to manage foreground and background jobs – an essential skill for multitasking in the terminal.
We’ll also tackle common points of confusion, such as the difference between jobs and processes, and how to find resource-hungry processes without relying on top.
But before we kill processes, let’s first refresh our knowledge of what processes are!
What is a Process in Linux?
In Linux, a process is an instance of a running program. Each process has its own memory space, system resources, and a unique Process ID (PID) that the kernel assigns.
Processes can be applications, system services, or background tasks essential for the operating system’s functionality.
Killing a process in Linux means terminating or stopping a program forcefully. This action is often necessary when a process becomes unresponsive, consumes too many system resources, or needs to be stopped for maintenance or security reasons.
Linux provides several methods to kill processes, ranging from graceful termination signals to forceful stops.
When you kill a process, you’re essentially sending a signal to that process, instructing it to terminate. The most common signal used for this purpose is SIGTERM (signal 15), which allows the process to perform cleanup operations before exiting.
In cases where a process doesn’t respond to SIGTERM, users can employ stronger signals such as SIGKILL (signal 9), which forces immediate termination without allowing for cleanup.
Before you can stop a process, you need to find it, but multiple processes with similar names can run simultaneously. In Linux, every process running on your system has a unique Process ID (PID).
While many users are already familiar with the ps aux | grep command, there are often faster and more precise tools for the job.
Let’s explore the best ways to locate processes.
Using the ps command in Linux
The ps (process status) command gives you a snapshot of the currently running processes. It has many options, but a few combinations are incredibly useful.
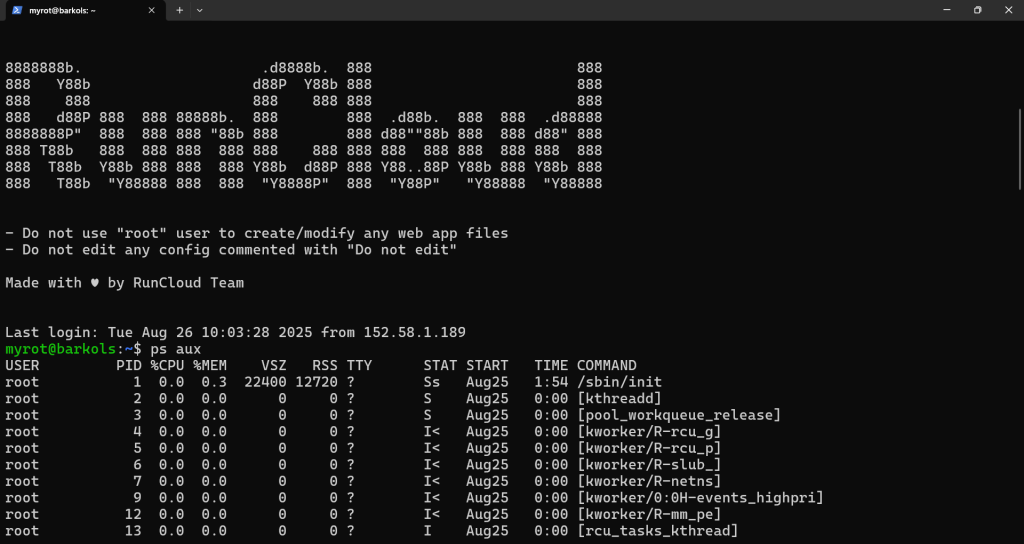
ps aux: This is one of the most common commands for tracking processes, as it shows all processes running for all users. You should use ps aux when you need to identify which user owns a process and how much CPU or memory it’s using.
The ‘aux’ in this case comprises the following three parameters:
a = show processes for all users
u = display the process’s user/owner
x = also shows processes not attached to a terminal
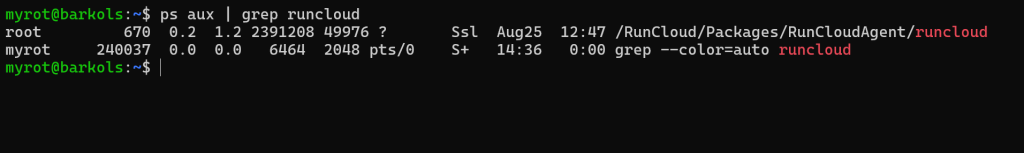
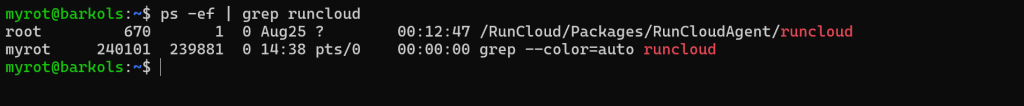
Example: To find the process ID of the RunCloud agent, you could type:
ps aux | grep runcloud
The second column in the output is the PID you need. You’ll notice that the output presented here is quite complex because of the number of columns, and it can be hard to locate what you need.
Let’s look at some of the better alternatives below, which provide us with the Process ID without any other complex information.
ps -ef: This command is similar to ps aux and shows every process on the system in a different format. You should use this command if you also need to find a process’s Parent Process ID (PPID).
-e = select every process
-f = display full-format listing
Example:
ps -ef | grep runcloud
This command returns cleaner output; the process ID is in the second column. However, some users might still find it hard to read. Let’s look at some of the better options below, which produce even simpler output in human-readable format.
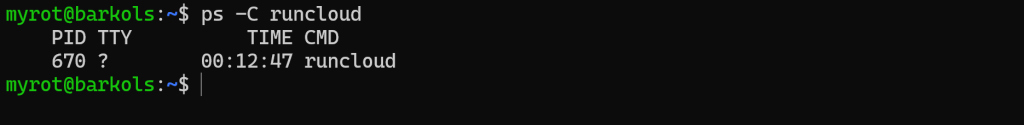
ps -C <process_name>: In the previous commands, the ps utility returned a very long list of processes, and we used a different tool (grep) to extract only what we needed and discard everything else. This command provides a much cleaner way to find a process by its name without needing grep.
-C = select by the command name
Example:
ps -C runcloud
This will list only the processes named “runcloud” with a clean output showing the PID and how long this process has been running. This command displays the information in a presentable format that is easy to read. However, it can still be cumbersome to extract the process ID of a particular process in an automated manner.
Using the pgrep Command in Linux
The pgrep (process grep) command is a modern and efficient tool for finding PIDs. It’s faster and less cumbersome than piping ps to grep. If you want to learn more about Linux pipes, we recommend reading our recent blog post on pipes vs xargs.
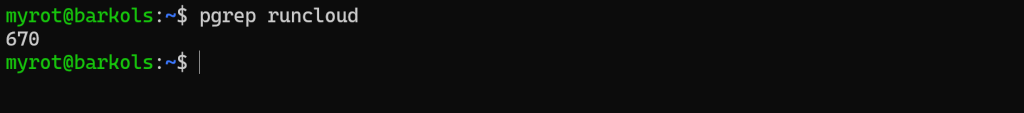
Basic pgrep: Simply type pgrep followed by the process name.
pgrep runcloud
This command will return only the PIDs of the sshd process, nothing more.
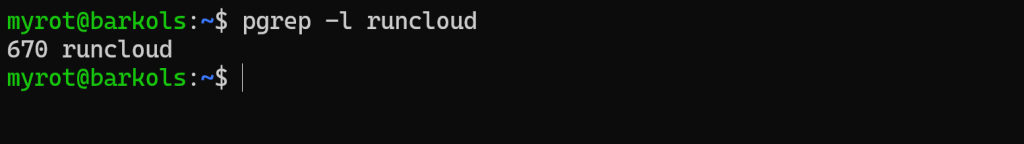
pgrep -l: If you want to see the process name alongside the PID, then you can use the -l (list-name) option
pgrep -l runcloud
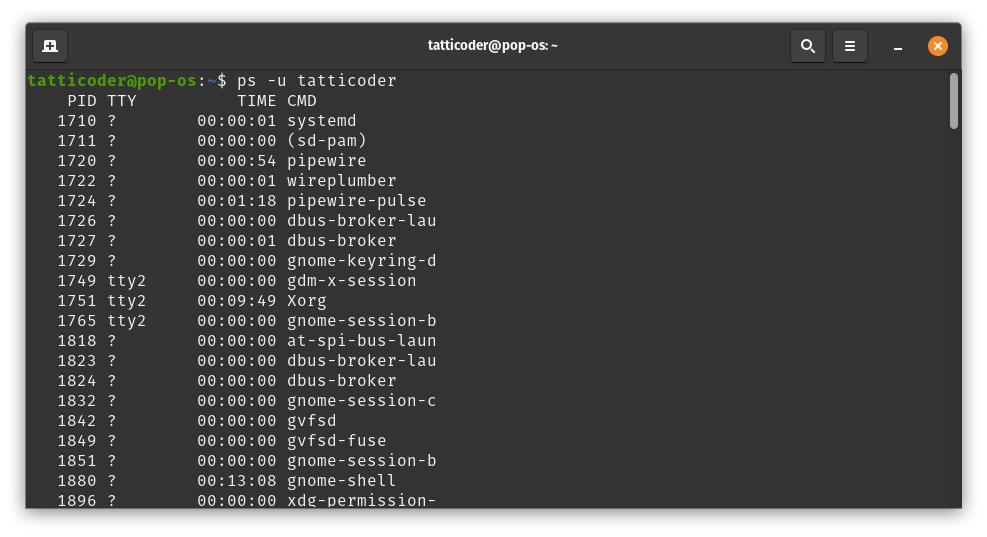
pgrep -u <username>: If you need to find all processes run by a specific user, you can use the -u (user) option.
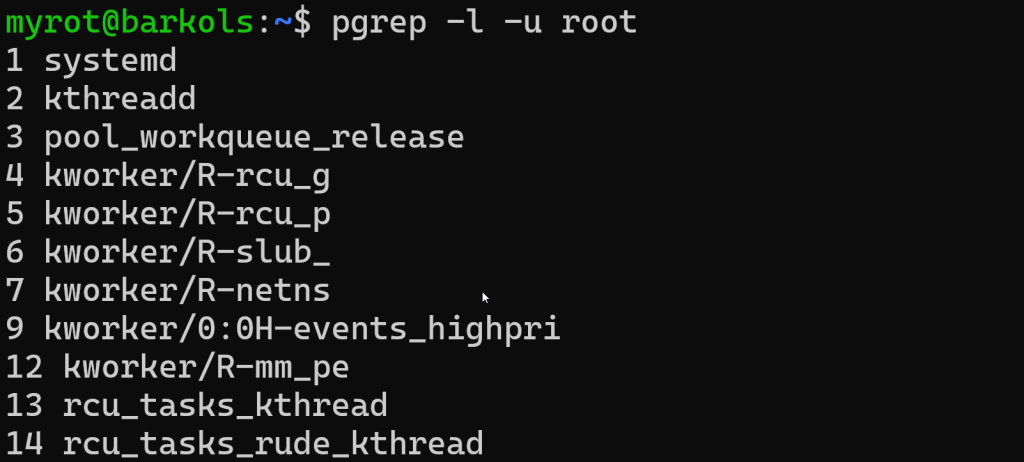
pgrep -l -u root
This will list the PID and name of every process owned by the user “root.”
Using the pidof Command in Linux
All the commands we discussed have returned some extra information. If you just want to see the process ID and nothing else, you can use the pidof command with the process name. This command is simple, fast, and doesn’t require data processing to extract the necessary information. This makes it extremely easy to integrate into bash scripts.
Example:
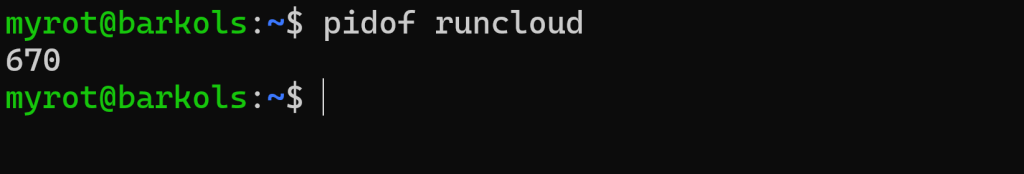
pidof runcloud
In the above example, if any process named ‘runcloud’ is running, this command will output its PID.
Using the top Command to find the Process ID
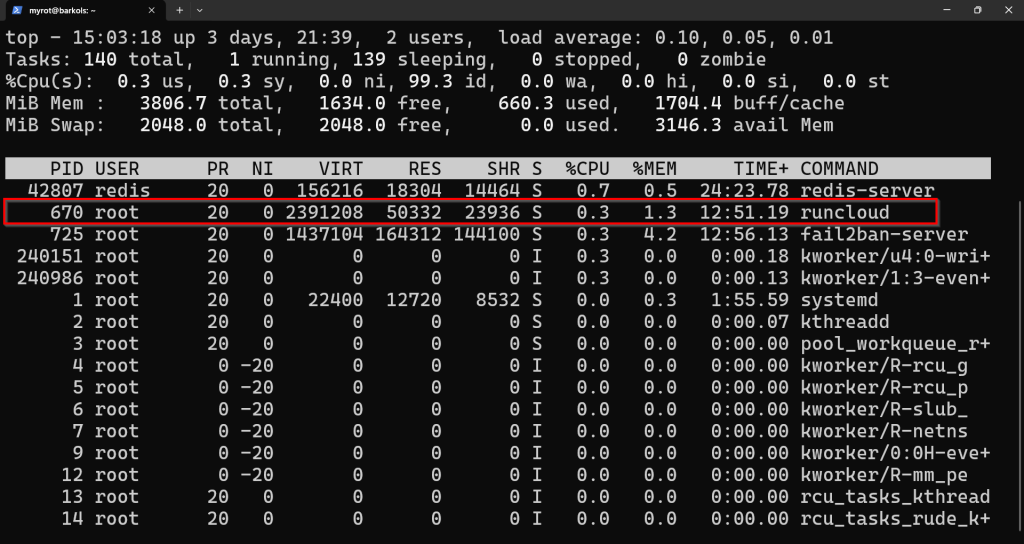
The top command provides a real-time, interactive view of your system’s running processes. Just type top to launch it, and you’ll see a constantly updated list of processes, sorted by CPU usage by default. The PID is in the first column, and the command is in the last column. Once you have found what you are looking for, press the ‘q’ key to exit.
The above example shows that the ‘runcloud’ process has the process ID 670.
Managing Background and Foreground Tasks in Linux
When you run a command in your terminal, it typically runs in the foreground. This means it occupies your terminal, and you must wait for it to finish before entering another command. But what if you need to run a time-consuming task and continue using your terminal?
This can be done using the built-in job control functionality. A job is a wrapper around one or more processes, allowing you to manage them within your current terminal session.
Sending a Job to the Background in Linux Shell
You can start a process directly in the background by adding an ampersand (&) at the end of the command.
Example: Let’s say you’re running a script that takes a long time.
./my-long-script.sh &
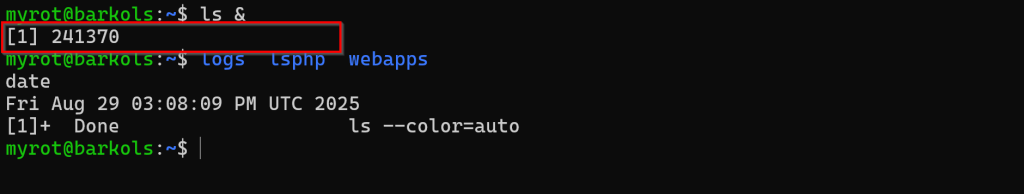
The script will start, and the terminal will immediately return you to the command prompt. You’ll see output similar to [1] 12345, where [1] is the job ID and 12345 is the PID.
The above example shows that the ls command was launched in the background and assigned the PID 241370.
Viewing and Managing Jobs with jobs
It is easy to forget once you have sent a job to the background. The jobs command lists all jobs associated with your current terminal session.
jobs -l
The -l option also shows the PID, which is very useful.
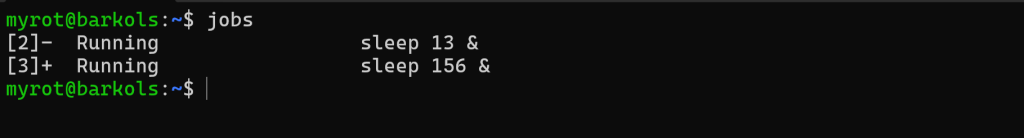
The above example shows that the current terminal session has two jobs running in the background.
Bringing Jobs to the Foreground and Background
fg (Foreground): If you need to interact with a background job again, you can bring it to the foreground with the fg command followed by its Job ID.
fg %1
This command brings job ID 1 back to the foreground and makes it the active process in your terminal.
bg (Background): If you’ve stopped a foreground process (using Ctrl+Z), you can send it to the background to continue running with bg.
bg %1
How to Kill a Process in Linux
There are several ways to kill a process in Linux, but the first step is always to identify the process you want to kill. Once you identify the process, you can choose the following method based on your needs:
How to Kill a Process Using the kill Command With a PID
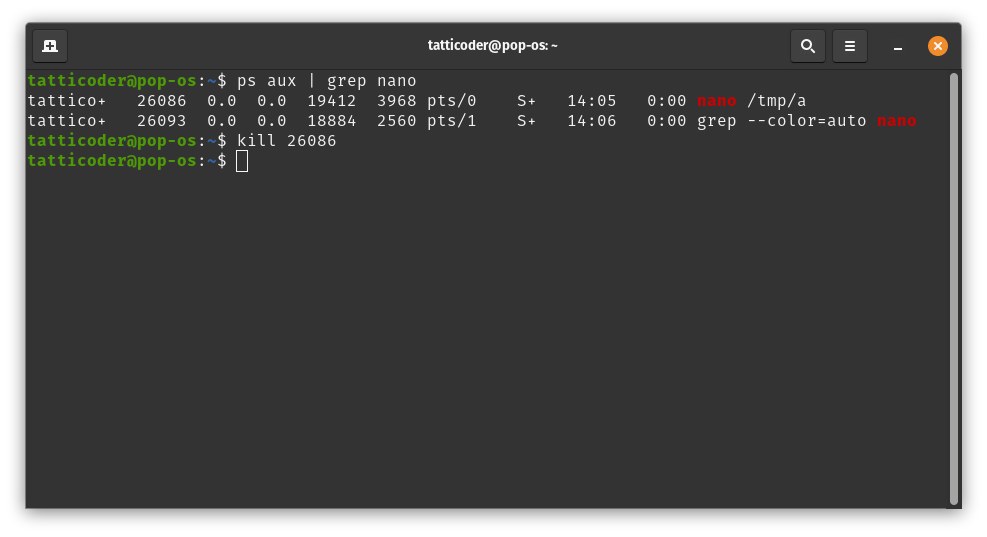
Using the kill command: Once you have the PID, you can use the kill command to terminate the process:
kill PID
Replace “PID” with the actual number you found. For instance:
kill 1234
This sends a SIGTERM signal, asking the process to shut down gracefully.
Forceful termination: If the process doesn’t respond to the regular kill command, you can use a stronger signal, SIGKILL (9), which forces immediate termination:
kill -9 PID
Be cautious with SIGKILL as it doesn’t allow the process to clean up, potentially leading to data loss or corruption.
How to Kill Multiple Processes
Sometimes, you need to terminate multiple processes simultaneously. Linux provides efficient ways to do this:
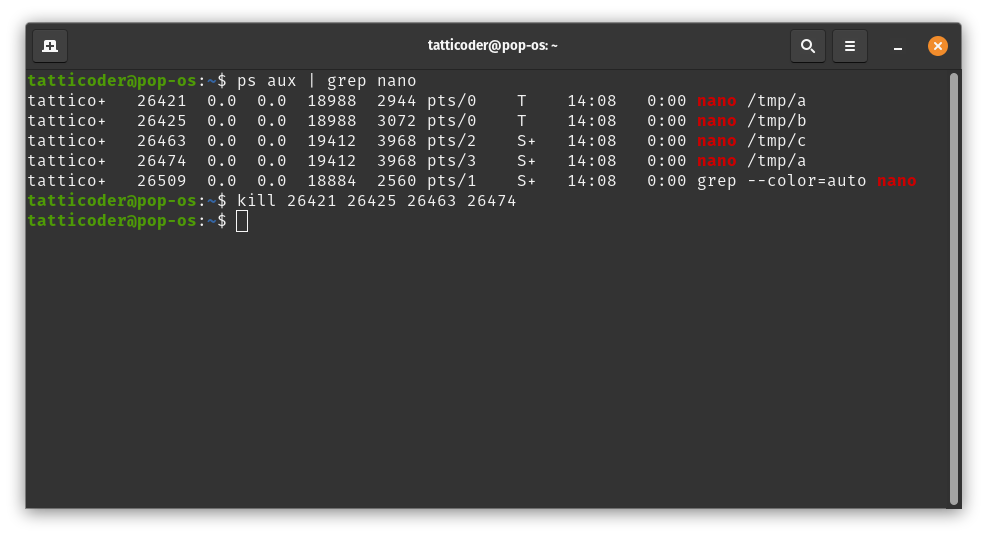
Using kill with multiple PIDs: If you know the PIDs of all processes you want to terminate, you can list them after the kill command:
kill PID1 PID2 PID3
For example:
kill 1234 5678 9101
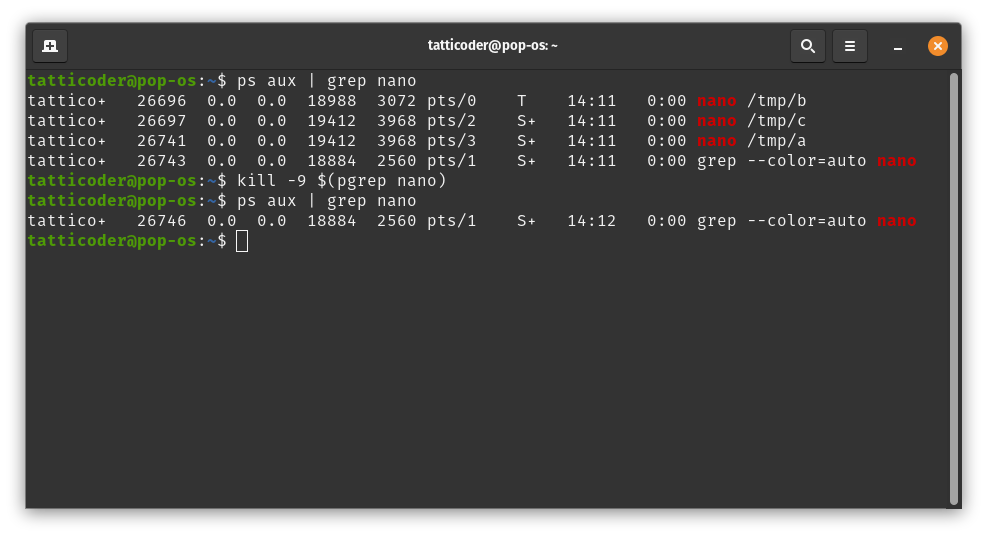
Using command substitution: A more dynamic approach is to use command substitution with pgrep. This method kills all processes matching a name:
kill $(pgrep process_name)
For instance, to kill all Firefox processes:
kill $(pgrep firefox)
This command first uses pgrep to find all PIDs associated with Firefox, then passes these PIDs to the kill command.
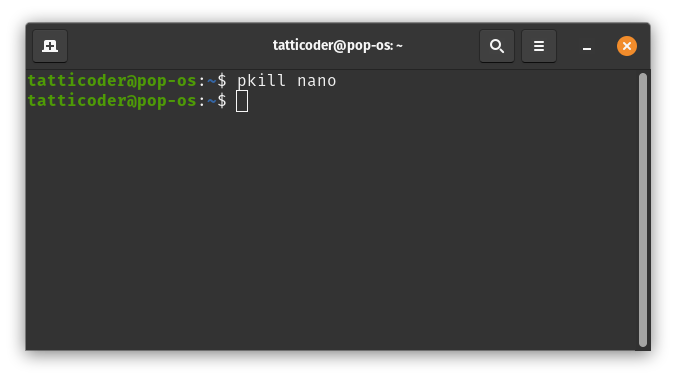
The pkill command simplifies process termination by allowing you to kill processes based on their names rather than PIDs:
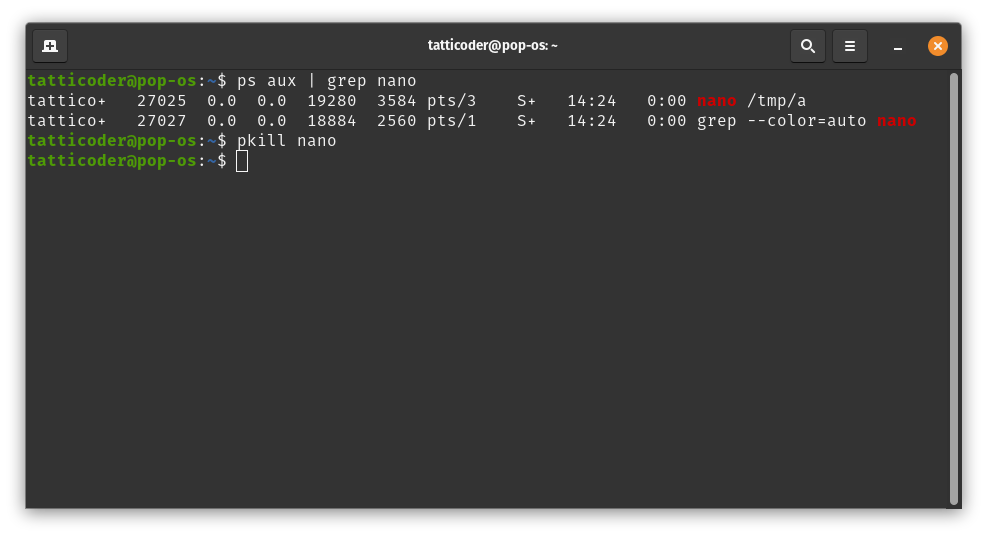
Basic usage: To kill a process by name, simply type: pkill process_name This will terminate all processes with “process_name” in their names.
Case-insensitive matching: If you need clarification on the exact capitalization of the process name, use the -i option. For instance: pkill -i firefox will match “Firefox”, “firefox”, or any other case variation.
How to Kill a Process Using the killall Command
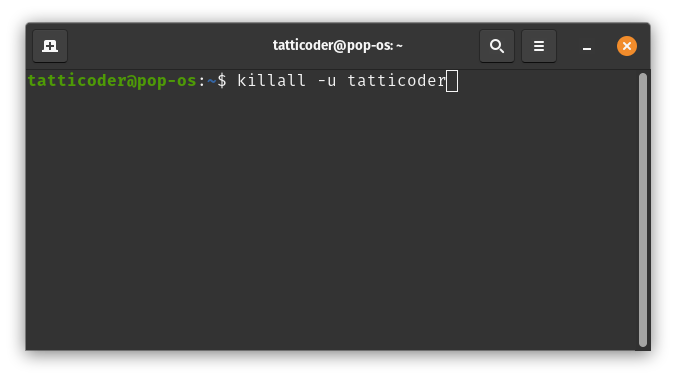
The killall command is similar to pkill but requires an exact match of the process name:
Basic usage: To kill all processes with an exact name match: killall process_name
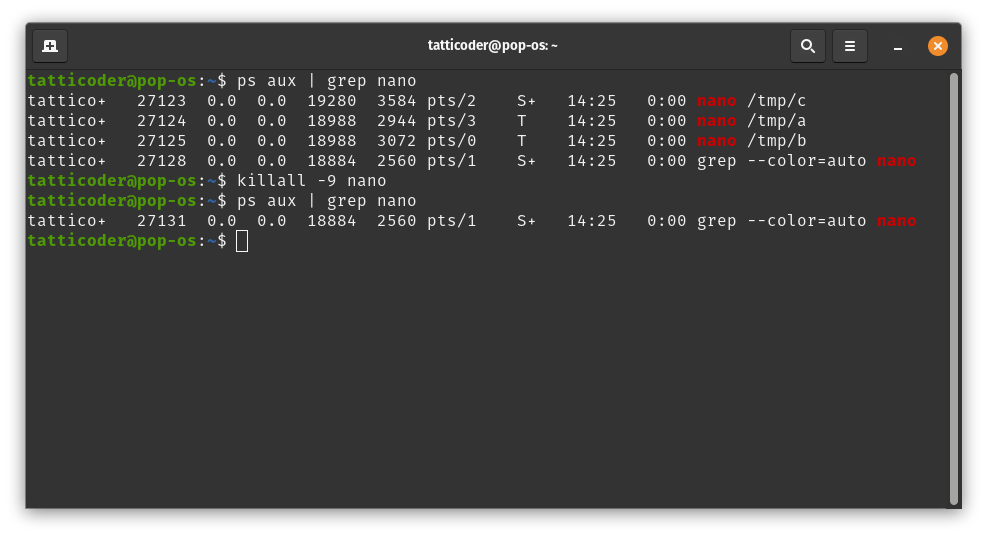
Forceful termination: For stubborn processes use the -9 option (equivalent to SIGKILL): killall -9 process_name
Killing processes by name is often more convenient than using PIDs. There are several ways to do this:
Using pkill: The simplest method is by running the following command: pkill process_name. Don’t forget to replace process_name with the name of the process you are trying to kill.
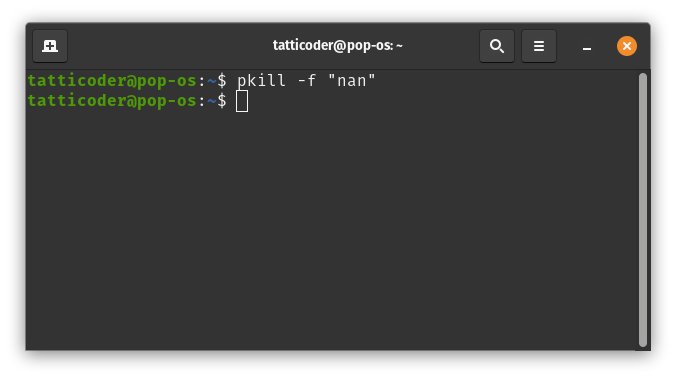
Partial name matching: Use the -f option to match a substring in the process name for more flexible matching. This is useful for processes with long or complex names. The syntax of this command is as follows:
pkill -f "partial_process_name"
For example, pkill -f "firefox" would match any process with “firefox” anywhere in its command line.
How to Kill a Process in Linux with Bash Script
Creating a bash script for process termination can be helpful for repetitive tasks. Follow the steps below to avoid typing the long and complex commands:
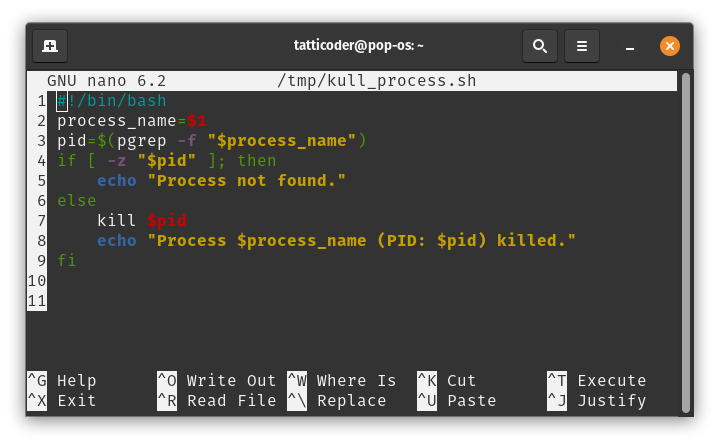
Create the script: Use a text editor to create a file named kill_process.sh. For example, you can use the nano editor to create the file using the following command: nano kill_process.sh.
Add the script content: After creating the file, paste the following content into it:
#!/bin/bash
process_name=$1
pid=$(pgrep -f "$process_name")
if [ -z "$pid" ]; then
    echo "Process not found."
else
    kill $pid
    echo "Process $process_name (PID: $pid) killed."
fi
Once you add the content, you can save it and exit it from the file editor. This script takes a process name as an argument, finds its PID, and terminates it.
Before you can execute the script, you need to make it executable. Change the file permissions by executing the following command to make it executable:
chmod +x kill_process.sh
After changing the file permissions, you can run the script by simply typing its name in the command line, followed by the name of the process you want to kill. For example:
./kill_process.sh firefox
The above command will attempt to kill a process named “firefox” on your computer.
Linux Process Management: At a Glance
This table provides a quick reference for common commands used to manage processes directly from the command line.
Action / Goal
Bash Command Example
When to Use It
Kill a process by its PID
kill 1234
The standard way to terminate a process when you know its exact PID. This sends a graceful shutdown signal (SIGTERM).
Force-kill a process by PID
kill -9 1234
A last resort to forcibly terminate a non-responsive process. This sends a SIGKILL signal that cannot be ignored.
Kill multiple specific processes
kill 1234 5678
When you have a specific list of PIDs, you need to terminate all at once.
Kill a process by partial name
pkill 'node'
To conveniently kill a process that matches a name or pattern, without needing to find the PID first.
Kill all processes with an exact name
killall 'firefox'
To terminate all instances of a specific program (e.g., all open Firefox windows). It’s safer than pkill if other processes have similar names.
Kill all processes owned by a user
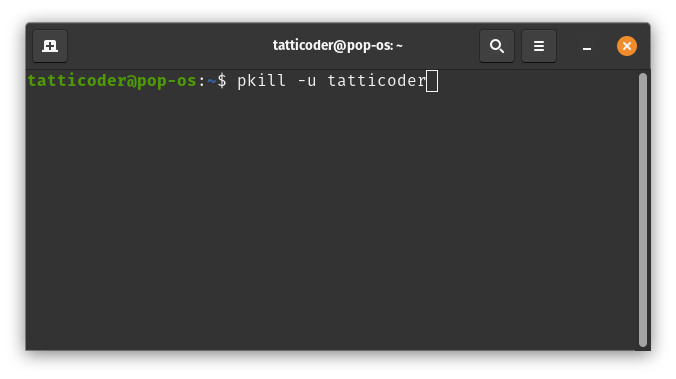
pkill -u 'Alex'
To terminate all processes running under a specific user account, often for administrative or security reasons.
Wrapping Up
In this post, we’ve explored various methods for killing processes in Linux from the command line. From using the kill command with a process ID to tools such as pkill and killall, you should now understand how to terminate unwanted or misbehaving processes on your Linux system.
While a good understanding of the Linux command line helps manage your website, it is not a requirement.
With the help of a hosting platform like RunCloud, you can easily manage your Linux server without getting bogged down in the technical details.
RunCloud provides a user-friendly interface that simplifies server management, allowing you to focus on building and growing your online presence.
Whether you’re a seasoned Linux user or just getting started, RunCloud makes it easy to deploy, monitor, and handle mundane tasks like performing regular backups.
Ready to take your website to the next level? Sign up for RunCloud todayand let us handle the Linux management so you can spend more time on what matters most – your business.
FAQs on Killing Linux Processes
How do you kill unnecessary processes in Linux?
To kill unnecessary processes in Linux, you can use commands such as kill, pkill, or killall to terminate the unwanted processes based on their process ID (PID) or name.
What command can you use to kill a process?
The kill -9 PID command, which sends the SIGKILL signal, can be used to forcefully terminate a process that is not responding to a regular termination signal.
How do you find the killed process in Linux?
To find a killed process in Linux, you can use the ps command to list all running processes or the pgrep command to search for processes by name.
How do I gracefully shut down a process in Linux?
To gracefully shut down a process in Linux, you can use the kill command without any signal options, which will send the SIGTERM signal and allow the process to perform cleanup operations before exiting.
How do you end a process by keystroke?
In Linux, you can use the Ctrl+C keyboard shortcut to interrupt and terminate the currently running foreground process.
How do you abort a run in Linux?
To abort a running process in Linux, you can use the Ctrl+C keyboard shortcut. This will send the SIGINT signal and interrupt the process’s execution.
Which key is used to cancel a process?
The Ctrl+C keyboard shortcut is commonly used to cancel or interrupt the currently running process in Linux.
How do I kill a high CPU process in Linux?
In Linux, you can use the top command to identify a process that consumes a large amount of CPU resources and then use the kill command to terminate it.
What’s the difference between a “job” and a “process” in Linux
A process is any program that is currently running on the operating system. The Linux kernel manages all processes. A job is a shell-level concept that manages one or more processes within a single terminal session. Think of it as a label for a task you’re running. You can move a job to the background or foreground, but the kernel still manages it as a process.
How can I see processes in a tree-like view?
It’s useful to see which processes were started by other processes (parent-child relationships). The pstree command is perfect for this, as it gives you a visual map of everything running on your system, which can be very helpful for troubleshooting.
Few WordPress errors are as frustrating as seeing the message “Error Establishing a Database Connection.” It instantly takes your site offline, blocks both visitors and admins, and can cause serious downtime if not resolved quickly.
This error occurs when WordPress cannot connect to your MySQL database, where all your posts, pages, and settings are stored. Without that connection, WordPress has nothing to display.
The good news is that this issue is common and almost always fixable.
In this guide, we’ll walk through exactly how to fix the error establishing a database connection in WordPress, step by step. From checking your wp-config.php file to repairing corrupted tables and optimizing your server, you’ll learn the proven fixes that quickly get your site back online.
Let’s get started!
What Causes ‘Error Establishing a Database Connection’ in WordPress?
Before we dive into the fix, it’s helpful to understand what triggers this error.:
Incorrect Database Credentials: This is the most common reason for this error. The wp-config.php file contains the database name, username, password, and host. If any of these are wrong, the connection will be refused.
Corrupted WordPress Database: Your database can become corrupted due to a faulty plugin update, a theme installation gone wrong, or a server glitch.
Corrupted WordPress Core Files: Although less common for this specific error, a damaged core file related to the database functions can cause the connection to fail.
Unresponsive Database Server: The server where your database is hosted might be down, overloaded, or experiencing technical issues. This is a problem on your hosting provider’s end.
Sudden Traffic Spikes: A massive surge in traffic can overwhelm your hosting server and temporarily make the database unresponsive to new connection requests.
Step-by-Step Checklist to Fix ‘Error Establishing a Database Connection‘
Follow these steps in order, as they are arranged from the most common and easiest fix to the least common.
1. Back Up WordPress Website Before Troubleshooting
Before making any changes, always create a full backup of your website. This protects your files and database if something goes wrong. RunCloud users can do this in one click from the dashboard.
If you’re not using RunCloud, you can:
Use your hosting control panel (cPanel, Plesk, etc.) to generate and download a backup.
Download your WordPress files via FTP and export your database through phpMyAdmin.
Skipping this step risks turning a small fix into a much bigger problem.
2. Check and Update wp-config.php Database Credentials
Incorrect credentials are the most common cause of this error. To check and fix them:
Connect to your site using FTP or your host’s File Manager. Open the wp-config.php file in the root WordPress folder. RunCloud users can edit this file directly from the dashboard.
Look for these lines of code:
// ** MySQL settings - You can get this info from your web host ** //
/** The name of the database for WordPress */
define( 'DB_NAME', 'your_database_name' );
/** MySQL database username */
define( 'DB_USER', 'your_username' );
/** MySQL database password */
define( 'DB_PASSWORD', 'your_password' );
/** MySQL hostname */
define( 'DB_HOST', 'localhost' );
Find your database details in your hosting control panel (often under “MySQL Databases”).
Make sure the DB_NAME, DB_USER, DB_PASSWORD, and DB_HOST values match exactly. Note: most hosts use “localhost” for DB_HOST, but some require a specific server name or IP.
If anything doesn’t match, update wp-config.php, save the file, and reload your site.
3. Repair WordPress Database via phpMyAdmin or WP-CLI
If your database tables are corrupted, WordPress cannot read them. Luckily, WordPress includes a built-in repair tool. This process fixes errors without deleting your data.
Open your wp-config.php file.
Add this line just above /* That's all, stop editing! Happy publishing. */:
define('WP_ALLOW_REPAIR', true);
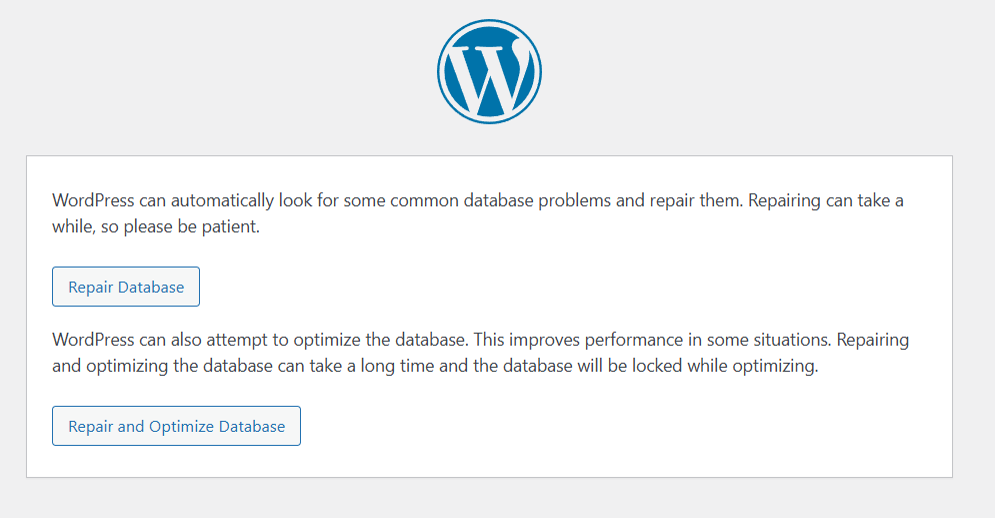
Save the file, then go to: http://runcloud-demo.com/wp-admin/maint/repair.php.
On that page, click “Repair Database.”
When it finishes, delete the line you added in wp-config.php. Leaving it in place is a security risk.
5. Reinstall or Replace Corrupted WordPress Core Files
If a WordPress core file is corrupted, replacing it with a clean copy usually fixes the issue. Don’t worry – this won’t affect your themes, plugins, or content.
Download the latest version of WordPress from WordPress.org.
Unzip the file on your computer.
Delete the wp-content folder and wp-config-sample.php file from the unzipped package.
Connect to your site via FTP and upload the remaining files, overwriting the old ones.
This refreshes all core files with clean copies without touching your content.
If the error persists, the problem may be with your hosting server rather than WordPress.
Check Server Status: Most hosting providers publish updates about outages or maintenance. RunCloud does not provide server status updates, so check directly with your cloud provider (e.g., AWS, Vultr, DigitalOcean).
Test Other Sites: If you host multiple sites on the same account, check if they are also down. If they are, it’s likely a server-wide issue.
Contact Support: Open a ticket with your provider. Tell them you’re seeing an “Error Establishing a Database Connection” and that you’ve already confirmed your wp-config.php credentials. Ask them to confirm that the MySQL service is running.
7. Optimize WordPress Database and Enable Caching
If the error followed a sudden traffic spike, it may disappear once traffic drops. But this is a clear sign your site needs optimization.
With RunCloud, you can enable NGINX FastCGI caching in one click, or add Redis or Memcached directly from the dashboard. This helps your site handle heavy database loads without needing command-line tools. For detailed guides, see:
Advanced Troubleshooting for WordPress Database Connection Errors
If you’ve worked through the standard checklist and are still facing the error, it’s time to investigate deeper server-level configurations and resource limitations. These advanced steps address less common but critical issues that often require more direct control over your hosting environment.
1. Update DB_HOST in wp-config.php
Most setups use localhost for DB_HOST, but some hosts run the database on a separate server. In those cases, you’ll need to replace localhost with the hostname or IP address your provider gives you (e.g., mysql.yourhost.com).
2. Increase PHP memory
Sometimes the error appears because PHP runs out of memory while processing a heavy query. To increase it, add this line to wp-config.php:
define('WP_MEMORY_LIMIT', '256M');
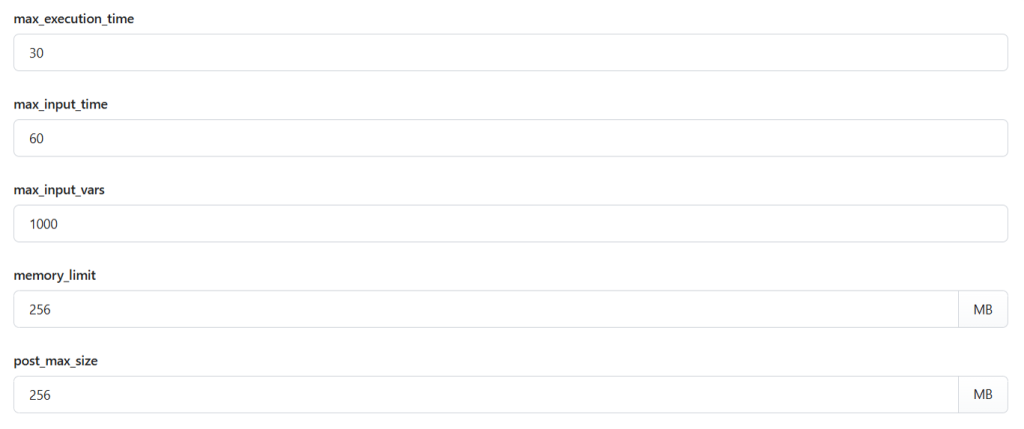
However, server-level settings can sometimes override this change. Manually editing the php.ini file via SSH is the most reliable method, but it can be intimidating for many users.
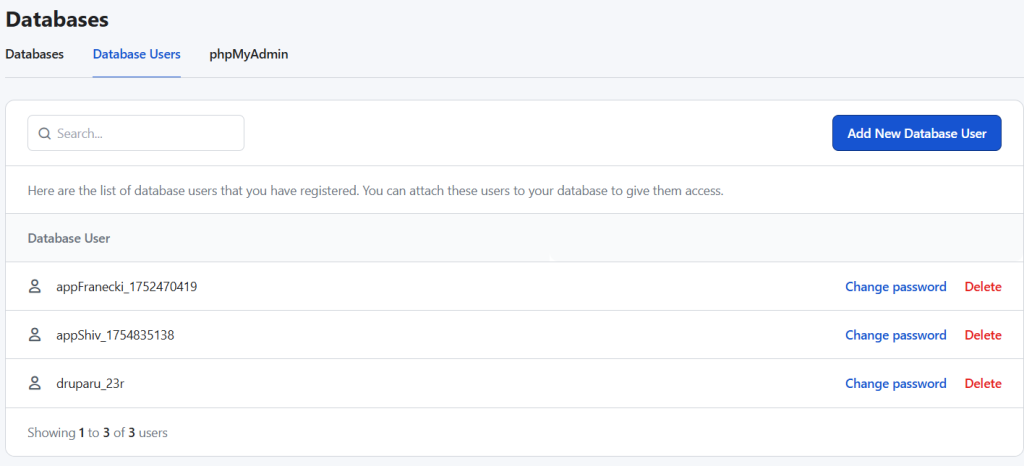
RunCloud gives you direct, graphical control over your server’s PHP settings. From your web application’s dashboard, you can select a new memory_limit via a text box and other critical values like max_execution_time and upload_max_filesize. This removes the risk of syntax errors in configuration files and instantly applies the changes only to the selected application.
3. Consider migrating to better hosting
If you see this error often, the problem may be your hosting provider. Shared hosting, in particular, is prone to overloaded databases. Moving to a VPS (DigitalOcean, Vultr, AWS, etc.) provides more stability.
The migration process can be daunting. It involves server provisioning, software installation (NGINX, PHP, MySQL), security configurations, and moving your site’s files and database.
RunCloud is designed to make this transition seamless. You can connect it to any VPS provider, and it will automatically provision, optimize, and secure the server with a modern server stack in minutes. This makes managing and deploying a WordPress website and any web application easy.
Wrapping Up: Preventing Database Connection Errors in WordPress
Fixing the “Error Establishing a Database Connection” is one thing – making sure it doesn’t happen again is even more important. Regular backups, reliable hosting, proper caching, and a clean server setup reduce the chances of future downtime.
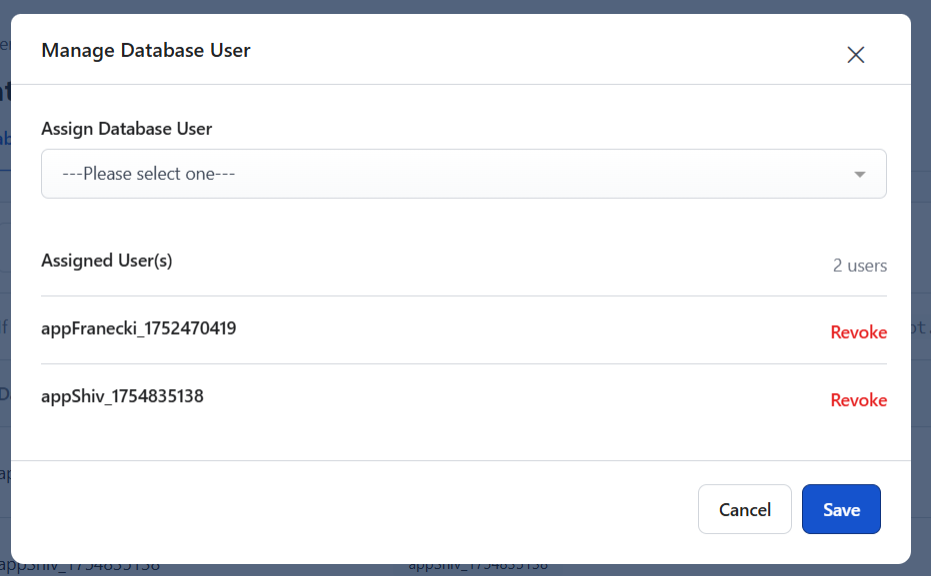
That’s where RunCloud helps. Instead of juggling FTP clients, php.ini edits, and command-line fixes, you get a simple dashboard to manage everything – from database users to PHP settings and caching – in just a few clicks.
If you want fewer headaches, faster performance, and a WordPress site that stays online even under heavy load, RunCloud is built for you.
FAQs on ‘Error Establishing a Database Connection’ in WordPress
Why is my WordPress site not connecting to the database?
Your site cannot connect because the PHP code is blocked from accessing the MySQL database where your content is stored. This is most often due to incorrect database credentials in your wp-config.php file.
How do I fix database errors in cPanel?
In cPanel, you can fix this by using the “MySQL Databases” tool to check the database username and reset its password. Then, you can use the integrated phpMyAdmin tool to select your database and run the “Repair table” command on any corrupted tables. Platforms like RunCloud offer a more modern interface for these tasks, making user management and phpMyAdmin access much quicker.
What causes database issues on localhost XAMPP?
MySQL is usually not running. Open the XAMPP control panel and check that the MySQL module is started (green status). Also, confirm that your wp-config.php settings match the XAMPP defaults – DB_USER is root, and DB_PASSWORD is blank.
How do I repair a corrupted WordPress database?
Add the define(‘WP_ALLOW_REPAIR’, true); line to your wp-config.php file to activate WordPress’s built-in database repair script. Alternatively, you can use phpMyAdmin to select all your database tables and choose the “Repair table” option. Server management panels like RunCloud provide one-click access to phpMyAdmin, simplifying the process of performing these database repairs.
Why is my database error only happening on my iPhone?
This is almost always a caching problem; your iPhone is likely viewing an old, cached version of the error page that no longer exists. Clear your mobile browser’s cache or purge your site’s caching plugin to resolve it. If you use server-level caching, a tool like RunCloud allows you to easily manage and purge the NGINX FastCGI cache directly from your dashboard.
How can I check the MySQL server status in WordPress hosting?
You’ll need to contact support on most shared hosting to confirm the MySQL server is operational. However, you can manage this using a VPS through a server panel. RunCloud provides a real-time server health monitoring dashboard that displays the status of essential services like MySQL, NGINX, and Redis.
What should I do if database errors appear intermittently?
Intermittent errors suggest your database server is temporarily overloaded, often due to high traffic spikes or slow database queries from a plugin. This is a resource issue, and you should enable an object caching solution to reduce the database load. With RunCloud’s server health monitoring, you can watch for spikes in CPU and memory usage to diagnose when your server is under strain.
On Linux, disk space can disappear fast. This guide shows you how to spot the biggest files and directories quickly, understand size mismatches, and free up space safely.
How Do You Check Disk Usage With Built-In Linux Tools?
In Linux Bash, you have several built-in utilities and commands that you can use to check and monitor disk usage. These utilities are readily available and don’t require any additional installations.
Here are some of the commonly used built-in utilities for checking disk usage in Linux:
How Do You Find Large Files in Linux?
Most Linux systems include the du tool. Use it to see which files and folders use the most space.
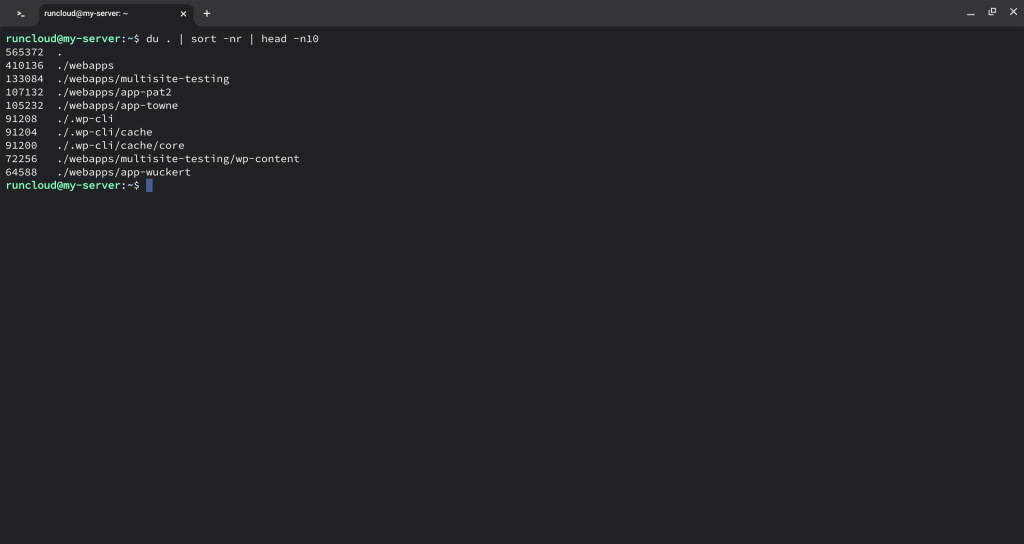
To find the top 10 largest files from the current directory, run the following command in your Linux terminal:
du . | sort -nr | head -n10
This command utilizes the du command to display disk usage, sort to sort the results in descending order, and head to display the top 10 largest files.
How Do You Check the Largest Directories in Linux?
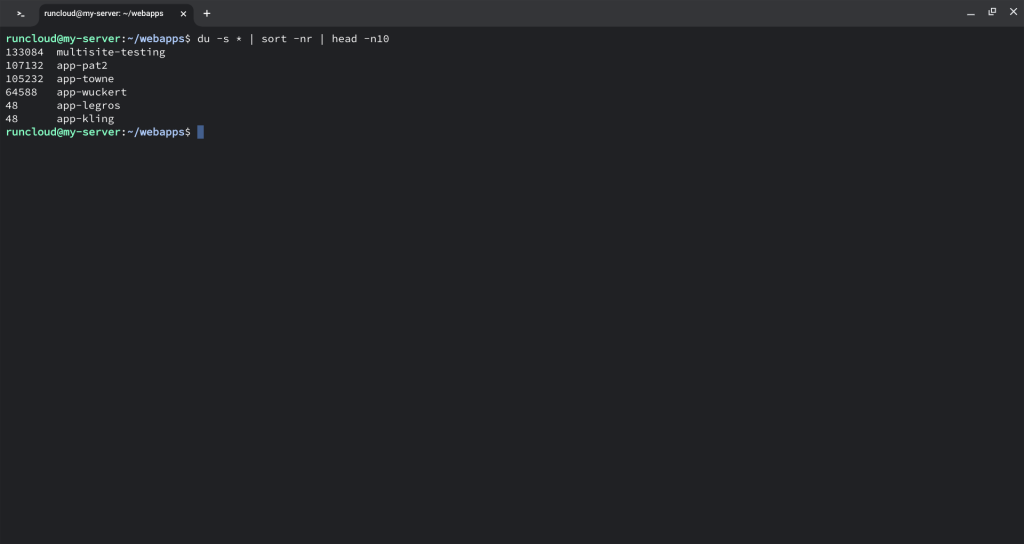
Sometimes thousands of small files fill a disk faster than a few large ones. To list the largest directories in the current directory, you can run the following command in your terminal:
du -s * | sort -nr | head -n10
This command summarizes directory sizes, sorts them, and shows the top 10 largest directories in the current working directory.
How Do You Find Large Files With GNU Tools in Linux?
You can also use clever bash scripting with the find command to list the biggest files and directories.
Method 1 – Identify Large Files With find
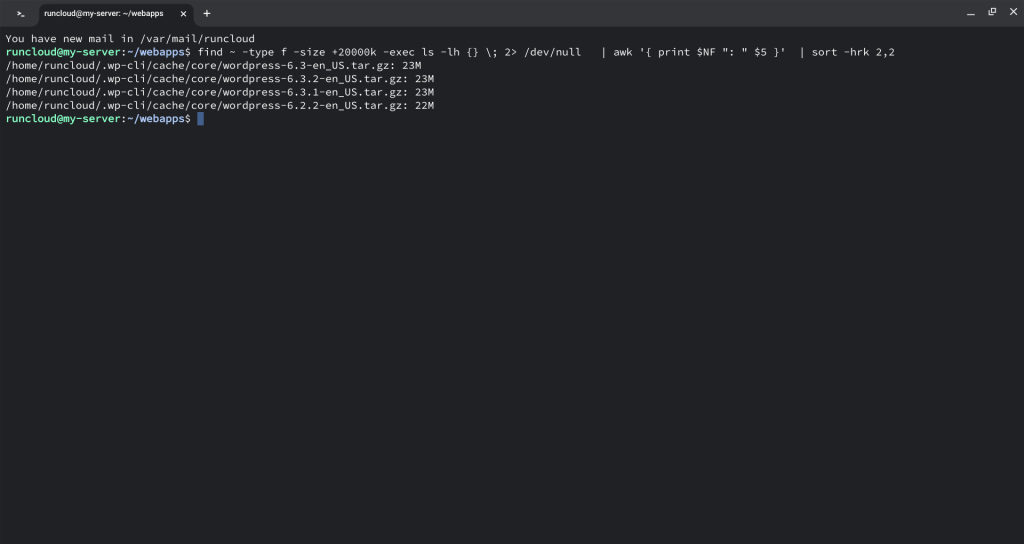
The following command can be used to find and list files larger than 20,000 kilobytes (20 megabytes) in the user’s home directory (~). It then sorts these files by size in reverse order and displays the file names along with their respective sizes:
Here’s a step-by-step explanation of how this command works:
find ~ -type f -size +20000k: This part of the command initiates the search for files in the home directory (~). If you want to use a different directory, replace ~ with the path of your directory. The -type f option specifies that we are looking for regular files, and the -size +20000k option filters files larger than 20,000 kilobytes.
-exec ls -lh {} \;: For each file that matches the criteria, the find command executes the ls -lh command, which lists detailed information about the file. The {} placeholder is replaced with the current file’s name during execution.
2> /dev/null: This part redirects any error messages (specifically, standard error) to /dev/null, effectively suppressing them. This is done to prevent error messages from being displayed in the terminal.
| awk '{ print $NF ": " $5 }': The awk command processes the output from the previous command. It extracts the file name (represented as $NF) and the file size (represented as $5) and prints them in the format “filename: size”.
| sort -hrk 2,2: The final part of the command uses sort to arrange the file entries. The options used are as follows:
-h: This tells sort to perform a human-readable sort, which is useful for sizes with suffixes like “K” or “M”.
-r: This specifies a reverse order sort, listing the largest files first.
-k 2,2: This instructs sort to use the second field (the size) as the key for sorting.
Method 2 – List the Biggest Files in Size Order
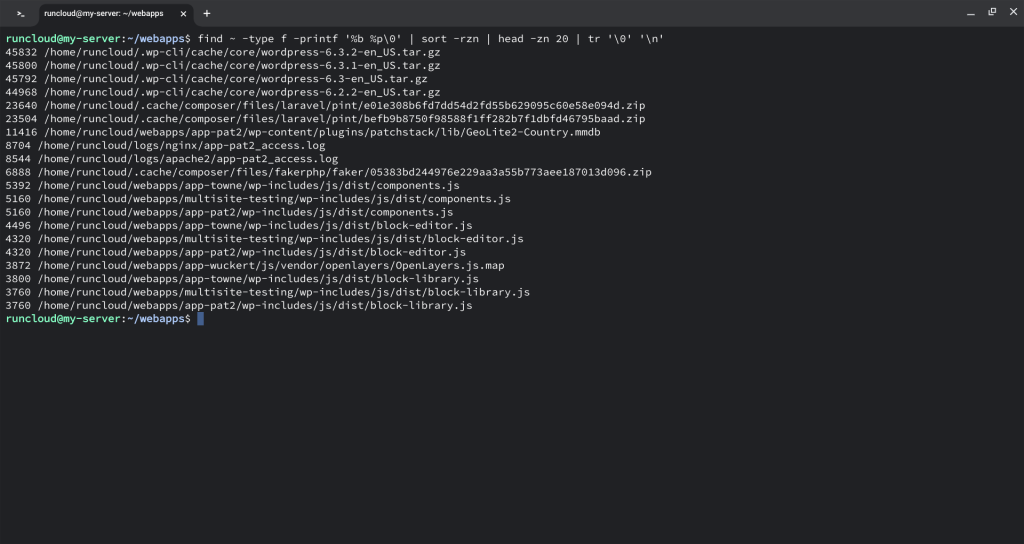
Alternatively, you can use the following command to find and display information about the top 20 largest regular files in the user’s home directory (~). It reports the size of each file and its path, sorted in reverse order by size.
find ~ -type f -printf '%b %p\0' | sort -rzn | head -zn 20 | tr '\0' '\n'
Here’s a step-by-step explanation of how this command works:
find ~ -type f -printf '%b %p\0': This part of the command initiates a search for regular files (-type f) in the home directory (~). For each file found, it uses the -printf option to format the output as follows:
%b: Represents the number of 512-byte blocks allocated for the file.
%p: Represents the file’s path.
\0: Terminates each output entry with a null character (\0). The null character is used to separate file entries, and is especially important when dealing with file paths that contain spaces or special characters.
| sort -rzn: The output from the find command is then piped (|) to the sort command for sorting. The following options are used with sort:
-r: Performs a reverse order sort, arranging the entries from largest to smallest.
-z: Informs sort that the input entries are null-terminated, which is why the null character (\0) was added at the end of each entry by the find command.
-n: Specifies a numerical sort, ensuring that file sizes are sorted based on their numeric values rather than lexicographically.
| head -zn 20: After the sorted list is generated by sort, the output is piped to the head command.
-z: Informs head that the input entries are null-terminated.
-n 20: Limits the output to the first 20 entries, which are the 20 largest files based on size.
| tr '\0' '\n': Finally, the tr (translate) command is used to replace the null characters (\0) in the output with newline characters (\n). This is done to format the output in a more human-readable way, with each file and its size on a separate line.
Note: You can also use the above bash script in conjunction with other bash commands such as numfmt to convert file sizes into human-readable formats. For example, you can do something like this:
To check how much storage memory each directory occupies, use the following commands:
cd /
du -sh * | grep G
The above command shows memory usage by directories that occupy a volume measured in Gigabytes. It helps you decide which directories or files you may want to consider for deletion or optimization.
Best Third-Party Tools for Disk Usage on Linux
In addition to built-in utilities, there are many third party tools that you can use to assess disk usage in Linux Bash.
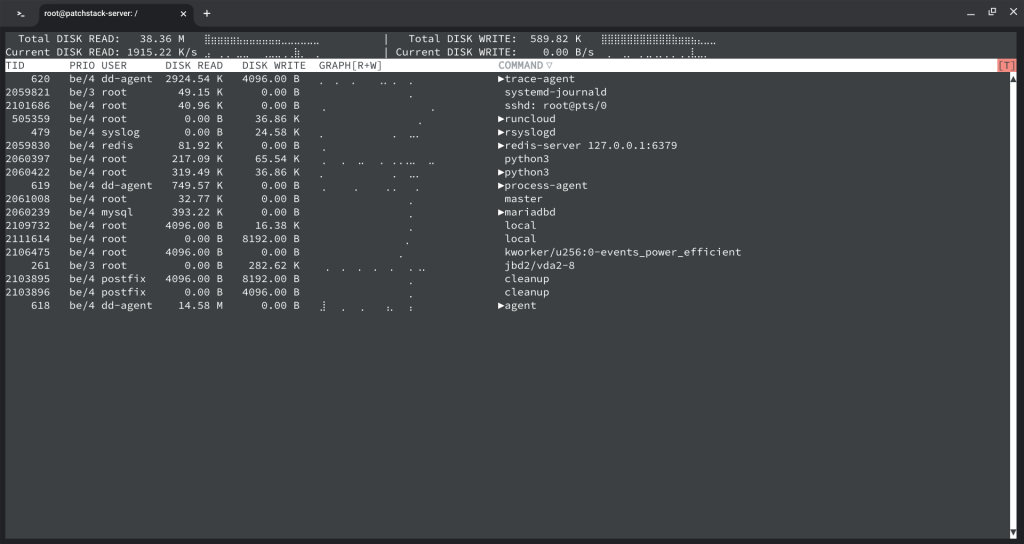
iotop shows which processes are reading and writing to disk right now. It helps you spot I/O bottlenecks and noisy neighbours.
Installation: You can use the apt package manager to install iotop-c:
sudo apt update
sudo apt install iotop-c
Usage: After installation, you can run iotop to monitor and assess disk I/O usage. The -o option sorts the output by disk read or write, and -P displays paths. The -a option shows accumulated values, which can be useful for identifying processes with high disk I/O over time.
Here’s an example of how to run iotop:
iotop -oPa
How to Use gdu to Scan Disk Usage
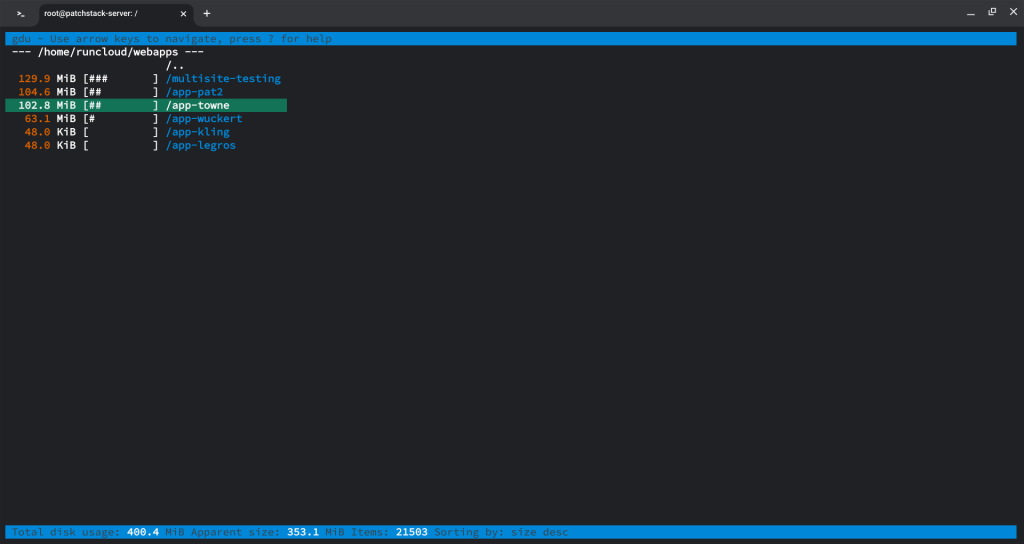
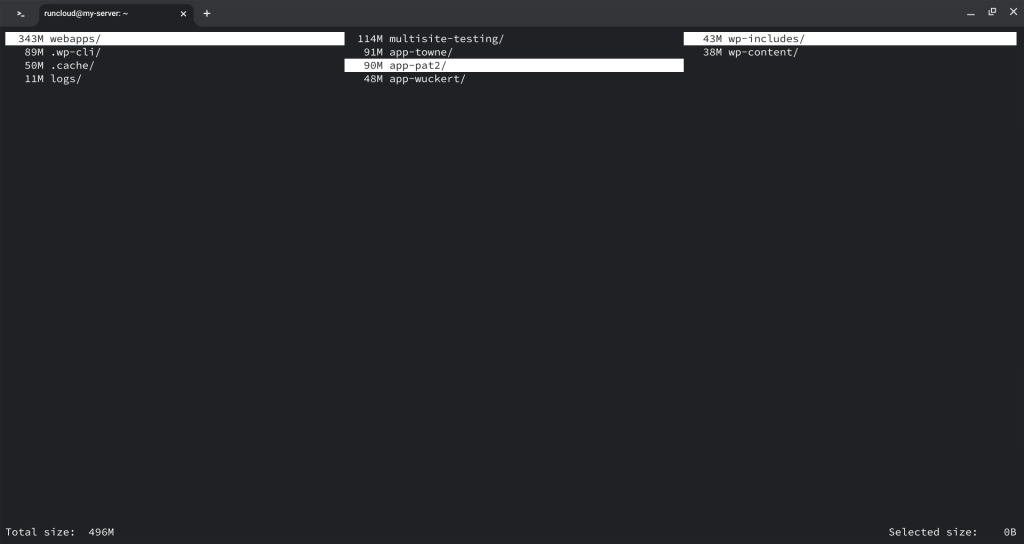
gdu is a fast, terminal-based disk usage analyzer. Use it to scan a path and navigate heavy folders.
Usage: To analyze disk usage, run gdu with the desired directory as an argument. Use arrow keys on your keyboard to navigate different folders.
How to Use dua for Disk Usage
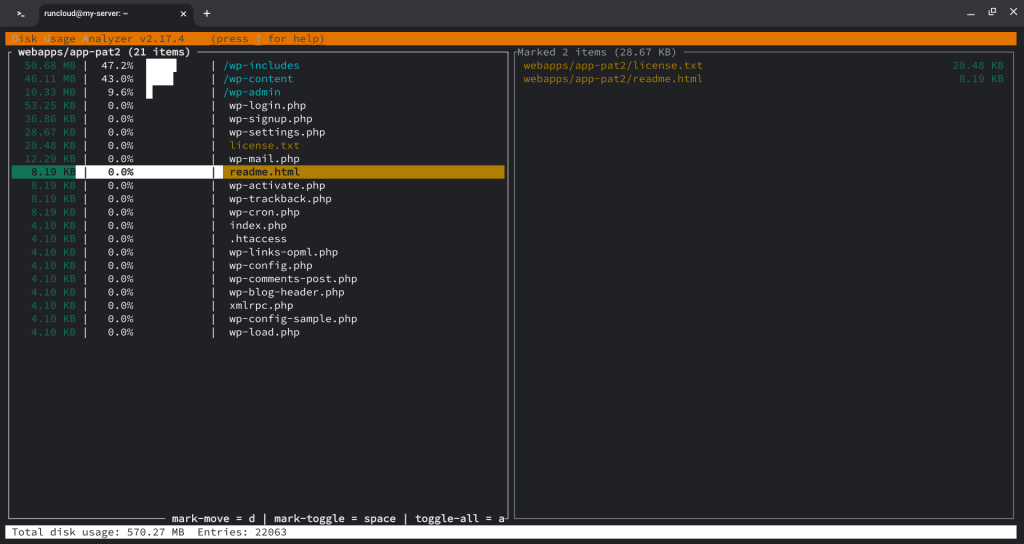
dua helps you assess disk usage quickly and offers an interactive mode for safe cleanup.The dua command features an interactive mode in which you can explore your file system and choose to delete files and directories to free up disk space. It is designed to minimize the risk of accidental deletions by using a multi-stage process, making it safe for exploration.
Installation: Dua can be installed by using the binary release for your specific system from the Dua repository.
Usage:
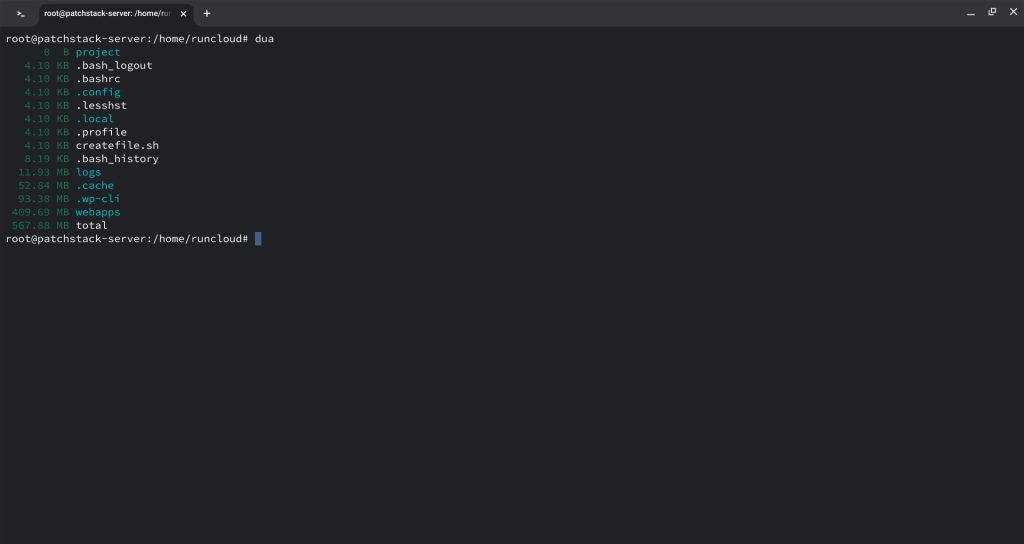
Run dua to count the space used in the current working directory.
Execute dua * to count the space used in all directories that are not hidden.
To learn about additional functionality such as the aggregate feature, use the dua aggregate --help command.
To launch into interactive mode, run dua i
How to Use godu to Analyse Disk Usage
godu identifies space-hungry files and directories with an interactive view.
Usage: Run godu to analyze disk usage for a specific directory. Use the arrow keys on the keyboard to navigate through the file system.
How to Use ncdu to Explore Disk Usage
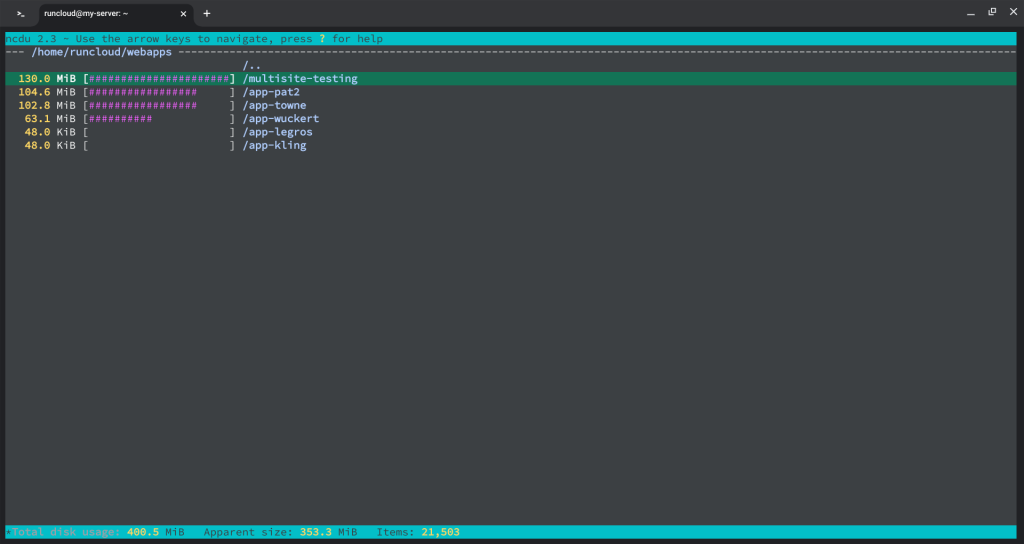
ncdu is a terminal disk usage explorer. It scans quickly and lets you drill down and delete from the same screen.
Installation: ncdu is an interactive disk usage analyzer that is available to most package managers. You can install it using apt on Debian-based systems:
sudo apt update
sudo apt install ncdu
Usage: Run ncdu to analyze disk usage in an interactive text-based interface:
These tools provide various ways to assess disk usage, and you can choose the one that best suits your needs and preferences. Some offer graphical interfaces, while others provide command-line-based analyses.
Why Do ls and du Show Different Sizes?
ls -l and du report different things, so sizes can look mismatched. Here’s what each one shows:
Apparent Size
This is the number of bytes that an application would read if it went from the beginning of the file to the end. It’s the “logical” size of the file. This is the value you see in the output of ls -l.
Actual Disk Usage (Blocks)
This is the amount of physical space the file actually occupies on the disk. Filesystems allocate space in fixed-size chunks called blocks (e.g., 4 Kilobytes). Even a file containing a single character will consume one full 4KB block. The du and quota commands report on this actual block usage.
This difference is most dramatically illustrated with sparse files. A sparse file is a file with “holes” where data has never been written. The filesystem is smart and does not allocate any physical disk blocks for these empty holes.
Compare Apparent vs. Actual Size on the CLI
Let’s create a 1 Gigabyte sparse file using the following command.
# Create a 1GB file instantly without writing any data to it
truncate -s 1G /tmp/sparse-file.img
Now, let’s measure it in two different ways:
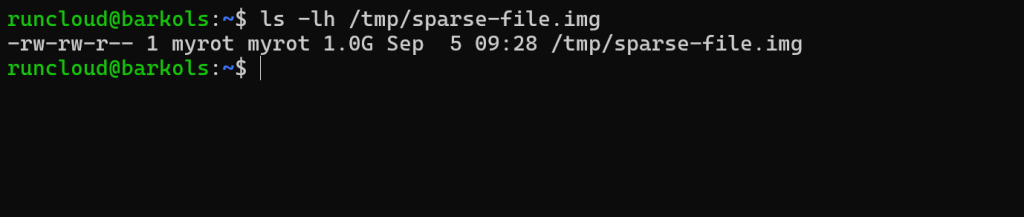
Check the Apparent Size with ls:
ls -lh /tmp/sparse-file.img
The ls command reads the file’s metadata and reports its logical size: a full Gigabyte.
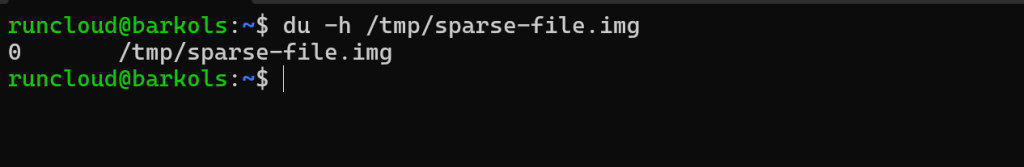
Check the Actual Disk Usage with du:
du -h /tmp/sparse-file.img
The du command inspects the blocks allocated by the filesystem and reports that it is using zero blocks of physical disk space.
This is an extreme example, but it perfectly illustrates that a file can appear to be very large while consuming very little of your quota. This is used heavily in virtual machine disk images, database files, and other applications that pre-allocate large files.
How Do You Find Deleted but Open Files With lsof?
In Linux, when you delete a file with rm, you are only removing its name from the directory. The actual data on the disk is not freed until every process that has the file open finally closes it. This is the most likely cause of the large discrepancy in your case.
The du utility can’t see the file because its name is gone from the directory tree.
However, its data blocks are still allocated to your user ID.
The lsof (List Open Files) command is the perfect tool for finding these “phantom” files.
How to Use lsof to Locate Deleted Files
To find deleted files that are still open, use lsof with the link-count filter. The output is noisy, so filter by your user.
# The +L1 flag filters for files with a link count less than 1 (i.e., deleted)
# The grep command filters this system-wide list to only show your files
lsof +L1 | grep 'runcloud'
Replace runcloud with your actual username before running the above command.
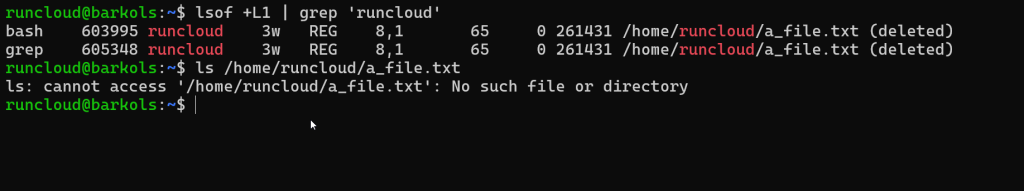
In the above example, we can clearly see that some files are still being identified by the lsof command even though they have been deleted and can not be accessed using the ls command.
How to Free Space From Deleted Files in Linux
If a deleted file is still open, stop the process holding it to release the space. Before you terminate the process, make sure you understand why it’s open.
kill <process ID>
After you run the kill command, the operating system will clean up the process, close the open file descriptor, and the filesystem will finally be able to free the data blocks.
Linux Disk Usage Tools – At a Glance
Tool Name
CLI Command to Run
What it Displays
Disk Free
df -h
Overall usage and free space for all mounted filesystems.
Disk Usage
du -sh *
Summarized disk usage for each file and directory in the current location.
Find Command (for large files)
find . -type f -size +1G
A list of all files larger than a specified size (e.g., 1 Gigabyte).
Find and Sort Pipeline
find . -type f -exec du -h {} + | sort -rh
A sorted list of all files by size, from largest to smallest.
NCurses Disk Usage
ncdu
A very popular, interactive text-based analyzer to explore disk usage.
Go Disk Usage (gdu)
gdu
A fast, modern, and interactive disk usage analyzer.
Disk Usage Analyzer (dua)
dua interactive .
An interactive tool to view disk usage and delete files from its interface.
Go Disk Usage (godu)
godu
An interactive disk usage tool that can display a treemap in the terminal.
I/O Top
sudo iotop
Real-time disk read/write activity shows which processes are using the disk now.
Key Takeaways
You now know several ways to find which files and directories are using the most space in Linux — from built-in commands like du and find to interactive tools like ncdu and gdu. These methods help you act fast when disk space runs low, prevent downtime, and keep your systems healthy.
But constantly logging in and running these commands isn’t always practical. That’s where RunCloud helps.
With RunCloud, you get:
A clear dashboard showing disk usage, CPU, and memory in real time
Alerts before space runs out, so you can act early
A secure, browser-based file manager to clean up files without needing command-line access
By combining Linux’s flexibility with RunCloud’s visibility, you can keep your servers lean and reliable.
DNS cache can speed up internet access and improve browsing experiences by storing recent domain name lookups and their corresponding IP addresses.
Clearing this cache periodically can enhance your browsing speed and resolve connectivity issues.
Modern operating systems generally cache DNS lookup results and IP addresses to process requests more quickly. Whenever you write a URL in your browser, it sends a request to the DNS servers to “locate” the site. But instead of sending that request every single time, the browser often caches the information. This way, the next time you type in that address, the browser looks it up through the DNS cache, allowing it to return the results much faster.
However, cached DNS records can become outdated or corrupted over time, potentially leading to browsing issues, including connection errors or the display of outdated website versions. Flushing your DNS cache occasionally is a good practice to ensure you’re accessing up-to-date versions of websites and protecting yourself from security risks like DNS spoofing.
In this article we will explain how to flush the DNS cache on different operating systems, including Windows, macOS, and Linux, as well as detailing the several reasons why it is so important to flush the DNS regularly.
How to Flush DNS Cache on Different Operating Systems
How to Flush DNS Cache on Windows 10 & 11
If you’re using Windows 10 or 11, here are the steps you can follow to flush the DNS cache:
Click on Start, then search for Command Prompt. Right-click it and select “Run as Administrator.”
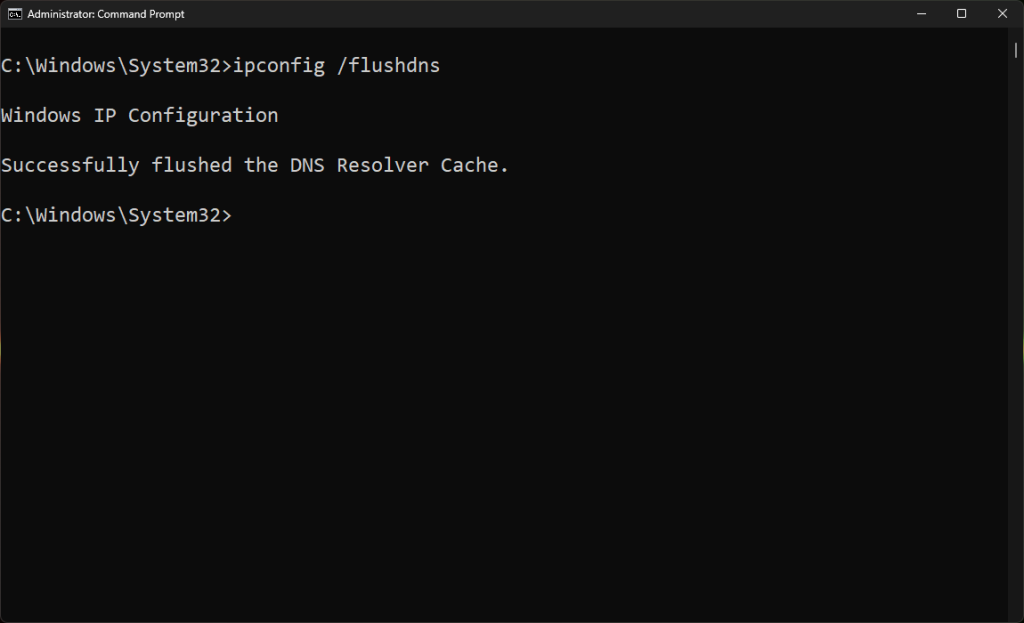
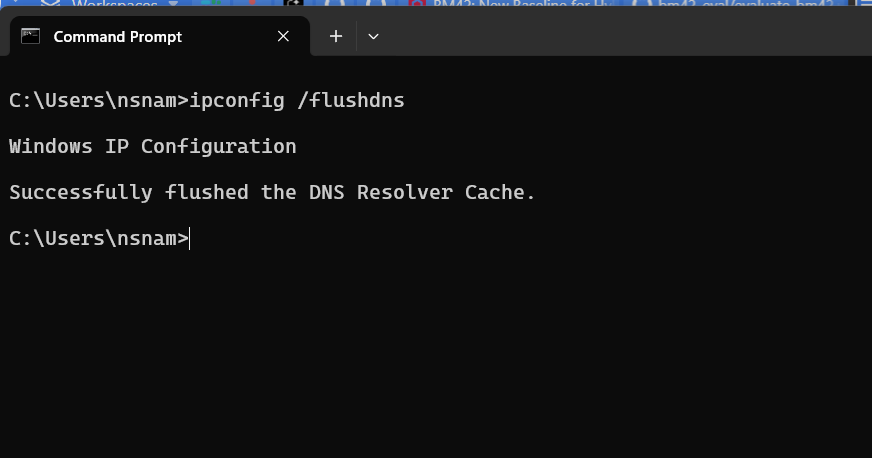
Once the Command Prompt is open, type ipconfig /flushdns and press Enter.
A message will appear confirming that the DNS Resolver Cache was flushed.
In addition to flushing the DNS, performing an IP release and renewal can help resolve network connection problems. Here’s how to do it:
How to Perform an IP Release, Renew, and DNS Flush on Windows
Open Command Prompt with administrative privileges.
Type ipconfig /release and press Enter to release the current IP address.
Next, type ipconfig /renew to obtain a new IP address.
Finally, type ipconfig /flushdns to clear the DNS cache.
How to Flush DNS Cache on macOS
Flushing the DNS cache on macOS involves using the Terminal app. Follow these steps:
Press cmd + space to open Spotlight Search.
Type Terminal and open the application (you can also find it in the Other section in the Launchpad).
Type the following command: sudo dscacheutil -flushcache; sudo killall -HUP mDNSResponder.
Enter your administrator password when prompted. Once you do, you will receive confirmation that the DNS cache has been flushed.
Note: The command can vary depending on your macOS version. Here’s how to check your macOS version:
Click on the Apple menu in the upper-left corner of your screen.
Select About This Mac.
Depending on your macOS version, use the appropriate command:
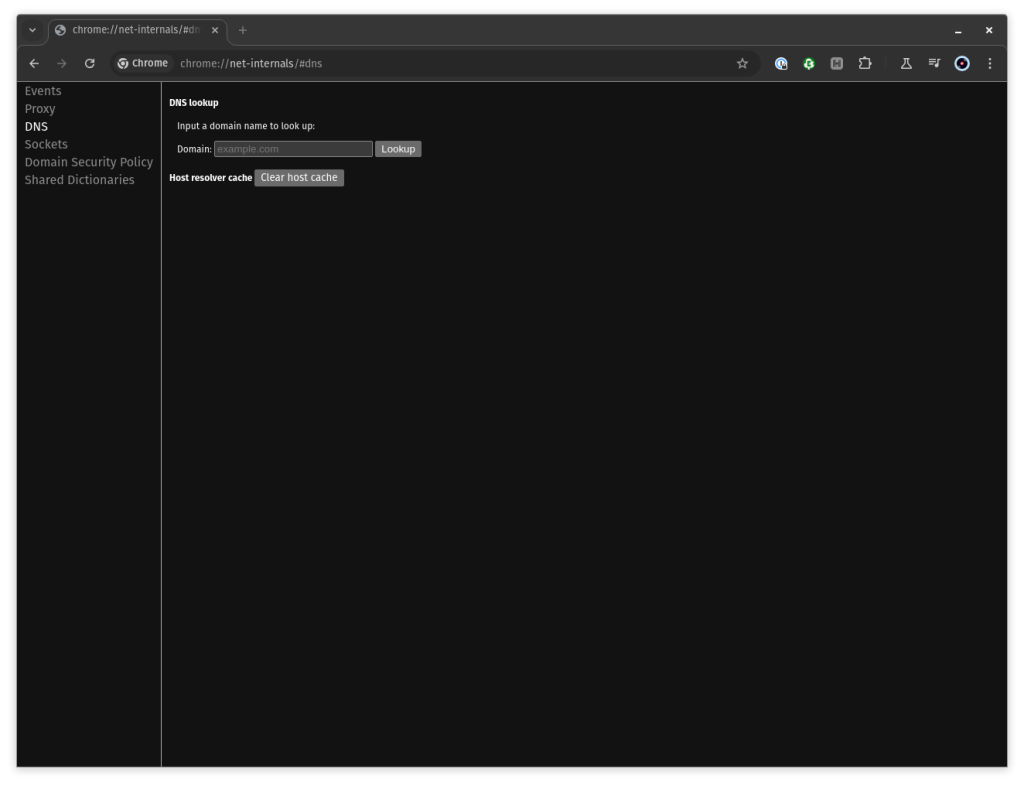
Click the Clear Host Cache button to flush the browser’s DNS cache.
This action will ensure that Chrome fetches fresh DNS data from the websites you visit.
Why Should You Flush Your DNS Cache?
There are several reasons why flushing the DNS cache periodically is important:
Resolve DNS Errors
If you’re encountering issues such as DNS_PROBE_FINISHED_NXDOMAIN or CONNECTION_TIMED_OUT, flushing the DNS cache may help resolve the problem. These errors often arise due to outdated or incorrect DNS information.
Speed Up DNS Propagation
After making changes to your DNS records, such as transferring a domain to a new hosting provider, DNS propagation can take time to fully update across the internet. Flushing your DNS cache ensures that your device picks up these changes more quickly, allowing you to see the updates sooner.
Prevent DNS Spoofing
DNS spoofing (or poisoning) occurs when an attacker manipulates DNS cache entries to redirect users to fraudulent or malicious websites. Flushing your DNS cache helps mitigate this risk by clearing any potentially corrupted entries.
Avoiding 404 Errors
A 404 error might indicate that your system is pulling up an outdated version of a website. Flushing the DNS cache ensures that your browser accesses the most current version of the site, which can help you avoid such errors.
Remove Old DNS Data
When you change DNS providers, such as switching to Google DNS or OpenDNS, it’s important to flush your DNS cache. This ensures that your system doesn’t use outdated data from the previous provider, helping to prevent connectivity issues.
After Action Report – Flush Your DNS Cache Periodically
Flushing your DNS cache is a simple yet effective way to resolve connectivity issues, speed up website access, and prevent security risks like DNS spoofing. Whether you’re using Windows, macOS, Linux, or even just browsing on Google Chrome, clearing your DNS cache periodically is a good habit to ensure optimal performance.
Do you regularly flush your DNS cache? Let us know if you have any tips or questions! Join the conversation below by leaving a comment! 💬
Wrapping Up
RunCloud is a powerful and easy-to-use platform that helps you manage your websites on any cloud server. With RunCloud, you don’t need to be a Linux expert to set up, secure, and optimize your web applications. You can do everything from a simple and intuitive dashboard, saving you time and hassle.
RunCloud supports various web servers, PHP versions, databases, and frameworks. You can also monitor your server performance, back up your data, and automate your tasks with RunCloud. Whether you are a developer, a freelancer, or a business owner, RunCloud can help you run your websites faster and smoother.
What are you waiting for? Join RunCloud today and enjoy the best web hosting solution for your websites. It’s free for 7 days, no strings attached!
Frequently Asked Questions (FAQ)
Is clearing the DNS cache safe?
Clearing the DNS cache is safe and does not affect your saved passwords, browser history, or other personal data. It removes outdated DNS information, ensuring your computer can fetch up-to-date DNS records.
How often should I flush my DNS cache?
There’s no hard rule on how often you should flush the DNS cache, but it’s a good idea to do it when you experience connection issues or DNS errors or after making changes to your network configuration (such as switching DNS providers).
Does flushing the DNS cache affect my internet speed?
Flushing the DNS cache may temporarily slow down website access on the first visit, as the DNS lookup will need to be performed again. However, once the cache is refreshed, your browser will store the new DNS records, which can speed up access to frequently visited websites.
How do I know if my DNS cache was successfully flushed?
After running the appropriate command to flush the DNS cache (such as ipconfig /flushdns on Windows), your system usually displays a message confirming that the DNS Resolver Cache was successfully flushed.
Will clearing the DNS cache fix DNS errors?
In many cases, yes. If you encounter errors like DNS_PROBE_FINISHED_NXDOMAIN or CONNECTION_TIMED_OUT, flushing the DNS cache can help resolve these problems by removing outdated or corrupted DNS entries.
If you use Google Chrome regularly, you’ve probably encountered the dreaded ERR_NETWORK_CHANGED error at least once. One moment, your page is loading fine – the next, you’re staring at a cryptic message that stops you in your tracks.
This error means Chrome has detected a sudden change in your internet connection. Maybe your Wi-Fi briefly dropped, you switched networks, or your VPN reconnected in the background. The good news is that it’s almost always easy to fix – and you don’t need to be a networking expert to do it.
In this guide, we’ll walk you through how to fix the ERR_NETWORK_CHANGED error in Chrome. You’ll learn the most common causes, how to troubleshoot them step-by-step, and how to get back online in minutes. We’ll start with quick fixes anyone can try, then move to more advanced solutions if the problem persists.
Let’s get started!
What Causes the ERR_NETWORK_CHANGED Error?
This error appears when Chrome loses track of its network route to a website. Even a split-second change in your internet connection can trigger it. Common causes include:
Unstable Wi-Fi Connection: Brief drops in signal or switching between your router’s 2.4GHz and 5GHz bands can interrupt Chrome’s connection.
Switching Between Networks: Moving from Ethernet to Wi-Fi, or from Wi-Fi to mobile data, forces Chrome to re-establish the connection.
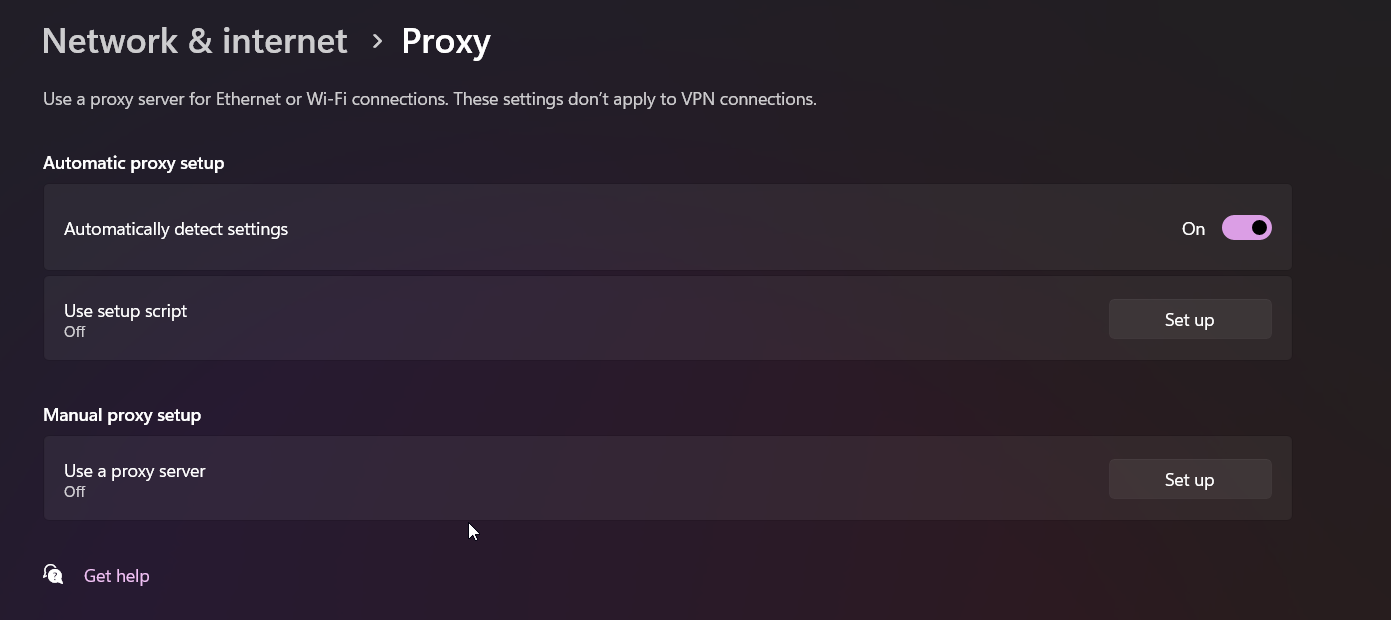
VPNs and Proxy Servers: Connecting, disconnecting, or switching VPN servers (or having a proxy enabled without realizing it) alters your network path.
Waking Your Computer from Sleep Mode: Your device’s network adapter may take a moment to reconnect, during which Chrome shows the error.
Faulty Network Hardware: Loose cables, an ageing router, or a failing modem can cause intermittent drops.
Outdated or Corrupt Network Drivers: If your network adapter drivers aren’t working properly, you’ll experience more frequent connection issues.
DNS Cache Issues: An outdated or corrupted DNS cache can send Chrome to the wrong address.
Knowing the cause helps you apply the right fix faster. Let’s go through the steps – starting with the quickest solutions that solve most cases.
How to Fix the ERR_NETWORK_CHANGED Error in Chrome
Now that you know what’s behind the ERR_NETWORK_CHANGED error, it’s time to fix it. We’ll start with quick, low-effort checks that solve most cases, then move into more targeted troubleshooting if the problem sticks around.
Important Instruction: Start with Solution 1 and work your way down the list. One of the first few steps will likely solve your problem, so you won’t need to complete the guide.
Step 1: Quick Fixes
These first steps take less than a minute each and solve most ERR_NETWORK_CHANGED errors. Think of them as a quick reset – no settings changed, just a fresh connection.
Solution 1: Reload the Page to Clear Temporary Connection Glitches
Before you do anything else, try the simplest fix of all. The network change may have been a temporary hiccup that has already resolved itself.
Click the reload icon (the circular arrow) next to the address bar in Chrome.
Or, press Ctrl + R on your keyboard (or Cmd + R on a Mac).
If the page loads, you’re all set! If the error reappears, move on to the next step.
Solution 2: Restart Your Router and Modem to Refresh the Network
Restarting your router and modem is one of the most reliable ways to fix network issues. This process clears your hardware’s temporary memory, which can get clogged with errors over time.
Unplug Router: Unplug the power cords from both your modem (the device that brings the internet into your home) and your router (the device that creates your Wi-Fi network).
Wait 60 Seconds: Leave them unplugged for at least a full minute. This ensures they fully power down and clear their memory.
Test Your Connection: Once your computer reconnects to the Wi-Fi, try loading the webpage again.
Solution 3: Restart Your Computer to Fix System Connection Issues
Your computer can also develop temporary glitches in its operating system or network services. A simple restart is a quick and easy way to fix them and start fresh.
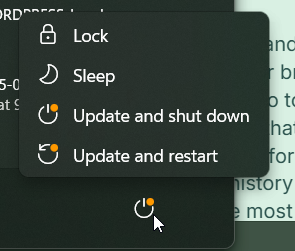
For Windows: Go to the Start Menu, click the Power icon, and select Restart.
For macOS: Click the Apple logo in the top-left corner and select Restart….
After your computer boots up, open Chrome and check if the error is gone.
Step 2: Chrome-Specific Fixes
If a simple restart didn’t help, the issue may be in Chrome’s stored data or your network configuration. These next steps dig deeper but are still safe and straightforward for any user.
Solution 4: Clear Chrome’s Cache and Data to Remove Corrupt Files
Chrome stores temporary data (cache and cookies) to help websites load faster. Sometimes, these files can become outdated or corrupt, especially after a network change, causing conflicts.
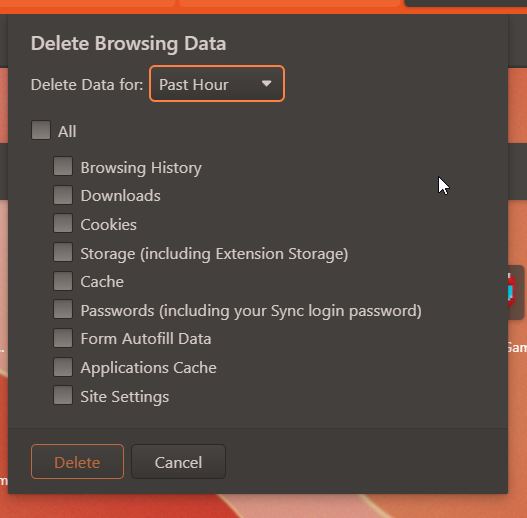
Open Chrome and press Ctrl + Shift + Del on Windows or Cmd + Shift + Y on Mac to open the “Clear browsing data” window directly.
Alternatively, go to Settings > Privacy and security > Clear browsing data.
In the window that appears, set the “Time range” to All time.
Check the box for “Cached images and files.” If you don’t want to be logged out of websites, leave “Cookies” and “Browsing history” unchecked.
Click the Clear data button.
Solution 5: Turn Off VPN or Proxy Server to Restore a Stable Connection
VPNs and proxies change your network route, making them a primary suspect for this error. If you use a VPN, temporarily disconnect or quit the application completely. Then, try reloading the webpage. If the error is gone, the problem lies with your VPN’s connection or configuration. You may need to try connecting to a different server within your VPN app.
Sometimes, a proxy can be enabled without you knowing.
On Windows: Go to Settings > Network & Internet > Proxy. Make sure “Use a proxy server” is turned off.
On macOS: Go to System Settings > Network, select your Wi-Fi or Ethernet connection, click Details…, and then go to the Proxies tab. Make sure no proxies are checked.
You will be prompted to enter your Mac’s password. Type it in and press Enter (you won’t see the cursor move, which is normal). The command will run and fix the issue.
Step 3: Network and Hardware Fixes
If you’re still seeing the error, the problem may be tied to your device’s core software or hardware. These last steps address driver issues and hardware faults that can cause persistent connection drops.
Solution 7: Update Your Network Adapter Drivers to Improve Stability
A driver is the software that lets your operating system communicate with hardware like your Wi-Fi card. An outdated or corrupt driver can cause all sorts of connection instability.
On Windows:
Right-click the Start Menu and select Device Manager.
Expand the “Network adapters” section.
Right-click on your primary adapter (it will usually have “Wi-Fi” or “Ethernet” in the name) and select Update driver.
Choose “Search automatically for drivers.” Windows will search for and install any available updates.
On macOS: Apple handles driver updates differently. They are bundled with system software updates. To ensure your drivers are current, simply check for a system update:
Go to System Settings > General > Software Update.
Install any available updates.
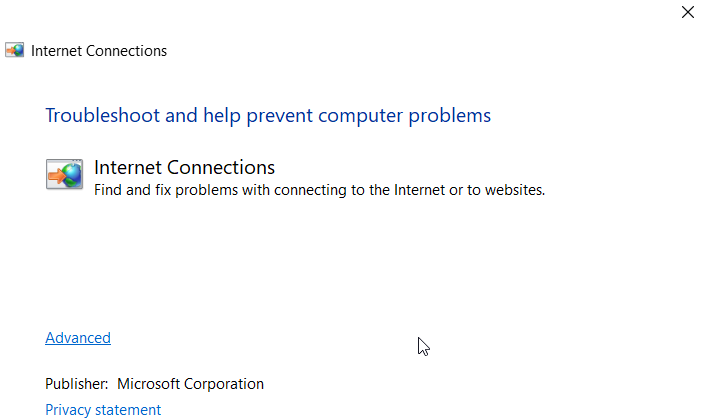
Solution 8: Run the Windows Network Troubleshooter for Automatic Fixes
For Windows users, there’s a built-in tool designed to automatically find and fix network problems. It’s a quick way to detect and fix issues automatically.
Go to Settings > System > Troubleshoot.
Click on Other troubleshooters.
Find the Network Adapter in the list and click the Run button next to it.
Follow the on-screen prompts and let Windows attempt to diagnose and resolve the issue.
Wrapping Up: Keep Chrome Connected and Avoid ERR_NETWORK_CHANGED in the Future
The ERR_NETWORK_CHANGED error might interrupt your work, but fixing it is usually quick once you know where to start. Whether it’s a simple Wi-Fi hiccup, a VPN reconnecting, or a misconfigured setting, this guide should help you get Chrome back online fast.
Of course, avoiding these interruptions starts with a stable, well-managed hosting environment – especially if you’re running WordPress sites for clients or your business.
That’s where RunCloud comes in. It gives you a powerful, easy-to-use control panel for deploying, managing, and securing your WordPress sites on any cloud provider. You’ll spend less time troubleshooting and more time building and delivering projects without disruption.
Take the hassle out of server management and keep your sites running smoothly.
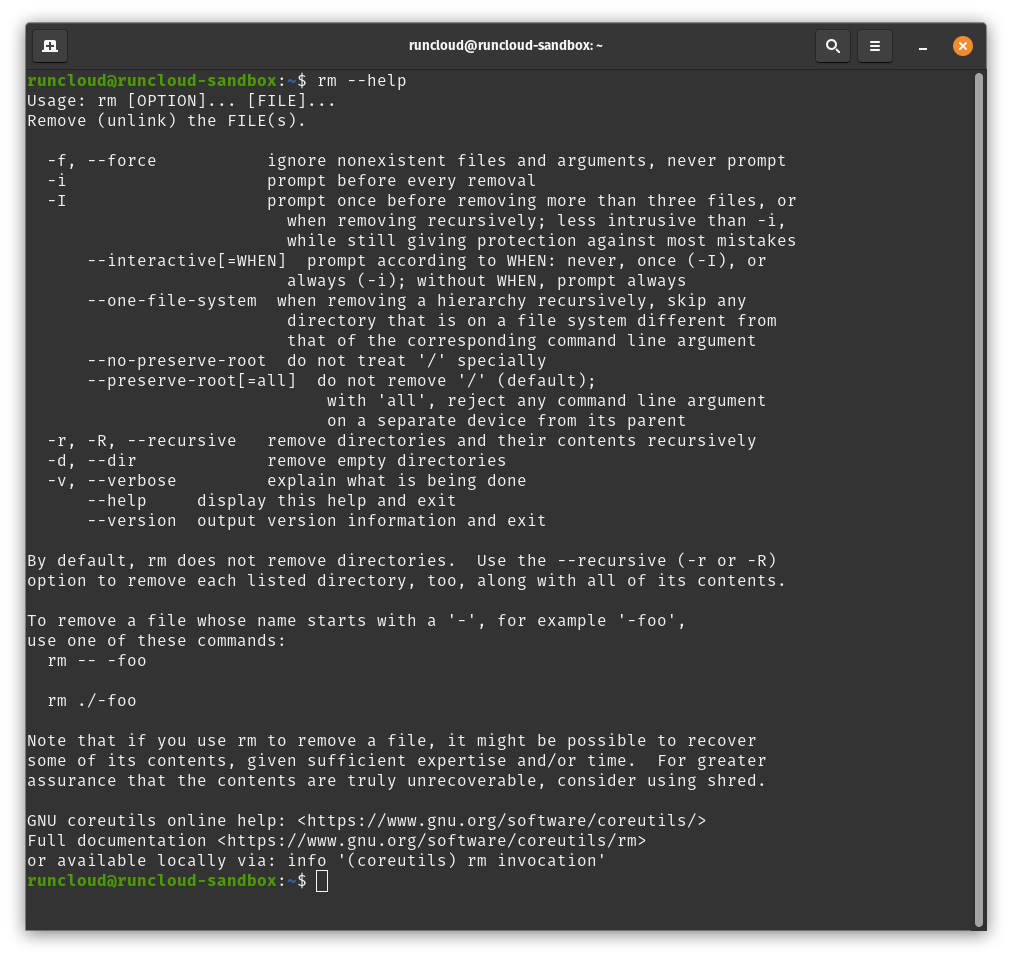
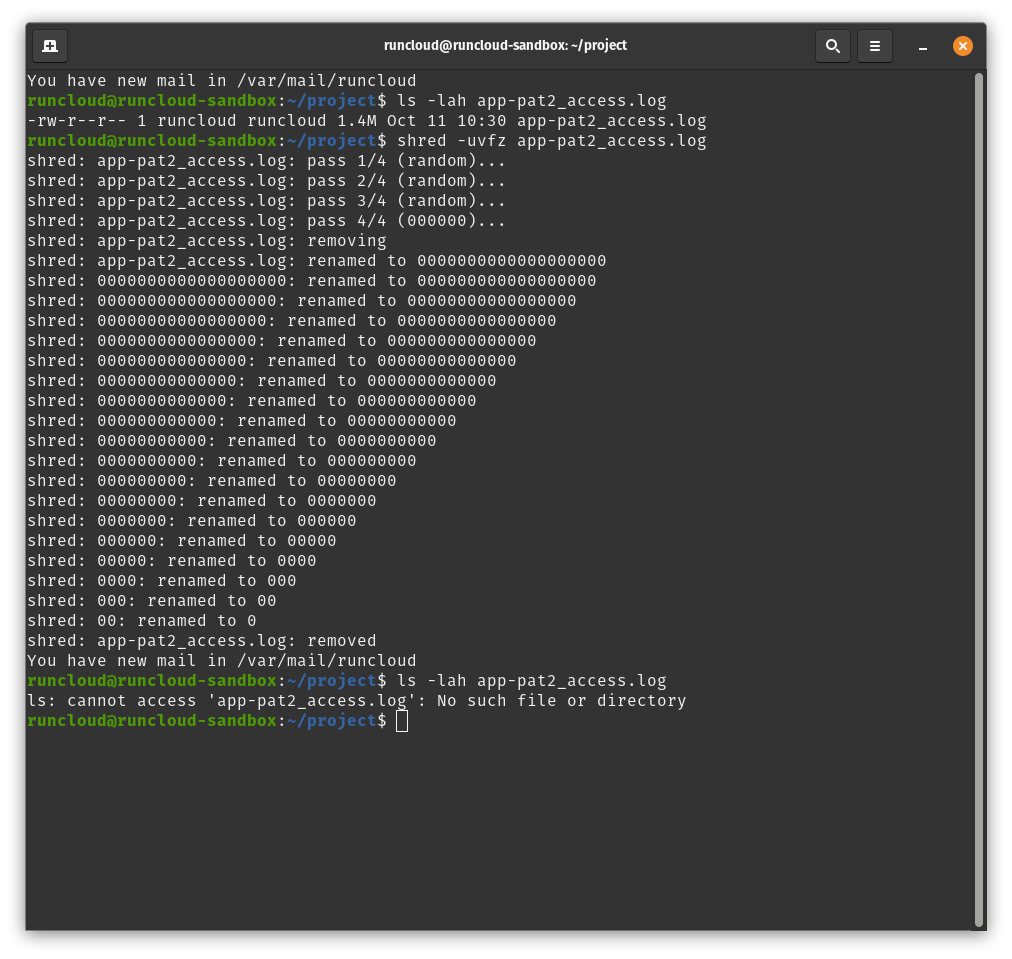
Deleting a large directory with thousands of files in Linux can be slow or even fail with basic commands. Whether you’re cleaning up old logs, project files, or datasets, knowing the right commands makes the process faster and more reliable.
In this guide, we’ll show you how to delete directories with thousands of files in Linux using several methods – from rm and find to faster alternatives like rsync. You’ll learn which approach is best for different scenarios, how to avoid common errors, and how to free up disk space safely.
Why Would You Need to Delete Thousands of Files at Once in Linux?
If you use a computer professionally, you may have stored many files on your hard drive over time. These files can include documents, photos, videos, music, and more. Some of these files may be important and useful, while others may be outdated and unnecessary.
Here are some possible scenarios:
You are a web developer and you have a project folder that contains thousands of files, such as HTML, CSS, JavaScript, images, etc. You want to delete the project folder because you no longer need it or you want to start from scratch.
You are a data analyst and you have a directory that contains thousands of CSV files, each containing data that you have processed or analyzed. You want to delete the directory because you have finished your analysis, and you want to free up some disk space.
You are a system administrator and you have a directory that contains thousands of log files, each recording system events or errors. You want to delete the directory because you have resolved the issues. If you want to clear the logs periodically then you should also read our article on log-rotation.
You are a photographer and you have a directory that contains thousands of RAW images, each capturing moments that you have taken with your camera. You want to delete the directory because you have edited or backed up the images, or you want to make room for new photos.
Having too many files can affect your computer’s performance and disk space. Therefore, it is advisable to periodically delete the files that you no longer need or want.
How Do You Delete a Directory in Linux?
There are multiple ways to delete a file or folder in Linux. Let’s take a look at some of these ways.
However, be careful when using these commands, as they are irreversible and may delete important files if used incorrectly.
Always double-check the path and the options before executing them.
How to Delete a Large Directory in Linux with rm
The rm command is one of the most common and basic commands for deleting files and directories in Linux. To delete a directory and all its contents, you can use the -r option, which stands for recursive.
For example, if you want to delete a directory named project, you can use the command:
rm -r project
However, this command may take a long time and generate a lot of output if there are too many files in the directory. To speed up the process and suppress the output, you can use the -f option, which stands for force.
This option will delete the files and directories without prompting for confirmation or showing any messages.
rm -rf project
How to Delete Files and Directories in Linux with find
Alternatively, you can use the find command, which is a powerful and flexible command for finding and manipulating files and directories in Linux.
To delete a directory and all its contents, you can use the -delete option, which will find and delete all the files and directories under a given path. For example:
find project -delete
The find command also has many other options that allow you to selectively delete files based on different criteria, such as pattern, date, time, or size.
How to Use rsync to Delete a Directory in Linux
The rsync command is generally used to transfer and synchronize files between local and remote devices in an efficient way. It uses a special algorithm that only sends the differences between the source and destination files, which reduces the network usage and speeds up the transfers.
This can be used for various scenarios, such as backup, mirroring, updating, copying, or even deleting files and directories. To delete a folder using rsync, you can use the following simple command:
rsync -a --delete source/ destination/
This command will sync the contents of the source folder to the destination folder, and delete any files or subfolders in the destination that do not exist in the source. The options used in this command are:
-a archive mode, which preserves almost everything (such as symbolic links, file permissions, user & group ownership, and timestamps).
--delete delete mode, which deletes extraneous files from the destination location.
Note that you need to add a trailing slash (/) after the source and destination folder names, otherwise rsync will treat them as file names and create a subfolder in the destination.
For example, if you use rsync -a --delete source destination, rsync will create a subfolder named source in the destination and sync the contents of the source folder to it.
How to Securely Delete Files in Linux with shred
Shred is used to permanently erase or destroy files so that no one can recover them. It is better than deleting normally, because a normal deletion only removes the reference to the file in the file system, but the actual data remains on the disk until it is overwritten by other data.
A deleted file can be recovered using special software or hardware tools that can scan the disk for traces of data. Shred prevents this by overwriting the file multiple times with random data, making it impossible to reconstruct the original data.
Shred also adds a final overwrite with zeros to hide the fact that the file was shredded. Therefore, shred is more secure and reliable than deleting normally, especially for sensitive or confidential files.
To shred a document in Linux, you can use the following simple command:
shred -uvfz document
This command will overwrite the data in the document file several times, making it harder for third party software and hardware probing to recover the data. The options used in this command are:
-u flag will remove the file or directory after overwriting it with random data.
-v verbose mode, which shows information on shredded files.
-f force mode, which changes permissions to allow writing if necessary.
-z zero mode, which adds a final overwrite with zeros to hide shredding.
The shred command can only be used to delete files and not directories. However, it is possible to use it in conjunction with other commands to create automated scripts that shred entire directories.
For example, you can use the ‘find’ command with the -exec option to execute the shred command on each file found by ‘find’. Here is an example of how to shred and delete all the files in a directory named ‘secret’:
find secret -type f -exec shred -u {} \;
This command will find all the files in the secret directory and execute the shred command with the -u option on each of them.
However, be aware that the shred command relies on the assumption that the underlying file system overwrites the same physical block when writing new data. Many newer file systems do not follow this assumption, and may use techniques such as journaling, copy-on-write, or wear leveling, which may prevent the shred command from effectively destroying the data. Therefore, shred may not work as expected on some file systems, such as ext3, ext4, btrfs, xfs, etc.
How to Selectively Delete Files in Linux
There are also a number of different ways in which it is possible to selectively delete files in Linux, depending on the criteria that you want to use. Here are some examples:
How to Delete Files by Pattern in Linux
You can use the rm command with a wildcard character (*), which matches any number of characters. This way, you can delete files that match a certain pattern, such as files with a specific extension, name, or prefix.
For example, if you want to delete all the files that have the .txt extension in the current directory, you can use the command:
rm *.txt
If you want to delete all the files that start with the prefix test in the current directory, you can use the command:
rm test*
How to Delete Files by Date or Time in Linux
You can use the find command with various options that locate files based on their modification (-mtime or -mmin), change (-ctime or -cmin), or access (-atime or -amin) time.
These options take a number as an argument, which can be preceded by either a plus sign (+) or a minus sign (-). A plus sign means more than the given number, while a minus sign means less than the given number.
The number can be either days (-mtime or -ctime) or minutes (-mmin, -cmin, or -amin).
For example, if you want to delete all the files that were modified more than 10 days ago in the current directory, you can use the command:
find . -mtime +10 -delete
If you want to delete all the files that were accessed less than 30 minutes ago in the current directory, you can use the command:
find . -amin -30 -delete
How to Delete Files by Size in Linux
You can use the find command with the -size option, which finds files based on their size.
This option takes a number as an argument, which can be followed by a suffix that indicates the unit of measurement. The suffix can be either bytes (b), kilobytes (k), megabytes (M), gigabytes (G), or blocks (c).
A plus sign (+) or a minus sign (-) before the number means larger than or smaller than respectively.
For example, if you want to delete all the files that are larger than 100 MB in the current directory, you can use the command:
find . -size +100M -delete
If you want to delete all the files that are smaller than 1 KB in the current directory, you can use the command:
find . -size -1k -delete
Key Takeaways on Deleting Large Directories in Linux
Deleting files in Linux may seem like a simple action, but there are lots of hidden nuances and challenges that you may encounter. In this article, we have explained how to delete directories with a large number of files in Linux using a variety of different commands and options.
We have also shown you how to selectively delete files based on different criteria, such as pattern, date, time, or size. However, you need to be careful when using these commands, as they are irreversible and may delete important files if used incorrectly. Always double-check the path and the options before executing them.
If you are struggling with the Linux command line, then you should take a look at RunCloud. RunCloud allows you to manage your sites effectively without needing to become a Linux system administrator. You can easily create, deploy, and update your websites with just a few clicks.
RunCloud supports various web servers, such as Apache, Nginx, and LiteSpeed. You can also switch between different PHP versions with the click of a button. RunCloud works with any cloud provider, such as AWS, Google Cloud, DigitalOcean, and more. Sign up to RunCloud today and forget all the hassle!
FAQs on Deleting Large Directories and Files in Linux
What Does the “Argument List Too Long” Error Mean in Linux?
This error occurs when a command like rm * expands to more filenames than the system can handle at once. You must use a more robust method, like the find or rsync commands, which process files individually or in batches.
Why Is rm -r Slow in Linux and How Can I See Progress?
rm can be slow because it has to process the metadata for every single file before deleting it. To see progress, you can add the verbose flag (rm -rv), which will print each file name as it’s deleted, though this can slow the process further.
What Is the Difference Between rm -r and rm -rf in Linux?
The -r flag means “recursive” to delete a directory and everything inside it. The -f flag means “force,” which suppresses confirmation prompts and ignores non-existent files, making it much more dangerous if you make a typo.
Can I Do a Dry Run Before Deleting Files in Linux?
Yes, before running a delete command, you can first list the files you intend to target by using find /path/to/directory -type f -print to be sure you’re in the right place.
What Is the Fastest Way to Delete a Large Directory in Linux?
The rsync method is often the fastest as it is highly optimized for this task. It works by syncing an empty directory over your target directory, which efficiently removes the files with minimal overhead.
How Do I Fix “Permission Denied” Errors When Deleting Files in Linux?
This means your user doesn’t have the rights to delete those files. You may need to run the command with sudo at the beginning, but be extremely careful as this grants root privileges and a mistake can damage your system.
Can I Recover Files After Deleting Them in Linux?
Unfortunately, no; command-line deletion in Linux is permanent and does not use a Trash or Recycle Bin. This is why you must always double-check your command and ensure you have reliable backups.
What Happens If I Cancel a Deletion Mid-Process in Linux?
The command will stop, but the files that were already deleted are gone forever. You will be left with a partially deleted directory that you can attempt to delete again later.
If you’re still sending invoices from Word documents, chasing late payments with awkward follow-up emails, or juggling endless spreadsheets, you’re wasting time you could spend on actual client work.
The right invoice management software can handle all that for you – creating professional invoices in minutes, tracking when they’re opened and paid, and sending polite reminders automatically.
In this guide, we’ll compare leading options, including QuickBooks, Xero, and FreshBooks, with strong alternatives such as Zoho Invoice, Wave, and others. You’ll see the key features, pricing, and differences that matter so you can choose the tool that will save you time, help you get paid faster, and keep your finances in order.
Let’s get started!
What is Invoice Management Software?
Invoice management software replaces the messy mix of spreadsheets, manual invoices, and payment-chasing emails with one streamlined system.
Instead of building each invoice from scratch and tracking payments in a separate file, you can create branded invoices in minutes, send them directly to clients, and see exactly when they’re viewed or paid.
The goal is simple: cut down on admin, speed up payments, and give your business a more professional edge.
How Invoice Management Software Works
Here’s how most platforms handle the process from start to finish:
Create – Pick a template, add your logo, enter client details, and list products or services. The system calculates totals, taxes, and discounts automatically.
Send & Track – Email the invoice straight from the platform and see when it’s sent, opened, and paid.
Remind – Set up automatic reminders for upcoming or overdue payments.
Get Paid – Add a “Pay Now” button linked to gateways like Stripe, PayPal, or Square for instant payment.
Report – View real-time data on revenue, outstanding invoices, and tax collected.
Top Features to Look for in the Best Invoice Management Software
When evaluating different invoice management platforms, not all are created equal. To ensure the software meets your business needs and can scale with you, focus on these essential features:
Customizable Invoice Templates: Look for the ability to easily add your logo, adjust colors, and modify the layout to create professional invoices that reflect your brand identity.
Automation Capabilities: The best software automates key tasks. This includes setting up recurring billing for retainer clients, scheduling future invoices, and, most critically, sending automated late-payment reminders.
Online Payment Gateway Integration: This is an important feature for getting paid quickly. Ensure the software integrates with popular and trusted payment gateways so clients can pay you with a single click.
Real-Time Invoice Tracking: The ability to see the status of an invoice (e.g., Sent, Viewed, Paid, Overdue) in real-time provides clarity and helps you manage your cash flow more effectively.
Robust Reporting and Analytics: Your software should provide clear, easy-to-understand reports on your income, expenses, outstanding invoices, and payment history to help you make informed business decisions.
Integrations with Other Tools: Check for compatibility with your existing software, such as accounting platforms (like QuickBooks or Xero), CRM systems, or project management tools, to create a seamless workflow.
Mobile Accessibility: A dedicated mobile app or a mobile-responsive web interface is essential for managing your business on the go. These apps allow you to send invoices and check payment statuses from anywhere.
Multi-Currency and Multi-Language Support: This feature is non-negotiable if you work with international clients. It allows you to bill clients in their local currency and language, simplifying the process for everyone.
Rossum provides an e-invoicing platform as a single solution designed to handle the complexities of modern businesses, particularly for companies operating across multiple regions. It uses sophisticated AI to automate the entire document lifecycle, from initial receipt to final processing. It also allows businesses to manage a hybrid reality where they receive both traditional PDF invoices and structured e-invoices.
The system is engineered to be more than a simple data entry tool. It automatically validates invoices against country-specific regulations, such as FatturaPA, XRechnung, and PEPPOL, and ensures compliance with evolving government mandates. This is particularly relevant for companies navigating the rollout of new e-invoicing requirements across Europe.
Additionally, the platform can convert machine-readable e-invoices into human-readable PDFs for auditing purposes and integrates with major ERP and business systems, including SAP, NetSuite, and Workday, to ensure data flows smoothly into your existing financial ecosystem.
Pricing and Subscription Plans
Rossum uses a customized pricing model based on factors like invoice volume, number of users, required integrations, and feature set. They encourage potential customers to request a free demo or start a 14-day trial to experience the platform firsthand.
Tipalti offers a comprehensive invoice management solution as part of its broader accounts payable automation platform. The platform is designed primarily for mid-market and enterprise-level businesses that manage high volumes of invoices. It offers multiple methods for invoice capture, including email, a supplier portal, and OCR scanning, which can read and process invoice data with high accuracy.
Tipalti also offers an advanced validation and approval system. The platform can perform two- and three-way PO matching and uses a powerful business rules engine to enforce internal controls, automatically routing invoices to the correct approvers. It also includes built-in compliance features, such as validating tax information (like W-9s and VAT IDs) before processing payments.
Pricing and Subscription Plans
Tipalti offers three plans: the “Select” plan is priced at €99 per month and includes unlimited user access, a supplier portal for self-onboarding, automated VAT ID collection and validation, AI Smart Scan for invoice processing and auto-coding, an AI Smart Report builder, and seamless integrations with leading ERPs. For more complex requirements, the “Advanced” plan, at €219 per month, contains all “Select” features while adding capabilities such as 2/3 way PO Matching, flexible bill approval rules, domestic multi-entity infrastructure, global Tax ID collection and validation, etc.
Yooz is a “pure cloud” solution for accounts payable that emphasizes speed and simplicity in its end-to-end invoice and payment processing. The platform uses advanced technologies like AI, deep learning, and robotic process automation (RPA) to minimize manual intervention from invoice capture to final payment. One of its primary highlights is its sophisticated data extraction capability. It can accurately capture relevant information from any document format, including emails, PDFs, and scanned paper, without prior template configuration.
The platform is designed to provide a complete workflow. After capturing an invoice, Yooz automatically handles GL coding, identifies duplicates, and initiates multi-level approval workflows that can be managed from any device, including a dedicated mobile app.
It has integrations for over 250 ERP and financial software packages, including popular systems like Sage, Xero, and QuickBooks. This means Yooz can serve many businesses, from small companies to larger enterprises, looking to streamline their AP processes.
Pricing and Subscription Plans
Although specific costs are customized, Yooz offers a more transparent pricing structure than many enterprise-level competitors. The company provides a tailored quote based on the client’s needs but frames its plans around clear tiers.
Yooz structures its pricing based on the yearly invoices you expect to process (e.g., up to 1,200, up to 6,000, etc.). This makes it scalable, allowing businesses to choose a plan that fits their current size and adjust as they grow.
Stampli offers an Accounts Payable automation platform emphasizing centralizing communication and collaboration directly on top of the invoice. Its core philosophy is eliminating the need for external email threads and disjointed conversations when resolving invoice-related queries.
Once an invoice is in the system, it becomes the central hub for all activities, including questions for approvers, stakeholder clarification, and related documentation. This ensures that the entire history of an invoice’s lifecycle, from receipt to approval, is contained in one auditable location.
Stampli is designed to be flexible, managing various invoice types, including those with or without purchase orders. It integrates seamlessly with leading ERP systems like NetSuite, Sage Intacct, QuickBooks, and Microsoft Dynamics.
Pricing and Subscription Plans
Stampli uses a customized pricing model based on factors like invoice volume, number of users, required integrations, and feature set. Contact the provider for a tailored quote.
The factors that influence the final subscription cost include:
Invoice Volume: The number of invoices your business processes monthly or annually.
Number of Users: The quantity of user seats required for your AP team, approvers, and other stakeholders.
ERP Integration: The specific ERP system being used and the complexity of the integration.
Feature Set: Access to specific advanced features or modules within the Stampli platform.
Paylocity’s AP Automation solution is an integrated module within its comprehensive Human Capital Management platform. It is primarily designed for businesses seeking to unify their finance and HR operations under a single vendor, creating a seamless connection between employee data and financial workflows. The tool automates the standard accounts payable lifecycle, from invoice capture using OCR technology to setting up customizable, multi-step approval workflows that route invoices to the correct stakeholders.
It securely processes vendor payments via ACH, virtual card, or check and ensures that all data syncs with the general ledger in real time. By linking AP processes directly with its core HR and payroll systems, Paylocity provides businesses with enhanced visibility and a single source of truth. This improves data consistency and streamlines overall administrative tasks across departments.
Pricing and Subscription Plans
Paylocity operates on a customized, quote-based pricing model and does not publicly list standard rates for its AP Automation module. As the tool is part of a larger HCM suite, its cost is bundled with other core services like Payroll, HR, and Time & Labor. This means pricing is not offered on a standalone basis for just the AP tool.
The final cost is calculated per employee, per month (PEPM), with the AP Automation functionality added to a company’s main service package.
QuickBooks Invoicing is not a standalone product but an integrated feature within the comprehensive QuickBooks accounting software ecosystem. It is designed primarily for freelancers, small businesses, and mid-sized companies needing a unified billing and bookkeeping solution. The platform allows users to create professional, customized invoices with their own branding, send them directly to clients, and track their status in real time to see when they have been viewed and paid.
The main strength of QuickBooks Invoicing lies in its seamless integration with the rest of the accounting suite. When a client pays an invoice online via the built-in payment gateway, the transaction is automatically recorded, categorized, and reconciled within the user’s books, drastically reducing manual data entry and potential errors.
Additionally, it can set up recurring invoices for retainers, send automated payment reminders for overdue accounts, and directly convert estimates into invoices, streamlining the entire sales cycle from proposal to payment.
Pricing and Subscription Plans
The invoicing functionality is not sold separately but is included in all QuickBooks Online subscription plans. Therefore, the pricing is tied directly to the cost of the overall accounting software package. QuickBooks offers several tiered plans, which start at $19/month and go as high as $76/month.
Vyapar is a business accounting application designed to meet the needs of small and medium-sized businesses in India. Its e-invoicing functionality is built to simplify compliance with the Indian government’s Goods and Services Tax (GST) e-invoicing mandate. The platform enables users to generate GST-compliant invoices and seamlessly register them on the government’s Invoice Registration Portal (IRP) to obtain the required Invoice Reference Number (IRN) and QR code.
It is an all-in-one solution for Indian SMEs as it integrates this compliance feature into a broader ecosystem that includes inventory management, payment reminders, expense tracking, and generating various GST reports (like GSTR-1 and GSTR-3B).
Pricing and Subscription Plans
Vyapar operates on a freemium model, one of its key market differentiators. The core e-invoicing functionality is available as part of its free business accounting software, making it highly accessible for freelancers, sole proprietors, and small businesses needing GST compliance without an upfront investment.
The pricing structure is as follows:
Free Plan includes essential features like creating GST-compliant invoices, managing inventory, and generating e-invoices. It is a fully functional offering designed to cover the basic needs of a small business.
Premium Subscriptions: Vyapar offers paid subscription plans starting at INR ₹3999/year (approximately USD $45) for businesses that require more advanced capabilities. These premium tiers unlock features such as multi-device synchronization (for using the app on both mobile and desktop), support for managing multiple businesses from a single account, and other advanced functionalities.
Swipe is a mobile-focused application designed to serve as an all-in-one business management tool for freelancers, solopreneurs, and small businesses in India. It is mainly built to create and manage GST-compliant invoices quickly. The platform is distinctly tailored to the Indian market, integrating natively with ubiquitous payment and communication channels in the region.
Users can send invoices, payment links, and reminders directly to clients via WhatsApp, a feature that aligns closely with common small business workflows in India. Additionally, it facilitates instant payment collection through embedded UPI invoice payment links.
In addition to invoicing, Swipe offers a suite of complementary features, including inventory management, expense tracking, business reporting (including GSTR-1), and the ability to create a simple “online store” to showcase products.
$
Pricing and Subscription Plans
Swipe uses a clear, tiered subscription model with a free plan, making it highly accessible for new and emerging businesses. The pricing structure is transparently listed on their website and is designed to be affordable.
The model is structured as follows:
Free Plan: This entry-level plan allows users to test the core functionality, but with limitations on the number of invoices, products, and clients that can be managed monthly. It is well-suited for businesses with very low transaction volumes.
Paid Subscriptions: Swipe offers several paid tiers starting at ₹250/month (approximately USD $2.90). These plans significantly increase or remove the limits on invoices and products and unlock more advanced features. Advanced compliance tools like e-invoicing and e-way bill generation are reserved for these premium tiers.
Wave offers a suite of features designed to streamline the billing process for small businesses. Its software allows users to create and send customized, professional invoices using professional templates, with options to add a business logo and brand colors. Wave supports recurring invoices and automatic credit card payments for businesses with repeat customers to ensure timely billing without manual intervention.
It also allows customers to accept online payments directly through invoices. Customers can pay via credit card, bank payment (ACH/EFT), or Apple Pay by clicking a “Pay now” button on the invoice. The platform also includes features to improve cash flow management, such as notifications tracking when an invoice is viewed, due, or paid.
Pricing and Subscription Plans
Wave uses a freemium model with two tiers: “Starter” and “Pro”:
The Starter Plan is free and allows users to create and send unlimited invoices and estimates. This plan includes the option to accept online payments, with transaction fees of 2.9% + $0.60 per transaction for most credit cards and 3.4% + $0.60 for American Express. Bank payments are charged at 1% per transaction with a $1 minimum fee.
The Pro Plan costs $190/year and includes advanced automation and customization features. Subscribers can automatically import bank transactions, capture unlimited receipts digitally, and automate late payment reminders. This plan also offers discounted online payment processing fees for the first ten monthly transactions.
Refrens offers a free online invoice generator for freelancers, consultants, and small agencies. The platform allows users to quickly create professional, customized invoices, with options to add a company logo, signature, and attachments. A significant highlight of the free tool is that the invoices generated do not carry any Refrens branding, a feature often reserved for paid tiers in other tools.
In addition to simple invoice creation, the tool is part of a broader freelance business management suite. When you create an invoice, the client is automatically saved in a simple client management system, and the platform also includes features for expense tracking and report generation.
Pricing and Subscription Plans
Refrens operates on a freemium model, with its core online invoice generator and associated business management tools completely free. The pricing structure is structured as follows:
Free Plan includes essential features like creating GST-compliant invoices, managing inventory, and generating e-invoices. It is a fully functional offering designed to cover the basic needs of a small business.
Accounts GST Lite: This plan costs INR ₹6,400 per year (approximately USD $73) per business and includes everything in the free plan, template customization, payment gateway integration, 1-click WhatsApp sharing, email tracking and scheduling, recurring invoices, etc.
Accounts GST: This plan costs INR ₹16,800 per year (approximately USD $192) per business and includes everything in the Accounts GST Lite plan, plus automated GSTR-1 Reports, e-way bill generation, e-invoices, and bulk IRN generation, e-way bills with IRN, the ability to verify and auto-fill clients GST details, emails from your own domains, GSTR-2B reports download and auto-reconciliation, and more.
Odoo Invoicing is not a standalone tool – it’s a module within Odoo’s suite of open-source business management applications. The biggest advantage of using Odoo is its native integration with other Odoo apps like Accounting, Sales, and CRM. These integrations create a deeply connected workflow from a sales quote to a reconciled payment.
When an invoice is created, it directly impacts inventory levels and accounting ledgers in real-time. The system also features a customer portal where clients can view their invoices, track payment status, and pay online through integrated payment gateways like Stripe and PayPal. This holistic approach makes it a powerful option for businesses looking for a single, scalable system that can grow with them from a simple invoicing tool into a full-fledged Enterprise Resource Planning solution.
Pricing and Subscription Plans
Odoo’s unique and flexible pricing model sets it apart from many competitors. The Invoicing app is part of the broader Odoo Accounting app.
The pricing structure is as follows:
One App Free Plan: Odoo offers a plan to use a single application for free with unlimited users. Since Invoicing is part of the Accounting app, you can use the full Accounting suite (including invoicing) at no cost. This makes it an incredibly compelling option for small businesses and startups.
Paid Plans (Standard and Custom): Odoo offers paid plans for businesses that need to use more than one Odoo application (e.g., combining Accounting with CRM, Inventory, and Project Management). These plans start at $19.90 per month, and they have a per-user, per-month fee that grants access to all of Odoo’s applications.
Xero’s online invoicing capability is one of the best features of its comprehensive cloud accounting platform, which is designed for small to medium-sized businesses. The tool enables users to create professional, customized invoices from a desktop or a dedicated mobile app and send them directly to clients.
Once an invoice is sent, businesses can set up automatic reminders to chase late payments without manual effort. Additionally, when a client pays via an integrated payment gateway like Stripe or GoCardless, the payment is automatically matched against the invoice and reconciled with the corresponding bank transaction. This significantly reduces administrative work and ensures that financial records are always up-to-date.
Pricing and Subscription Plans
Xero’s invoicing feature is not available as a standalone product but is a core component across all its subscription plans. Xero offers three tiered pricing plans: “Starter” at USD $29 per month, “Standard” at USD $46 per month, and “Premium” at USD $69 per month. Each plan includes the core invoicing features, with higher tiers offering additional accounting functionalities.
FreshBooks offers invoicing software along with its all-in-one accounting software. This software is designed for service-based small businesses, freelancers, and agencies. The platform is widely recognized for its user-friendly interface, simplifying the creation of professional, customized invoices in minutes.
FreshBooks also offers a unique time tracking feature that calculates the time spent on a project. This feature makes it easy for you to bill clients fairly. The system also automates follow-ups with late payment reminders. It allows clients to pay directly from the invoice via integrated payment gateways, which are automatically recorded and reconciled within the accounting system.
Pricing and Subscription Plans
The invoicing functionality is not sold as a separate product but is a core feature included in all FreshBooks subscription plans.
The Lite plan starts at USD $2.10 per month, the Plus plan is USD $3.80 per month, and the Premium plan is USD $6.50 per month. These prices reflect a 90% discount for the first three months. After the initial three months, the prices will increase to $21, $38, and $65 per month.
Zoho Invoice is a dedicated invoicing application that’s part of the extensive business software suite. Unlike many other tools discussed in this article, Zoho Invoice is a standalone. It is specifically designed for freelancers and small to medium-sized businesses, and offers a comprehensive set of features to automate and manage the entire billing cycle.
Users can create highly customized invoices from a gallery of templates, set up recurring billing for repeat customers, and automatically send payment reminders to reduce manual follow-up.
One of its most valued features is the self-service client portal. It allows customers to view all their past and present invoices, approve estimates, and make bulk payments in one place, enhancing transparency and client relations.
The platform integrates with numerous online payment gateways and enables instant payment collection directly from the invoice. While it works independently, it seamlessly integrates with other Zoho apps, such as Zoho CRM and Zoho Analytics.
Pricing and Subscription Plans
Zoho Invoice’s most significant and compelling feature is its pricing model: the software is completely free to use. This is not a limited-time trial or a freemium plan with major restrictions on core features.
The pricing structure is as follows:
Free Plan: The standard Zoho Invoice plan is free and allows businesses to manage a substantial number of customers (up to 1,000) and send unlimited invoices. It includes access to customizable templates, automated reminders, time tracking, expense management, and payment gateway integrations, making it one of the most robust free invoicing solutions available on the market.
Zoho Books: While Zoho Invoice is free, businesses that require more advanced, double-entry accounting features (like a full balance sheet, bank reconciliation, and in-depth financial reporting) are encouraged to upgrade to a paid subscription of Zoho Books, which includes all the functionality of Zoho Invoice and much more.
Sage Intacct is a cloud financial management and accounting platform designed for mid-market and enterprise-level organizations that have outgrown simpler accounting software.
Unlike other tools discussed in this article, Sage Intacct isn’t merely an invoicing tool but a full-fledged cloud ERP system focused on automating complex financial processes. The platform excels in areas where businesses face significant complexity. For example, its multi-entity management capabilities allow companies with multiple business units, locations, or legal entities to automate financial consolidation in real-time.
Sage Intacct also provides powerful, dimensional reporting and dashboards that give finance leaders deep visibility into performance metrics across various business drivers. This allows for sophisticated analysis without relying on cumbersome spreadsheets.
Pricing and Subscription Plans
Sage Intacct uses a customized pricing model based on factors like invoice volume, number of users, required integrations, and feature set. Contact the provider for a tailored quote.
Wrapping Up: Who Should Invest in Invoice Management Software in 2026
Any freelancer, agency, or service-based business that wants to get paid faster and spend less time on admin should invest in invoice management software. If you’re still sending invoices manually or juggling spreadsheets, switching to a dedicated platform will save time, improve accuracy, and make your business look more professional.
For agencies, though, invoicing is only half the picture. You also need to manage the technical side of client work – hosting, performance, and security.
While your invoicing software handles the money, RunCloud takes care of the servers and websites behind your client projects.
With features like Workspaces, backups, server monitoring, and SSL management, you can manage all your client sites from one place while keeping costs under control. Combine the right invoicing tool with RunCloud, and you’ve got a complete operations setup – from sending the first invoice to maintaining the last website.
What is the difference between invoice management software and accounting software?
Invoice management software focuses on creating, sending, and tracking invoices. Accounting software includes invoicing but also handles the rest of your financial operations – bookkeeping, expense tracking, reporting, and tax preparation.
Can invoice management software integrate with my ERP or CRM?
Yes, most modern invoice management platforms are designed to integrate seamlessly with other business systems, such as Enterprise Resource Planning (ERP) or Customer Relationship Management (CRM) software.
Is cloud-based invoice management secure?
Yes – leading platforms use encryption, secure infrastructure, multi-factor authentication, and regular audits. This means your client and payment data is protected from interception or unauthorised access, reducing both security and compliance risks.
How much does invoice management software cost in 2025?
In 2025, the cost of invoice management software varies widely, from free plans with basic functionality to enterprise solutions costing several hundred dollars per month. For small to mid-sized businesses, typical monthly plans range from approximately $15 to $60 per user. Pricing is often tiered based on the number of clients, invoices, users, and access to advanced features like payment gateways.
What is the best free invoicing app?
The “best” free invoicing app depends on your needs, but businesses often recommend Wave, Zoho Invoice’s free plan, and PayPal Invoicing. These tools offer core invoice creation, sending, and tracking at no cost but may have limitations on the number of clients or access to advanced features. They are an excellent starting point for freelancers and new businesses before scaling to a paid plan.
If you’ve ever searched for information on how to SSH into a Docker container, you’ve probably found conflicting advice. The truth is, you don’t usually need to run an SSH server inside a container at all. Instead, Docker provides built-in commands that give you secure, direct access to your containers.
In this guide, we’ll show you the correct ways to get a shell inside a running container, explain the difference between docker exec and docker attach, and demonstrate how to safely detach without stopping your application. We’ll also cover when copying files makes sense, and why adding a full SSH server inside a container should be avoided except in rare cases.
Let’s get started!
Why should you use CLI over Docker Desktop?
While graphical user interfaces for Docker exist, the CLI is the primary and most powerful way to interact with the Docker daemon and containers. There are several scenarios where you’ll need to access your Docker server via the CLI:
Automation and Scripting: The most significant advantage is the ability to script any Docker operation. The CLI allows you to build a CI/CD pipeline, automate deployments, create complex multi-container setups with Docker Compose, and much more.
Server Environments: Most servers run headless (without a graphical interface). When you SSH into a remote production server, the CLI is the only way to manage Docker containers.
Precision and Control: The CLI gives you fine-grained control over every possible Docker option and flag. This level of precision is often abstracted or unavailable in GUIs.
Resource Efficiency: The CLI is lightweight. GUIs consume additional system resources that are better allocated to your applications, which is critical on a production server.
Universality: The Docker CLI is consistent across all platforms (Linux, macOS, and Windows). This universal experience makes it a reliable tool for developers and administrators, regardless of their local operating system.
When debugging an issue in a Docker container, shell access is extremely helpful because it lets you monitor and inspect individual services.
The phrase “SSH into a container” is common, but technically a misnomer. The most common and recommended methods do not involve running an SSH server inside the container at all. Let’s explore the primary techniques for gaining access and their common use cases.
Using the ‘docker exec’ command (Recommended)
The docker exec command is the most direct and recommended method for getting an interactive shell in a running container. This command starts a new process inside the container, letting you run commands without attaching to its primary process. Use the following command to get CLI access to your Docker container:
docker exec -it <container_name_or_id> <command>
-i (–interactive): Keeps STDIN open, allowing you to type commands.
-t (–tty): Allocates a pseudo-TTY, which connects your terminal to the container’s shell, making it interactive.
<command>: The command to run. To get a shell, this is typically /bin/bash or /bin/sh.
In the above example, we executed the date command inside a container with the ID ba06f65c55e7. It returned the current date and time of the Docker container (which was different from the host system).
When to use the ‘docker exec’ Command
Debugging a Live Application: If your web server is running in a container and throwing errors, you can use docker exec to get a shell, check log files that aren’t being piped to stdout, inspect the environment variables (env), or use tools like curl from inside the container to test network connectivity to other services.
docker exec -it my-web-app /bin/bash
Running Database CLI Tools: You need to inspect a database running inside a container. To do so, you can exec into the container and use a command-line client like psql or mysql.
Installing Debugging Tools: Your container uses a minimal base image and doesn’t include tools like ping or vim. You can use exec to open a shell and install them temporarily for the current session.
# Get a shell and then install curl
docker exec -it my-app /bin/sh
# Inside the container shell:
# apt-get update && apt-get install -y curl
Note: Changes made via docker exec (like installing a package) are ephemeral. If the container restarts, they will be gone. To make permanent changes, you should modify your Dockerfile and rebuild the image.
Using the ‘docker attach’ Command
The docker attach command connects your terminal’s input and output streams directly to the container’s main process (PID 1). This is fundamentally different from docker exec, which starts a new process. Execute the following command to attach to a Docker container:
docker attach <container_name_or_id>
When to use the ‘docker attach’ Command:
Interactive Applications: If you use a container that runs an interactive process by default (like a Python REPL or a shell itself), you can use the docker attach command to connect to it.
# Start a basic container with an interactive shell process
docker run -it --name my-interactive-shell ubuntu /bin/bash
# If you detach, you can re-attach with:
docker attach my-interactive-shell
Viewing Real-time Logs: If a container’s main process is an application that logs directly to stdout, docker attach will show you that live output, similar to the docker logs -f command.
How to Detach from a Docker Container Safely
When you use the docker attach command, you should understand that your terminal session becomes directly wired to the container’s primary process (PID 1). This means that keyboard signals like Ctrl-C are passed directly through to the application. If the main process within the container is a shell or an application that isn’t specifically programmed to handle this interrupt signal, it will interpret Ctrl-C as a command to terminate.
And since a Docker container’s lifecycle is tied directly to its main process, this action will cause the process to shut down, and as a result, the container itself will stop completely. This often surprises new users, who expect to just exit the logs, but instead end up shutting down the entire application.
To safely disconnect from an attached container without terminating it, you must use Docker’s specific escape sequence: holding the Ctrl key and pressing P, followed immediately by Q. This key combination is intercepted by the Docker client on your local machine and is not sent to the process running inside the container.
The docker cp command copies files to and from a Docker container. Before using it, though, it’s worth understanding that Docker Volumes are usually a better way to handle persistent data.
When Not to use the docker cp Command
A Docker Volume is a standard mechanism for decoupling the data your application generates from the container’s lifecycle. A volume is like a USB drive that can be attached to one or more containers. The biggest advantage of using volumes is that the data within a volume persists even if the container is stopped, deleted, or rebuilt. This makes it ideal for databases, application logs, user-uploaded content, and critical configuration files.
If you need a consistent and reliable way to share files between your host machine and a container, or ensure that your data survives container restarts, you should always use volumes by mounting them when you first run the container (e.g., using the -v or --mount flag with docker run).
When to use the docker cp Command
While volumes are the correct solution for persistent application data, there are specific scenarios where you might need to perform a one-time, manual file transfer. This is where the docker cp command becomes an invaluable utility for ad-hoc operations.
The docker cp command is useful in several situations, such as:
Quickly pulling a specific log file from a running container for analysis
Pushing a hotfix configuration file without rebuilding the image
Extracting a build artifact that was generated inside a temporary container.
While technically possible, running an SSH server inside your container is considered an anti-pattern. Docker containers are designed to be lightweight, disposable, and focused on a single process. Adding an SSH server adds unnecessary bulk and complexity.
When Might You Actually Need It?
Legacy Systems: You’re containerizing a legacy application, and existing management scripts or tools rely exclusively on SSH to function.
Providing Sandboxed User Environments: You are using a container to give a user a sandboxed environment on a shared server, and they need to connect with a standard SSH client.
If you must do this, you would need to:
Modify your Dockerfile to install an SSH server (e.g., openssh-server).
Configure the SSH server, add user accounts, and manage SSH keys.
EXPOSE port 22 in the Dockerfile.
Run the container, mapping a host port to the container’s port 22 (e.g., docker run -p 2222:22 …).
Final Thoughts
You now know the right way to SSH into a Docker container – by using Docker’s own tools like docker exec for most cases, and docker attach when you need to connect to a container’s main process. Running a full SSH server inside a container isn’t just unnecessary – it adds complexity and risks that Docker was designed to avoid.
Mastering these commands gives you confidence in managing containers directly. But if you want to go further – scaling deployments, automating workflows, and simplifying day-to-day server management – RunCloud gives you the best of both worlds: a clean interface with the full power of the CLI underneath.
Sign up for RunCloud today and make managing your servers and Docker environments faster, easier, and more reliable.